Results that are similar to your search
Similar results

Linux VPS SysAdmin AWS & Oracle Cloud Architect | Terraform
- $•••••
- Earned
- 1x
- Hired
- 5.0
- Rating
- 14
- Followers
Linux VPS SysAdmin AWS & Oracle Cloud Architect | Terraform
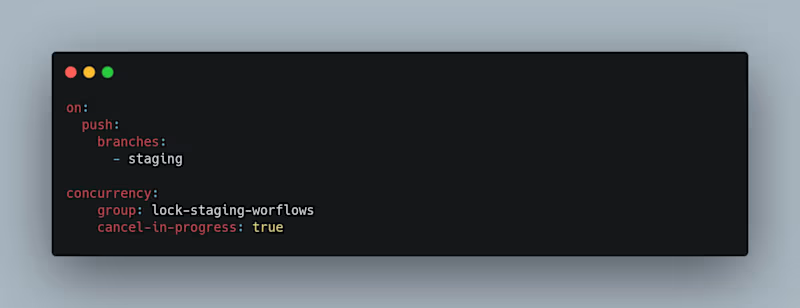
🛠️ DevOps Tips 🛠️ If your GitHub workflows or jobs are failing due to jobs concurrently accessing and/or modifying shared resources, You can control execution at the workflow or job levels using the concurrency.
Jobs/Workflows in the same are prohibited from running at the same time, and you can cancel any jobs/workflow if you trigger another one.
Groups let you define compartments in which you don't want concurrent workflows running. They can be organized however you like. I find that using them in separate environments is a great practice.
Cancel-in-progress: specifies if the old running job/workflow needs to shut down.
Read more in docs: https://docs.github.com/en/actions/how-tos/write-workflows/choose-when-workflows-run/control-workflow-concurrency
2
3
664


Expert in building an efficient and scalable data pipeline
Expert in building an efficient and scalable data pipeline


Analytics Engineer | Snowflake, Airflow, dbt
Analytics Engineer | Snowflake, Airflow, dbt


Full Stack Rapid Prototyping – Vision to Product in Weeks 🚀
- 5.0
- Rating
- 8
- Followers
Full Stack Rapid Prototyping – Vision to Product in Weeks 🚀



Data Scientist, Backend Engineer, Data Analyst

Proud to share that I’ve earned the Oracle Cloud Infrastructure (OCI) 2025 Certified Data Science Professional certification (https://tinyurl.com/dsmlaidl) — issued by Oracle.
This certification validates my expertise in Machine Learning (ML) | Data Science | Artificial Intelligence (AI) | Cloud Computing, showcasing my ability to design, build, deploy, and manage end-to-end ML solutions using OCI Data Science and Oracle AI Services.
💡 Core Expertise:
🔹 Scalable ML pipelines on OCI Data Science
🔹 AI, MLOps, and Cloud best practices for model optimization
🔹 Leveraging OCI Data Flow, Data Catalog, and AI Services for automation
🔹 Skilled in Python | TensorFlow | Scikit-learn | OCI SDKs for production-grade workflows
💪 Passionate about applying ML | Data Science | AI | Cloud Innovation to drive real business transformation.
2
2
326


Data & AI Engineer
Data & AI Engineer
Problem:
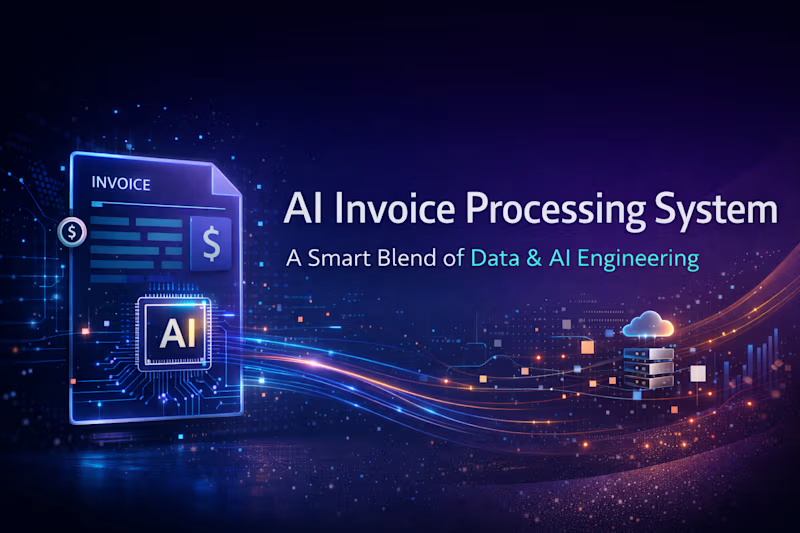
Many organizations still process invoices manually by reading PDF documents and entering key details (invoice number, vendor, amount, etc.) into systems. This process is slow, error-prone, and difficult to scale, and it also makes it harder to detect duplicate invoices or incorrect totals.
Solution:
This project builds an automated invoice processing pipeline that converts uploaded invoice PDFs into structured data. It uses OCR to extract text, LLMs to identify invoice fields, validation checks to ensure correctness, and Kafka-based event streaming to manage the processing pipeline. The extracted data is stored in PostgreSQL and visualized through a dashboard, enabling faster, scalable, and more reliable invoice processing.
3
3
226

Problem Statement
Urban traffic management systems lack real-time, integrated data combining traffic conditions with weather patterns. This results in poor routing decisions, delayed emergency responses, and inefficient traffic flow management.
Solution
Developed a comprehensive real-time ETL pipeline that integrates traffic APIs and weather data sources, processes millions of data points, and delivers actionable insights through interactive dashboards for traffic management and route optimization.
0
74


Database Architect & Engineer
Database Architect & Engineer


Data Engineer | Web Scraping | SQL | BI Dashboards
Data Engineer | Web Scraping | SQL | BI Dashboards
Problem:
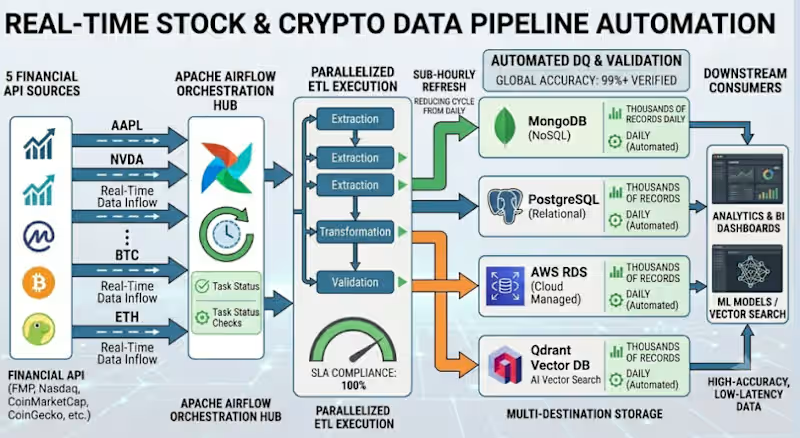
Financial data from stocks and crypto APIs was scattered, refreshed manually, and not ready for analytics or ML use.
Solution:
Built an Apache Airflow pipeline to collect, transform, validate, and load real-time financial data from multiple APIs into PostgreSQL, MongoDB, AWS RDS, and Qdrant.
Tools:
Apache Airflow, Python, PostgreSQL, MongoDB, AWS RDS, Qdrant, APIs
Result:
Automated sub-hourly data refresh, processed thousands of records daily, and delivered clean data for dashboards, analytics, and vector search.
0
106
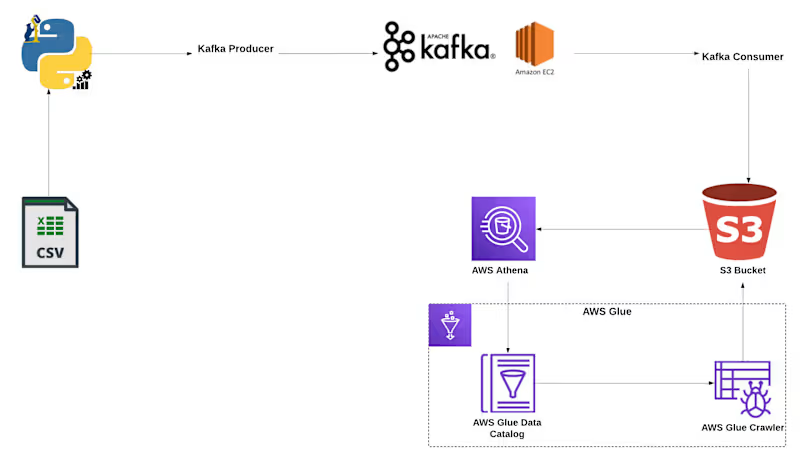
Problem:
Batch data processing was not suitable for real-time analytics and scalable cloud-based data ingestion.
Solution:
Created a real-time streaming pipeline using Kafka on AWS EC2, stored processed data in S3, cataloged it with AWS Glue, and queried it with Amazon Athena.
Tools:
Python, Apache Kafka, AWS EC2, Amazon S3, AWS Glue, Amazon Athena, Pandas
Result:
Built an end-to-end cloud data streaming workflow that supports real-time ingestion, storage, cataloging, and SQL-based analytics.
0
100
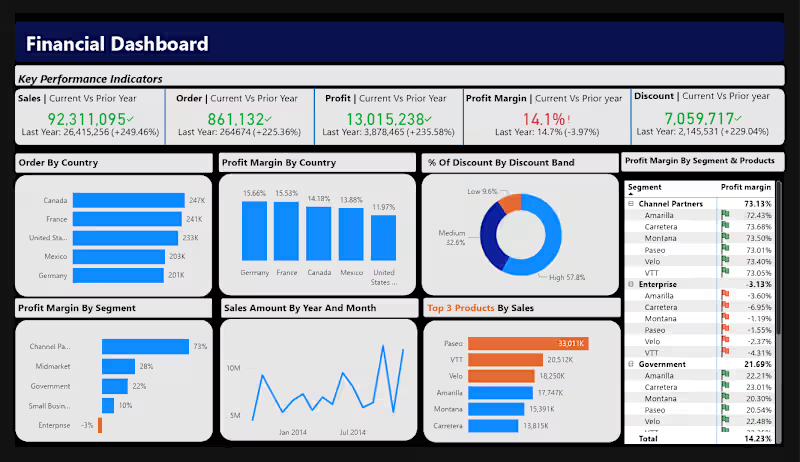
Problem:
Finance data was difficult to analyze across sales, profit, orders, discounts, countries, and customer segments.
Solution:
Created an interactive Power BI dashboard with KPI cards, sales trends, profit analysis, country performance, and segment-level insights.
Tools:
Power BI, Power Query, DAX, Excel, Data Modeling
Result:
Delivered a clear executive dashboard for tracking financial performance, identifying trends, and making faster business decisions.
0
88

Problem:
Users needed a faster way to find the most relevant counselor based on specialization and available data.
Solution:
Built a recommendation workflow using PySpark for data processing and Redis for fast lookup and recommendation serving.
Tools:
Python, PySpark, Redis, Docker, Docker Compose
Result:
Created a containerized recommendation system that processes counselor data and returns relevant matches efficiently.
0
96