René Bon Ćirić
Principal Cloud Architect | OpenStack, KVM & SRE | RHCE



Why your multi-tenant database has a Load Average of 100: It isn't a hardware problem; it's an architectural indexing disaster.
When application performance tanks, the knee-jerk reaction is almost always: "We need a bigger cloud instance. Double the vCPUs and give it 64GB of RAM."


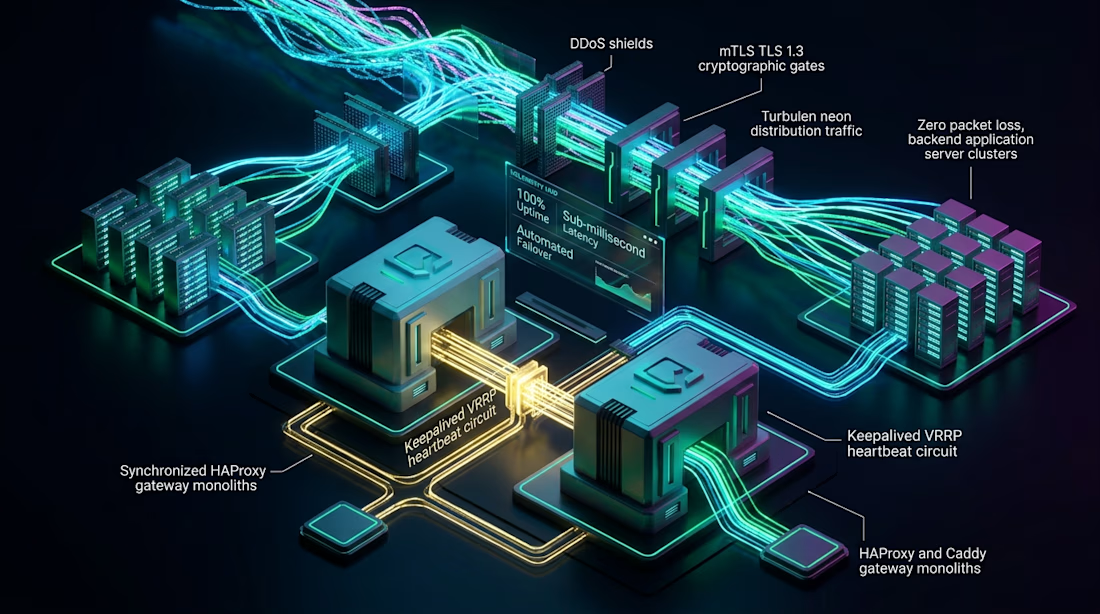
The Single HAProxy Illusion: Why your "High Availability" ingress is actually a single point of failure.
Most engineering teams set up an HAProxy or Caddy instance in front of their application clusters, configure health checks across three backend nodes, and check "High...

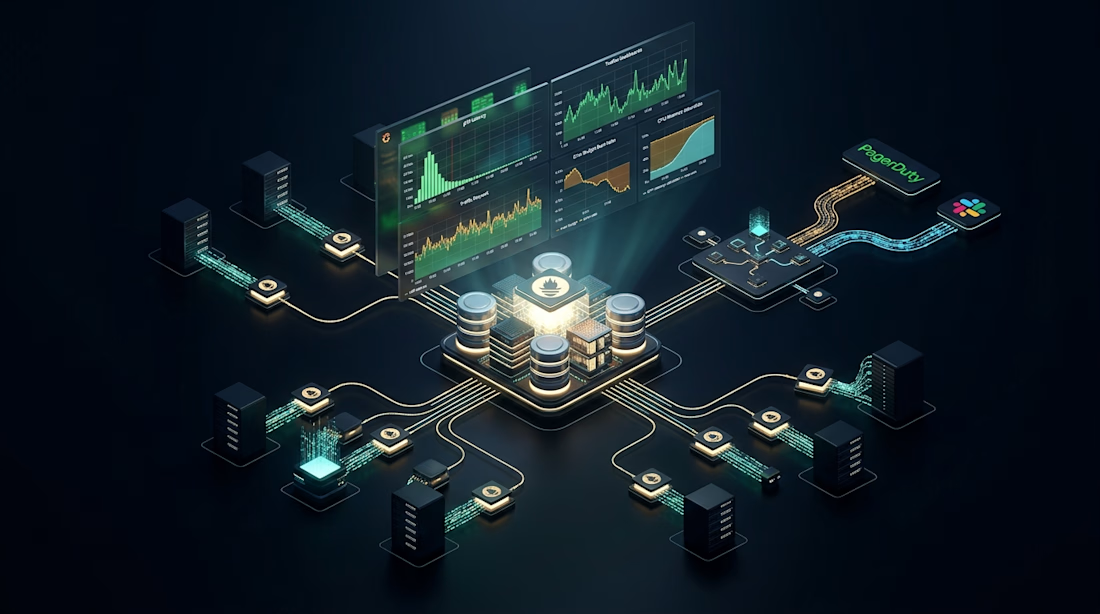
Self-inflicted monitoring outages: Why opening multiple uncached Grafana dashboards crashes your central Prometheus server right when you need it most.
During a major production incident, the entire engineering team gathers to triage the problem. Dozens of engineers open Grafana...

The StrictHostKeyChecking blindspot: Why disabling SSH host key verification in automation invites trivial man-in-the-middle attacks across your fleet.
When automating infrastructure deployments using Ansible, CI/CD pipelines, or bastion jump hosts, engineers frequently encounter...
The Cloud NAT bill shock: Why downloading backups and container images from object storage quietly drains thousands of dollars in managed NAT processing fees.
When auditing AWS or GCP monthly cloud bills, engineering leaders are frequently stunned by one line item that outpaces...