René Bon Ćirić
Principal Cloud Architect | OpenStack, KVM & SRE | RHCE



Why your multi-tenant database has a Load Average of 100: It isn't a hardware problem; it's an architectural indexing disaster.
When application performance tanks, the knee-jerk reaction is almost always: "We need a bigger cloud instance. Double the vCPUs and give it 64GB of RAM."


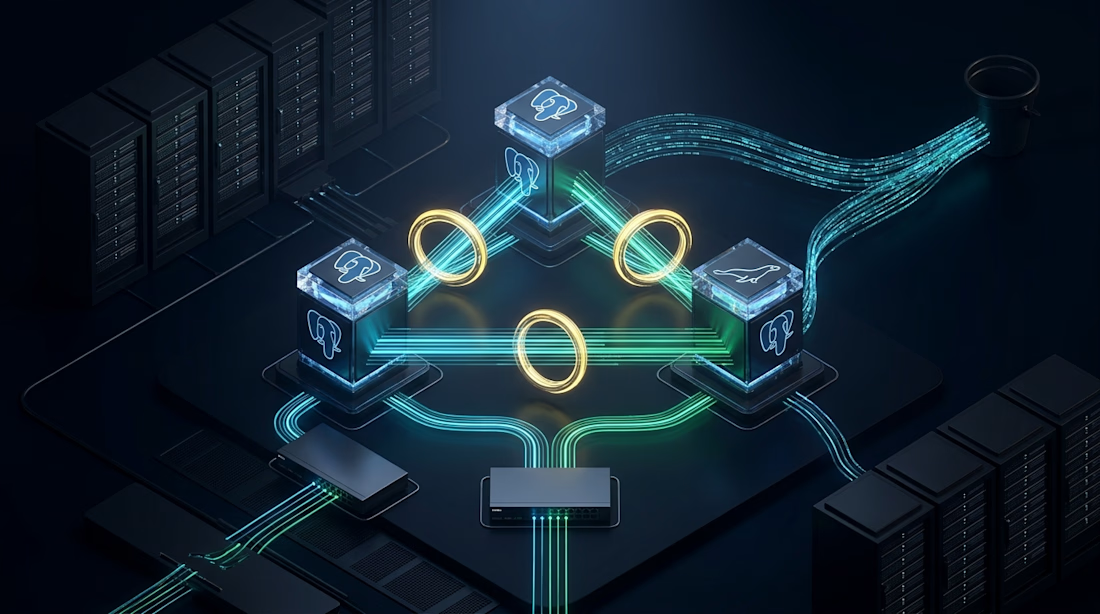
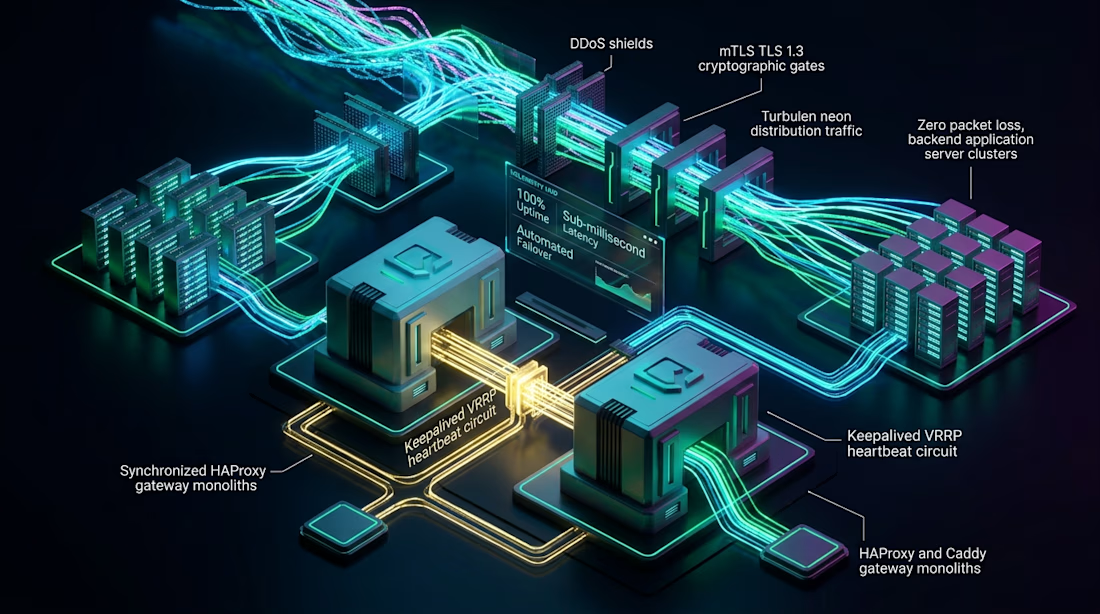
The Single HAProxy Illusion: Why your "High Availability" ingress is actually a single point of failure.
Most engineering teams set up an HAProxy or Caddy instance in front of their application clusters, configure health checks across three backend nodes, and check "High...

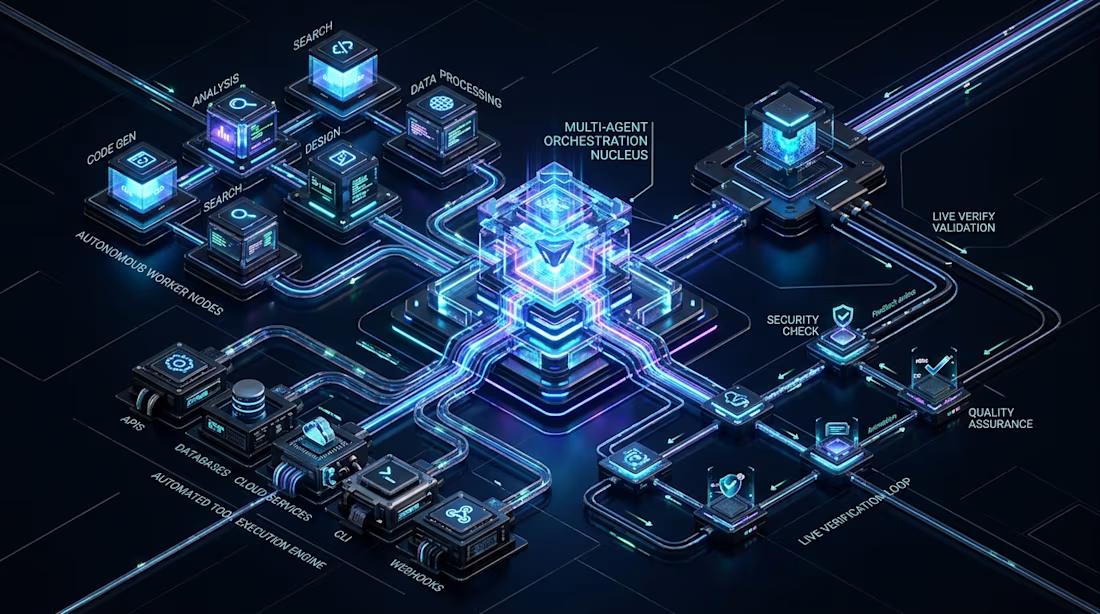
Beyond prompt engineering: Why brittle LLM string wrappers fail in production and how deterministic Model Context Protocol (MCP) harnesses guarantee reliable execution.
Over the past two years, enterprise engineering teams rushed to build "autonomous AI agents" to automate...
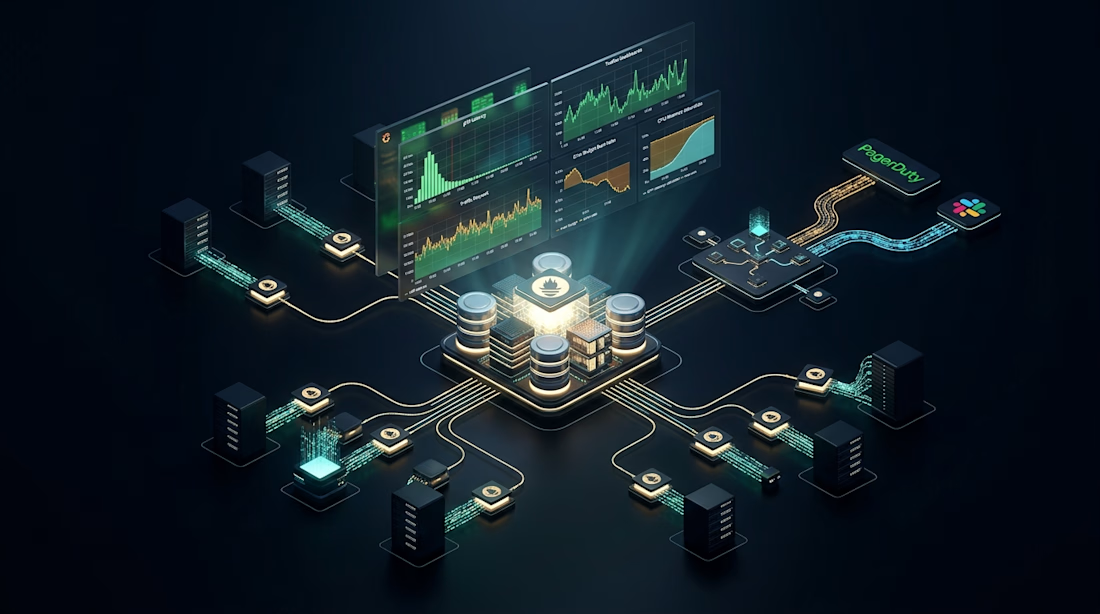
Self-inflicted monitoring outages: Why opening multiple uncached Grafana dashboards crashes your central Prometheus server right when you need it most.
During a major production incident, the entire engineering team gathers to triage the problem. Dozens of engineers open Grafana...

Upstream dependency outages: Why relying on live internet package registries during CI/CD builds paralyzes releases during critical emergencies.
When a severe production zero-day vulnerability hits your application, engineering teams sprint to patch the code, commit the hotfix,...