
SuperCollider — Multicloud Data Ingestion & Processing Platform
Summary
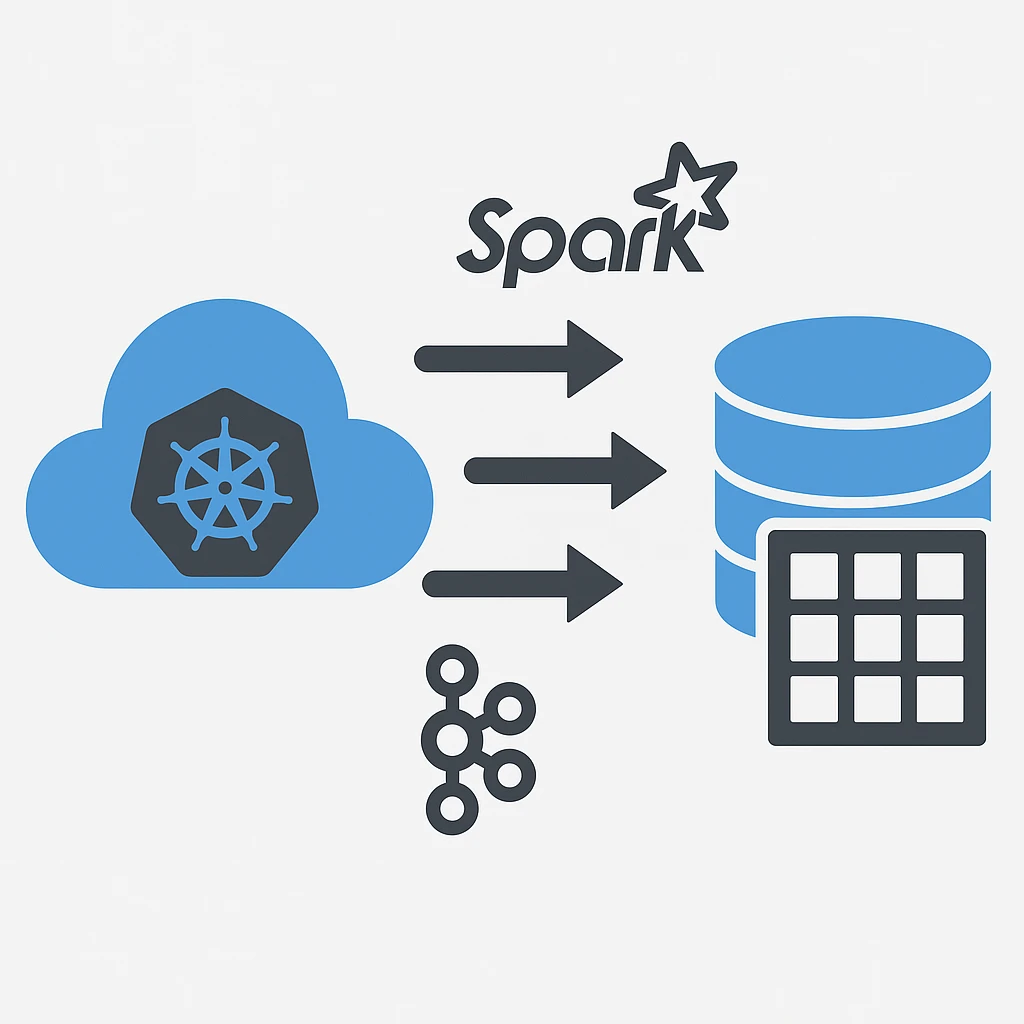
I worked as an MTS3 Big Data Engineer on SuperCollider(VMware project), a multicloud ingestion and processing platform built with Spark on Kubernetes, Kafka, and a Parquet Lake. The system ingests raw data from many sources, normalizes schemas, applies GDPR masking, and produces optimized datasets for analytics and ML.
Problem
Enterprise customers must ingest and standardize massive volumes of diverse data. Schema drift, GDPR rules, and multicloud complexity create constant failures and maintenance overhead.
Solution
SuperCollider processes data in batch Spark jobs (one per client), deserializes complex JSON, applies schema evolution rules, performs anonymization, and writes high-quality Parquet datasets. I also designed and implemented the Data Validator — an end-to-end testing system that simulates client behavior, validates schemas, and prevents bad data from entering production.
Impact
More consistent data, fewer production failures, faster ingestion, higher-quality datasets, and reliable ML workflows. The Data Validator became a core tool for onboarding new clients safely.
Role
MTS3 Big Data Engineer — ingestion pipelines, Spark jobs, schema evolution, GDPR logic, performance tuning, and developer of the Data Validator.
Tech
Apache Spark, Kafka, Kubernetes, Hive Metastore, Parquet, Python, Java, Prometheus/Grafana.
0 likes · 17 views · Nov 30, 2025
Worked on VMware project SuperCollider - multicloud data platform with Spark, Kafka, and Parquet Lake.
Timeline
May 5, 2021 - Feb 29, 2024


