One Collector, Three Data Shapes: HTML, Directories & JSON

Matt Ashes


The challenge
Web-data jobs vary in layout, but rebuilding retrieval, pagination, deduplication, validation, and exports for every source wastes time and creates inconsistent QA.
The reusable approach
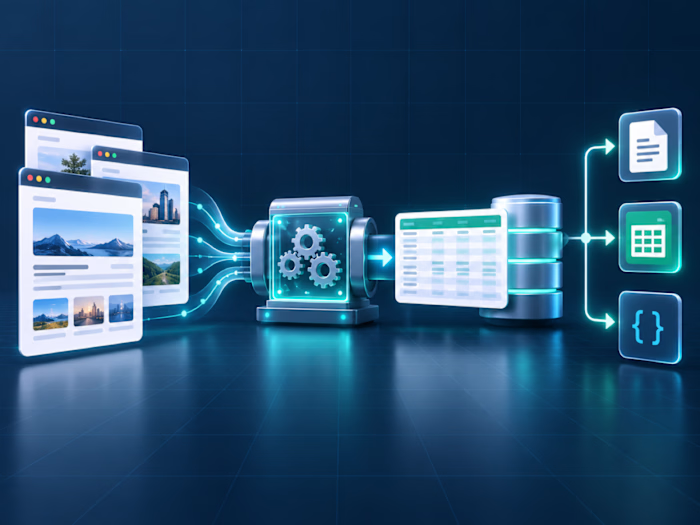
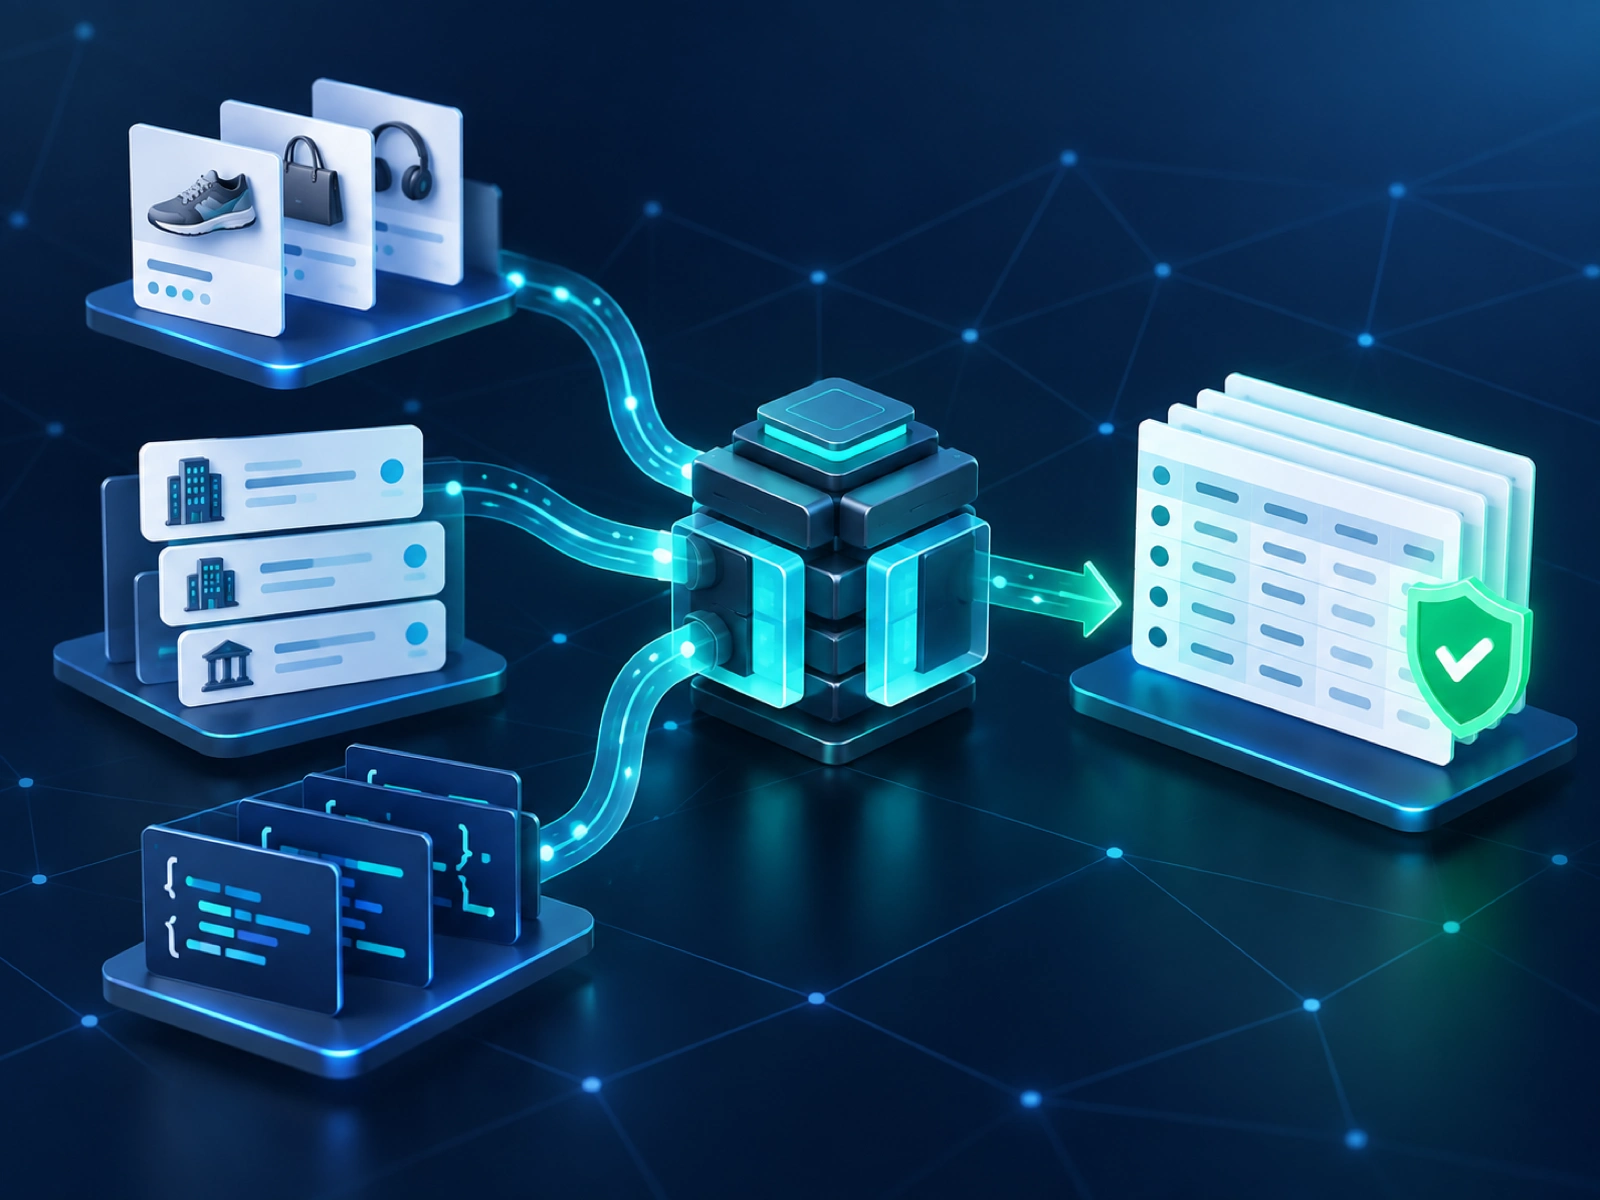
I built one configuration-driven collector and tested it against three independently defined source shapes: a product catalog with detail pages, an organization directory, and a paginated JSON service. Only the schema and selectors changed; the retrieval, verification, evidence, and delivery pipeline stayed the same.
Exact-reference results
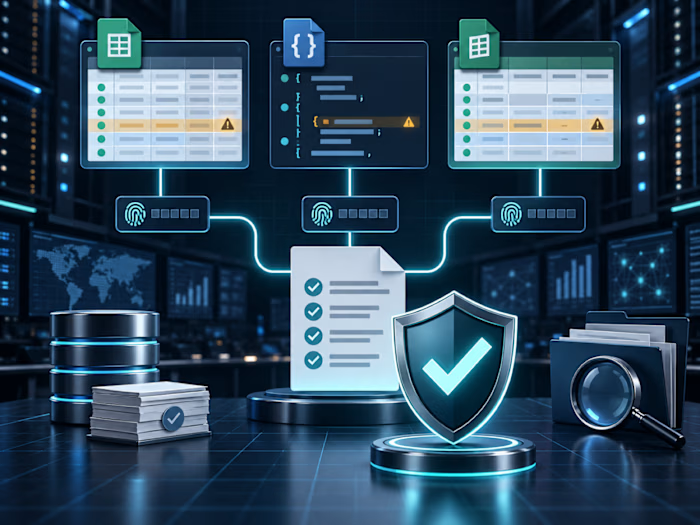
The product example matched 3 rows and 21 business values exactly. The organization directory matched 3 rows and 12 values exactly. The JSON example matched 3 rows and 18 values exactly. Every delivery passed its output verifier.
Change and failure handling
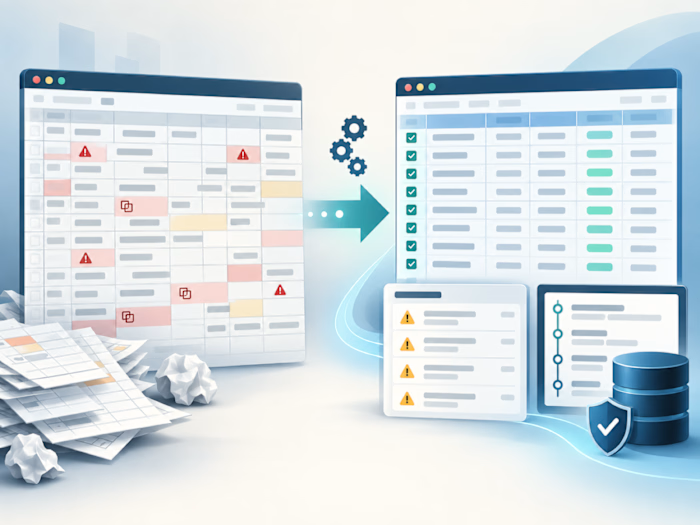
A controlled comparison correctly identified one added record, one changed field, and one missing record. When a page failed, the run was marked incomplete and change conclusions were suppressed. An interrupted run resumed from verified cached responses without duplicating records.
Client value
This makes a new supported source faster to configure while keeping coverage, source evidence, and acceptance criteria visible. Each real source still receives a feasibility sample before a full quote.
This is an independent synthetic portfolio demonstration, not paid client work.
Like this project
Posted Sep 21, 2026
Proved one reusable extraction engine across product catalogs, organization directories, and paginated JSON with exact reference matches.
Likes
0
Views
0