Verified Public-Web Collection: 1,000 Records, 50 Pages

Matt Ashes


The goal
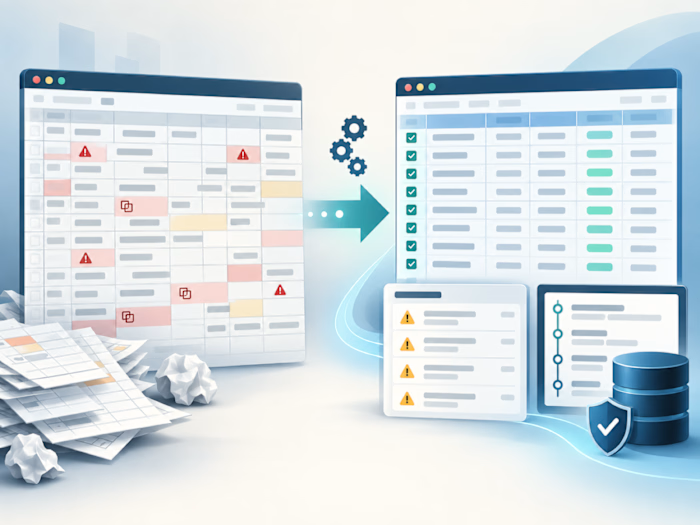
Collect a complete, reviewable dataset from a real public multi-page source without silently dropping pages, changing values, or delivering an unverifiable spreadsheet.
The workflow
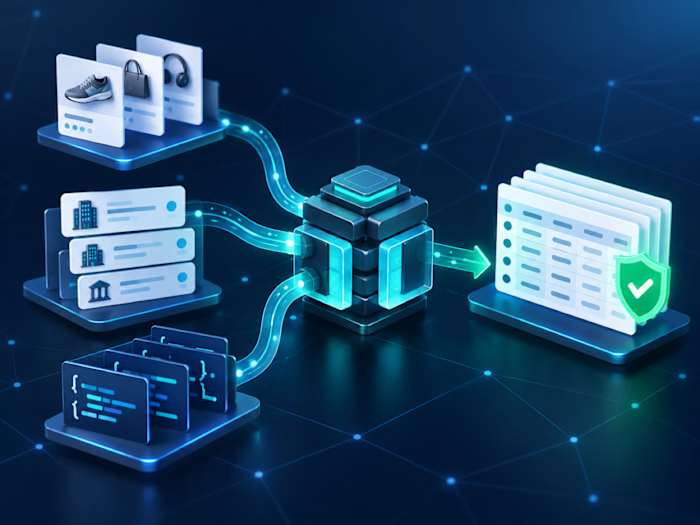
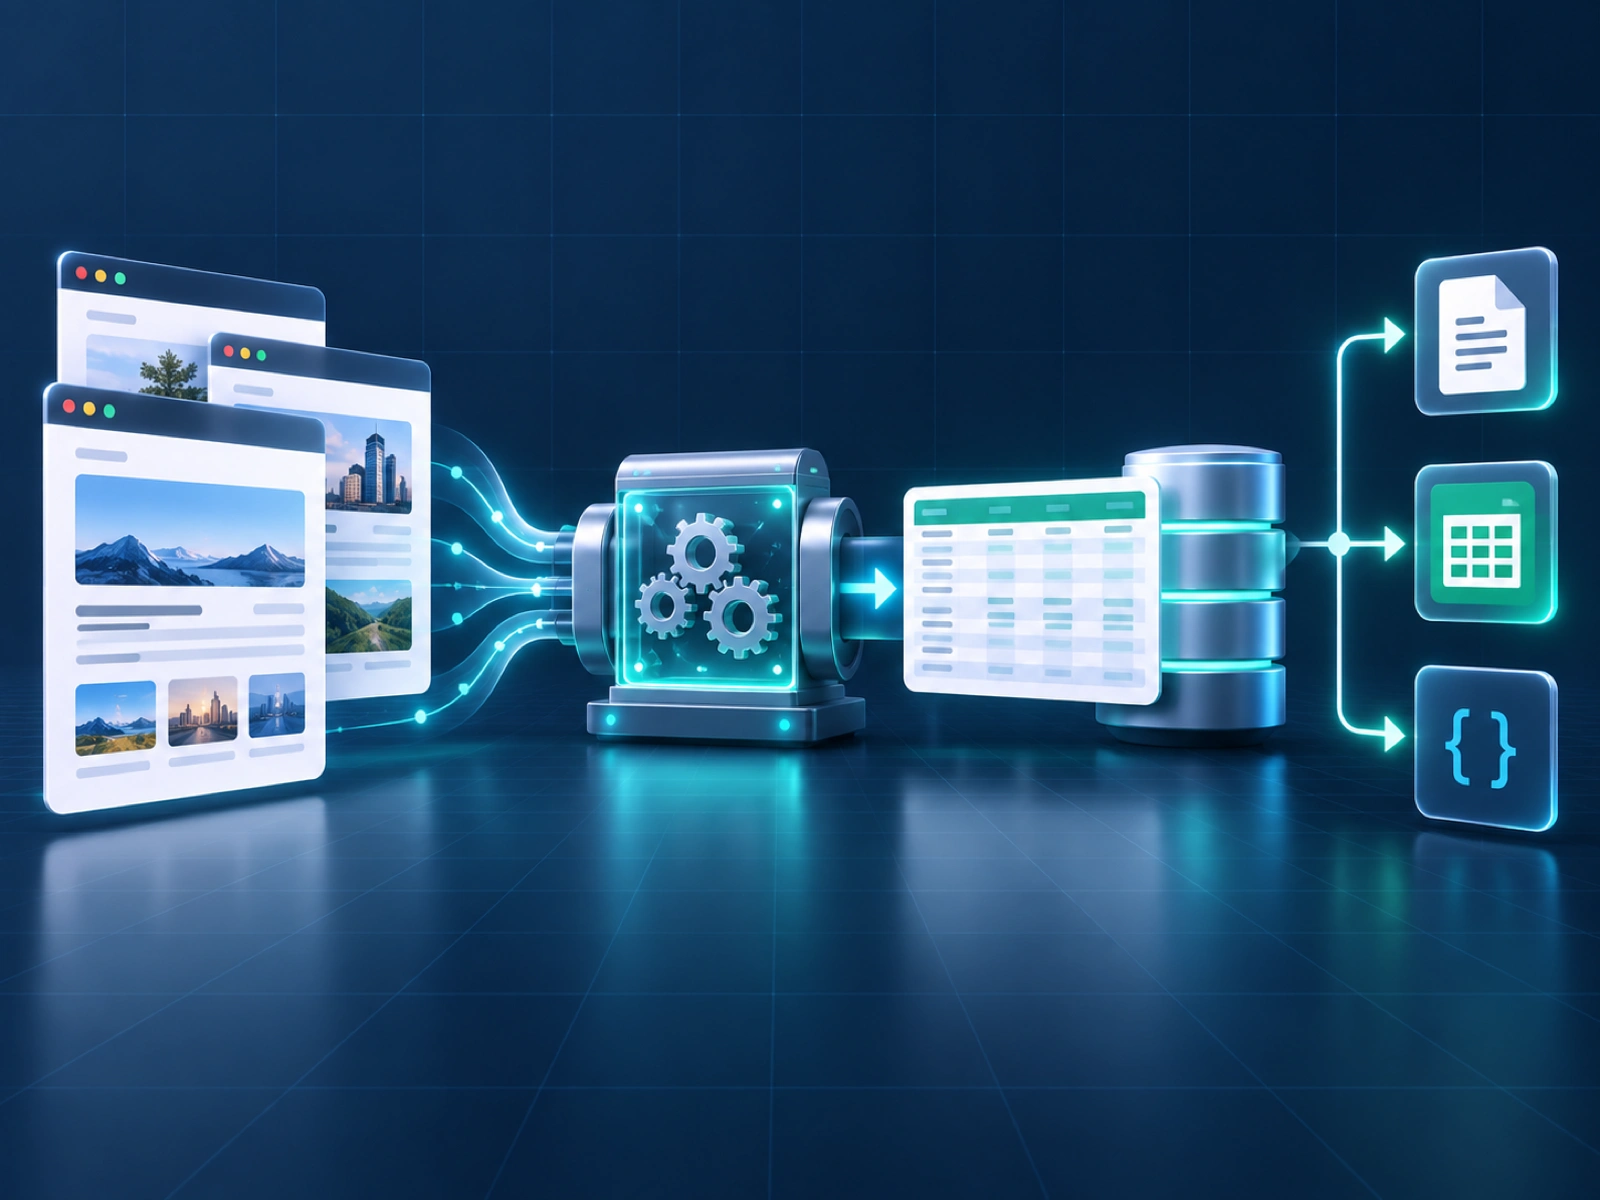
I configured a bounded Python collector for an explicitly designated scraping sandbox. It followed 50 public pages, preserved source URLs and response evidence, enforced the expected total, and exported the result as CSV, JSON, and Excel.
Verified result
The live run collected all 1,000 expected records. The delivery verifier re-read and compared all 1,000 CSV rows and all 1,000 Excel rows, confirmed 50 archived source responses, checked file hashes, and reported no coverage issues.
What the client receives
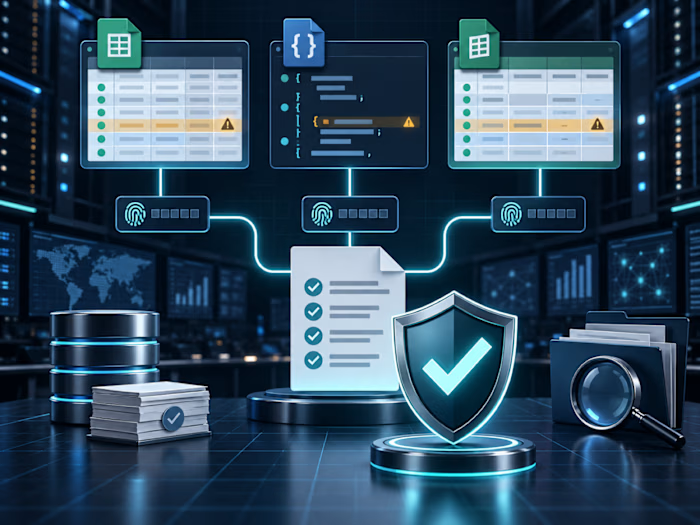
The delivery includes structured files, an offline coverage report, original response evidence, source timestamps, a manifest of file hashes, and a machine-readable verification record. Unsupported or incomplete runs are reported as incomplete instead of being presented as finished.
Scope boundaries
This demonstration covers bounded public HTML or JSON sources that do not require login, CAPTCHA bypass, or anti-bot evasion. A real client source is tested with a small sample before quoting the full job.
This is an independent live portfolio demonstration using a public scraping sandbox, not paid client work.
Like this project
Posted Sep 21, 2026
Collected 1,000 records across 50 public pages and verified every CSV and Excel row with archived source evidence and file hashes.
Likes
0
Views
0