Audit-Ready Data Delivery: Cross-Format QA & Failure Detection

Matt Ashes


Why this matters
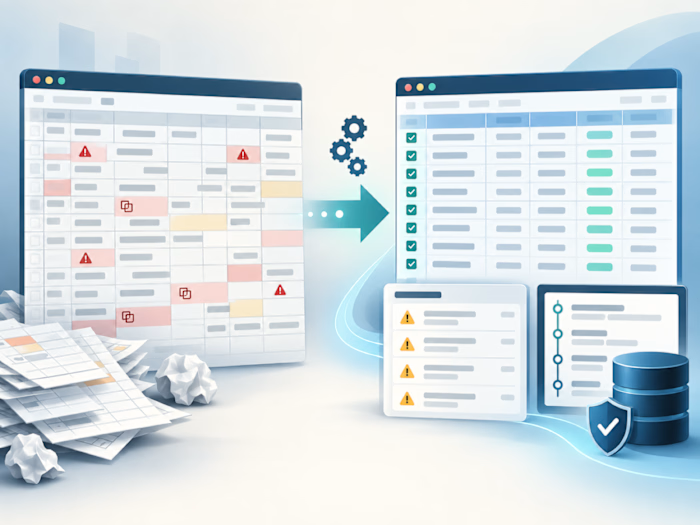
A scraper can run without crashing and still deliver missing pages, duplicate records, altered spreadsheet values, or files that cannot be audited. “The script finished” is not an acceptance test.
The QA layer
I built delivery checks around the collector rather than relying on visual review. The verifier re-reads CSV and Excel values, compares them with the internal records, validates file inventory and hashes, links records back to archived source responses, and flags unsafe or unsupported spreadsheet values.
Test evidence
The release passes 61 automated tests covering configuration validation, pagination, retries, robots handling, duplicate conflicts, response-shape changes, output preservation, formula-safe CSV exports, tamper detection, incomplete runs, change comparisons, and checkpoint resume.
Failure-first behavior
Expected totals, required fields, request limits, cycles, conflicting keys, failed pages, and malformed responses cannot silently become successful deliveries. Incomplete collections remain reviewable evidence packages, but they are labeled incomplete and are not used to claim missing or changed records.
Delivery standard
A client receives CSV, JSON, Excel, a standalone report, coverage and change files, archived response evidence, and a manifest. These checks prove delivery integrity and coverage under the agreed contract; they do not claim that public-source facts are inherently true.
This is an independent engineering portfolio demonstration, not paid client work.
Like this project
Posted Sep 21, 2026
Built a 61-test QA layer that rechecks CSV and Excel exports, verifies archived evidence and hashes, and refuses incomplete or ambiguous deliveries.
Likes
0
Views
0