Scaling Lead Scrapers with Smarter Lead Filtering

Widada W
Verified


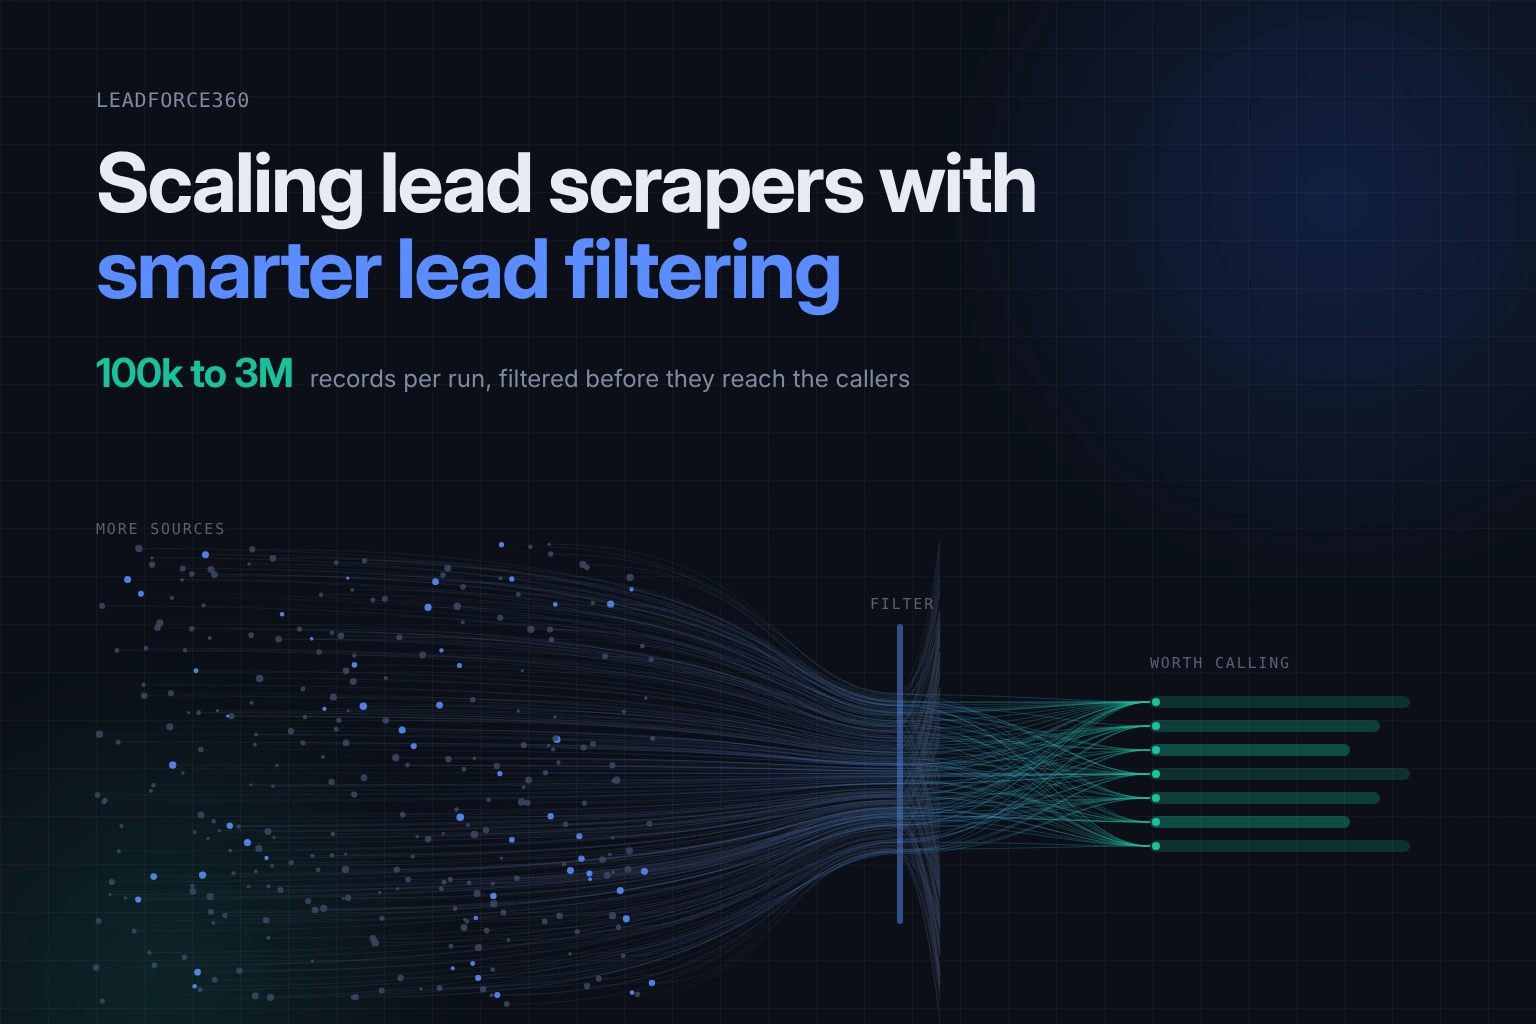
The problem
After the first round of scrapers went live, LeadForce360 needed more coverage and better consistency. Sources changed often, volumes kept growing, and not every scraped business was worth a call.
What I did
Expanded the scrapers to cover more sources and kept them stable as source sites changed
Maintained and optimized the pipeline in Node.js and Python so large runs finish reliably
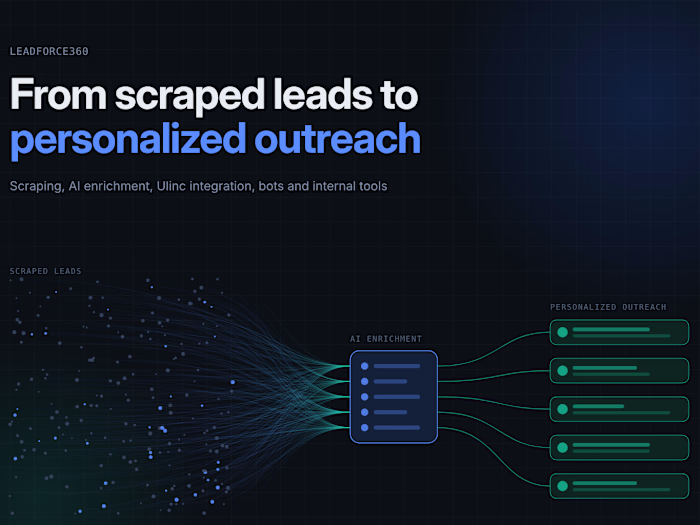
Added a lead filtering step, including a simple scikit-learn model, to flag which leads are worth calling
Kept NAICS mapping and campaign exports running so the telemarketing team always had fresh lists
Scale
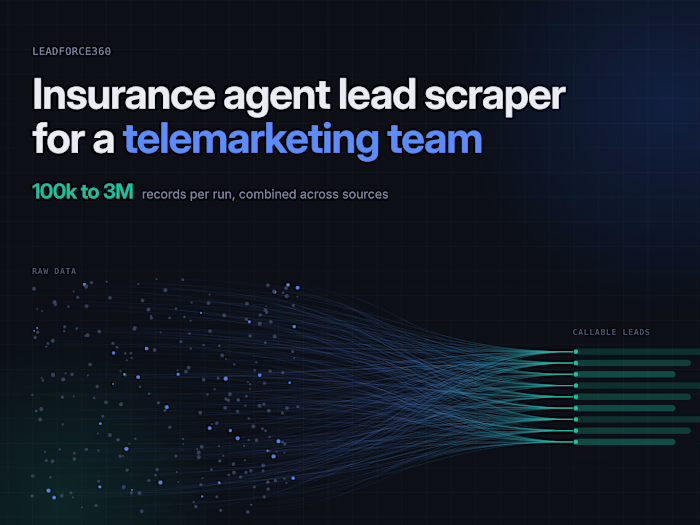
Combined across sources, runs typically collect between 100k and 3 million records.
Result
The team gets bigger, fresher lead lists with less noise, so callers spend less time on businesses that were never a fit.
This was the second phase of an ongoing engagement with LeadForce360, building on the scrapers from the first phase.
Like this project
Posted May 3, 2025
Expanded and maintained the lead scraping pipeline across more sources, and added a filtering step so the telemarketing team only gets leads worth calling.
Likes
1
Views
27
Timeline
Apr 30, 2025 - Sep 4, 2025
Clients
LeadForce360