Freelance Fullstack Engineers in Karachi
Sign Up
Post a job
Sign Up
Log In
Filters
2
Projects
People
Muhammad Hassan
pro
Karachi, Pakistan
Full-Stack & AI Developer | Next.js, AI Agents
$50k+
Earned
12x
Hired
5.0
Rating
243
Followers
Follow
Message
Full-Stack & AI Developer | Next.js, AI Agents
0
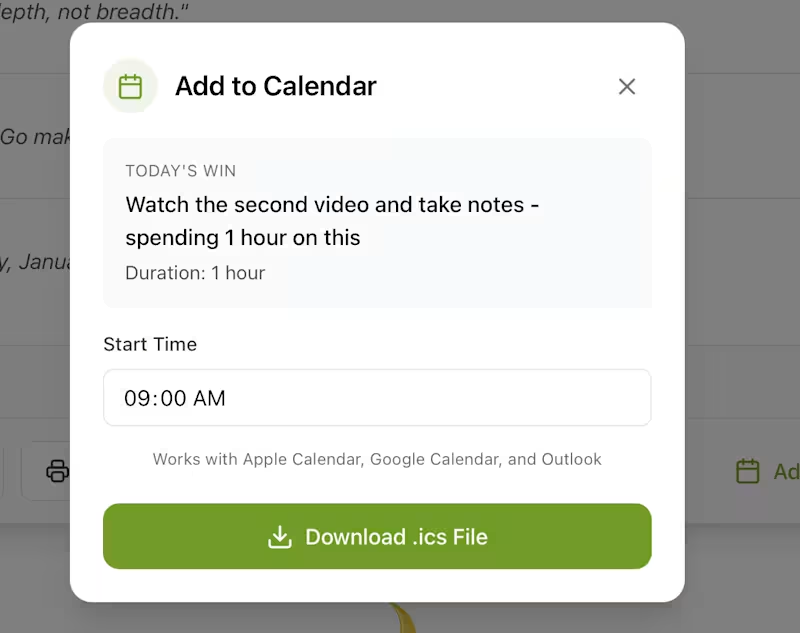
Add Session Timings to Calendar Directly Using Agent
0
4
0
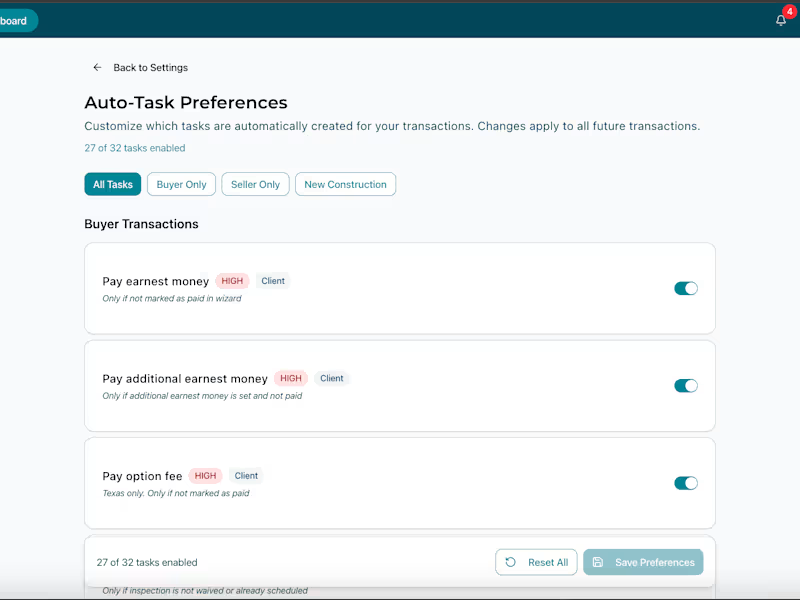
Automatic Rules Set for creating tasks
0
4
0
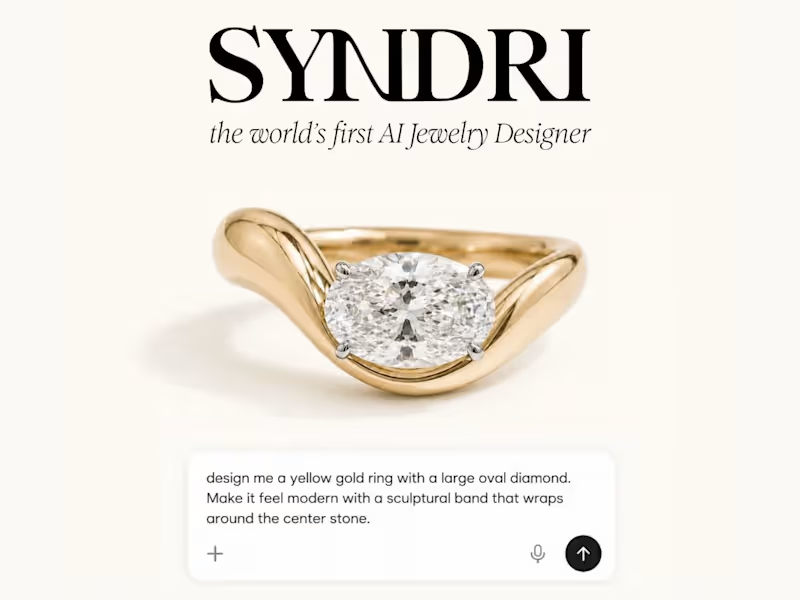
SYNDRI - the world’s first AI jewelry designer.
0
6
2
Rebuilding NestLink's Real Estate SaaS Platform
2
91
Fullstack Engineer
(22)
Follow
Message
Faarid Qureshi
pro
Karachi, Pakistan
Full-Stack & AI Developer | Next.js, AI Agents
$25k+
Earned
7x
Hired
5.0
Rating
54
Followers
Follow
Message
Full-Stack & AI Developer | Next.js, AI Agents
0
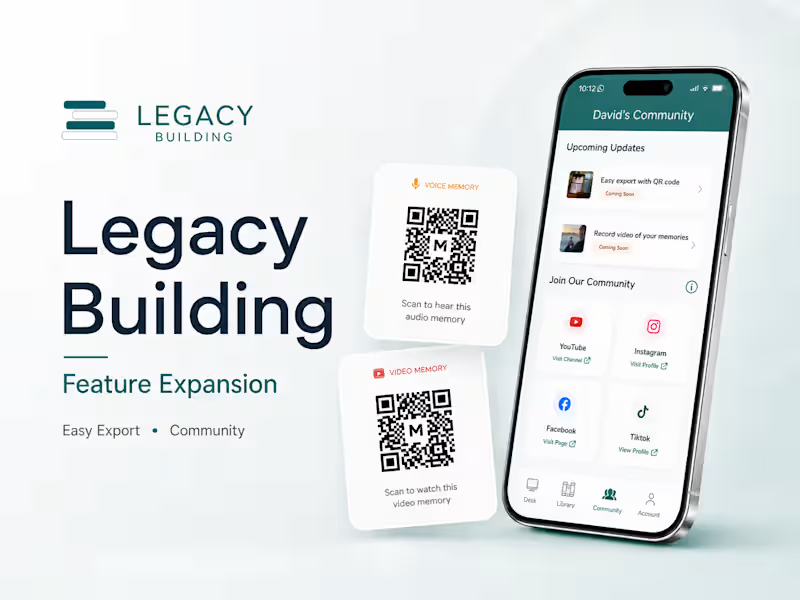
Legacy Building: Media Export & Community Features
0
10
2
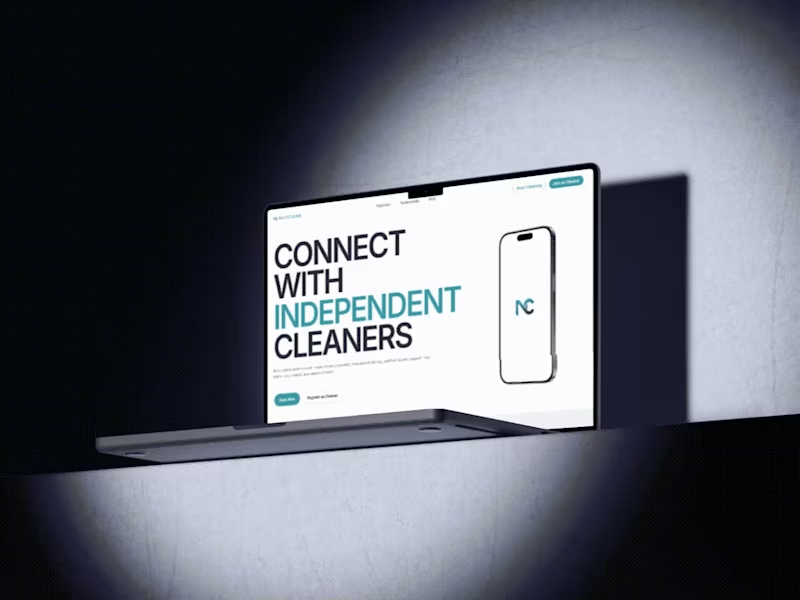
NextClean - Cleaning Service Platform
2
27
3
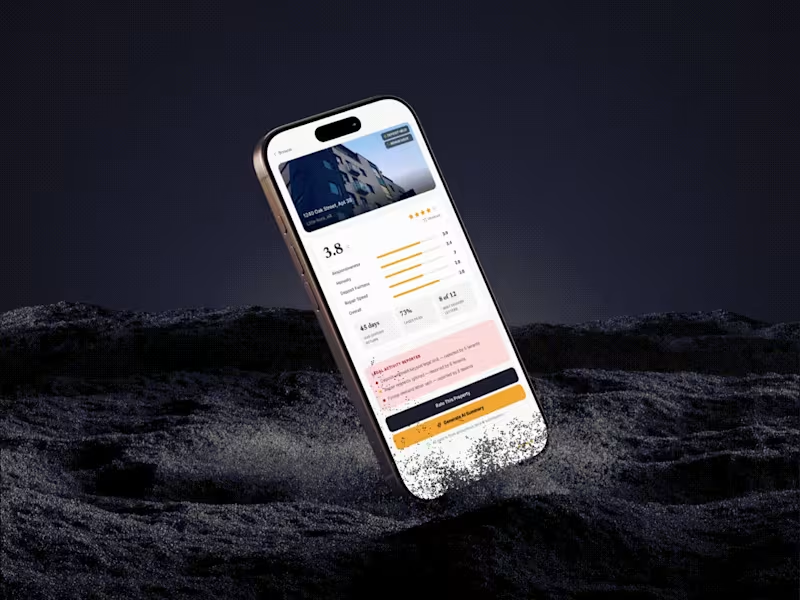
Traced - Tenant Advocacy Platform
3
28
2
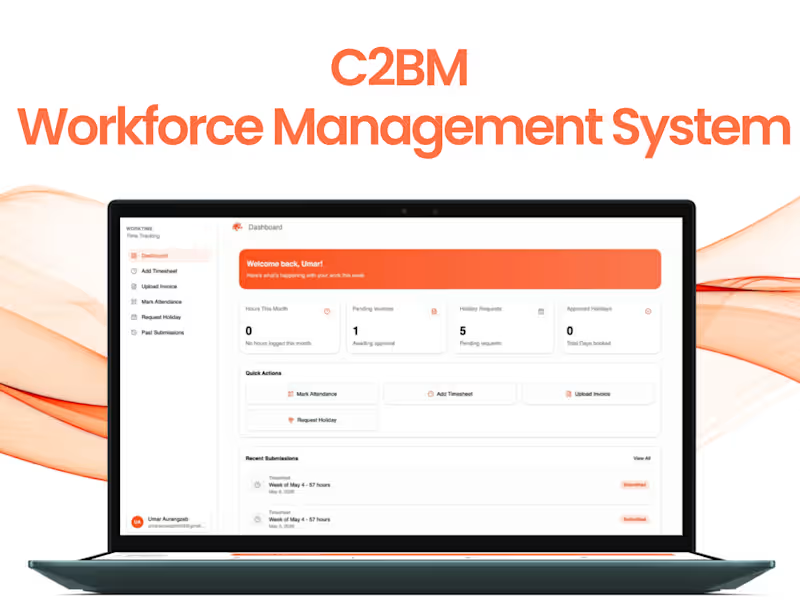
C2BM Workforce Management System
2
32
Fullstack Engineer
(27)
Follow
Message
Abdul Moiz Memon
pro
Karachi, Pakistan
Senior Full-Stack & Web3 Engineer | Technical Lead
$1k+
Earned
1x
Hired
5.0
Rating
20
Followers
Follow
Message
Senior Full-Stack & Web3 Engineer | Technical Lead
0
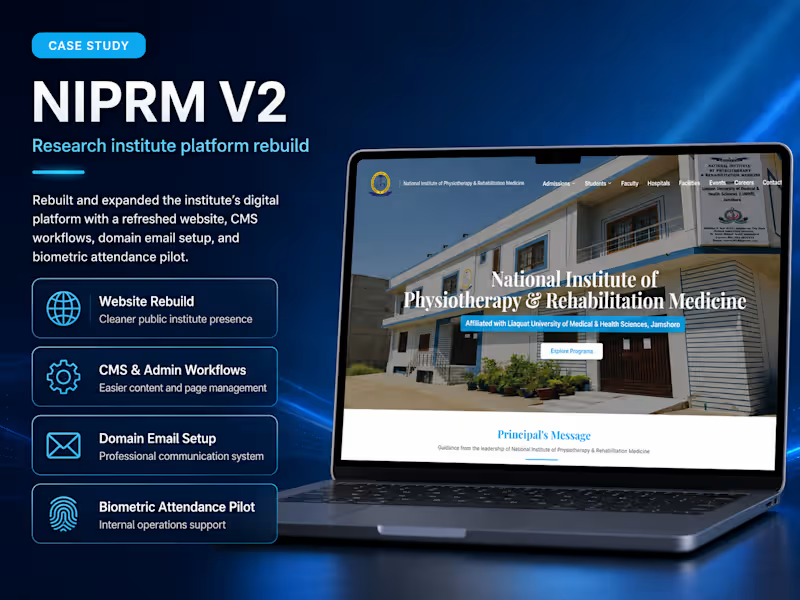
NIPRM V2 — Website, CMS & Biometric Attendance System
0
7
1
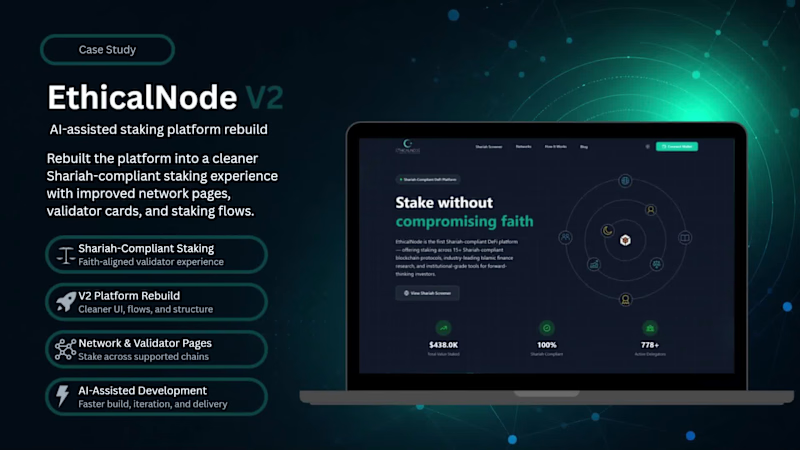
EthicalNode V2 — AI Assisted Platform Rebuild
1
8
1
Sahal Wallet — Cosmos Staking & Wallet Integrations
1
12
0
Throughput — Proof-of-Scheduling Blockchain Protocol MVP
0
15
Fullstack Engineer
(7)
Follow
Message
Ehtasham Ali
pro
Karachi, Pakistan
Production-ready AI agents and SaaS built to scale reliably.
$25k+
Earned
2x
Hired
102
Followers
Follow
Message
Production-ready AI agents and SaaS built to scale reliably.
3
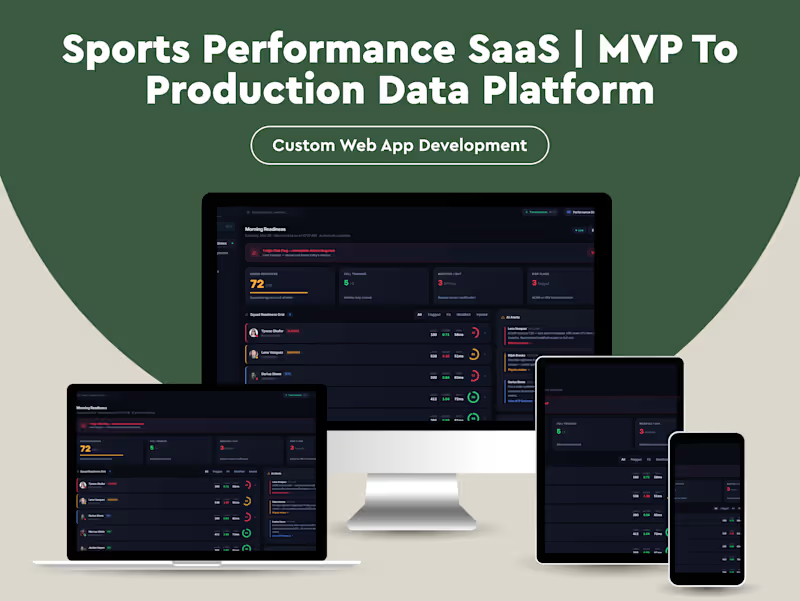
From Instinct to Infrastructure: How Athliq Went From Trainer's Notebook to Production Performance Platform ────────────────────────────────────────── The Person Who Understood the Problem Before Anyone Else Did Marcus had been a strength and conditioning coach for eleven years. He'd worked with professional football squads, Olympic track athletes, and NCAA programs. He knew exactly what was wrong with how performance data was managed, not because someone told him, but because he'd lived inside the problem every day. Every morning, he'd open four browser tabs, a spreadsheet, and a WhatsApp thread just to answer one question: Is this athlete safe to train today? HRV from one app. Sleep data from another. Yesterday's load from a Google Sheet. Wellness check-ins in a form nobody filled out consistently. Injury notes in a physio's personal folder. The picture was always incomplete, not because the data didn't exist, but because no system was designed to assemble it. He wasn't guessing the problem. He was the problem's daily victim. So he built something. ────────────────────────────────────────── The First Version Had Real Value What Marcus and a developer friend put together in six weeks was genuinely useful. A React frontend. Static JSON files simulating the data feeds he wished he had. A morning readiness dashboard showing each athlete's status: green, amber, red. ACWR calculations. A training plan view. A return-to-play protocol tracker. It looked like a real platform. It felt like one. When he demoed it to his performance director, the response was immediate: "This is what we've been trying to build for two years." The prototype surfaced something important. The problem wasn't that nobody had the data. The problem was nobody had designed the right lens to look at it through. Marcus had. His system organized information around the questions coaches actually ask, not the questions software vendors assume they ask. The initial build worked. For one squad. In static conditions. With fake data. And that was exactly the point where it started to matter, and exactly the point where its limitations became unavoidable. ────────────────────────────────────────── What Started Breaking The prototype had no backend. Data was hardcoded. Every "insight" was pre-written. The readiness scores didn't calculate; they were authored. When a second sport scientist saw the demo and said, "Can we plug in our GPS data?" there was no honest answer that didn't involve a complete rebuild. More specifically: The data layer was decorative. The JSON files looked real but required manual authoring for every scenario. There was no pipeline, no ingestion, no validation. Any live deployment would mean the dashboard showed stale or fabricated numbers, which in a performance context is worse than showing nothing at all. The AI insights were static strings. Every "AI-generated" recommendation was hardcoded text. In the prototype, this was fine. It demonstrated the concept. In production, it would mean the same insight appearing for every athlete regardless of their actual state, silently eroding clinician trust. The system had no concept of time. Training load calculations, ACWR ratios, wellness trends, all of these are temporal by definition. The prototype rendered them as snapshots. A real system needed rolling windows, historical comparison, and the ability to detect change over time. There was no role isolation. The role switcher in the UI was cosmetic. A physio and a performance director seeing the same underlying data with a CSS class change was not access control, it was theater. Nothing would survive a real integration. Real wearables return messy, incomplete, delayed data. The system had no error handling, no retry logic, no fallback states. The first real data feed would have broken the UI in ways that were invisible until they were catastrophic. The system was not wrong. It was early. ────────────────────────────────────────── Why They Didn't Just Fix It Themselves Marcus understood sport science. His developer understood React. Neither of them had built a production data system before, and that gap is not a skills deficiency, it is a domain specialization. What they needed was not someone to rewrite their frontend. The frontend was actually good. The visual hierarchy was sharp, the domain terminology was accurate, the workflows reflected how coaches genuinely think. That institutional knowledge was irreplaceable and not to be discarded. What they needed was: • A real-time data layer that could ingest from multiple sources reliably • A calculation engine that could run ACWR, load zone distributions, and readiness scoring against live data • A structured API contract between the front and back end • Authentication and role-based data scoping that actually enforced access boundaries • Observability, so when something silently broke, someone would know The prototype had proven the concept. The job now was to make the concept dependable. ────────────────────────────────────────── What We Actually Did We kept the frontend. Almost entirely. The visual design, the component architecture, the domain-accurate terminology, all of it stayed. We refactored the data layer, not the UI layer. The prototype's greatest strength was its UX fidelity to how coaches actually work, and we had no interest in rebuilding that from scratch. We built a real data ingestion pipeline. Rather than static JSON, we designed a service layer that could ingest from GPS units, HRV monitors, and wellness form submissions. Each source had its own adapter with validation, normalization, and error handling. Partial data was acceptable; silently wrong data was not. We replaced static calculations with a live computation engine. ACWR calculations now ran against a rolling 28-day window of actual load data. Readiness scoring pulled from real HRV baselines, not fixed numbers, and recalibrated as an athlete's personal baseline shifted over a training block. We replaced pre-written AI insights with a rules-based inference layer. Every insight shown in the platform now corresponded to a condition that was evaluated against live data. If Lena Vasquez's ACWR crossed 1.3 and her HRV dropped more than 15% from her 7-day baseline, the injury risk flag was triggered, not because it was hardcoded, but because those conditions were true. We implemented real role-based access control. A physio sees medical data, injury history, and RTP protocols. A sport scientist sees load analytics and benchmarks. A performance director sees the squad-level overview. A head coach sees readiness and today's session. The frontend already had role-switching built in, we gave it actual enforcement. We added observability throughout. Every data ingestion event was logged. Every calculation that produced an out-of-range result generated an alert. If a data source stopped sending, the system surfaced a staleness warning rather than silently displaying old numbers as current. ────────────────────────────────────────── Tech Stack React 19 + Vite, Tailwind CSS v3, Recharts, React Router v7, Node.js + Fastify, PostgreSQL + TimescaleDB, Redis, GPS/HRV/sleep data adapters (Catapult, Polar, Garmin), Google Forms/Typeform ingestion, Auth0, row-level security, Sentry, Datadog, Railway/Render, Vercel, Supabase Storage What Changed The morning workflow Marcus had been running across four tabs and a spreadsheet now ran in a single view that was populated automatically before he arrived at the training ground. The difference wasn't just convenience. It was confidence. When the dashboard flagged an athlete as high-risk, the coaching staff could interrogate why and trust the answer. When a return-to-play progression showed 80% completion, that number reflected actual criteria met against measured data, not a manually updated percentage. The platform was no longer a demo tool. It was a clinical decision-support system. For the squads using it, the shift was measurable: fewer reactive injury responses, more consistent load monitoring, and perhaps most importantly, a shared language between coaching staff, physios, and sport scientists built around the same data rather than competing interpretations of separate sources. ────────────────────────────────────────── The Part That Rarely Gets Said Most platforms built in this space start from the software side. Someone builds a data collection tool, adds a dashboard, and then tries to reverse-engineer what coaches actually care about. Athliq started from the other direction. A domain expert who understood the problem at a professional level built the frame first, and built it correctly. The pain points were real, the workflows were accurate, the terminology was precise. The engineering work didn't fix a bad idea. It made a good idea survivable. That distinction matters more than most technical case studies acknowledge. The hardest part of building a platform like this is not the infrastructure. It's knowing which questions to answer. That knowledge was already there. Our job was to make sure the system could keep answering them reliably, at scale, over time. ────────────────────────────────────────── Athliq is now in active deployment across two professional squads and one university performance program. The morning readiness dashboard processes real-time data from four integrated sources and serves role-scoped views to performance directors, sport scientists, physiotherapists, and athletes.
1
3
1.8K
2
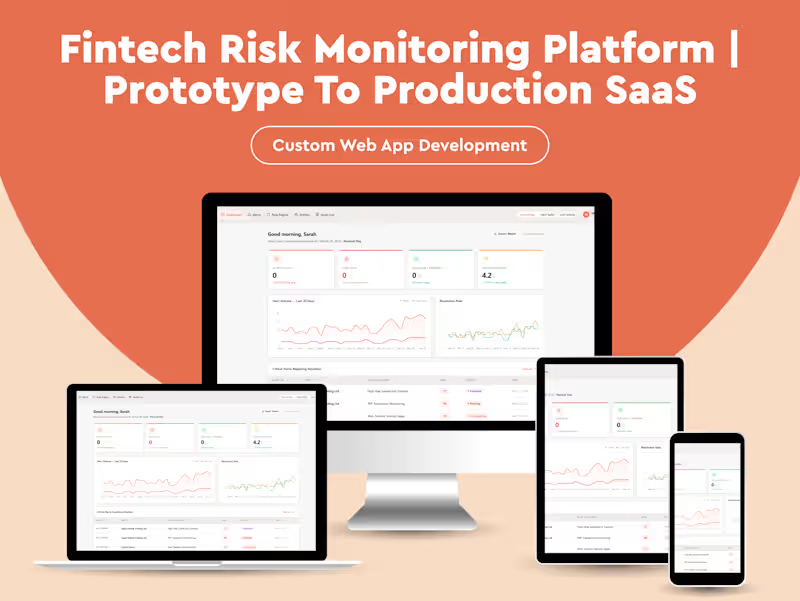
KovaRisk: When the Interface Knew More Than the System ────────────────────────────────────────── The Expert in the Room Compliance officers don't struggle to understand risk. They struggle to act on it fast enough. The team behind KovaRisk understood this precisely. They had spent years inside financial institutions watching the same dysfunction repeat: alerts buried in spreadsheets, investigations tracked in email threads, audit trails reconstructed after the fact. They knew what the interface needed to feel like because they'd lived with the one that didn't. So they built it. Fast. Exactly as they'd imagined it. What emerged was sharp: a risk monitoring dashboard with filterable alert feeds, entity profiles with 12-month risk trajectories, a rule engine with toggle controls, and an audit log that felt immutable. The scenario switcher let compliance teams stress-test different alert load states. The side panel made investigations feel contained and intentional. It looked like a system that had survived production. It hadn't been asked to yet. ────────────────────────────────────────── What Existed Was a Strong Interface - Not a System Every alert in KovaRisk was generated at startup. Every risk score was computed by a random seed function. Every status change - Investigating, Resolved, Escalated - lived in component state. Every timeline event was appended to an in-memory array. Every rule toggle disappeared on refresh. The audit log recorded nothing. The export downloaded a snapshot of what React was holding at that moment. The entity risk history was a curve drawn from a formula, not a record. The logic was there. But it had nowhere to live. A compliance officer investigating a high-risk wire transfer would open the side panel, read the plain-English rule explanation, mark the alert as Investigating, add an internal note - and lose every one of those actions the moment they refreshed the browser. No colleague could see what they'd done. No regulator could verify it had happened. In financial compliance, that's not a UX problem. It's a liability. The prototype validated the workflow brilliantly. It exposed exactly how a compliance team would move through their day. But three things were missing: a source of truth, a coordination layer, and a trail that could be audited under pressure. ────────────────────────────────────────── They Didn't Need More Features - They Needed a System Behind the Interface The team came with a clear idea and a working prototype. What they needed was the architecture that made the prototype a product - the layer that turned interface actions into durable facts. Not a rebuild. A foundation. ────────────────────────────────────────── The Layer That Made It Dependable Data Models: Giving State a Home The first thing to reconstruct was where the data should actually live. KovaRisk's frontend implied a clear schema - alerts, entities, rules, audit events - but none of it persisted. The production system needed a PostgreSQL core with five primary entities: • Alert — with foreign keys to Entity, Rule, Transaction, and a JSONB timeline column for ordered event history • Entity — with risk tier, jurisdiction metadata, and a one-to-many relationship to RiskScore snapshots • Rule — with active/disabled state, trigger thresholds, false-positive tracking, and a versioning mechanism so changes to rules didn't retroactively alter historical alerts • AuditEvent — append-only, with actor ID, action type, target reference, and a server-generated timestamp that clients cannot modify • InternalNote — owned by an alert, with authorship and a soft-delete flag to preserve compliance integrity Every status change, note, escalation, and flag the UI handled ephemerally became a write to this schema. The Alert Generation Engine: Replacing the Seed Function In the prototype, 85 alerts appeared because a loop ran 85 times at startup. In production, alerts are the output of a Transaction Monitoring Service - a background process that runs continuously against incoming transaction streams. This service: • Evaluates each transaction against every active Rule definition • Computes a risk score using rule weights, entity risk tier, jurisdiction flags, and behavioral baselines • Creates an Alert record only when a threshold is breached • Emits an event to a notification queue for high-risk triggers The rule engine the UI let users toggle wasn't decorative. Each rule mapped to an evaluation function in the monitoring service. Disabling a rule didn't just grey out a card - it removed it from the active evaluation set. Re-enabling it didn't retroactively generate alerts it would have caught; it resumed from the point of activation. That distinction mattered for regulatory defensibility. ────────────────────────────────────────── Async Workflows: The Operations the UI Implied But Couldn't Sustain Several interactions in the prototype implied workflows that couldn't complete synchronously. Escalation - When an alert was escalated, the UI changed a status badge. In production, escalation triggers a queue job that: notifies the senior compliance officer via a configured channel, creates a case record linking the alert, and starts a response SLA timer. The UI reflects the outcome - it doesn't produce it. Scheduled Screening - The Sanctions Screening Match rule in the prototype was static. In production, it's a nightly job that re-screens all active entities against updated OFAC, EU, and UN sanctions lists - generating new alerts if a previously clean entity now appears. The results feed back into the alert pipeline. Report Export - The dashboard's Export Report button downloaded a text file of whatever React was holding in memory. In production, report generation is an async job: the user requests the report, the job runs server-side against the live database, and a download link is returned when ready. The content is a verifiable, timestamped record - not a UI snapshot. ────────────────────────────────────────── The Audit Log: From Feed to Fact The prototype's audit log was populated by a generateAuditLog function. It looked comprehensive and immutable. It was neither. Production audit events are written by the API layer on every state-modifying operation - before the response is returned to the client. The table is append-only. No update operations are permitted on AuditEvent records. Timestamps are server-generated in UTC and stored with full precision. Actor identity comes from the authenticated session, not from a string the client sends. The audit log the interface displayed was a simulation of accountability. The production version is the accountability. ────────────────────────────────────────── Tech Stack 1. Frontend: React + Vite, React Router v6, Recharts, React Context + local state, TanStack Query 2. Backend: Node.js + TypeScript, Fastify, Prisma, PostgreSQL, Redis, BullMQ, Passport.js + express-session 3. Infrastructure: AWS ECS / Railway / Render, S3, AWS Secrets Manager / Doppler, Sentry + Datadog, GitHub Actions 4. External Integrations: OFAC / ComplyAdvantage, Refinitiv World-Check, SendGrid / SMTP, Webhooks ────────────────────────────────────────── From Interface to System The prototype answered the right questions. It proved the workflow was sound, the information hierarchy was correct, and the alert investigation pattern worked the way compliance officers needed it to. What it couldn't answer was: what happens when two investigators open the same alert simultaneously? What happens when a rule change needs to take effect immediately across 200 pending alerts? What happens when a regulator asks for every action taken on a specific entity over the past 18 months? Those questions don't live in the interface. They live in the system. KovaRisk's interface was always strong. What it needed was the architecture to make it real - persistent, coordinated, auditable, and defensible under scrutiny. The logic existed from the beginning. We gave it somewhere to live.
2
1.8K
2
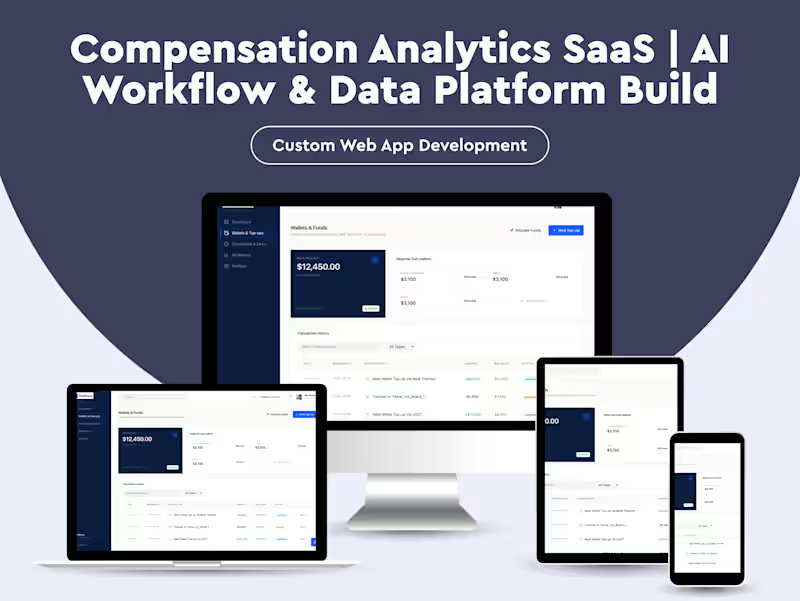
Case Study: From Prototype to Production — Building a Credit Management Platform for Ad Operations The Starting Point The founder wasn't guessing the problem. They had spent years inside the ad-credit ecosystem, managing wallet balances across regions, reconciling top-ups via bank wire and stablecoin, chasing compliance documents, and watching campaigns stall because a pixel stopped firing at 2am. They knew exactly what a credit management platform needed to look like. So they built one. Using Figma wireframes translated directly into a React frontend, they shipped a working prototype in days. Two portals were created. One for clients managing wallets and ad accounts, and one for internal operators handling treasury, compliance, and risk. It included real-time spend charts, AI-driven anomaly detection banners, a work queue for ops teams, and an embedded AI assistant that could answer questions about balances, compliance status, and pixel health. The prototype proved the concept. Clients could see their wallet balances, request top-ups, allocate funds to ad accounts, and track campaign performance. Admins could manage treasury operations, review KYB pipelines, monitor risk scores, and process a prioritized work queue. The domain logic was sound. The UX was sharp. But the system was never designed to survive real load. What Started Breaking The prototype worked on mock data. Every API call returned hardcoded arrays after a random delay. There was no backend. No database. No real authentication. The login screen accepted any email and assigned a role based on a toggle switch. Session state lived in localStorage as a raw JSON blob. This was fine for demos. It stopped being fine the moment real money entered the picture. The specific fractures: 1. No transactional integrity. Wallet balances, top-ups, fund transfers, and ad account allocations were all simulated. In a live system, a transfer of $25,000 from a master wallet to a regional sub-wallet is not a UI state change. It is a financial transaction that requires atomicity, audit trails, and rollback capability. The prototype had none of this. 2. Compliance was cosmetic. KYB document statuses were static labels. In production, document verification involves third-party identity providers, expiration tracking, automated re-upload reminders, and regulatory audit logs. The prototype rendered badges like "Verified", "Pending", and "Missing", but nothing enforced the state machine behind them. 3. Risk scoring was decorative. The AI risk badges showed tooltips like "Large P2P transfer detected, document expiring", but these were string literals, not outputs from a scoring model. Real risk assessment requires transaction pattern analysis, velocity checks, cross-referencing compliance status, and escalation workflows that route to the right ops agent. 4. The work queue had no backend. Urgent items like "$45,000 P2P transfer anomaly" appeared in the queue, but resolving them was just a frontend state toggle. There was no case history, no assignment logic, no SLA tracking, and no integration with the compliance or treasury systems that actually needed to act on these events. 5. Multi-tenancy was absent. The platform served one mock client and one mock admin. Scaling to dozens of clients, each with their own wallets, sub-wallets, ad accounts, compliance profiles, and credit limits, required data isolation, permissioning, and tenant-aware queries that did not exist. 6. Ad platform integration was faked. TikTok metrics like impressions, clicks, ROAS, and pixel health were all static datasets. Production requires OAuth-based API integrations, rate-limited data syncing, webhook listeners for pixel status changes, and graceful degradation when platform APIs go down. The founder understood all of this. The prototype was never meant to be the product. It was meant to prove that the product was worth building. Why They Brought In a Team The gap between the prototype and production was not a matter of fixing bugs. It was an architecture problem. The founder needed: - A real backend with transactional guarantees for financial operations - A compliance engine that could enforce document workflows across jurisdictions - A risk system that could ingest transaction data and surface actionable alerts, not static strings - Multi-tenant data architecture with proper isolation and access control - Ad platform integrations that could handle real API contracts, rate limits, and failures - Observability including logging, monitoring, and alerting so the ops team could trust the system under load They did not need someone to rewrite the frontend. They needed someone to build the system underneath it. What We Delivered Financial Operations Layer We replaced the mock API with a transactional backend. Every wallet operation, including top-ups, transfers, allocations, and refunds, now runs through an auditable pipeline with: - Atomic balance updates with optimistic locking - Double-entry ledger for every fund movement - Idempotent transaction processing to prevent duplicate charges - Full audit trail with actor, timestamp, and before and after state Top-up requests now flow through a verification pipeline with submission, proof-of-payment upload, approval, and balance credit. Each step is recorded and reversible. Compliance and KYB Engine - We built a document lifecycle system that replaces static badges with enforced state transitions: - Documents move through missing → uploaded → under_review → verified → expired with rules governing each transition - Expiration monitoring triggers automated client notifications before deadlines - Third-party identity verification integration for director ID matching - Jurisdiction-aware requirements where different regions require different document sets - Audit-grade logging for every status change, reviewer action, and override The KYB pipeline now routes cases to specific compliance agents based on workload, region, and verification type. Risk and Anomaly Detection We replaced hardcoded risk labels with a scoring system that evaluates: - Transaction velocity based on spend acceleration versus historical baseline - P2P transfer patterns and threshold breaches - Compliance status correlation, such as expired documents combined with high spend - Account dormancy detection where inactivity triggers review Risk scores update in near real time. High-risk events automatically generate work queue items with priority, context, and suggested actions. Work Queue and Case Management We transformed the frontend-only task list into an event-driven operations system: - Events from treasury, compliance, and risk systems automatically create queue items - Assignment logic routes items to the right agent based on type, region, and capacity - SLA tracking with escalation rules for overdue items - Case history that records every action, note, and resolution - Enforced status transitions so items cannot be resolved without required actions Multi-Tenant Architecture We designed the data layer for tenant isolation from the ground up: - Each client organization has isolated wallets, documents, ad accounts, and transaction histories - Role-based access control separates client-facing and admin-facing data - API endpoints are tenant-scoped to prevent cross-tenant data leakage - Admin views aggregate across tenants with proper permissioning Ad Platform Integration We built a sync layer for TikTok Ads with an architecture that supports additional platforms: - OAuth-based account linking with token refresh management - Scheduled metric pulls with rate limit awareness and backoff - Pixel health monitoring via event signal tracking instead of static labels - Graceful degradation where stale data is clearly labeled if APIs fail Observability We added the infrastructure the ops team needs to trust the system: - Structured logging for every financial operation, compliance action, and API call - Health dashboards for backend services, integration sync status, and queue throughput - Alerting on anomalies such as failed transactions, sync delays, and SLA breaches - Error tracking with business context, not just stack traces The Outcome The system went from a prototype that could demo well to a platform that could process real money, enforce real compliance, and surface real risk under real load. What changed: - Financial operations now run with transactional guarantees. Wallet balances are accurate, auditable, and reconcilable. - Compliance is enforced, not displayed. Document workflows follow regulated state machines with full audit trails. - Risk detection is continuous and contextual. The ops team acts on scored alerts instead of static labels. - The work queue drives operations. Events flow in automatically, route correctly, and track resolution against SLAs. - Multi-tenancy works. New clients onboard into isolated environments without architectural changes. - Ad integrations sync reliably. When they fail, the system clearly shows it instead of masking stale data. The founder’s instinct was right from the start. The domain model, the UX, and the operational workflows all held up. What we built was the engineering foundation that made it dependable. The system worked until it didn’t. Not because the idea was flawed, but because it was never designed to handle this level of complexity. The prototype proved the product. The production system proved it could scale. Tech Stack Overview 1. Backend: Node.js (NestJS) 2. API: GraphQL 3. Auth: Auth0 4. Database: PostgreSQL 5. Cache/Queue: Redis 6. Search: Elasticsearch 7. Infrastructure: AWS 8. Containers: ECS Fargate 9. CI/CD: GitHub Actions 10. IaC: Terraform 11. Integrations: Stripe 12. Risk Engine: Python (FastAPI) 13. ML Pipeline: scikit-learn 14. AI Assistant: OpenAI GPT-4 15. Vector Store: Pinecone
2
1.7K
1
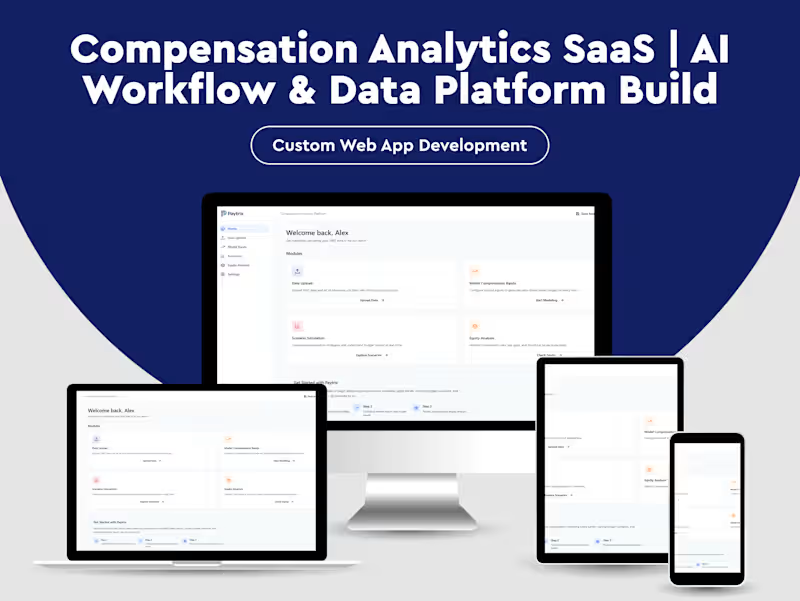
Paytrix: From Interface Logic to Compensation Infrastructure The Insight The builder behind Paytrix understood compensation deeply, not as a payroll function, but as a structural problem. They knew that most companies manage salary bands in spreadsheets, that job title normalization is a nightmare at scale, and that equity analysis gets ignored until it becomes a legal liability. They knew this because they lived it. So they built what they knew. Fast. What Existed Paytrix, as delivered, was a polished React application, built with Vite, Tailwind, Radix primitives, and Recharts, spanning six distinct modules: a dashboard, an HRIS data upload flow, a compensation modeling engine, a scenario simulator, an equity analysis suite, and a settings panel. The interface was sharp. The workflows were correct. A user could upload employee data, watch AI "normalize" job titles into a structured architecture, model salary bands against market percentiles, run budget impact scenarios, and review compression risks across career levels. It looked like a product. But every piece of logic lived on the client. Where It Breaks The 114 employees in the system are not uploaded. They are hardcoded in a TypeScript file. The "AI normalization" is a setInterval cycling through four progress labels over two seconds. Market benchmarks are arithmetic constants (industryPremium = 0.08). The equity analysis, compa-ratios, range penetration histograms, compression heatmaps, renders from static arrays defined at the top of the component. Scenario simulation multiplies a base salary by a percentile offset. The entire application state persists to localStorage. None of this is a criticism. It's what a vibe-coded prototype should be: directionally correct, visually convincing, structurally hollow. The problems emerge when you try to use it: • No persistence. Clear your browser, lose your scenarios. There's no database, no user accounts, no tenant isolation. • No real data ingestion. The upload flow accepts nothing. There's no CSV parser, no file handler, no validation pipeline. The "AI" that maps "Sr. Software Engineer" to "Engineering / L3 - Mid-Level" is a pre-written array with confidence scores already assigned. • No market data layer. Salary benchmarks are invented constants. There's no connection to BLS, Radford, Mercer, or any compensation data provider. The "industry premium" and "funding stage adjustment" are fixed floats that don't change regardless of input. • No computation engine. Compa-ratios, range penetrations, and compression risks are display values, not derived metrics. Change an employee's salary in the mock data and the equity charts do not move, because the charts read from a different hardcoded array. • No multi-user support. "Welcome back, Alex" is a string literal. There's no auth, no RBAC, no concept of who should see what. The logic was all there. It just had nowhere to live. The System That Needed to Exist What Paytrix required was not more UI work. It required the invisible layer that makes compensation software trustworthy. Data Ingestion Pipeline A backend service that accepts HRIS CSV uploads, validates schema (employee ID, title, department, salary, location, demographics), handles malformed data gracefully, and stages records for processing. This is not a file drop. It is an ETL pipeline with column mapping, deduplication, and audit logging. The upload endpoint needs to support files from Workday, BambooHR, Rippling, and manual exports, each with different schemas. Job Architecture Normalization Service The prototype simulates AI-driven title mapping. In production, this is a classification service, likely backed by an LLM or a trained model, that ingests raw job titles and maps them to a canonical taxonomy of families and levels. It needs to handle ambiguity ("Sr. Software Engineer" vs. "Senior Software Engineer" vs. "SWE III"), surface confidence scores that reflect model uncertainty, and support human-in-the-loop correction that feeds back into the model. This is a backend job queue, not a frontend animation. Market Data Integration Layer Compensation modeling requires real benchmark data. The system needs API integrations with at least one primary data provider (Radford, Mercer, Comptryx) and the ability to ingest custom survey data. Market rates need to be indexed by role, geography, industry, company size, and funding stage. This is a multi-dimensional lookup that changes quarterly. This data must be versioned and cacheable, with fallback logic when specific cuts are not available. Compensation Calculation Engine The core math, midpoint derivation, band construction, compa-ratio computation, range penetration, compression detection, needs to run server-side against real employee records and real market data. The prototype calculates midpoint = baseMarket * (1 + industryPremium + fundingAdjustment) * percentileMultiplier. In production, this becomes a parameterized model where each variable is resolved from the market data layer, scoped to the company’s configuration, and applied across every employee in the dataset. Band width, skills premiums, and geographic differentials are all configurable per job family. Scenario Persistence and Comparison The prototype stores scenarios in React context backed by localStorage. Production requires a database-backed scenario system where a user can save named configurations, compare them side by side, share them with stakeholders, and track which scenario was ultimately adopted. Each scenario needs to carry its full parameter set, the resulting budget impact, and a snapshot of the employee population it was run against. Equity Analysis Engine The hardcoded charts need to be replaced by a statistical analysis service. Gender and ethnicity pay gap calculations require controlled regression, adjusting for level, tenure, location, and department, not raw averages. Compression detection needs to compare adjacent levels within the same job family dynamically. Flagged roles need to be generated algorithmically, not listed manually. Authentication, Tenancy, and Access Control Compensation data is among the most sensitive in any organization. The system needs proper auth (SSO at minimum for enterprise), tenant isolation so each company sees only its data, and role-based access so an HR analyst sees different things than a VP of People. Audit logging is non-negotiable. Every view, edit, and export must be tracked. What Changed The interface did not need to be rebuilt. It needed something behind it. What was a demo became a system. What was localStorage became a database. What were constants became integrations. What was a progress bar became a processing pipeline. The prototype proved the idea was right. The architecture made it real. From demo-ready to production-ready. From UI-driven logic to system-driven reliability. We built the layer that made it dependable.
1
1.7K
Fullstack Engineer
(7)
Follow
Message
Zaid Ali
Karachi, Pakistan
Full Stack Developer | Custom SaaS & Web Applications
5.0
Rating
3
Followers
Follow
Message
Full Stack Developer | Custom SaaS & Web Applications
2
There's something satisfying about building the part users never see. This Node.js backend powers the entire application - from APIs and authentication to database operations. Clean code. Scalable architecture. Reliable performance. On to the next build. 🚀
2
235
1
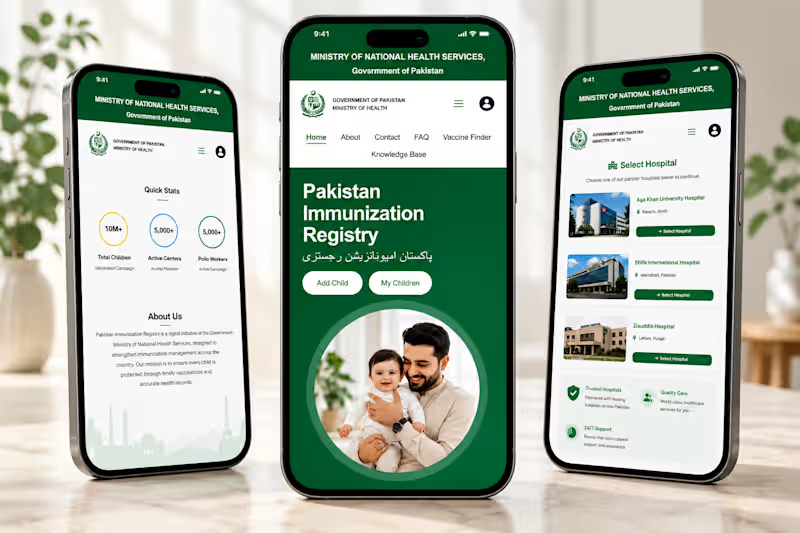
Pakistan Immunization Registry
1
5
1
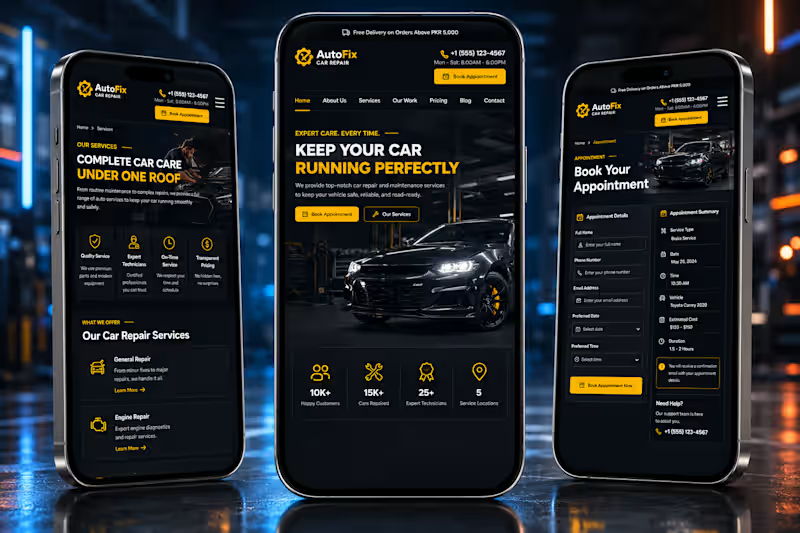
AutoFix Car Repair System | Garage Management
1
3
0
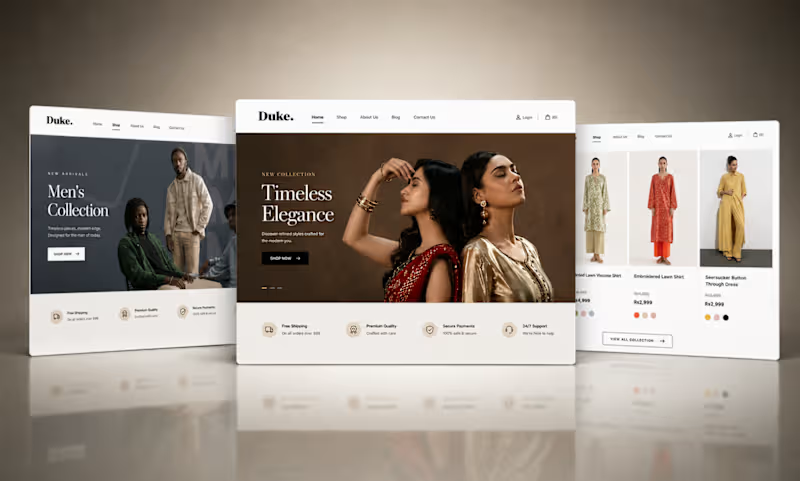
Duke | Modern Fashion E-Commerce Website
0
10
Fullstack Engineer
(3)
Follow
Message
Moid Khan
Karachi, Pakistan
Product Builder | Nurturing Ideas into ROI $$$ | moidrk
$1k+
Earned
5.0
Rating
61
Followers
Follow
Message
Product Builder | Nurturing Ideas into ROI $$$ | moidrk
1
ESHAAT - Donation Portal WebApp Design & Development
1
10
1
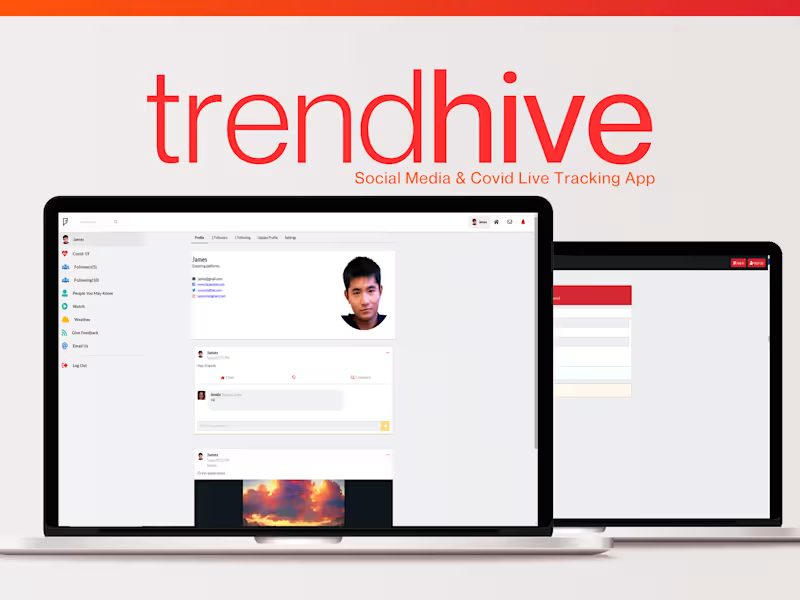
TrendHive - Social Media Full App Design & Development
1
10
1
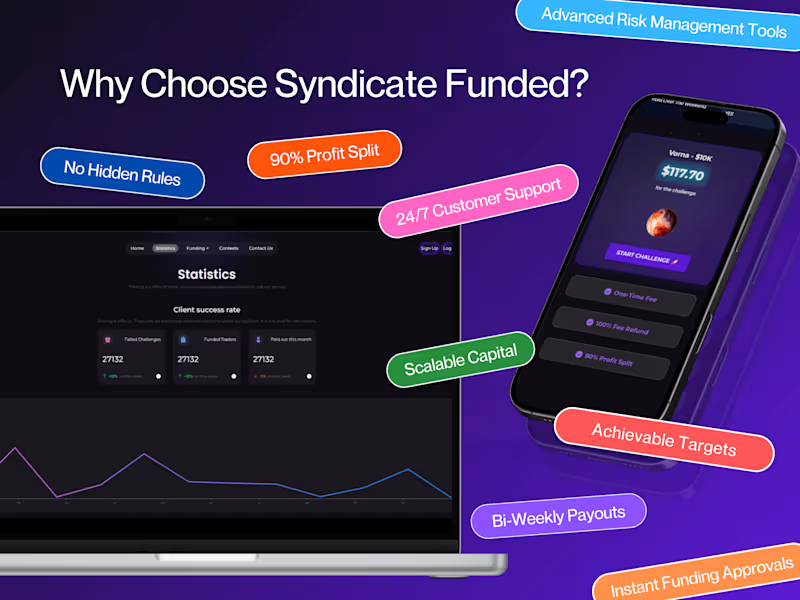
Syndicate Funded - Finance Trading App Design + Development
1
9
1
Playeon Streaming App - Full App Design & Development
1
7
Fullstack Engineer
(4)
Follow
Message
Arsalan Abbas
pro
Karachi, Pakistan
Building high-performance products for ambitious startups
New to Contra
Follow
Message
Building high-performance products for ambitious startups
0
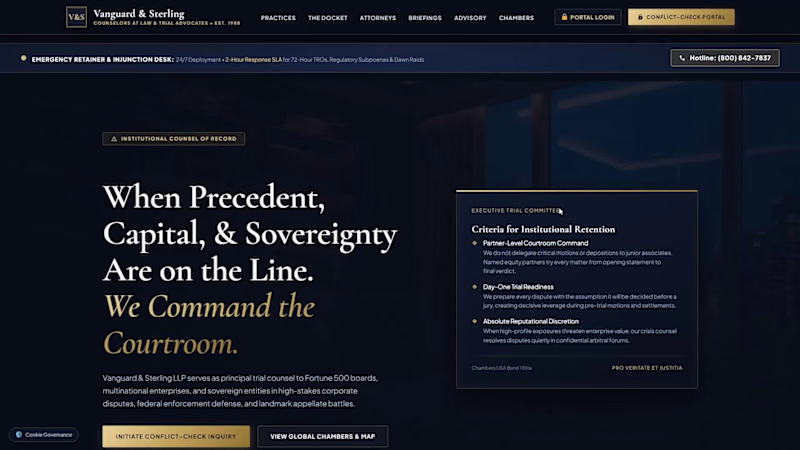
Vanguard & Sterling LLP - Ultra-Luxury Corporate Litigation Web Platform & Executive Portal Role & Services Role: Lead Full-Stack Web Architect & Product Designer Services: Custom WordPress Development, Full-Stack Architecture, UI/UX Design System, LegalTech Engineering, Cloud DevOps (Docker & Railway) Project Overview Vanguard & Sterling LLP is an elite corporate defense and appellate litigation practice operating in high-stakes venues, including the Delaware Court of Chancery and the U.S. Federal Courts. The objective was to transcend conventional corporate legal websites by creating an ultra-luxury sovereign web presence coupled with an authenticated Executive Portal Enclave. The platform provides clients, general counsels, and senior partners with real-time court docket synchronization, conflict-of-interest clearance screening, an FRCP 26(b)(3) privileged document vault, and an ABA Model Rule 1.15-compliant IOLTA fiduciary trust ledger. The Challenge Generic Industry Norms: Traditional law firm websites feel sterile, outdated, and template-driven, failing to project the prestige and authority required for multi-billion-dollar corporate disputes. Dual-Sided Architecture: The platform needed to serve two distinct audiences: prospective Fortune 500 corporate clients seeking counsel, and authenticated enterprise clients/partners accessing privileged litigation work product. Complex Compliance & Data Handling: Legal-grade compliance demands: strict ABA Model Rules 1.6 (Confidentiality), 1.7–1.10 (Conflicts of Interest), and 1.15 (Trust Accounting) workflows with segregated access controls. The Solution & Deliverables Bespoke Sovereign Design System Visual Aesthetic: Tailored obsidian dark mode palette (#060A14, #0A1224), brushed champagne and royal gold accents (#B89552, #DFC080), and polished marble glassmorphism (backdrop-filter: blur(16px)). Institutional Typography: Classical stone-carved judicial serif (Cinzel) paired with contemporary structural sans-serif (Plus Jakarta Sans) and editorial body type (Cormorant Garamond). Interactive Micro-Interactions: Real-time ticker feeds, responsive chamber locator maps across Wilmington, Washington D.C., New York, and London, and zero-flicker glass modals. Executive Portal & Sovereign CMS Modules Engineered an administrative control suite natively inside WordPress without relying on bloated third-party plugins: Certified Litigation Dockets (vg_matter): Chronological procedural histories with PACER docket numbers, presiding judge assignments, and hearing schedules. IOLTA Trust Ledger & Statements (vg_invoice): Complete fiduciary trust accounting engine tracking escrow balances, monthly legal fee drawdowns, itemized hours/disbursements, and instant PDF generation. Conflict Clearance Desk (vg_conflict): Real-time conflict checking mechanism with SLA response countdowns, adverse party tracking, and ethical wall sequestration directives. Privileged Document Vault (vg_vault_doc): Work-product classification system featuring SHA-256 cryptographic digests, audit logs, and encrypted access gates. 3. Custom In-Dashboard Dossier Experience Built an in-dashboard dossier view (vanguard-portal-view) that eliminates public website headers and footers during administrative reviews while preserving the full WordPress CMS sidebar and top bar. Custom architectural twilight rendering on wp-login.php with frosted glass container cards and glowing focus states. Tech Stack & Tools Core Engine: WordPress (Custom Theme & MU-Plugin Architecture), PHP 8.2 Frontend: Semantic HTML5, Vanilla Modern CSS3, JavaScript (ES6+), SVG Vector Engineering Database & Hosting: MySQL, Docker Containerization, Railway Cloud Infrastructure Design & Assets: Custom Design System, Architectural Renderings, Font Interactivity (Google Fonts)
0
51
0
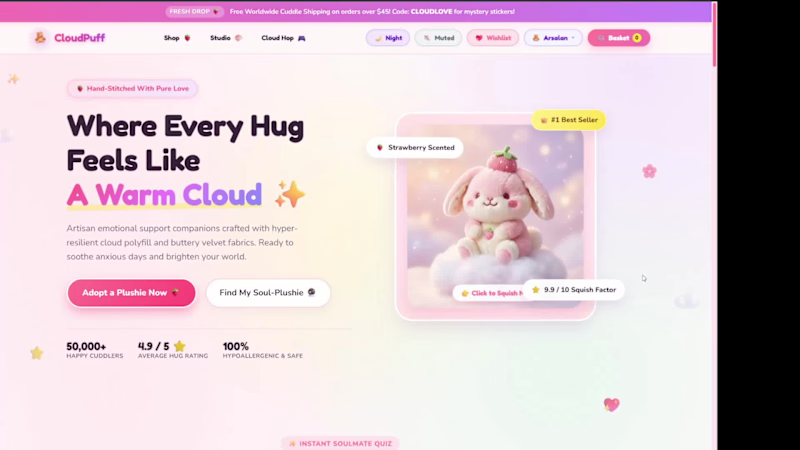
🚀 Project Update: CloudPuff Sanctuary (Phase 2) Project: CloudPuff Plushies — E-Commerce Experience Role: Lead Full-Stack Engineer & UI/UX Product Architect Milestone: Platform Release v1.2 Status: Completed & Live in Development Stack: Next.js 15 · React 19 · TypeScript · Vanilla CSS · Web Audio API 📣 Milestone Overview This milestone evolved CloudPuff Sanctuary from a visually engaging storefront into a more complete e-commerce experience with interactive shopping features, role-based dashboards, and seamless guest-to-account data synchronization. The primary focus was on improving customer engagement, account architecture, security, personalization, and overall UX while keeping the codebase modular and performant. Key Deliverables Interactive storefront and custom plushie experience Customer and administrator dashboard separation Guest wishlist functionality with account synchronization Enhanced authentication and admin security Interactive shopping and personalization features Responsive, lightweight frontend architecture 🧸 1. Interactive Storefront Experience Built a highly interactive storefront designed around the brand's playful customer experience. Key features include: Interactive Plushie Customizer: Real-time customization of fur colors, aromas, accessories, and engraved tags. Mood Matcher: Recommends plush companions based on the visitor's selected mood. Size & Hug Comparison: Interactive visual comparisons to help customers understand product dimensions. Cloud Hop Arcade: HTML5 Canvas mini-game with reward-based shopping incentives. Adoption Certificates: Generates personalized post-purchase certificates with registry information and print/PDF-friendly formatting. Web Audio Interactions: Custom audio feedback for selected UI interactions, product actions, and ambient experiences. 🛡️ 2. Dual-Persona Dashboard Architecture The dashboard was restructured around two distinct experiences: Customer Cuddle Hub Profile and identity management Orders and adoption registry Wishlist Billing and saved payment information Notifications Account/session management Sanctuary Shop Command Center Inventory management Fulfillment and dispatch Revenue and operational KPIs Store governance Administrative security Customer-facing preview Security & UX Improvements Strict role-based access controls Administrative features isolated from customer accounts Dedicated TOTP/2FA management for administrators Independent billing and notification sections Device/session management Cleaner navigation with deep-linked dashboard tabs This keeps the customer experience simple while providing administrators with the tools they need to operate the platform. 💖 3. Guest-to-Account Wishlist Sync A major focus of this milestone was removing friction from wishlist functionality. Visitors can save products without creating an account first. The system then: Stores guest wishlist selections locally. Preserves selections through registration/login. Merges guest and account wishlists automatically. Removes duplicate products during synchronization. Updates open browser tabs through cross-tab events. The authenticated dashboard then provides a dedicated wishlist experience with: Saved products Bulk "Adopt Whole Squad" cart action Wishlist sharing Product ratings Direct shopping navigation 🛠️ Technical Architecture Layer Technology Implementation Framework Next.js 15 App Router, dynamic routes, client components Frontend React 19 Modular component architecture Language TypeScript Strict typing across models, contexts and components Styling Vanilla CSS Semantic tokens, responsive layouts, themes Audio Web Audio API Custom UI sound synthesis State React Context Auth, Cart, Theme and Sound contexts Sync Browser Storage/Events Guest persistence and cross-tab synchronization The implementation prioritizes modularity, type safety, performance, and minimal frontend overhead. 📊 Results Improved Customer Experience Guests can immediately save products without encountering an authentication barrier. Better Operational Separation Customers and administrators receive purpose-built interfaces with appropriate permissions and workflows. Stronger Account Continuity Wishlist data is preserved when users transition from guest browsing to registered accounts. Lightweight Frontend The custom CSS architecture avoids unnecessary UI-library overhead while maintaining responsive layouts and rich interactions. Maintainable Codebase Features are organized into reusable components, typed models, context providers, and isolated functionality to support continued development. 🔮 Next Development Opportunities Planned enhancements include: Automated SMS delivery notifications Multi-currency support AR-based plushie previews using WebXR Further personalization and engagement features This milestone establishes a stronger foundation for CloudPuff Sanctuary to evolve from an e-commerce storefront into a more personalized and interactive digital shopping platform.
0
71
0
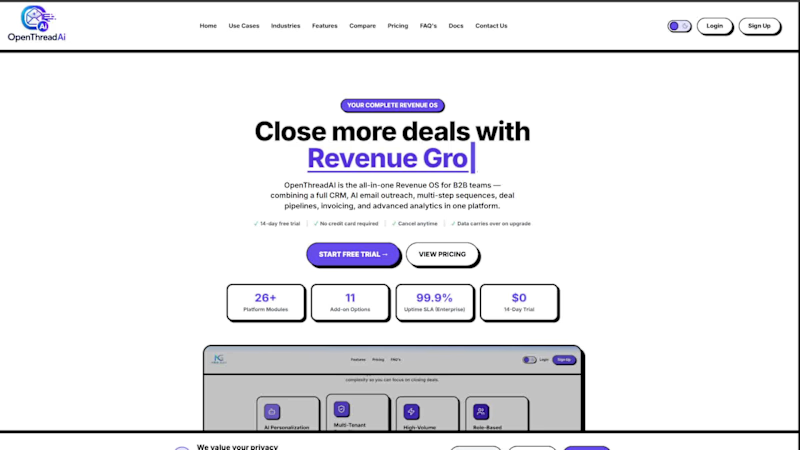
OpenThreadAI - AI-Powered Revenue OS Designed and developed the website for OpenThreadAI, an all-in-one Revenue OS built for B2B sales and revenue teams. The product brings together CRM, AI-powered email outreach, automated sequences, deal pipelines, invoicing, proposals, analytics, and workflow automation into a single platform. The website was designed to communicate a complex SaaS product clearly through strong information architecture, feature-driven sections, product visuals, pricing comparisons, use cases, and conversion-focused calls-to-action. Key features showcased: AI-powered email composer CRM and Kanban deal pipelines Multi-step email sequences Sales automation engine Revenue analytics and reporting Email verification and tracking Invoice and proposal builder Team roles and workspace management Integrations with popular business platforms Enterprise security and compliance features Detailed pricing and feature comparison Responsive SaaS marketing experience Goal: Create a polished SaaS presence that makes a feature-rich AI sales platform easy to understand while building trust and driving free-trial conversions.
0
207
0
Rocky - The Rockefeller 🌲 Demo / Work in Progress - Not a Final Render A preview of a whimsical animated short bringing Rocky, a little Christmas tree, to life. Set in a magical snow-covered forest, the story follows Rocky as he discovers friendship, confidence, and a little holiday magic along the way. This demo explores the character animation, storytelling, environments, and overall visual direction of the project. This is a demo and not the final render. It is intended to showcase the creative direction, animation approach, and work-in-progress development of the piece. Final rendering, polish, lighting, effects, and other production elements may differ from what is shown here. What we're exploring: Character-driven animation Expressive movement and storytelling Snowy forest environments Character interactions Cinematic framing and camera movement A warm, playful storybook-inspired visual direction The aim is to create a world that feels cozy, magical, and alive - like a Christmas storybook brought to motion.
0
22
Fullstack Engineer
(3)
Follow
Message
Maaz M.
Karachi, Pakistan
Product Design, Growth and Developer | E-Books and Software
5.0
Rating
10
Followers
Follow
Message
Product Design, Growth and Developer | E-Books and Software
2
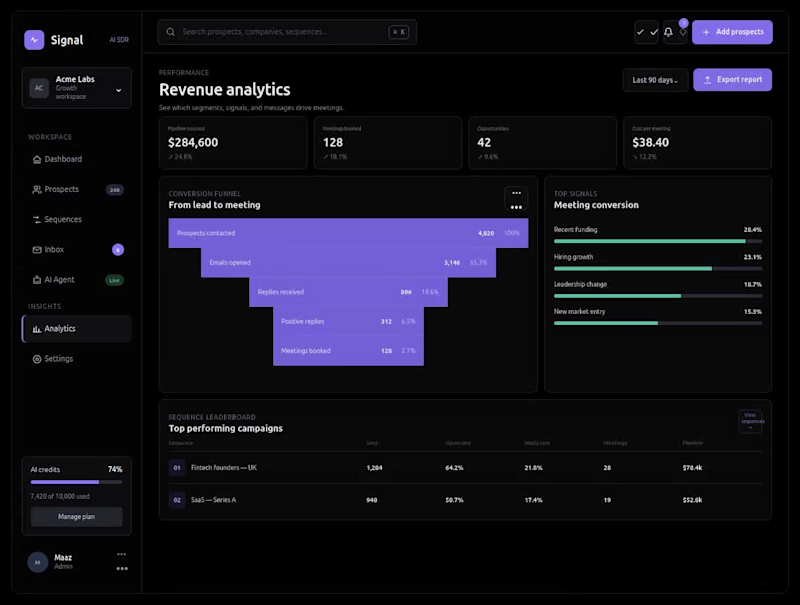
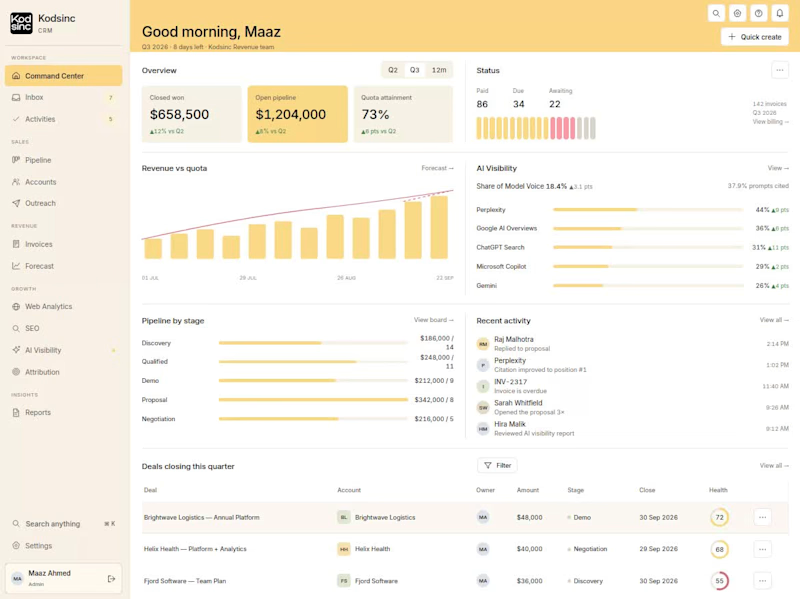
Kodsinc CRM: AI-First Revenue Intelligence and Sales Management Platform I designed Kodsinc CRM as an AI-first revenue operating system for modern B2B sales teams. Rather than treating AI as a chatbot added on top of a conventional CRM, the entire product is designed around intelligent agents that continuously understand customers, monitor opportunities, interpret buying signals, prioritize work, assist sales representatives, forecast revenue, automate repetitive activity, and connect every interaction back to measurable commercial outcomes. Traditional CRMs are primarily systems of record. Sales representatives enter contacts, update stages, create tasks, and managers review reports after the activity has already happened. Kodsinc CRM is designed to operate differently. It functions simultaneously as a system of record, system of intelligence, and system of action. The CRM records what has happened, AI analyzes what it means, and specialized agents help determine what should happen next. This creates a connected operating environment covering the complete revenue lifecycle: lead generation, account intelligence, prospect engagement, sales conversations, deal management, forecasting, invoicing, attribution, website intelligence, SEO performance, AI-search visibility, management reporting, and operational administration. AI Agent Operating Layer At the centre of Kodsinc CRM is an agentic intelligence layer that continuously works across the CRM rather than waiting for users to manually request assistance. The agents share access to approved CRM context including accounts, contacts, deals, emails, activities, website behaviour, buying signals, invoices, campaigns, marketing attribution, AI citations, historical performance, and user-defined business rules. This allows multiple specialized AI agents to work together. The Revenue Intelligence Agent continuously watches the overall business. It monitors pipeline creation, deal movement, forecast categories, quota attainment, revenue velocity, lead sources, invoice status, marketing contribution, and AI-influenced pipeline. It surfaces important changes to leadership instead of requiring them to search through multiple dashboards. The Deal Agent monitors every opportunity individually. It understands the deal stage, stakeholders, communication history, website visits, competitor involvement, days in stage, engagement levels, next steps, and close date. It can identify stalled opportunities, missing decision makers, declining engagement, overdue actions, or unusual risk patterns and recommend the most appropriate next action. For example, rather than simply showing that a deal is worth $48,000 and currently in Proposal, the agent can identify that the economic buyer has not been engaged recently and recommend arranging a CFO review before the expected close date. The Account Intelligence Agent maintains a living view of every customer and prospect account. It combines firmographic information, people, open opportunities, invoices, engagement history, website visits, sales activity, technology information, acquisition channels, and relationship strength into one account profile. Sales representatives therefore enter a customer conversation already understanding what that company has been researching and how engaged it has become. The Conversation Agent assists inside the Inbox. It understands previous messages, the associated account, active opportunity, recent activity, and next steps before producing a response suggestion. The user can review, edit, or send the response, preserving human control while dramatically reducing time spent drafting repetitive communication. The Outreach Agent supports structured multi-step prospecting sequences across channels such as email, LinkedIn and calls. Rather than evaluating outreach only through sending volume, it watches opens, replies, meetings, step-level conversion and sequence performance. Over time it helps identify which message, channel, audience and sequence structure actually produces qualified conversations. The Forecasting Agent analyzes the probability of revenue landing during the quarter. It combines closed revenue, Commit, Best Case and Pipeline opportunities with individual deal behaviour and recent movement. Instead of merely adding CRM probabilities together, it produces an AI-predicted landing range and explains the factors that are pushing the forecast upward or downward. The Growth Intelligence Agent connects sales with digital demand generation. It understands how prospects discovered the company through traditional search, AI answer engines, campaigns, referrals, paid traffic and outbound activities. This means management can move beyond asking, “Where did this lead come from?” and begin asking, “Which source, page, AI citation, campaign or search journey actually influenced this revenue?” The AI Visibility Agent monitors how the company appears inside ChatGPT, Perplexity, Google AI Overviews, Gemini, Copilot and other AI-driven discovery environments. It tracks citations, brand visibility, citation position, sentiment, factual inaccuracies, unanswered high-intent prompts and AI-influenced pipeline. The Revenue Operations Agent acts as the operational layer across the CRM. It can surface incomplete data, overdue tasks, stale opportunities, missing fields, unassigned records, unusual pipeline behaviour and integration problems. This reduces the administrative burden normally placed on RevOps teams. Finally, the Finance and Collections Agent connects sales outcomes with invoicing. Once an opportunity becomes revenue, its financial lifecycle remains visible inside the same system. Paid, due, overdue and awaiting invoices can therefore be connected back to the account and opportunity that generated them. Together these agents transform Kodsinc CRM from a database users maintain into a platform that actively helps operate the revenue function. Command Center The Command Center acts as the executive cockpit of Kodsinc CRM. It immediately presents closed-won revenue, open pipeline, quota attainment, revenue versus target, pipeline distribution, invoice status, AI-search visibility, recent activity and deals expected to close during the current quarter. Instead of forcing managers to move through several reporting applications, the screen combines commercial performance, pipeline health, cash status and growth intelligence in one view. The system is designed around exception management. Management does not need to inspect every opportunity manually. AI highlights meaningful changes such as a high-value deal losing momentum, an invoice becoming overdue, an important prospect reopening a proposal, an AI citation suddenly improving, or pipeline coverage falling below acceptable levels. Every metric is also actionable. Pipeline numbers lead directly into opportunities, forecast values lead into revenue intelligence, invoice metrics lead into billing, and AI visibility metrics lead into the growth intelligence module. The result is not simply a dashboard showing what happened. It is a control centre for deciding where the team needs to act next. Intelligent Sales Pipeline The Pipeline workspace manages every active opportunity visually across stages such as Discovery, Qualified, Demo, Proposal and Negotiation. Each deal card communicates more than an opportunity name and monetary value. It includes account context, expected close date, time spent in the current stage, forecast category, health score and acquisition source. This allows managers to understand both the financial value and underlying quality of the pipeline. Deals can be moved between stages through drag-and-drop interaction. When an opportunity changes stage, associated probability, forecast contribution and pipeline totals can update automatically. The deeper intelligence comes from AI monitoring the movement itself. The system can identify: opportunities spending unusually long periods in a stage; high-value deals without recent contact; close dates repeatedly being moved; missing economic buyers; falling engagement; unusually strong intent signals; opportunities whose stated stage does not match observed behaviour; deals that should potentially move into Commit or out of the current forecast. Instead of forcing managers to run weekly pipeline-cleaning exercises manually, Kodsinc CRM makes pipeline hygiene part of the operating system. Deal Intelligence and Deal 360 Opening an opportunity moves the user into Deal 360. This screen becomes the complete operating environment for that commercial opportunity. The CRM displays the stage, amount, probability, forecast category, close date, opportunity type, acquisition source, first-touch source, last-touch influence, time in stage, health indicators, competitors and account owner. More importantly, it combines traditionally disconnected events into a single chronological activity timeline. Emails, calls, meetings, notes and stage changes can appear alongside website visits, proposal engagement and AI-search citations. For example, a representative could see that a prospect: first discovered the company through Google, attended a webinar, visited the pricing page three times, opened a proposal, appeared through a Perplexity citation, and later replied to the sales representative. That sequence gives the seller a far more complete understanding of buying behaviour than an ordinary CRM activity log. The Deal Agent continuously analyzes this information and can recommend a next-best action. A deal health score becomes explainable rather than decorative. The system can show which behaviours are strengthening or weakening the opportunity so representatives understand why the AI considers something risky. Accounts and Contacts The Accounts and Contacts workspace provides the master customer database. Accounts include information such as company size, industry, geography, owner, annual recurring revenue, health, active opportunities, acquisition channel and recent activity. Contacts contain relationship-level information including title, account, deal role, qualification score, source, engagement state and last interaction. Contacts can be classified as Champions, Decision Makers, Influencers, Blockers or Users, giving sales teams visibility into the political structure of an opportunity. AI scoring can prioritize people and accounts using explicit evidence rather than opaque numerical scoring. For example, a high prospect score could be explained through factors such as seniority, company size, webinar attendance, repeated pricing-page visits or direct email engagement. This allows sellers to understand why someone is important rather than simply being told that a lead has a score of 91. Account 360 Account 360 combines every relevant commercial signal for a company. Sales representatives can see annual revenue contribution, account health, open pipeline, lifetime value, company characteristics, technology stack, contacts, opportunities, invoices and recent engagement. An Engagement view connects CRM activity with web behaviour. Instead of website analytics remaining anonymous inside a marketing product, known-account behaviour can be attached to the customer record. The account team might therefore see that a company has recently visited the pricing page fourteen times, viewed a forecasting product page nine times and visited a competitor comparison page six times. These behaviours become valuable buying signals. The Account Intelligence Agent can then summarize what is happening across the account and surface meaningful changes before a seller begins their next conversation. Unified Inbox and Activity Management The Inbox combines customer conversations and sales work in one place. Email, LinkedIn-compatible messages and other supported communication channels can appear in a unified conversation view. Users can see unread messages, tasks due today, overdue activities and conversations connected to specific accounts or opportunities. Opening a conversation simultaneously displays the message thread and CRM context. Instead of switching from email to CRM to account records to opportunity notes, the seller can immediately see who the person is, which company they belong to, what opportunity is active and what the next step should be. The AI Conversation Agent can draft replies using that complete context. Crucially, AI-generated responses are treated as recommendations rather than autonomous truth. Users can review and modify the generated content before sending it. Task management is also integrated into the same workflow. Completing a task updates activity records and reduces outstanding workload immediately. This creates a daily workspace in which sellers can operate without repeatedly moving between CRM, email, task management and prospecting applications. AI-Assisted Outreach The Outreach workspace manages multi-step sales sequences. Teams can create structured cadences containing combinations of email, waiting periods, LinkedIn activity and calls. Each sequence tracks enrolment, open rates, response rates, meetings booked and performance at individual steps. This makes the system useful for both SDR execution and management optimization. The Outreach Agent can analyze which steps produce engagement and which steps cause prospects to disappear from the sequence. Templates can then be evaluated using actual downstream outcomes instead of only open rates. The objective is not simply “send more messages.” The objective is to continuously improve which people are contacted, what is communicated, when communication occurs and which channel is most appropriate. Over time, the platform can use this information to recommend sequence structures and messaging based on prospect segment, seniority, industry, previous engagement and buying signals. Revenue Forecasting The Forecast workspace turns pipeline data into a forward-looking revenue model. Management can see Closed Won, Commit, Best Case, Pipeline and projected quarter-end revenue compared with quota. A traditional CRM forecast often depends heavily on seller-selected probabilities. Kodsinc CRM adds a behavioural intelligence layer. The Forecasting Agent can consider opportunity movement, engagement patterns, close-date changes, stakeholder coverage, historical conversion, opportunity health and recent events before producing an expected landing range. The output therefore includes both a prediction and confidence interval. More importantly, the system explains why the prediction changed. Management might see positive drivers such as three opportunities moving into Commit, alongside negative drivers such as a major deal slipping four days. Forecasting therefore becomes a management conversation supported by evidence rather than a single unexplained number. Individual sales representatives can also be expanded to inspect the opportunities contributing to their forecast, making the model auditable. Billing, Invoicing and Deal-to-Cash Management Kodsinc CRM continues tracking a customer after the opportunity closes. The Invoices and Billing workspace displays paid revenue, amounts due, contracted balance, overdue invoices, invoice status, recent transactions and available payment methods. Invoices remain linked to their original accounts and deals. This provides a true deal-to-cash workflow. A sales leader can therefore follow an opportunity from pipeline creation through close, invoice generation and eventual payment without losing context between CRM and finance systems. New invoices can be generated directly from the CRM. Existing invoices can be previewed, reminders can be issued, and payment status changes can update financial metrics. Overdue invoices can also become operational signals. Instead of Finance discovering a problem separately, the account owner can immediately see that an important customer has an overdue balance and adjust the commercial conversation accordingly. Web Analytics The Web Analytics module brings acquisition behaviour directly into the revenue platform. It tracks sessions, users, engagement time, bounce rate, conversion rates, traffic channels, landing pages, devices, geography and the complete marketing-to-revenue funnel. A real-time visitor view provides current website activity, while historical visualizations explain longer-term trends. The important difference is that web analytics are not isolated from CRM outcomes. Traffic channels can be connected to leads, opportunities and closed-won revenue. AI answer engines are specifically tracked as their own acquisition channel, allowing teams to compare traffic and conversion from services such as ChatGPT, Perplexity, Gemini and Copilot against traditional channels. This helps answer a commercially important question: Which digital discovery environments are actually creating customers? SEO Intelligence The SEO workspace monitors conventional search visibility. It tracks organic traffic, impressions, CTR, average ranking position, domain strength, keyword movement, referring domains, backlinks, indexed pages and Core Web Vitals. Keywords can be connected with landing pages and AI Overview presence. Technical SEO issues are also surfaced directly in the CRM environment. Instead of presenting technical problems without commercial context, AI can generate remediation guidance and help teams understand which issues may affect high-value pages or revenue-producing search journeys. This connects the work of growth teams with the same commercial dataset used by Sales and RevOps. AI Visibility: AEO, GEO and LLMO AI Visibility is one of the defining capabilities of Kodsinc CRM. As buyers increasingly ask AI systems for recommendations rather than relying entirely on traditional search engines, the platform monitors how the company appears inside those AI-generated answers. The module covers three complementary disciplines. AEO — Answer Engine Optimization measures visibility in answer-oriented search experiences such as featured snippets, People Also Ask results, structured answers and schema-driven results. GEO — Generative Engine Optimization measures brand presence and citation position inside generative search environments such as Google AI Overviews, Perplexity, ChatGPT Search, Copilot and Gemini. LLMO — Large Language Model Optimization measures how often a brand appears within LLM-generated answers, its share of model voice, citation frequency, sentiment and factual accuracy. Kodsinc CRM can therefore track questions that prospective customers are asking AI systems and determine whether the company appears in the answer. It can also compare visibility across different engines. A GEO matrix can show which queries receive strong citations and which engines fail to mention the company. The platform can identify high-intent prompt gaps where competitors appear but the company does not. AI can then create a content brief designed to address the missing information. The platform also detects factual errors. For example, if an AI engine incorrectly describes pricing, lists an obsolete integration or attributes a competitor capability to the company, Kodsinc CRM creates an alert. The AI Visibility Agent can draft a correction strategy, supporting content or structured-data recommendation for review. This turns AI-search visibility into an operational business process rather than an experimental marketing metric. Revenue Attribution The Attribution workspace connects marketing investment with commercial results. Users can analyze first-touch, last-touch, linear and time-decay attribution models. Channels can be evaluated against spend, sessions, leads, pipeline generated, closed-won revenue, CAC and return on investment. The platform also visualizes actual customer journeys. A successful opportunity might follow a journey such as: Organic Search → Pricing Page → Perplexity Citation → Demo → Closed Won. This is extremely valuable because modern B2B buying journeys are rarely attributable to a single click. Kodsinc CRM preserves that multi-touch context while still allowing management to understand which channels materially influence revenue. AI answer engines therefore become measurable alongside outbound, paid advertising, events, referrals and conventional organic search. Reporting and Revenue Analytics The Reports workspace gives leadership and RevOps teams a configurable analysis environment. Reports can combine Sales, Growth and Finance data because the underlying platform works from one connected revenue model. Users can create reports around metrics such as AI-sourced pipeline, quarter performance, keyword movement, accounts receivable ageing, pipeline velocity or campaign ROI. Metrics, dimensions, filters and visualization formats can be configured directly. Reports can also be scheduled for recurring distribution. Instead of rebuilding management packs manually every week, teams can create persistent reporting views that remain connected to live CRM data. The AI layer can eventually extend this into narrative reporting by explaining material changes such as: “Pipeline increased 11% this week, primarily due to three AI-sourced opportunities entering Proposal, while forecast risk increased because two enterprise opportunities moved their expected close dates into Q4.” This changes reporting from static visualization into decision support. Settings, Teams, Permissions and Integrations The Settings area manages the operating environment behind the CRM. Administrators can manage workspace configuration, users, roles, permissions, pipeline stages, custom fields, notifications, integrations, billing and API access. Role-based access supports administrators, managers, account executives, SDRs and viewers. The platform is designed to integrate with systems such as Gmail, Outlook, Slack, HubSpot, Stripe, Google Search Console, GA4, Ahrefs, Perplexity, OpenAI, Segment and Zapier. These connections allow the CRM to become the intelligence layer across the broader revenue technology stack rather than replacing every specialized system. The RevOps Agent can monitor these connections and identify issues such as missing data, failed synchronization or incomplete records. Cross-Functional Automation One of the strongest aspects of Kodsinc CRM is that features are not designed as isolated pages. The application supports complete operational journeys. An AI citation can generate referral traffic. That visitor can become a lead. The lead can be qualified, converted into an account and contact, and eventually become an opportunity. The opportunity can progress through the pipeline, contribute to the forecast, become closed revenue, generate an invoice and eventually appear in attribution reporting. Likewise, an incorrect AI-generated claim can become a visibility alert. AI can draft a remediation strategy, create a task, assign it to the appropriate team, track the resulting SEO or AI visibility improvement and later connect recovered traffic with pipeline. A sales opportunity can move into Negotiation, become Closed Won, automatically affect revenue reporting, produce an invoice and update forecast performance. Quarterly management reviews can move seamlessly from executive KPIs into forecast inspection, individual seller performance, attribution analysis and board reporting. This connected architecture is what makes Kodsinc CRM fundamentally different from a collection of dashboards. Human-Controlled AI Although AI is deeply embedded throughout the product, the system is designed around controlled automation. Generated responses, recommendations, content corrections and actions remain visible to the user. AI-generated material can be reviewed, accepted, modified or dismissed. Important actions can be logged through an audit trail. Role permissions, approval rules, sending limits and operational guardrails can govern what an agent is allowed to perform automatically. The objective is not to remove people from the sales process. The objective is to remove unnecessary administrative work so people can spend more time on judgment, relationships, negotiation and closing business. AI-First CRM Architecture The conceptual architecture can be understood as five connected layers. At the bottom is the Revenue Data Layer, containing accounts, contacts, leads, deals, activities, communications, campaigns, invoices, website behaviour, search data, AI citations and revenue events. Above it is the Intelligence Layer, where AI models analyze relationships, score opportunities, detect signals, summarize information, forecast outcomes and identify anomalies. Above that sits the Agent Layer, containing specialized agents responsible for deals, accounts, outreach, conversations, forecasting, visibility, RevOps and revenue operations. The fourth layer is the Action Layer, where agents can draft communication, recommend tasks, prepare reports, create briefs, update records, trigger workflows and surface notifications within defined permissions. Finally, the Experience Layer exposes everything through the Command Center, Pipeline, Account 360, Inbox, Outreach, Forecast, Billing, Growth Intelligence, Reporting and Settings interfaces. Because every layer operates on the same revenue graph, intelligence generated in one part of the product can immediately become useful somewhere else. The Result Kodsinc CRM is designed to move CRM software beyond data entry and pipeline administration. It gives sales representatives a clearer understanding of every prospect and opportunity. It gives managers continuous visibility into pipeline quality, seller performance and forecast risk. It gives SDR teams intelligent outreach and prioritized conversations. It gives RevOps a connected system for data quality, workflow management, automation and reporting. It gives Growth teams visibility into SEO, AI discovery, attribution and digital behaviour. It gives Finance a direct connection between deals, invoices and collected revenue. And it gives leadership one environment for understanding where revenue came from, what is happening now, what is likely to happen next and where the organization should act. The result is an AI-first CRM that does not merely store the history of the customer relationship, it continuously helps the revenue team decide and execute the next best action.
2
253
1
GPUStore: A Modern GPU Shopping and Discovery App I designed GPUStore to make buying graphics cards feel less like decoding a spec sheet and more like exploring a well-organized catalog. Instead of overwhelming users with dense tables and inflated resale listings, I structured the product around what PC builders actually ask: which generation is this, what did it originally cost, and what will it do for me? The visual identity pairs a dark charcoal interface with electric lime green accents. The green guides interaction. It marks active filter tabs, the Shop Now and Add to Cart buttons, the cart badge, saved hearts, and the NVIDIA brand label. Dark cards and high-contrast product renders give each card a premium, showroom feel while keeping specs and prices easy to read. The home screen opens with a personal greeting, a search bar with a real example query ("RTX 4090"), and quick category chips for All, NVIDIA, AMD, Accessories, and Builds. A bold RTX 50 Series banner promotes new releases, followed by a "Featured GPUs" section. Each card shows the architecture, release year, launch price, and a one-tap cart button. The All GPUs screen turns browsing into a timeline. Segmented filters (All, GTX, RTX, By Year) sit above a 2016 to 2026 range slider, so users can explore generations and their original launch prices (MSRP). Seeing the GTX 1080 at $599 next to the RTX 4090 at $1,599 makes a decade of pricing history readable at a glance. The product detail screen prioritizes clarity. An image carousel with wishlist and share actions leads into the architecture and release date, then a dedicated MSRP panel. A compact Key Specifications table follows (Ampere architecture, 8,704 CUDA cores, 10 GB GDDR6X, 320-bit memory bus, 320 W TDP). A sticky quantity stepper and Add to Cart button stay within thumb reach. A short note clarifies that launch price shows original MSRP and actual market prices may vary. The profile screen gives users a personal hub with their saved items, orders, builds, and member-since year. Wishlist, Orders, and Settings tabs keep everything in one place, and saved cards show the date each item was added. Across the app, a five-tab bottom navigation (Home, Browse, Wishlist, Orders, Account) keeps the structure predictable. Frontend I built the client as a cross-platform mobile app using React Native with TypeScript. React Navigation handles the bottom tabs and the stack flows between listing, detail, and cart. TanStack Query manages server data, caching, and loading states, while Zustand holds lightweight local state such as cart count, wishlist toggles, and active filters. The year-range slider and category filters update query parameters, so results refresh without a full reload. Reusable components (GPU card, spec row, filter chip, quantity stepper) are driven by a shared design-token file for the dark theme and green accent, keeping the UI consistent across screens. Backend The backend is a Node.js REST API (Express or NestJS) backed by PostgreSQL through Prisma. The core schema covers users, GPUs, wishlists, carts, cart items, orders, order items, and builds. Each GPU record stores brand, series (GTX or RTX), architecture, release date, MSRP, CUDA cores, memory size and type, bus width, and TDP. MSRP is stored separately from the live selling price, which matches the app's "launch price vs. market price" approach, and all money values are stored as integer cents to avoid rounding errors. Endpoints support search, brand, series, and year-range filtering (GET /gpus?series=RTX&yearFrom=2016&yearTo=2026), product details, cart and wishlist actions, and order history. Authentication uses JWT with refresh tokens, images are served through a CDN, and Stripe handles checkout. The result is a GPU shopping experience that feels premium, informative, and easy to navigate, built for gamers and creators.
1
155
0
Signal: AI-Powered Sales Development and Outreach Platform I designed Signal as a full-stack AI sales development platform that helps teams discover prospects, manage outreach sequences, prioritize conversations, and convert engagement into qualified meetings. Instead of spreading sales activities across disconnected tools, Signal brings prospect research, communication, automation, and performance reporting into one focused workspace. The visual identity uses a pitch-black interface with subtle violet, teal, green, and amber accents. Flat panels, restrained borders, professional outline icons, and generous spacing give the product a confident, human-designed appearance. Color is used functionally to distinguish active sequences, positive responses, scheduled meetings, prospect scores, and automation statuses without overwhelming the interface. The main dashboard provides an immediate overview of active prospects, emails sent, reply rates, and meetings booked. Outreach performance is displayed through clean charts, while campaign tables highlight prospect volumes, delivery activity, and response rates. A dedicated research queue shows the work currently being completed by the sales agent without relying on distracting animations or exaggerated AI visuals. The Prospects screen operates as the central lead database. Users can search and filter contacts, review company information, examine buying signals, compare qualification scores, and track each prospect’s latest activity. Qualified prospects can be moved directly into outreach sequences, creating a connected workflow from discovery to engagement. The Sequences workspace enables teams to build and monitor structured, multi-step campaigns across email and LinkedIn. Every sequence presents its delivery schedule, prospect volume, open rate, reply rate, meetings generated, and current operating status. The connected Inbox brings replies into one place, prioritizes high-intent conversations, and provides context-aware response suggestions that users can review, edit, or send. The AI Agent workspace gives users control over automated prospecting. Teams can define their ideal customer profile using industry, company size, geography, seniority, department, and buying-signal criteria. Guardrails and written instructions determine how prospects are researched, qualified, enriched, and prepared for outreach, while a live activity log keeps every automated action visible and accountable. The Analytics screen connects outreach activity to commercial outcomes. It tracks pipeline sourced, meetings booked, opportunities created, cost per meeting, funnel conversion, top-performing buying signals, and sequence-level performance. This allows sales leaders to understand not only how much activity is taking place, but which audiences, signals, and messages are producing meaningful results. The backend architecture is designed around a secure REST or GraphQL API layer built with Node.js and TypeScript. PostgreSQL stores users, workspaces, prospects, companies, sequences, messages, tasks, campaign events, and analytics records. Redis supports caching, background queues, rate limiting, and scheduled outreach, while asynchronous workers handle enrichment, qualification, message generation, email delivery, follow-ups, and CRM synchronization. AI capabilities are managed through a controlled orchestration layer that combines company data, prospect history, buying signals, sequence context, and user-defined instructions. Retrieval-based context can be used to ground generated messages in approved company information, while approval workflows, audit logs, prompt controls, and configurable sending limits provide operational oversight. Authentication uses secure session or token-based access with role-based permissions for administrators, managers, and sales representatives. External integrations can connect Signal with email providers, LinkedIn-compatible workflows, calendars, enrichment services, and CRM platforms such as HubSpot or Salesforce. Webhooks capture delivery, open, reply, bounce, booking, and opportunity events in near real time. Across the complete product, I prioritized clarity, practical automation, transparent AI assistance, and connected navigation between Dashboard, Prospects, Sequences, Inbox, AI Agent, Analytics, and Settings. The result is a modern sales development platform that feels focused, professional, scalable, and genuinely useful to the people responsible for building pipeline.
0
146
6
Northstar CRM: Full-Stack Customer Relationship and Sales Management Platform I designed and developed Northstar CRM to transform customer relationship management into a focused, visually intuitive, and connected workspace. Instead of overwhelming sales teams with dense tables and fragmented tools, I structured the platform around clear customer insights, actionable sales data, and streamlined daily workflows. The visual identity combines a soft atmospheric background with glass-inspired surfaces, dimensional cards, and vibrant blue, teal, yellow, and charcoal accents. Carefully layered shadows, subtle gradients, and elevated components create a refined 3D appearance while maintaining clarity and professional usability. The entire interface follows a consistent 4:3 presentation ratio, making every screen suitable for portfolio displays and high-quality screenshots. The overview dashboard gives users an immediate picture of business performance. Key metrics—including total revenue, pipeline value, completed tasks, priority deals, recent activities, and upcoming meetings—are presented through scannable cards, progress indicators, compact charts, and contextual status colours. This allows teams to identify important changes and required actions without navigating through multiple reports. The customer management screen provides a searchable directory with company information, recent interactions, account value, relationship status, and assigned ownership. Selecting a customer dynamically updates the detailed profile panel, where users can review contact information, relationship health, next actions, and communication options such as messaging, calling, or scheduling a meeting. The deal pipeline organizes opportunities into clear stages, including Discovery, Proposal, Negotiation, and Closing. Each opportunity card displays its customer, estimated value, expected closing date, owner, and current stage. The Kanban-style structure gives sales teams a visual understanding of pipeline movement while supporting faster prioritization and opportunity management. The calendar and reporting screens connect operational planning with performance analysis. The calendar provides monthly scheduling, customer meetings, deadlines, focus time, and team commitments. The reporting workspace combines revenue trends, conversion rates, customer retention, pipeline sources, account health, and period-based performance comparisons through interactive charts and summary cards. On the backend, I implemented a modular Node.js and Express REST API connected to a PostgreSQL database. The data model supports users, customers, companies, contacts, deals, pipeline stages, activities, tasks, meetings, notes, and reporting records. Structured relationships and indexed queries ensure that customer histories, pipeline summaries, and dashboard analytics remain fast and consistent as the dataset grows. Authentication is handled through secure token-based sessions, password hashing, protected API routes, and role-based access control. Different permissions can be assigned to administrators, sales managers, and sales representatives, ensuring users only access or modify information relevant to their responsibilities. Input validation, centralized error handling, audit logging, and rate limiting strengthen reliability and application security. Real-time updates allow changes to deals, tasks, customer activity, and meeting schedules to appear across connected screens without requiring a manual refresh. Background processes handle reminders, notifications, scheduled follow-ups, and reporting calculations, while caching improves the performance of frequently requested dashboard metrics. Across the complete full-stack platform, I prioritized reusable frontend components, responsive layouts, secure API design, reliable data relationships, and consistent interaction patterns. The result is a modern CRM experience that feels premium and approachable while providing the technical foundation required for scalable customer management, sales execution, and business intelligence.
4
6
1.1K
Fullstack Engineer
(6)
Follow
Message
Explore people