Web Scraping & Crawling: Polite, Safe Data Extraction

Mojtaba Karimiabdar


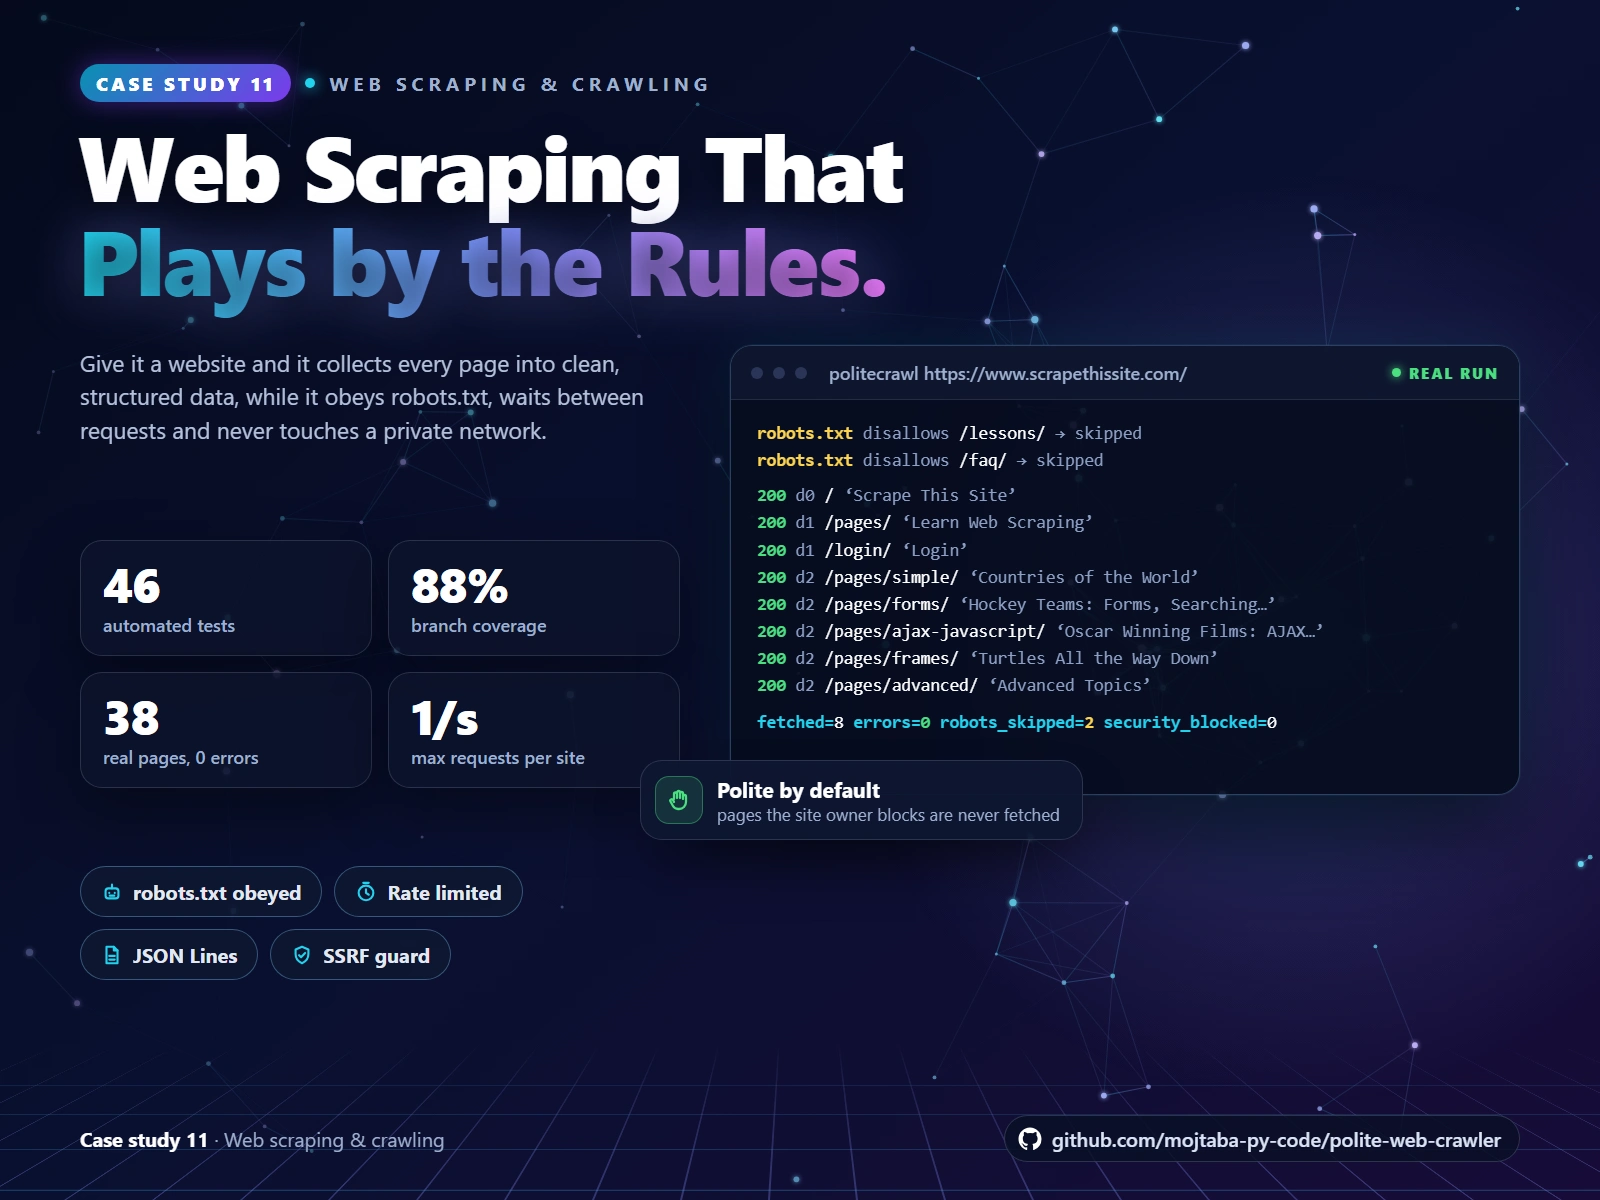
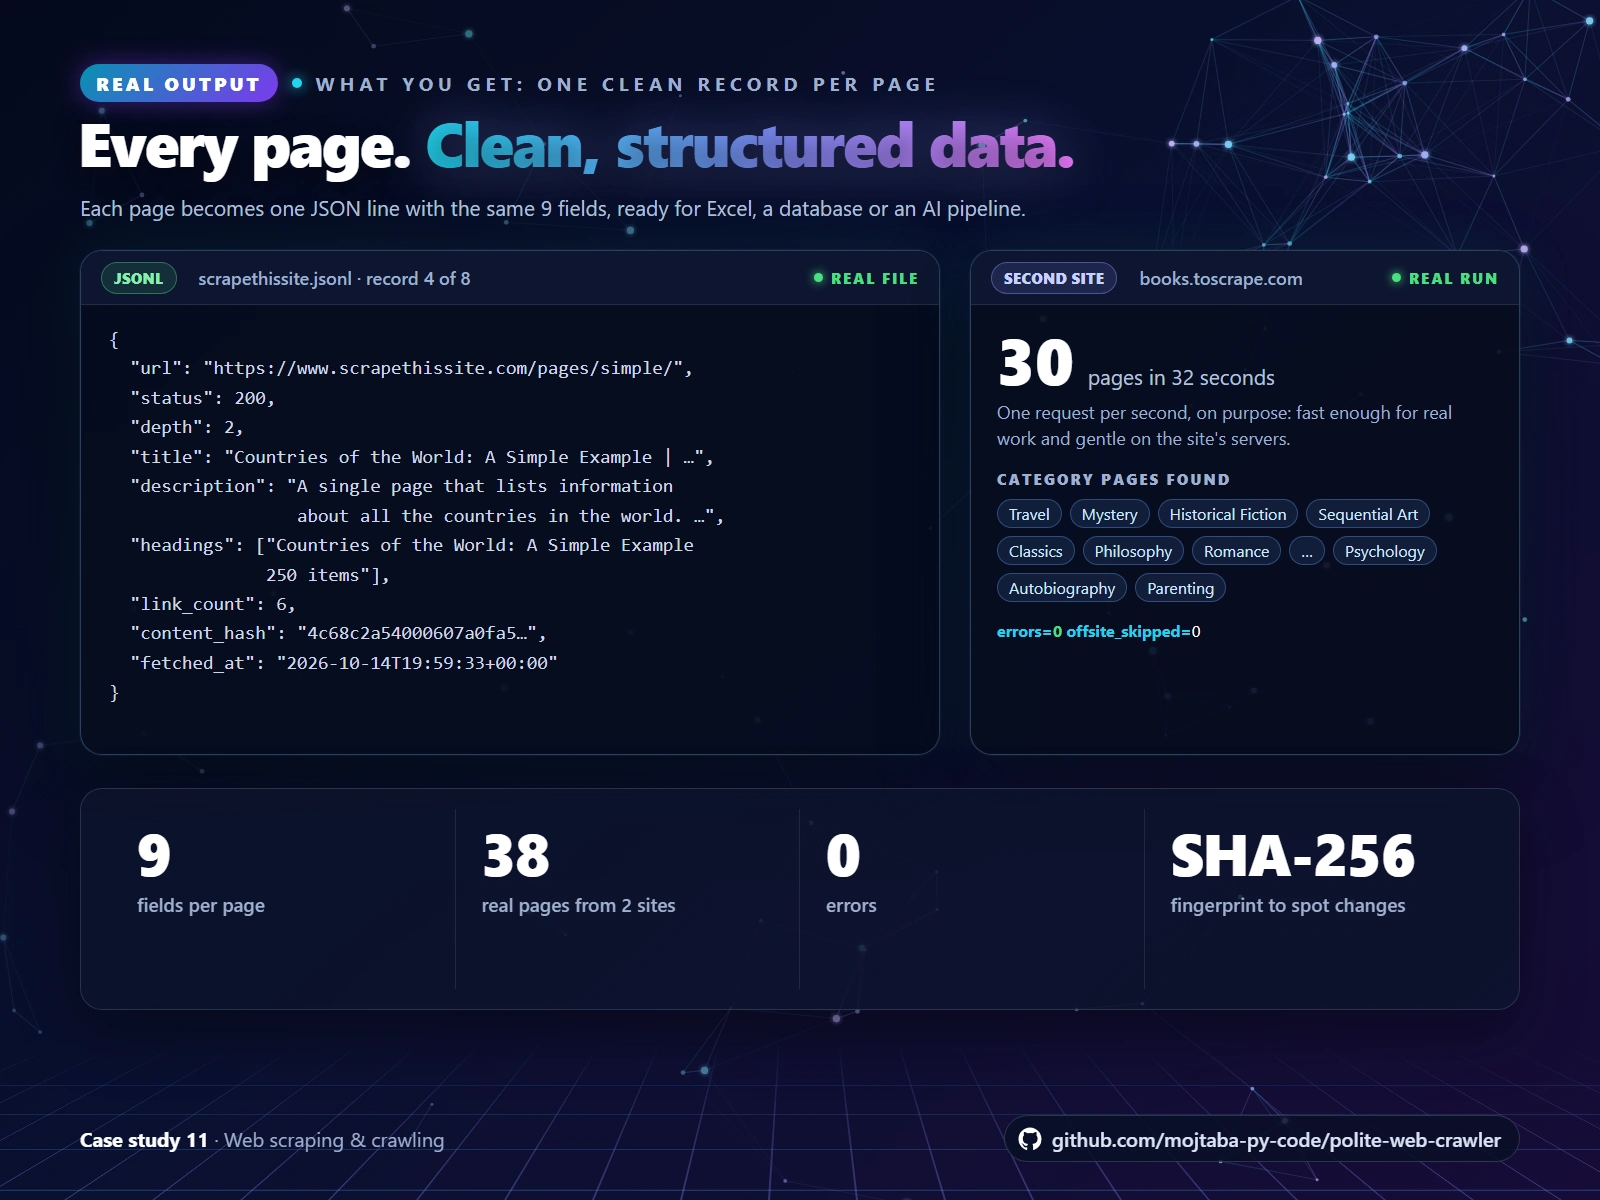
Real output: one clean JSON record per page with 9 fields, plus a second real crawl of 30 pages in 32 seconds at one request per second.
The challenge
Many scrapers hammer websites, ignore robots.txt and get blocked. On a server, a careless scraper can even be tricked by a single link into reading private internal systems.
The solution
I built a polite, safety-first web crawler in Python. Give it one start URL and it collects every page of that site into clean JSON data, while it obeys robots.txt, waits between requests and refuses private networks.
The real output
One JSON line per page with 9 fields: URL, status, depth, title, description, headings, link count, a SHA-256 fingerprint and the time.
38 real pages from 2 public scraping sandboxes, 0 errors. On books.toscrape.com: 30 pages in 32 seconds, at one request per second on purpose.
The fingerprint shows which pages changed since the last run.
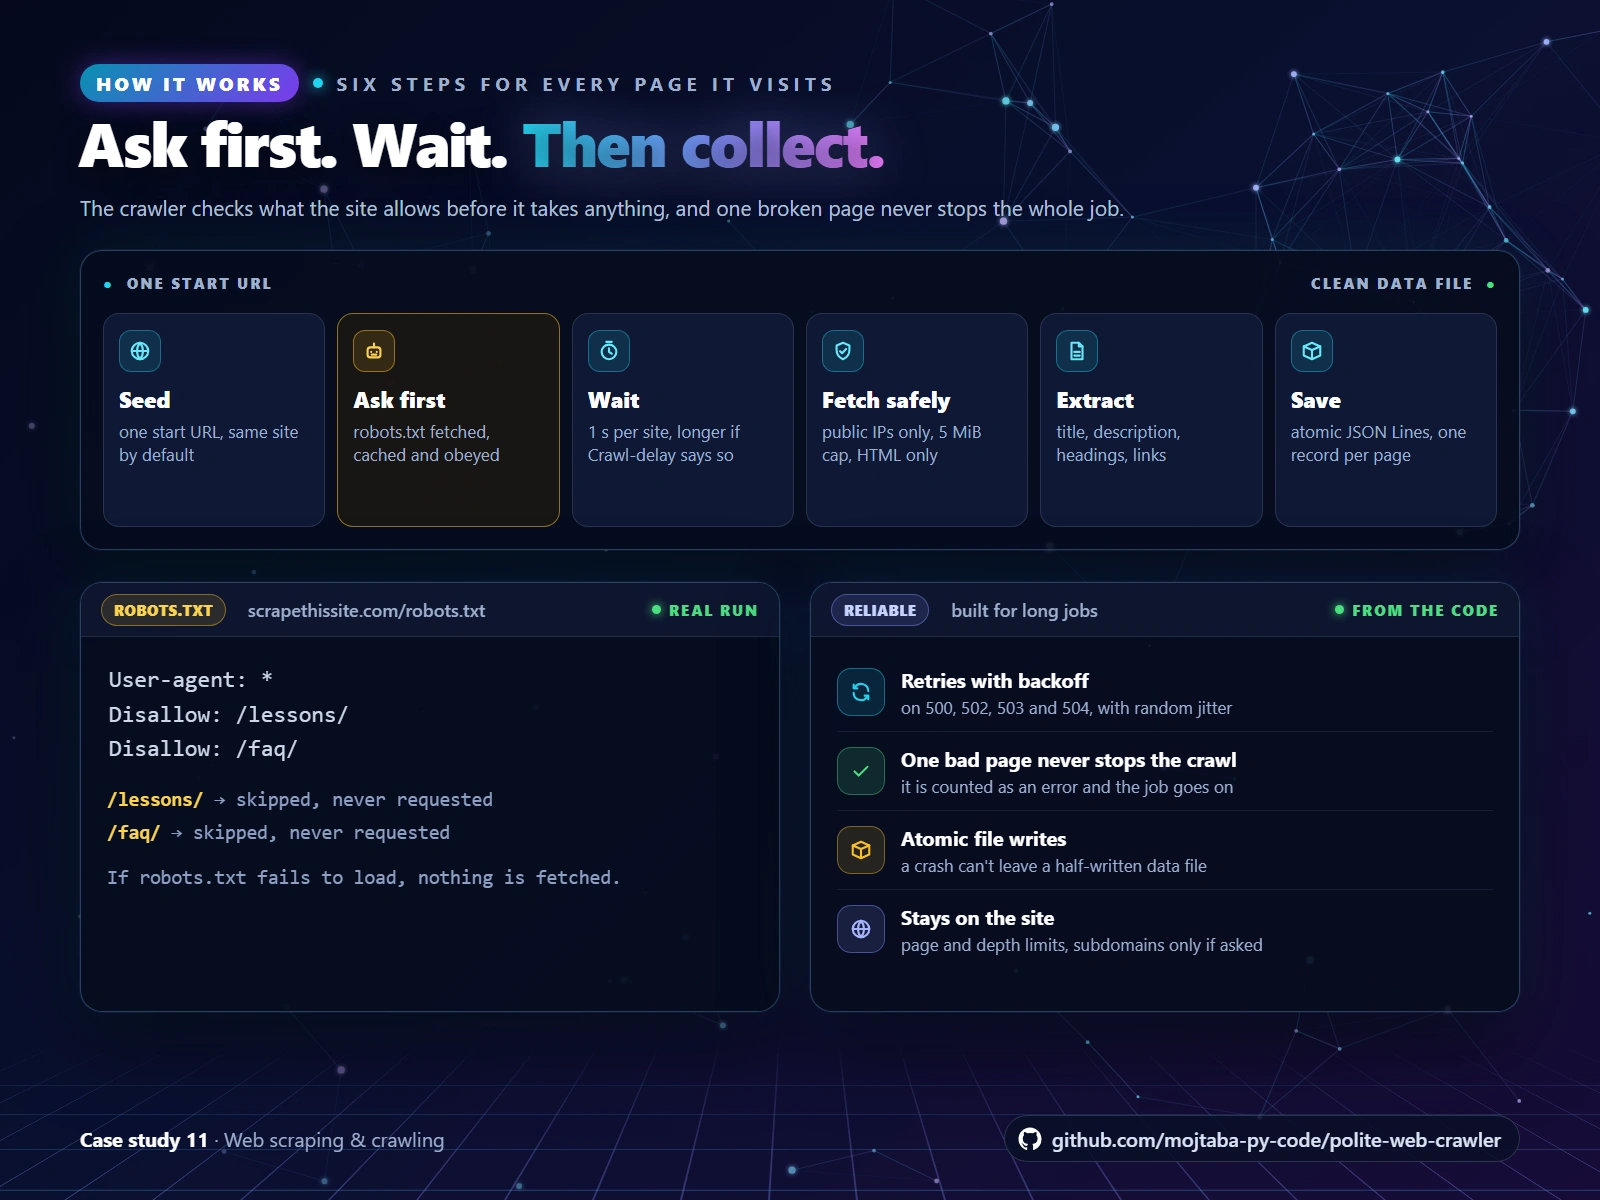
Six steps for every page: ask robots.txt first, wait between requests, fetch safely, extract, then save atomically.
How it works
Ask first: robots.txt is fetched, cached and obeyed. On scrapethissite.com it blocks /lessons/ and /faq/, so those pages were never requested. If robots.txt fails to load, nothing is fetched.
Wait: at most one request per second per site, and longer when the site asks for it with Crawl-delay.
Fetch safely: public addresses only, redirects checked hop by hop, responses capped at 5 MiB, HTML only.
Reliable on long jobs: retries with backoff on 500, 502, 503 and 504; one bad page is counted as an error and the crawl goes on.
Save: results are written atomically, so a crash never leaves a half-written data file.
Stays on the site: page and depth limits, and subdomains only when asked.
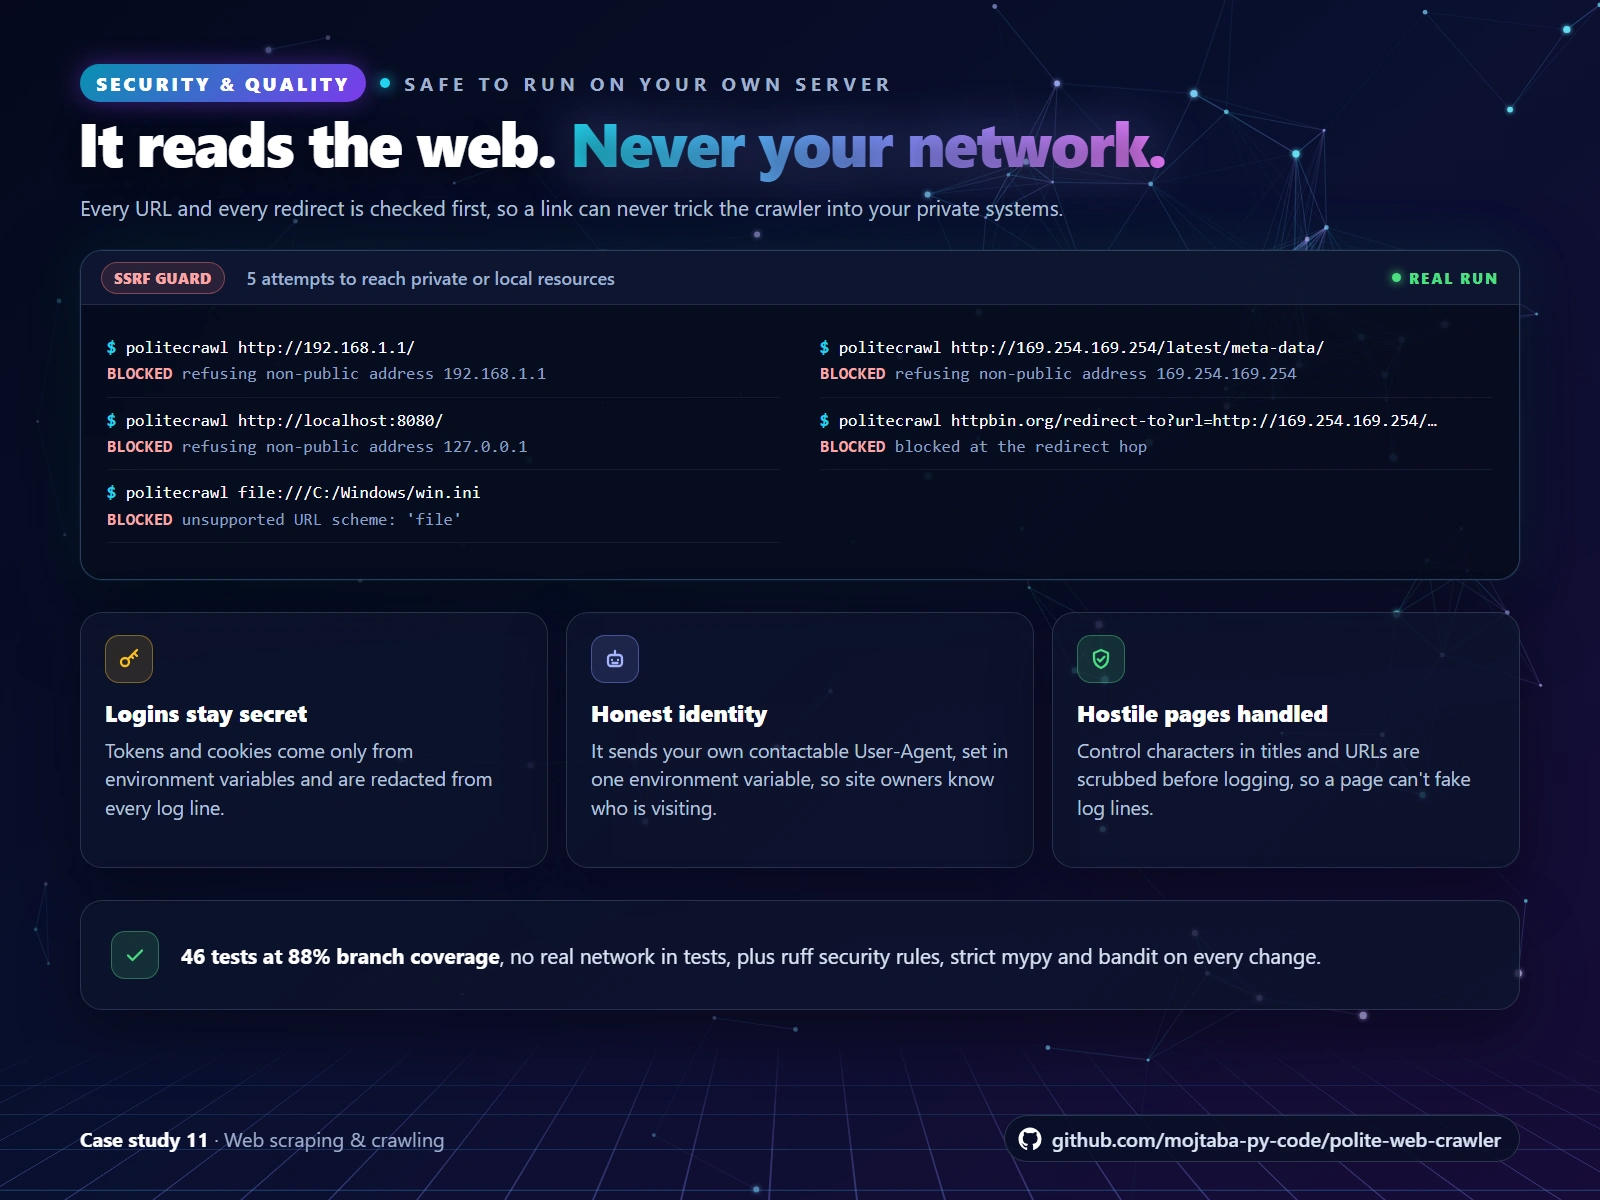
Five real attempts to reach private or local addresses, all blocked, including one hidden behind a redirect. 46 tests, 88% coverage.
Security and quality
SSRF guard: 5 real attempts to reach private or local resources (192.168.1.1, the cloud metadata address 169.254.169.254, localhost, a file:// path and a redirect to the metadata address) were all blocked.
Logins stay secret: tokens and cookies come only from environment variables and are redacted from every log line.
Honest identity: it sends your own contactable User-Agent, so site owners know who is visiting.
Hostile pages handled: control characters in titles and URLs are scrubbed before logging.
46 automated tests at 88% branch coverage with mocked HTTP and faked DNS, plus ruff security rules, strict mypy and bandit in CI.
Tech stack: Python, requests, Beautiful Soup and GitHub Actions.
Source code: github.com/mojtaba-py-code/polite-web-crawler
Need data collected from websites, safely and politely? Send me a message with the sites and the fields you need.
Like this project
Posted Oct 14, 2026
Crawls a website into clean JSON, one record per page, while obeying robots.txt, rate limits and an SSRF guard. 46 tests, 88% coverage.