
Built a Production-Grade, Multi-Format YellowPages Scraper with Advanced Bot Bypass.
I recently engineered and deployed a robust, server-side web scraping pipeline designed to extract high-density business listings from YellowPages. While many directory scrapers rely on fragile frontend DOM parsing or heavy, resource-intensive browser automation (like Selenium), this project focuses on speed, architectural cleanliness, and smart evasion.
🛠️ The Tech Stack
Language: Python
Networking Layer: curl_cffi (Advanced TLS/HTTP2 browser impersonation)
Parsing Engine: BeautifulSoup4
Data Manipulation & Structuring: Pandas, Openpyxl
💡 The Core Challenges & Engineering Solutions
1. Bypassing WAF & Anti-Bot Mitigations (403 Forbidden)
Standard HTTP client libraries (like requests) are immediately flagged by modern Web Application Firewalls (WAF) due to predictable TLS fingerprints.
The Solution: I integrated curl_cffi to mimic low-level Google Chrome TLS handshakes and HTTP/2 signatures flawlessly.
The Session Layer: Combined this with persistent session management (requests.Session abstraction) and dynamic Referer header chaining to replicate natural human pagination paths, completely eliminating multi-page blocks.
2. Avoiding Fragile DOM Selectors
Web layouts change constantly, breaking traditional CSS element selectors.
The Solution: Instead of targeting class names on the frontend page, the script isolates and extracts structured application/ld+json script blocks hidden inside the raw HTML. This extracts pristine, un-truncated schema objects directly from the backend payload.
3. High-Fidelity Data Delivery (5 Formats)
Different clients need different data deliverables. I built a dynamic pipeline that automatically deduplicates records by business name/phone and compiles the data into five distinctive formats simultaneously:
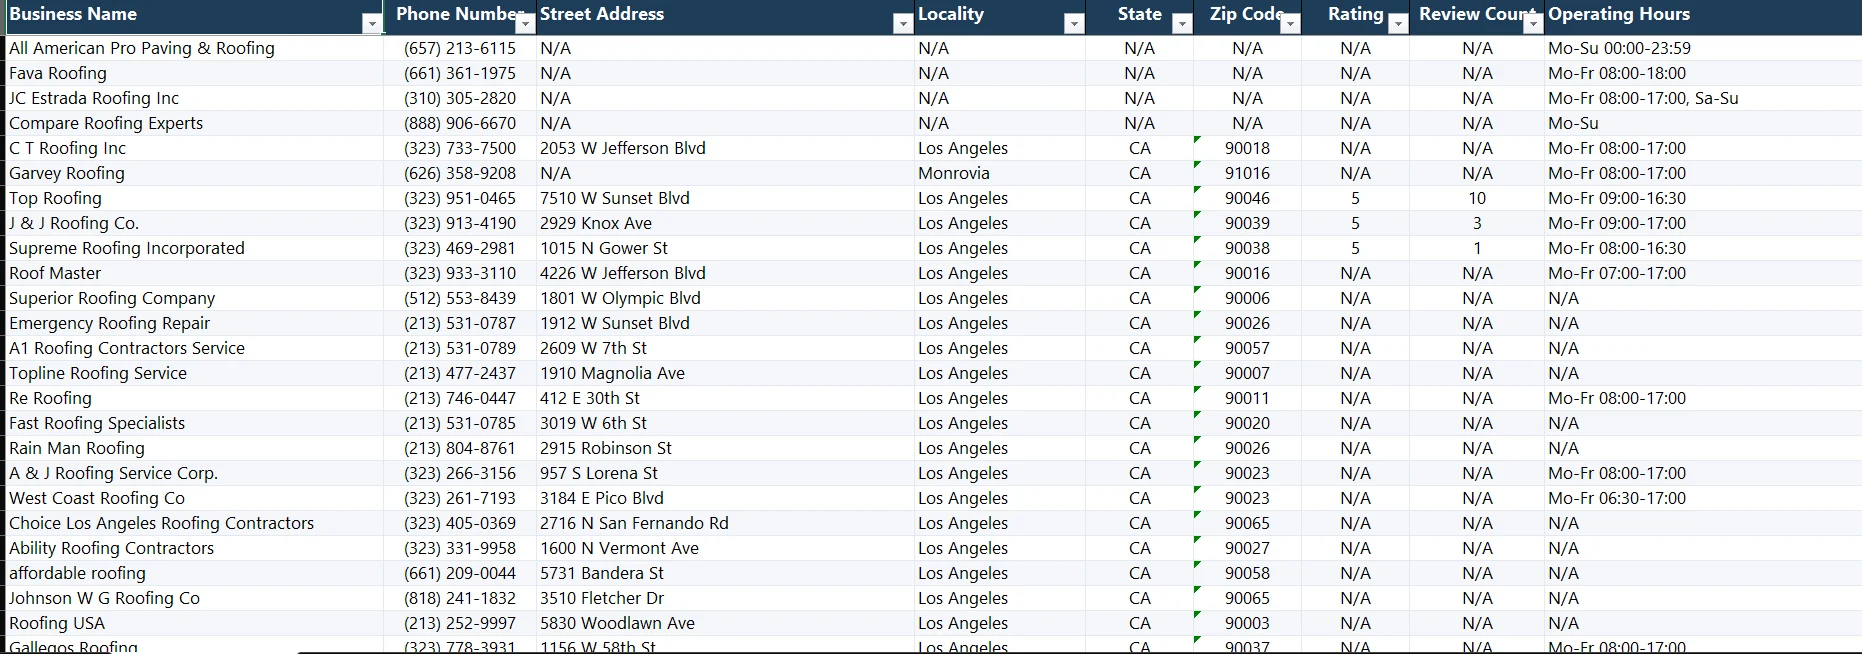
Excel Workbook (.xlsx): Fully stylized with custom corporate themes, column auto-fit scaling, frozen header planes, and built-in active sorting filters.
Flat CSV Matrix: UTF-8 encoded, optimized for smooth importing into database architectures or CRMs.
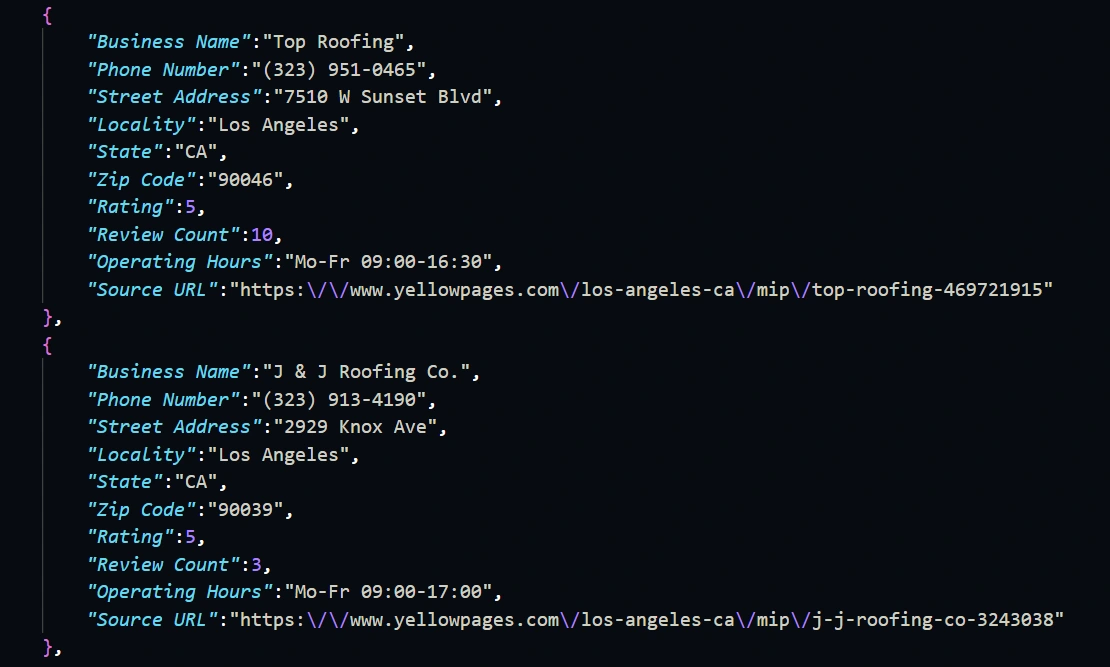
Schema JSON Array: Clean, nested relational object trees.
Structured Markup XML: Safely escaped entities for enterprise software parsing.
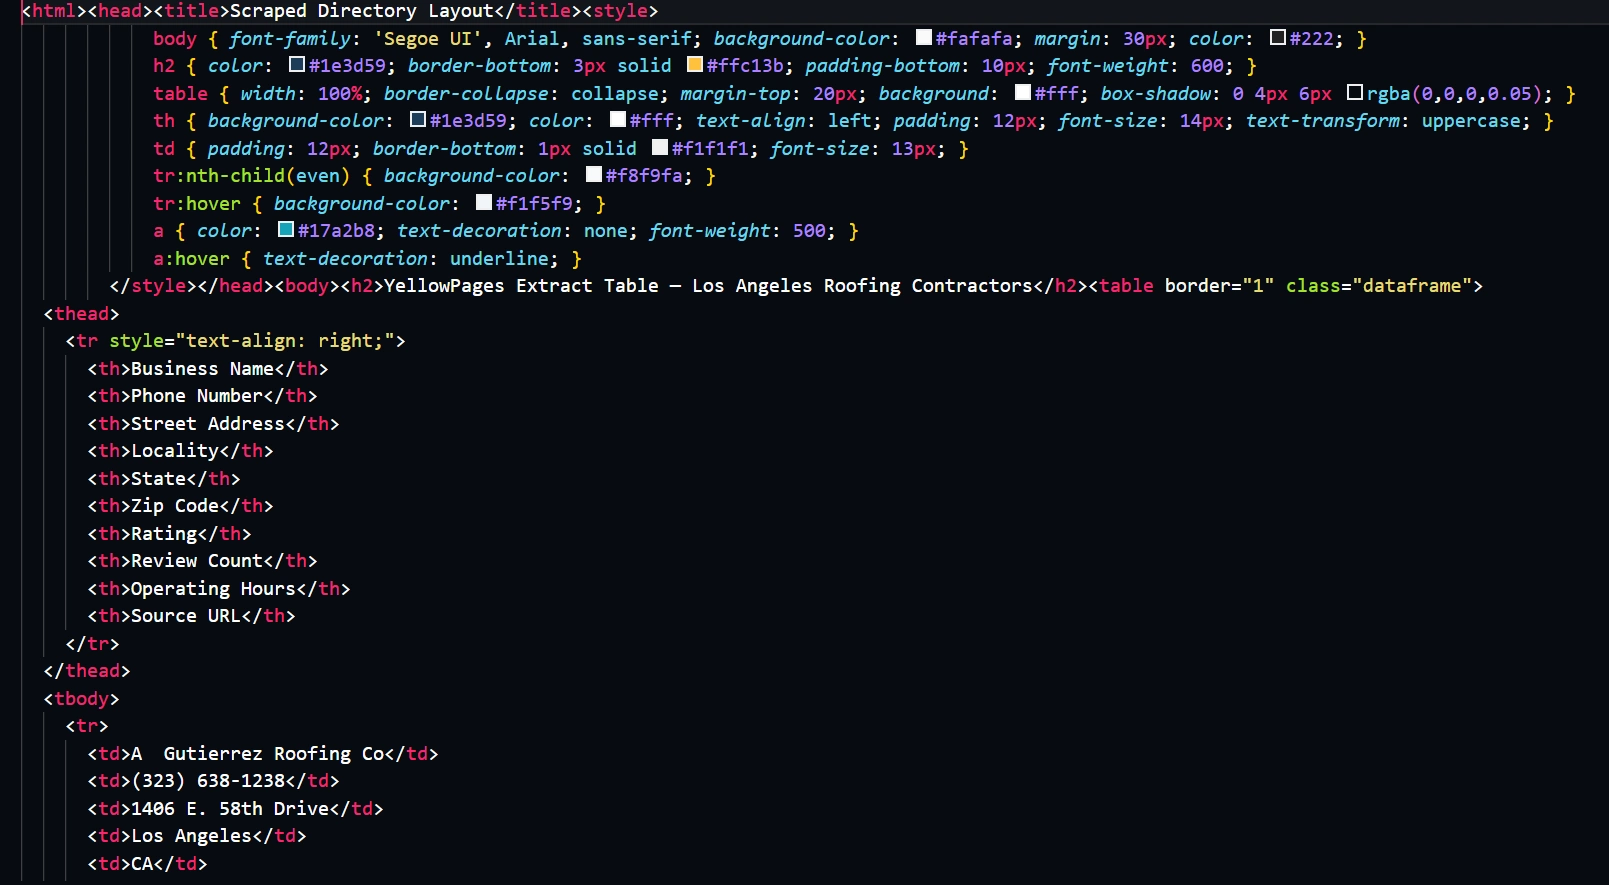
Presentable HTML View: A responsive CSS-styled table markup for quick localized browser validations.
📊 The Results
On its final deployment run, the pipeline handled 20 sequential page cycles completely block-free, cleanly generating 578 unique, deduplicated B2B leads directly into organized local assets.
📂 Repository & Code Architecture
The code is built strictly around clean architecture guidelines:
Isolated virtual environments (venv).
Production-safe configurations (.gitignore masking raw data and dependencies).
Modular, object-oriented class execution flow (src/scraper.py).
For Full Project Overview and Source Code
Check Out Github : https://github.com/Tausif-11/yellowpages_scraper
If You want to work with me and build a similar project, You can send a message or you can also check out my Fiverr Page , there I've made customized offers for different projects.
https://www.fiverr.com/s/WEaA6PL
0 likes · 0 views · Jun 1, 2026
Built a Production-Grade, Multi-Format YellowPages Scraper with Advanced Bot Bypass. I recently engineered and deployed a robust, server-side web scraping pi...


