Second Rater Spot-Check: Sample Verdict (Synthetic Data)

Suliman Abdelaty

What this is
An illustrative example of the one-page verdict a Second Rater Spot-Check client receives. The app, the responses and the scores are fictional; no client data is used.
The brief
A fictional AI writing-feedback app scores B1–C1 workplace emails. Its product team asks two questions: does our scorer agree with a trained examiner, and where does it not?
What I did
I took 20 emails the AI had already scored, marked them blind against the app's own band descriptors, then compared my bands with the model's by task, band and language feature.
What the verdict showed
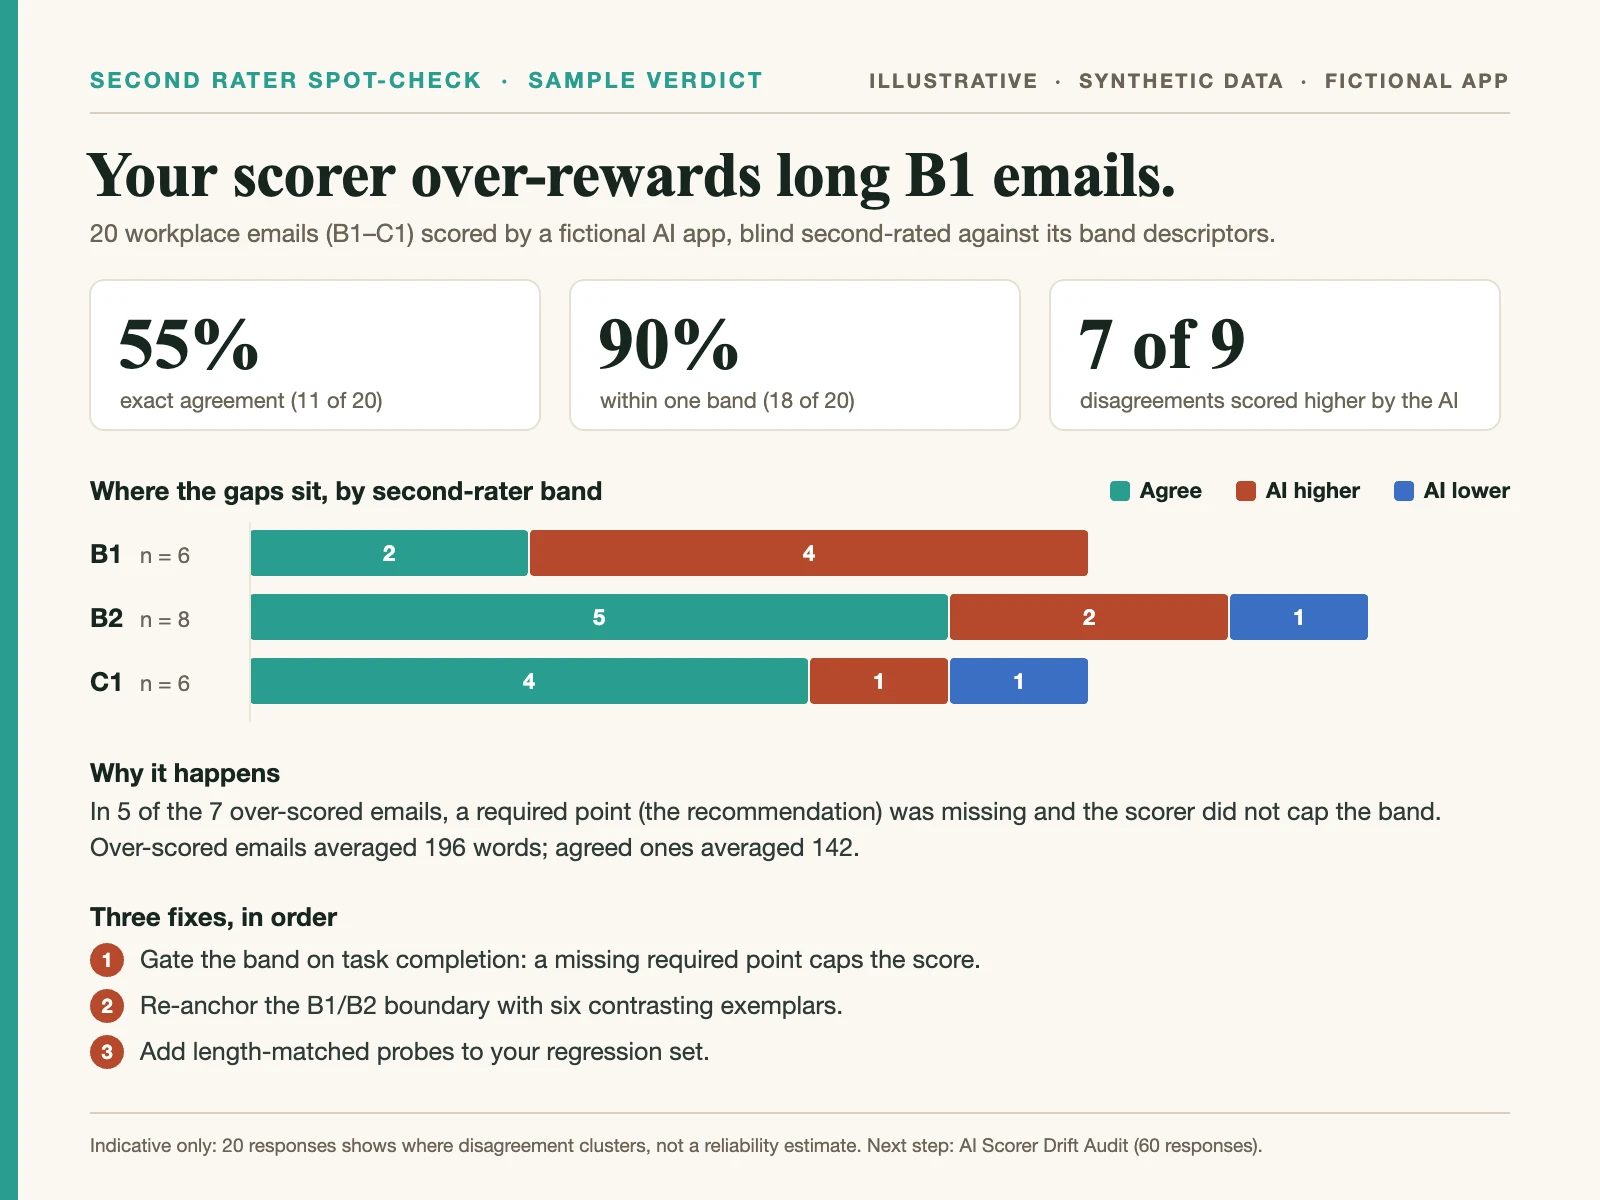
Exact agreement on 11 of 20 emails, and 18 of 20 within one band. Seven of the nine disagreements went the same way: the AI scored higher. Most sat at B1, where long, fluent-looking emails that skipped the required recommendation still earned B2.
The three fixes
Gate the band on task completion, so a missing required point caps the score.
Re-anchor the B1/B2 boundary with six contrasting exemplars.
Add length-matched probes to the regression set so the fix can be tested.
Limits
Twenty responses show where disagreement clusters; they cannot estimate reliability. Confirming this pattern would need the AI Scorer Drift Audit on a 60-response probe set.
Get your own verdict
Send 20 responses your AI has already scored and book the Second Rater Spot-Check: $550, five days, one page, with the fee credited against a Drift Audit.
Like this project
Posted Nov 2, 2026
An illustrative one-page verdict: 20 AI-scored emails second-rated blind, where the scorer drifts, and three fixes. Fictional app and data.