
I built custom 4-bit (NVFP4) training kernels and tooling for a consumer RTX 5070 Ti, to see how far one home GPU can go training language models from scratch.
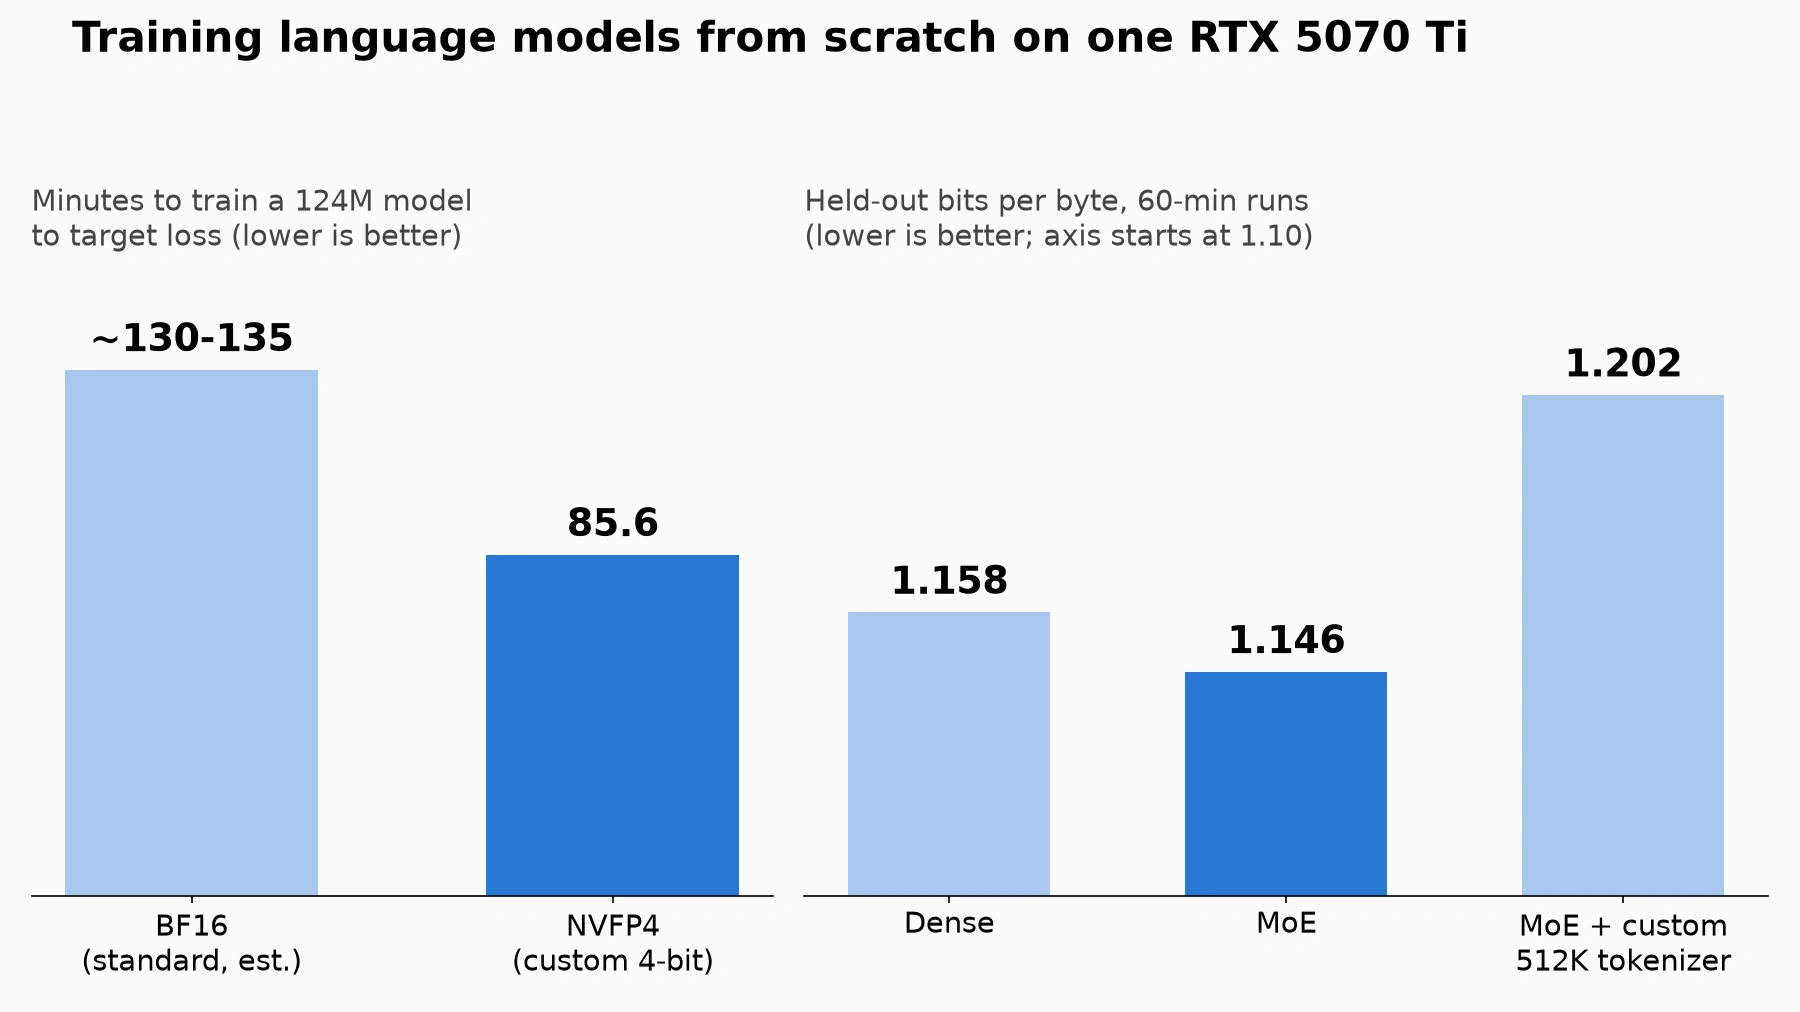
A 124M-parameter model reached target loss (val 3.28) in 85.6 minutes, versus about 130 to 135 minutes estimated for standard BF16 training.
I also ran from-scratch architecture experiments on a 9-domain corpus, comparing held-out bits per byte (lower is better) after 60-minute runs.
Dense model 1.158
Mixture-of-experts 1.146
Mixture-of-experts with a custom 512K superword tokenizer 1.202
0 likes · 0 views · Nov 10, 2026
Custom 4-bit (NVFP4) training kernels on one RTX 5070 Ti: a 124M model hit target loss in 86 minutes vs about 130 for standard BF16.


