
For Workybara I distilled a larger LLM into a 350M-parameter LoRA model that pulls structured skills out of job posts.
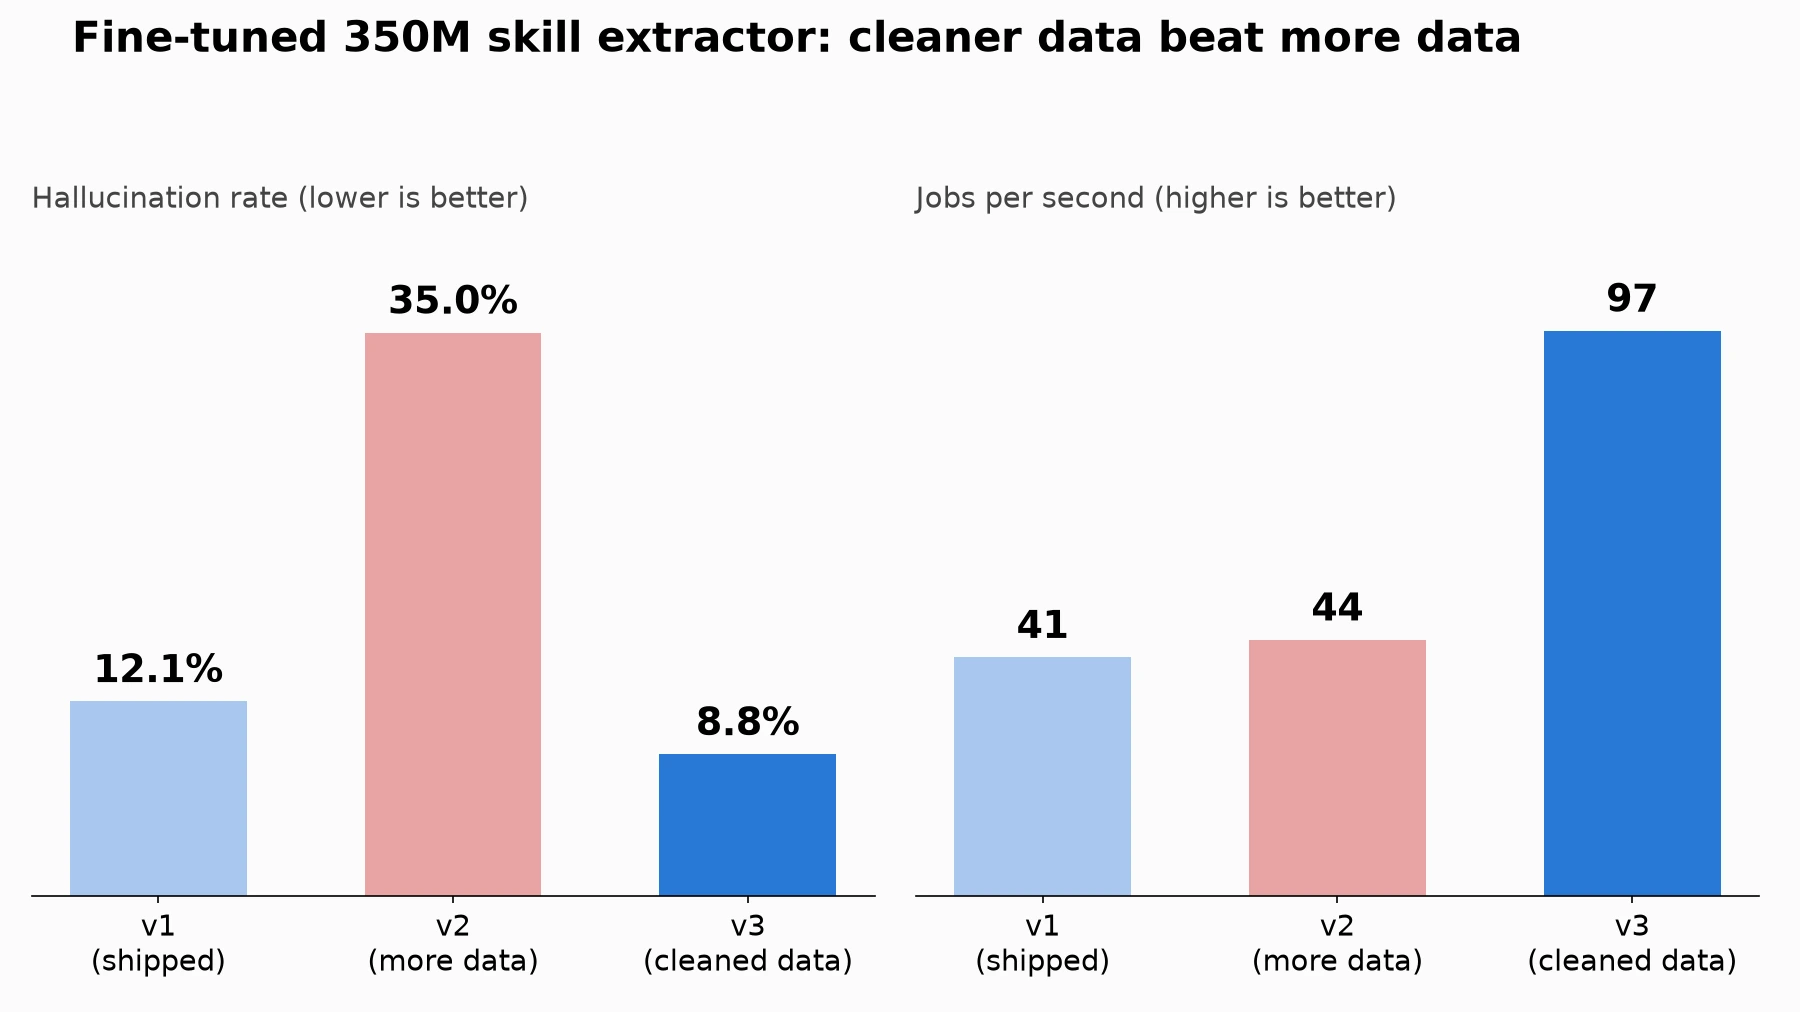
The biggest win was the data, not the model. I cleaned 128K noisy training labels down to 82K using LLM audits and MinHash dedup. An earlier version trained on more, noisier data nearly tripled its hallucination rate, which is what pushed me to fix the data first.
Results versus the previous version are below.
35% fewer hallucinated skills per job
2.4x faster (41 to 97 jobs per second)
99.8% valid JSON output
Trains in about 2 hours on one consumer GPU (RTX 5070 Ti)
0 likes · 0 views · Nov 10, 2026
Distilled LLM extractor: 35% fewer hallucinations, 2.4x faster, 99.8% valid JSON, trained in about 2 hours on one consumer GPU.


