
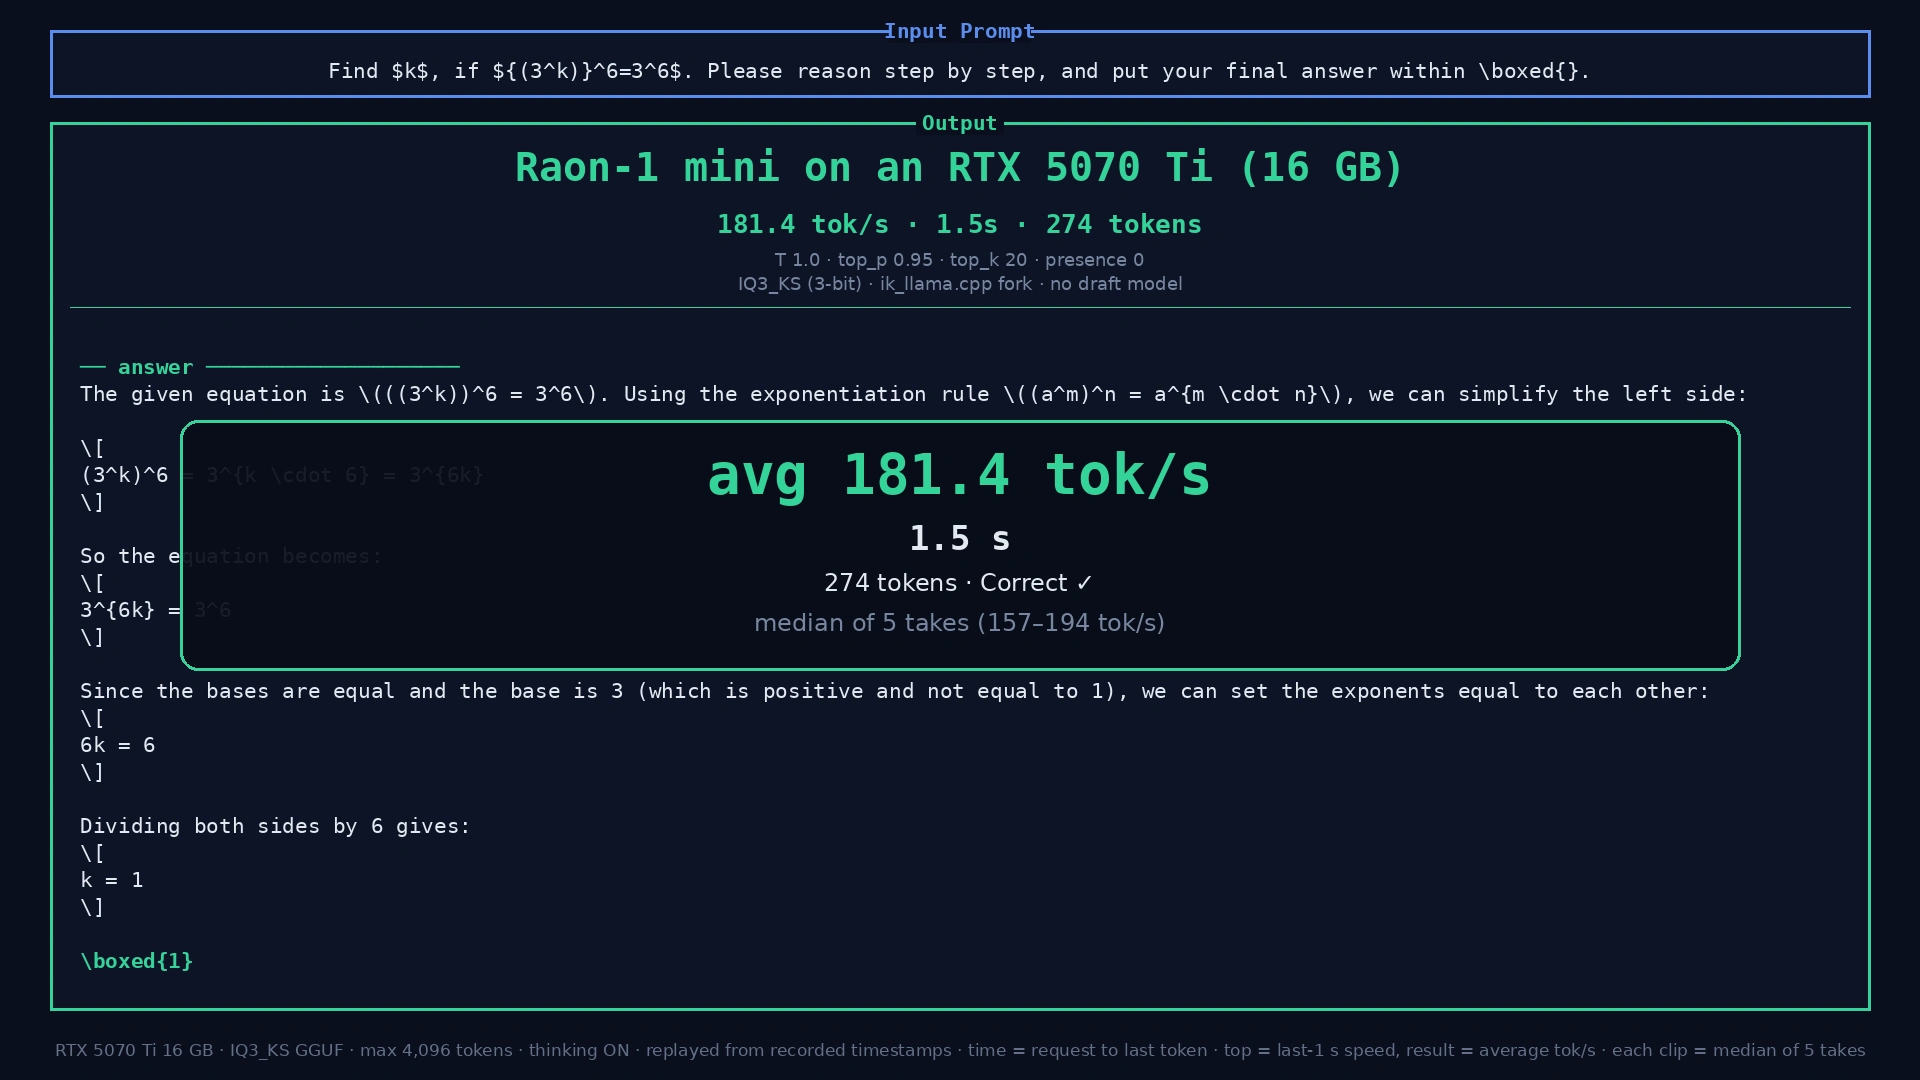
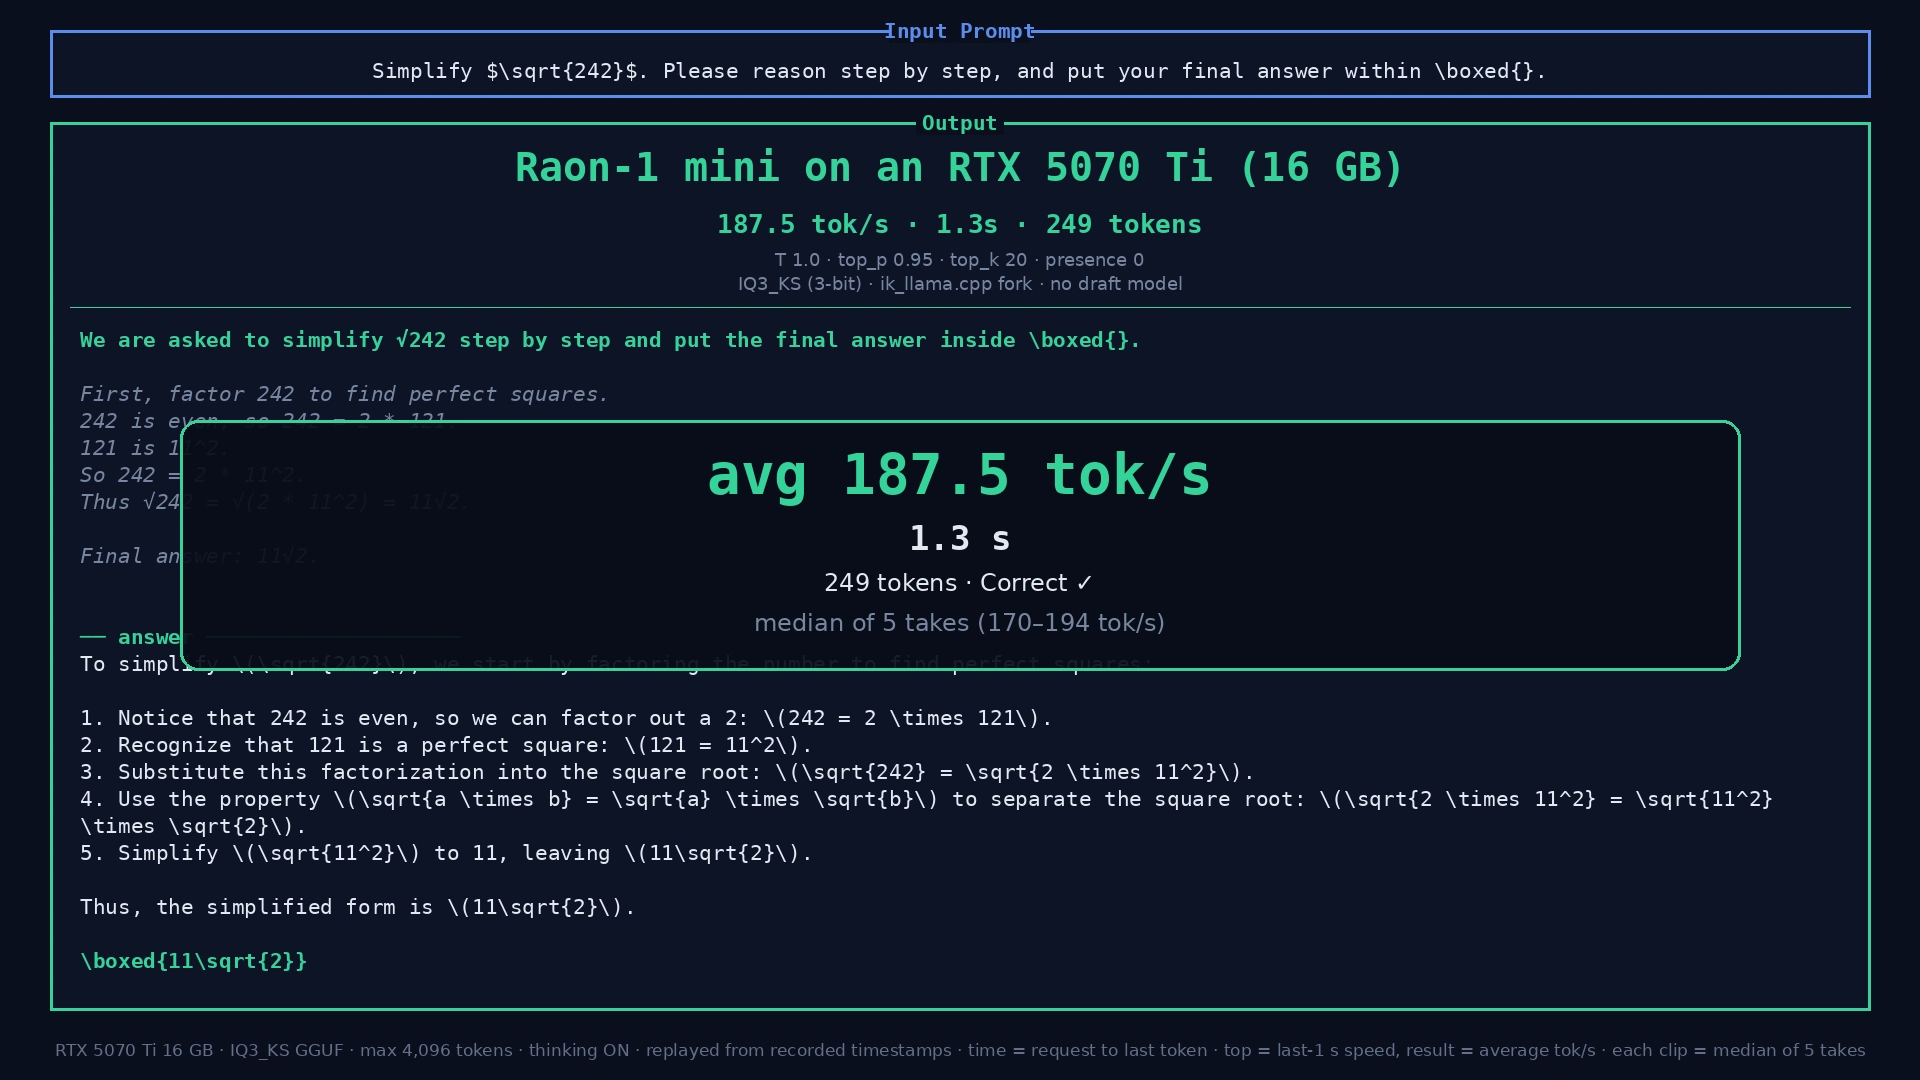
KRAFTON's Raon-1 mini is a brand-new 30B-parameter model that normally needs far more GPU memory than a consumer card has. I got it running entirely on a single 16GB RTX 5070 Ti.
Using quantization, expert pruning and custom CUDA kernels on a fork of ik_llama.cpp, decode speed went from about 97 tokens per second in a plain port to about 220 to 230.
Output was checked against the reference implementation, and I built the eval harness around it, with public benchmarks, custom test sets and blind LLM judging. Adding retrieval over Wikipedia raised accuracy on my test set from 25% to 70%.
The cards above are replays of real runs answering step-by-step math questions (median of 5 takes each).
The fork is open source on GitHub (linked below).
0 likes · 0 views · Nov 10, 2026
Got a brand-new 30B model running on one 16GB consumer GPU at about 220-230 tokens/sec, roughly 2.3x a plain port, verified against the reference.


