Short-form clips cut from a long talk

Vincent L. Anderson


A demo built for a specific brief. Not client work: the material shown is sample data, so what is on display is the mechanism.
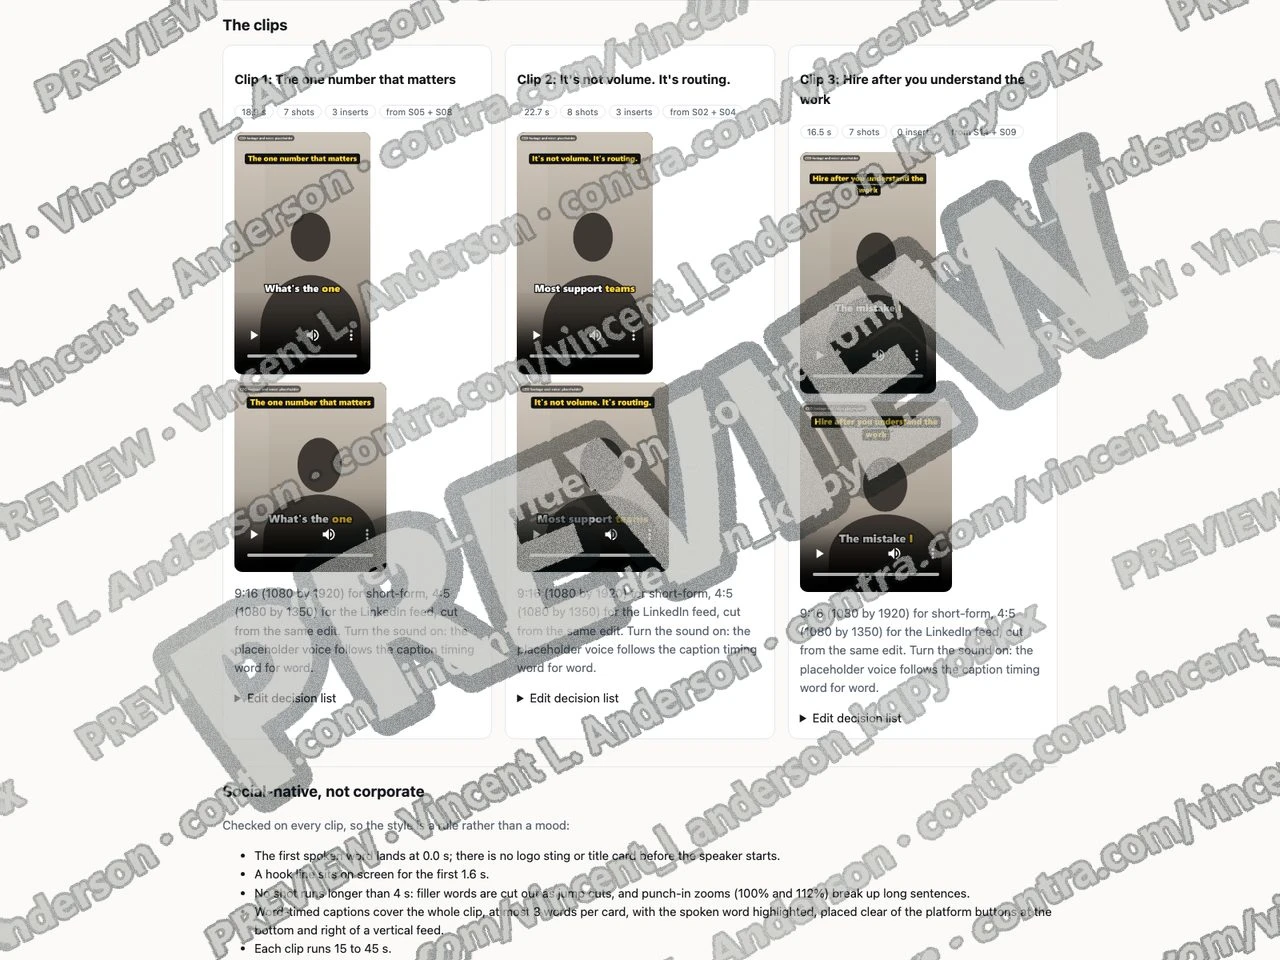
Short-form clips cut from a long talk, animated preview 1 of 3
Short-form clips cut from a long talk, animated preview 2 of 3
Short-form clips cut from a long talk, animated preview 3 of 3
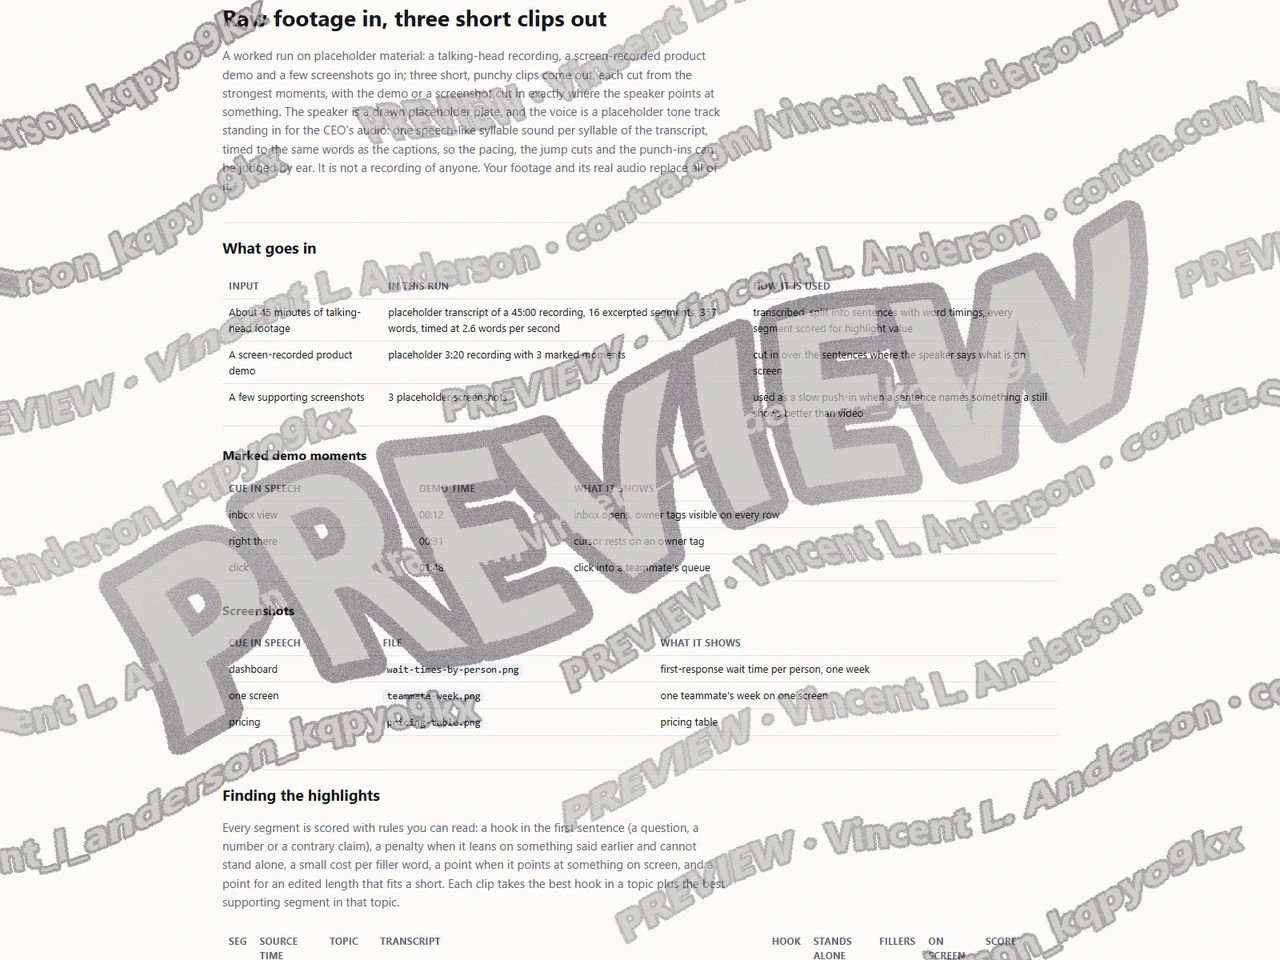
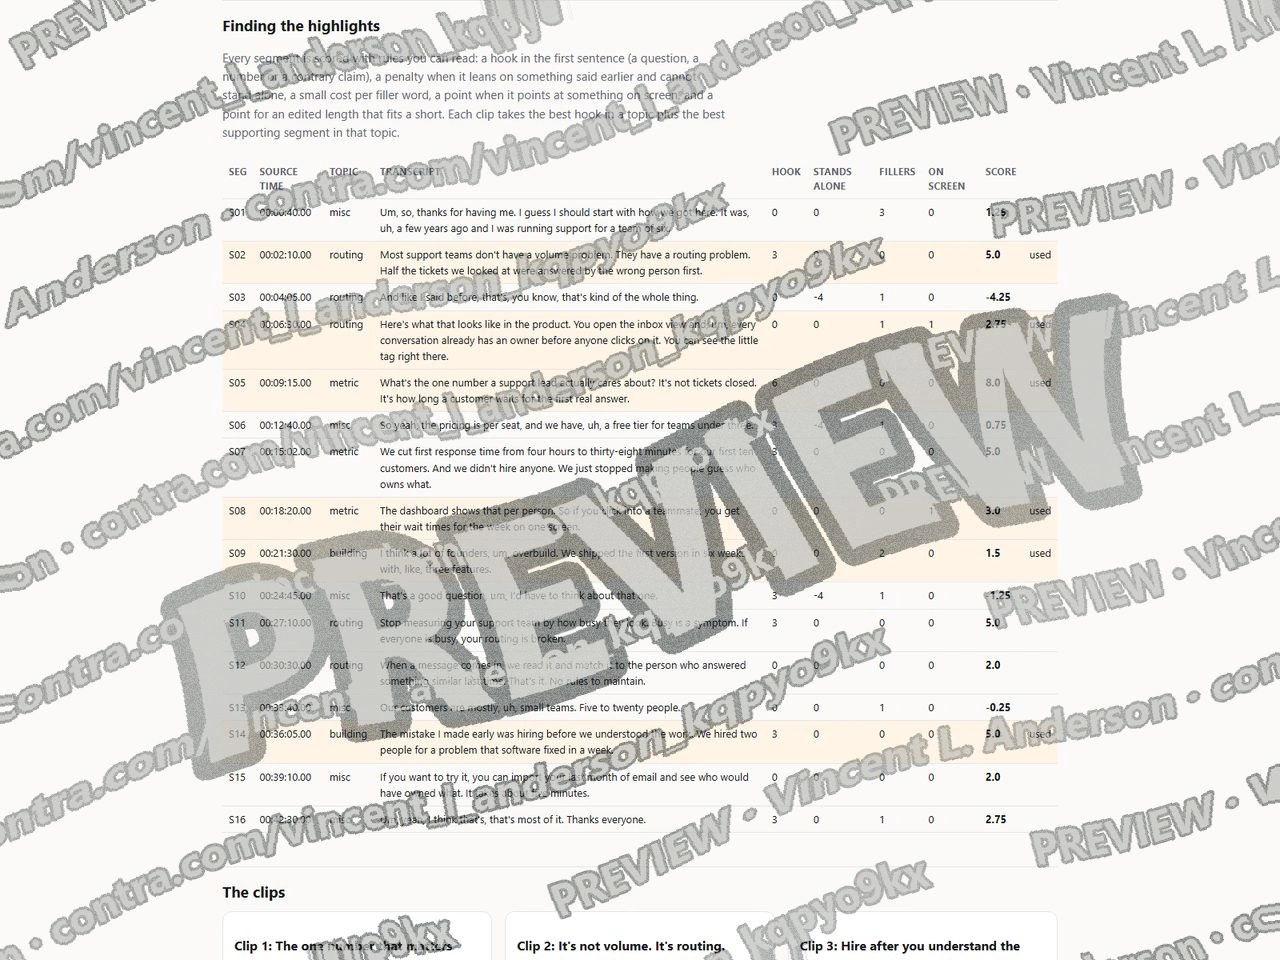
I built a worked run of a long-talk-to-short-clips job on placeholder inputs. A placeholder transcript of a 45:00 talking-head recording (16 excerpted segments) is split into sentences and word timings, and every segment is scored with readable rules: a hook in the first sentence, a penalty if it leans on something said earlier, a cost per filler word, a point when it refers to something on screen. The best hook in each of 3 topics plus its best supporting segment becomes a clip; fillers are cut as jump cuts, punch-ins keep every shot at or under 3.9 s, and the demo recording or a screenshot cuts in only over the sentences that point at them (6 inserts). Clips run 19, 23 and 17 s, the first word lands at 0.0 s with no logo sting, and captions of at most 3 words cover the whole clip. It renders 6 MP4s, each clip at 1080x1920 (9:16) and 1080x1350 (4:5), with an edit decision list per clip. The speaker is a drawn placeholder and the voice is a placeholder tone track timed to the caption words; with real footage the same edit runs on the speaker's own audio and video.
Short-form clips cut from a long talk 1
Short-form clips cut from a long talk 2
Like this project
Posted Sep 23, 2026
Three short, social-native clips cut from a placeholder 45-minute talking-head recording, with a demo recording and screenshots woven in, delivered at 1080x1920 and 1080x1350 with a placeholder voice track so the pacing can be heard.
Likes
0
Views
1