Find the source behind the answer.

Ivan Madrigal


The business problem
A large collection of documents and correspondence needed to become searchable without losing the connection between a result and its source. The work required more than a chat interface: extraction, indexing, provenance, and ingestion checks all had to function together.
What I built
LIT is an internal document-intelligence and evidence-retrieval system. It combines Docling extraction, document chunking, local embeddings through Ollama, PostgreSQL with pgvector, a Python/FastAPI backend, and a React interface. Search and source review support human judgment.
A documented ingestion result
An audit dated July 26, 2026 recorded a batch adding 2,359 document records and 20,822 searchable chunks. It reported zero NULL embeddings and zero documents without chunks in that batch. Semantic retrieval over the new records was also checked end to end.
Result and scope
This case demonstrates an implemented retrieval pipeline and a specific ingestion-quality check. The figures are a historical batch snapshot, not a current corpus count or an accuracy score. Source contents are private; the visuals use only aggregate figures and a reconstructed workflow.
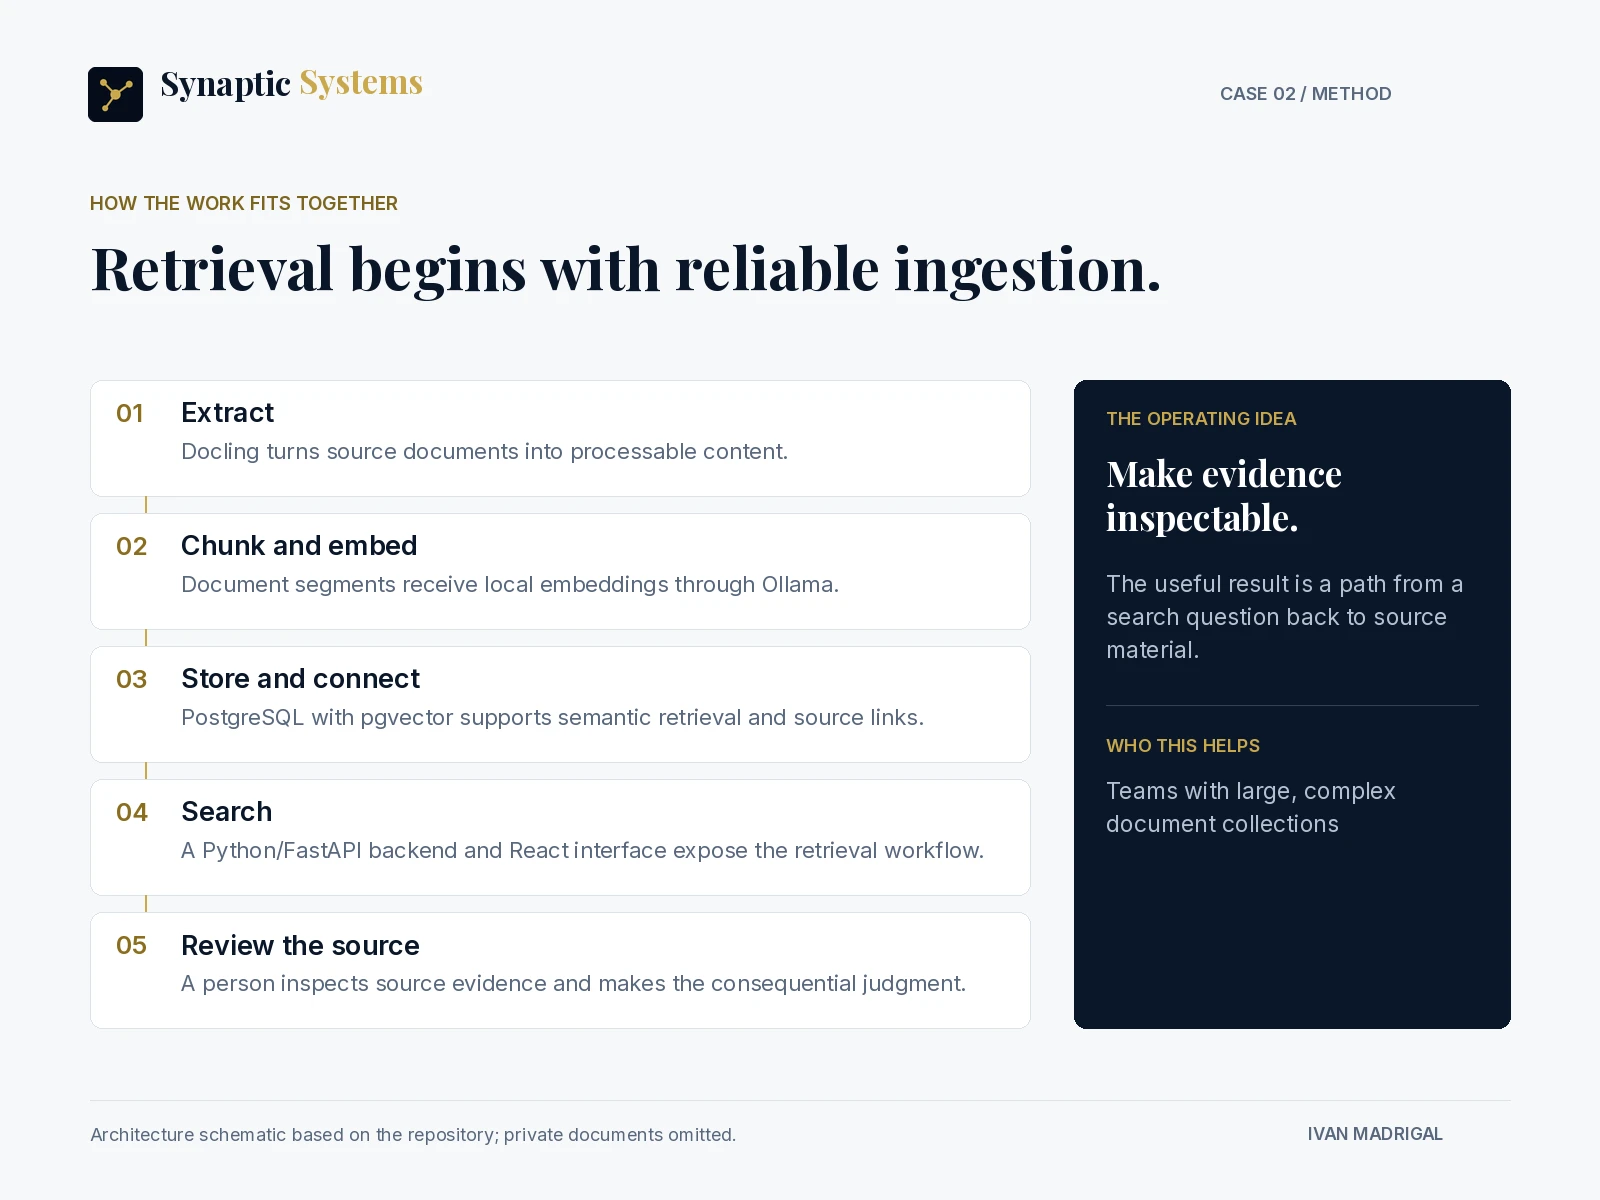
Architecture schematic based on the repository: extract, chunk and embed, store, retrieve, and review. It is not a product screenshot.
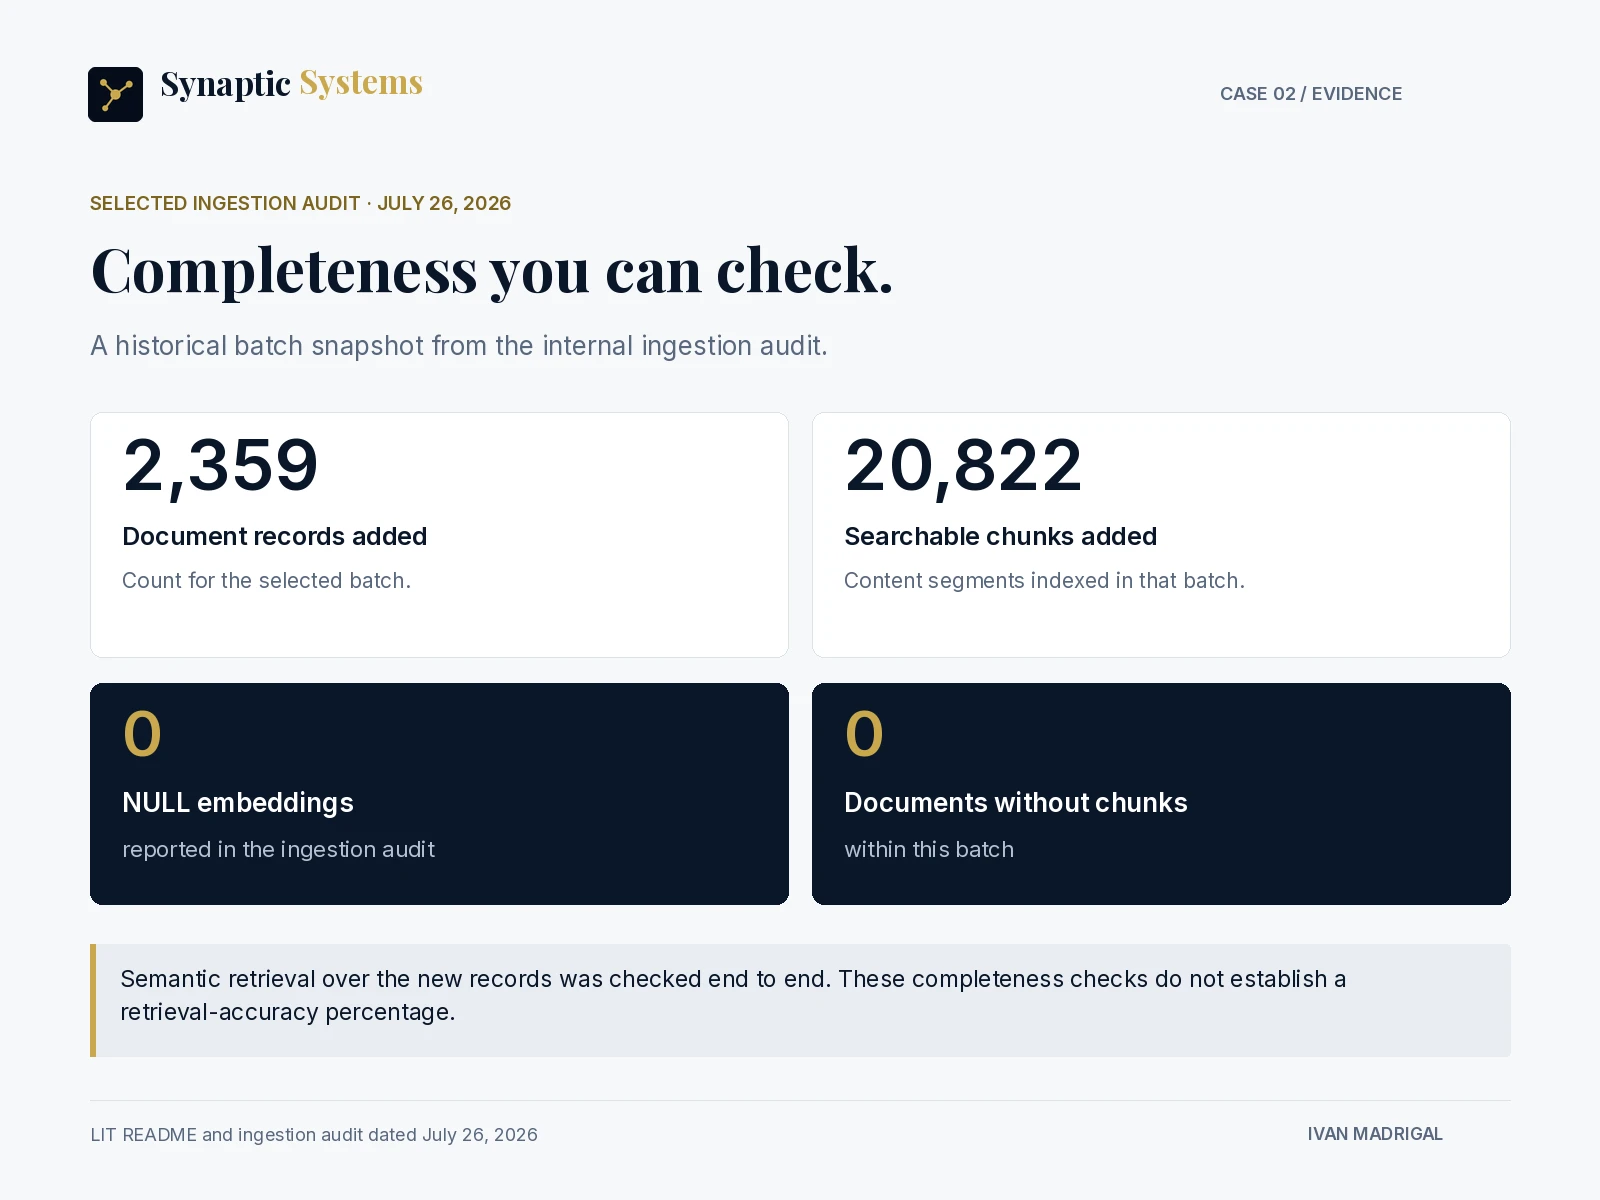
Selected ingestion audit, July 26, 2026: 2,359 added records, 20,822 chunks, zero NULL embeddings, and zero unchunked documents in that batch. These are completeness checks, not a retrieval-accuracy score.
Like this project
Posted Oct 20, 2026
An internal document-intelligence system combining extraction, semantic search, source traceability, and human review.
Likes
0
Views
4