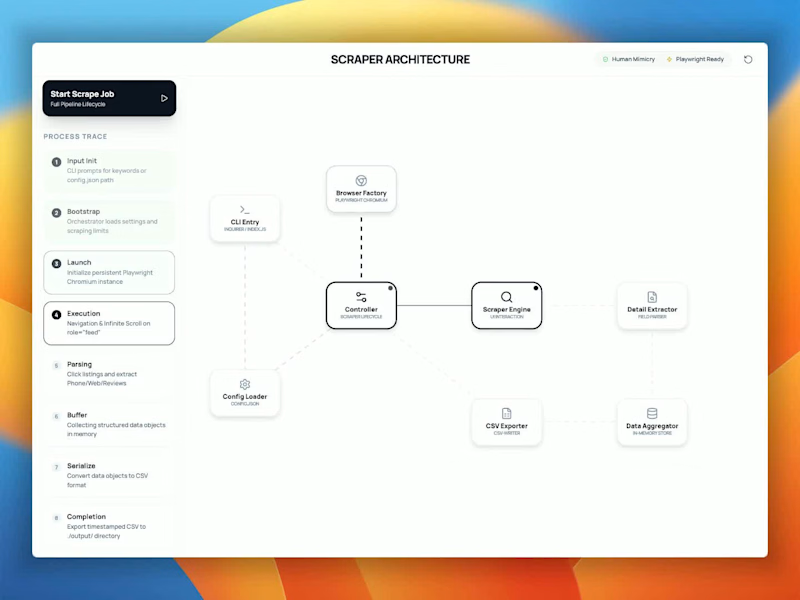
Projects using PlaywrightProjects using PlaywrightExpert in reliable web scraping and data extraction for dynamic websites, eCommerce, directories, marketplaces, and business platforms. Experienced with Python, Playwright, Selenium, Scrapy, BeautifulSoup, Requests, APIs, proxies, browser automation, and data pipelines to collect, clean, validate, and export structured data into CSV, Excel, JSON, databases, or APIs with robust error handling and scalable workflows.
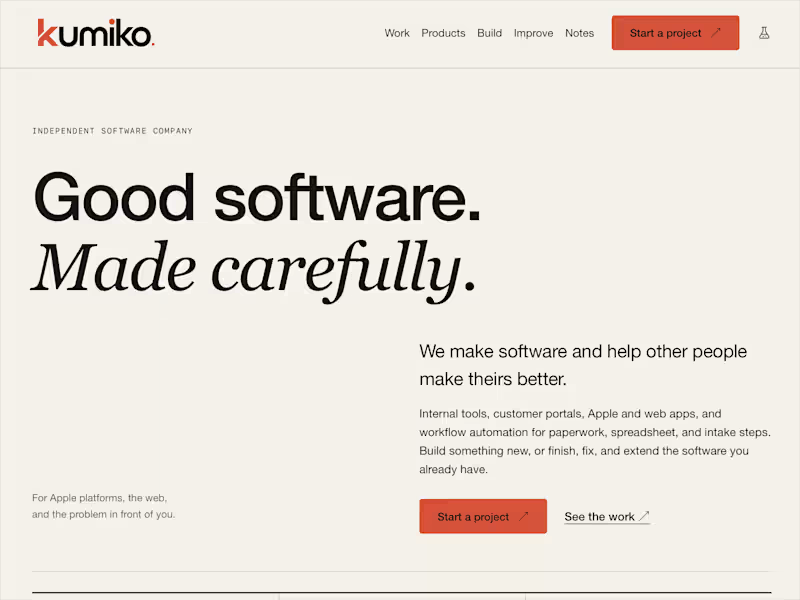
Kumiko's own website, designed, built and operated by me on Cloudflare Workers, with every push to main deploying automatically via a custom CI/CD workflow.
What it covers:
Hosting and DNS: HTTPS enforced, www redirects to the main domain with paths and query strings kept, and old URLs permanently redirected to their new homes.
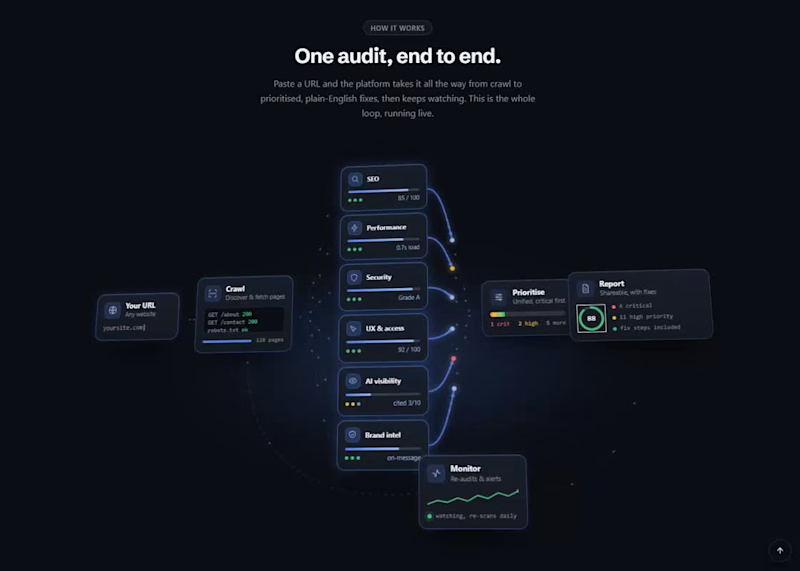
SEO and AI search: page titles and descriptions everywhere, schema.org (http://schema.org) structured data linking the company, its services, products, case studies and notes, an llms.txt file plus a full-text version for AI engines, Markdown and RSS versions of every note, and a sitemap verified in Bing Webmaster Tools. GPTBot, ClaudeBot, PerplexityBot and other AI crawlers are allowed in.
Contact form: inquiries go straight to email through a transactional email service, verified end to end in production.