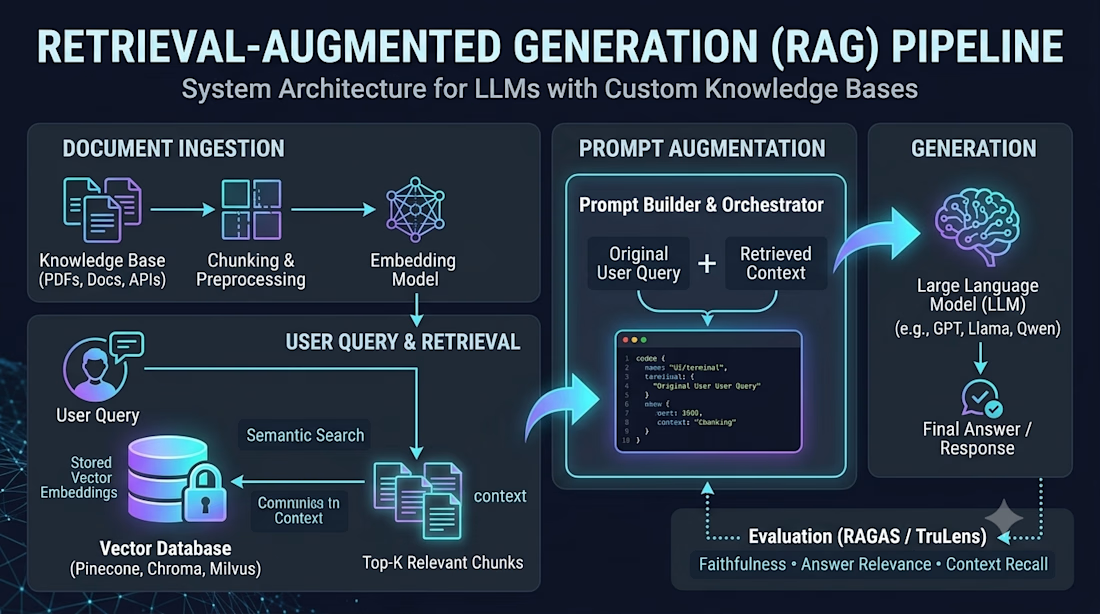

Building an LLM application that doesn't hallucinate? It’s all about the context. 🧠
I put together this high-level architecture breakdown of a Retrieval-Augmented Generation (RAG) pipeline to visualize how we can ground large language models in custom, domain-specific knowledge...