Recovering Rails Capacity from Stale PostgreSQL Connections

Mahmoud Ali


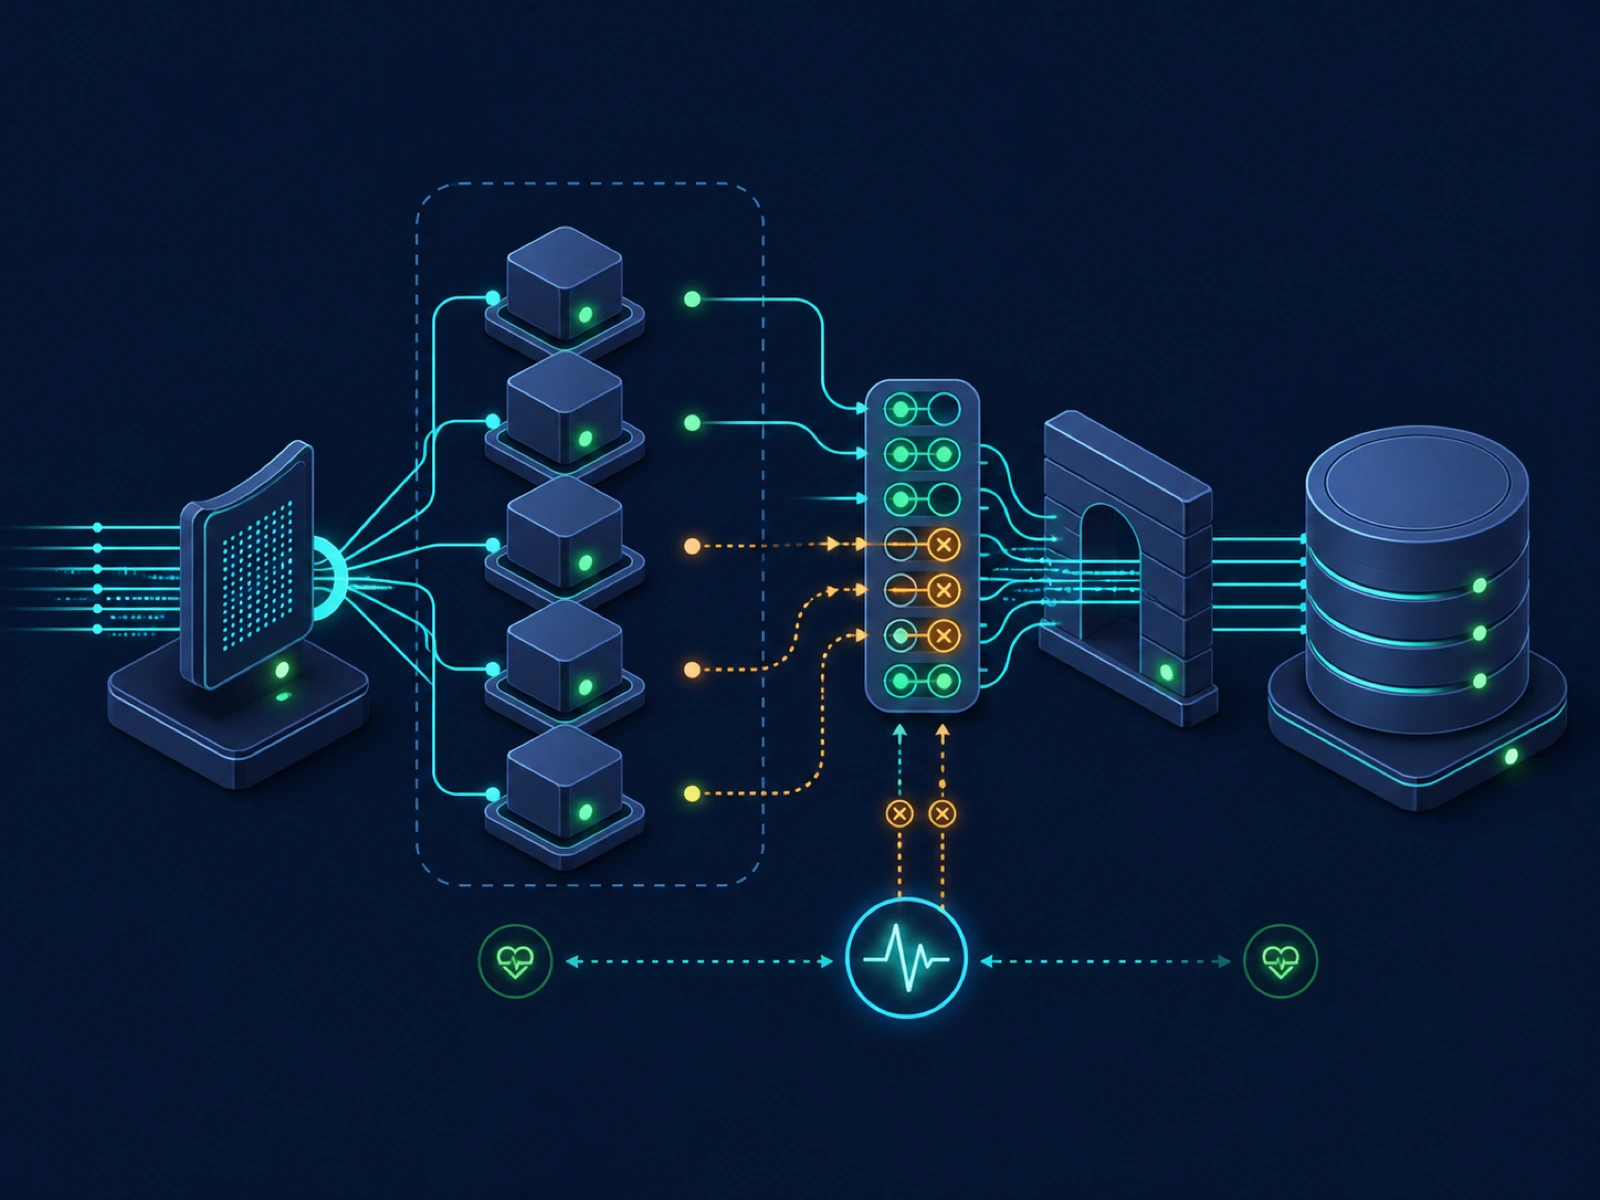
A production Rails service experienced approximately three hours of customer-visible downtime while its process-level health remained green. I led the investigation, recovery, preventive change, validation, and production release.
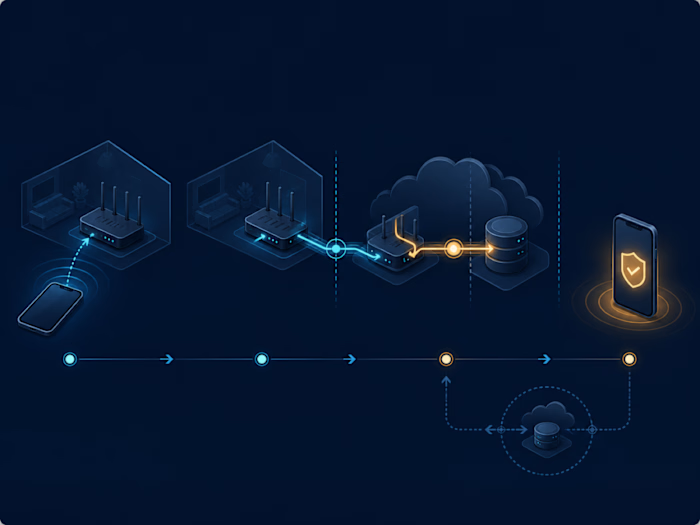
Requests were either fast or hit the proxy's 30-second cap. Host load stayed low and PostgreSQL remained healthy. The failure was between them: Rails retained long-lived PostgreSQL connections across a Docker bridge after network connection-tracking state disappeared. The client socket still appeared open, so a request thread could block waiting for a response to a query the database never received. Forty request threads across five workers were gradually consumed while system-default keepalive detection could take roughly two hours and eleven minutes.
Restarting the application container restored service but was only mitigation. I added a five-second connection-establishment timeout and explicit client-side TCP keepalives: 30 seconds idle, three probes, and ten seconds between probes. That bounded dead-connection detection to roughly 60 seconds so Active Record could discard the connection, reconnect, and return the thread to the pool.
I verified the live settings, keepalive countdown, normal request latency, and unaffected background jobs before release, then added a dedicated alert for the incident's 504 symptom. The same monitored 504 pattern was not observed during the following month. This is a bounded no-observed-recurrence result, not a guarantee of zero errors or outages.
Like this project
Posted Aug 30, 2026
A three-hour outage with green process health traced to stale pooled database connections that silently consumed Rails request capacity.