Web Data Pipelines Development for Crawlexa

Sagar Ahirrao


Crawlexa web-data examples
Small, readable examples of how Crawlexa builds data pipelines: crawl → extract → clean → compare → deliver.
Folder
What it shows
A polite catalogue scraper (robots.txt check, rate limit, retries, pagination) that writes CSV and JSON
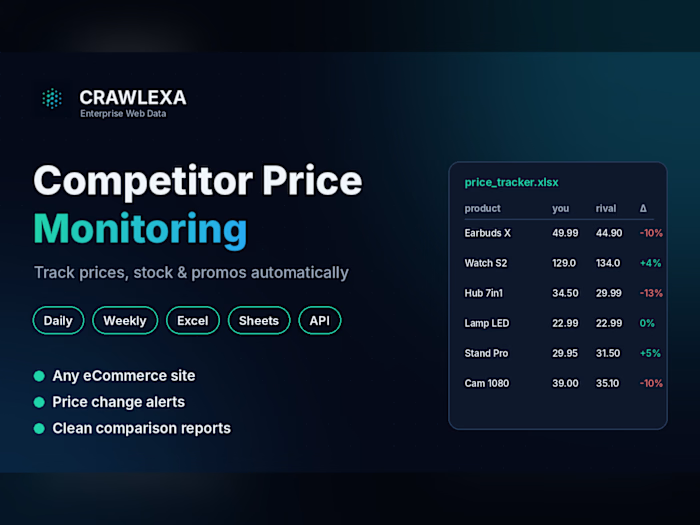
Compares two daily snapshots and reports price drops, rises, new and removed products
Normalises messy company and price records, removes duplicates and validates the result
The scraper targets books.toscrape.com , a public sandbox built for scraping practice.
Quick start
pip install -r requirements.txt python scraper/catalog_scraper.py --pages 3 --out sample_output/books python price_monitor/compare_snapshots.py sample_output/snapshot_day1.csv sample_output/snapshot_day2.csv python data_cleaning/clean_companies.py data_cleaning/messy_companies.csv
Principles
Public data only, within each site's terms and robots.txt
Identify the crawler, rate-limit requests, back off on errors
Validate every record before delivery
Need this at scale, with monitoring, on your own target sites? Get a free 1,000-record sample: crawlexa.com · sales@crawlexa.com
MIT licensed.
About
Example web data pipelines: polite scraper, price-change monitor and data-cleaning scripts (Python).
Like this project
Posted Nov 1, 2026
Developed web data pipelines for scraping, monitoring, and cleaning data.
Likes
0
Views
0