The problem. Teams ship LLM

The problem. Teams ship LLM features for contracts without knowing how accurate they are or when a prompt change breaks them.
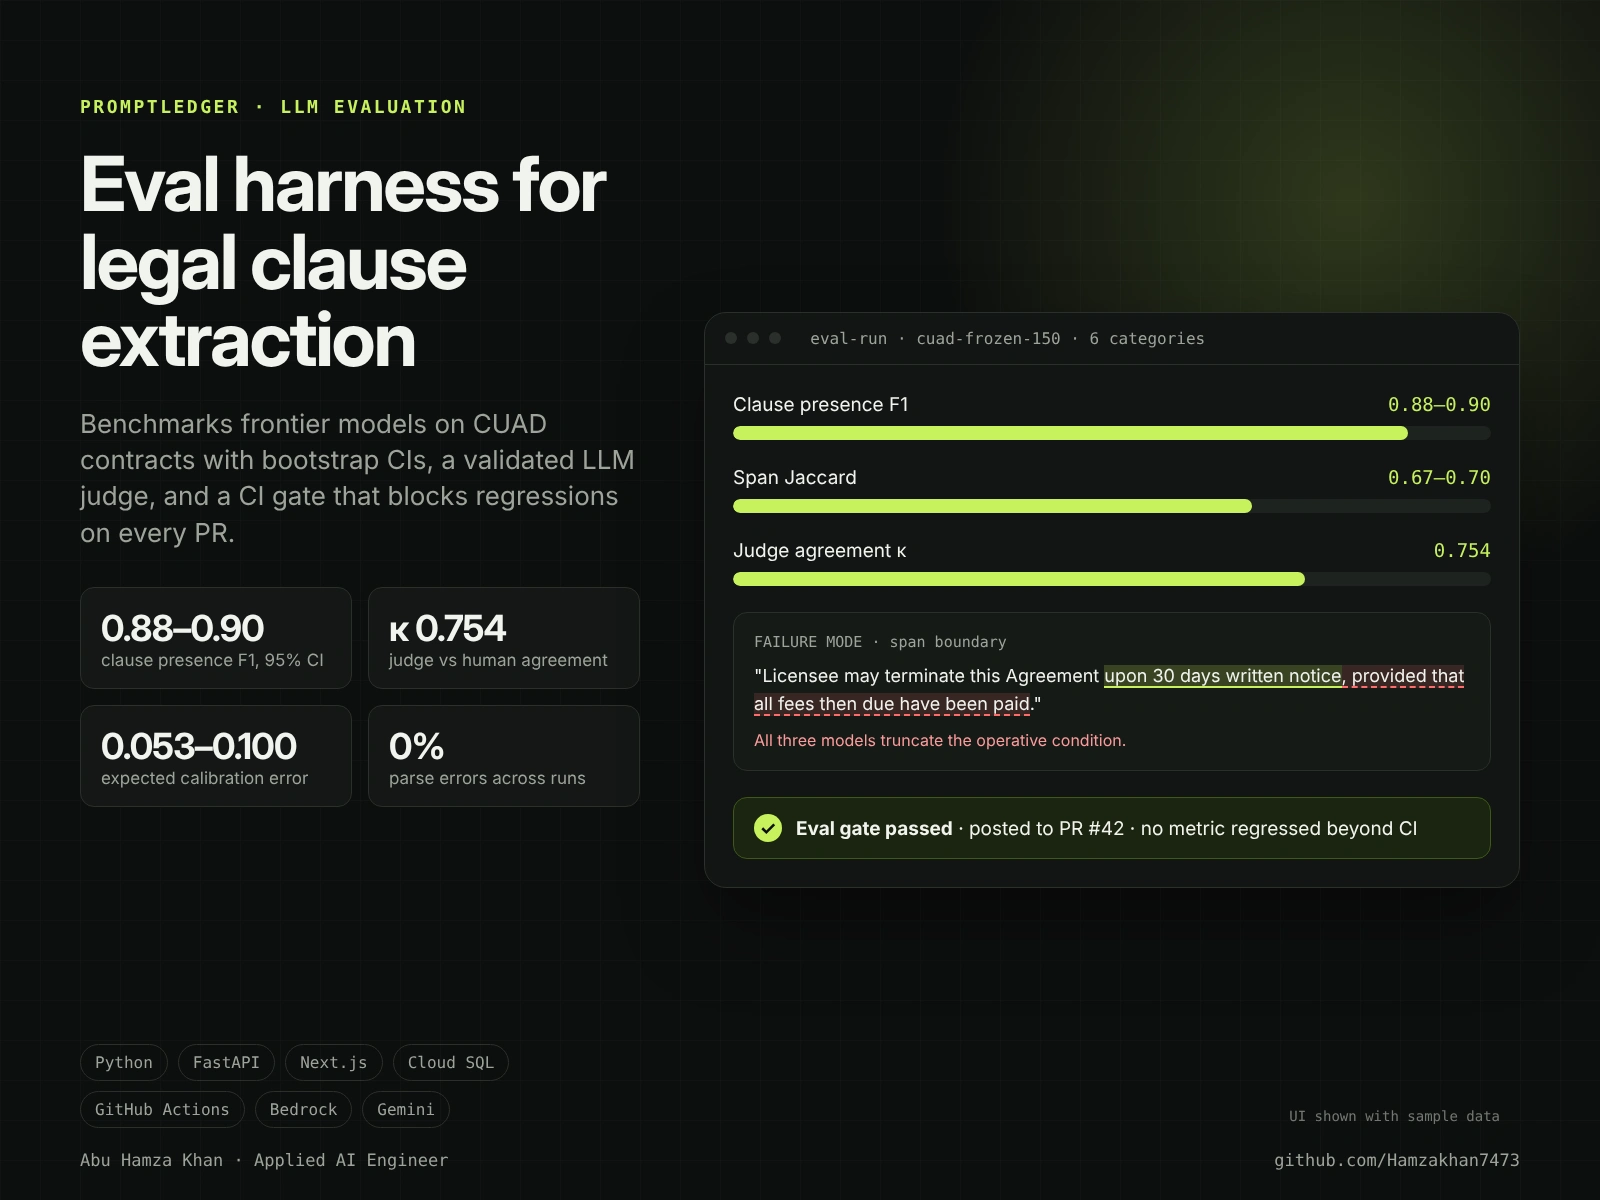
What I built. A multi-provider eval harness on CUAD contracts (150-example frozen set, 6 clause categories) with bootstrap confidence intervals, an LLM judge validated against human labels, calibration metrics, and a GitHub Actions gate that comments on every PR.
Results. Clause presence F1 0.88-0.90 (95% CI), judge agreement κ = 0.754, ECE 0.053-0.100, 0% parse errors. Found a shared failure mode: all three frontier models truncate the legally operative condition at span boundaries.
Stack. Python, FastAPI, Next.js, Cloud SQL, GitHub Actions, Bedrock, Gemini, Cloud Run.
0 likes · 0 views · Oct 11, 2026
The problem. Teams ship LLM features for contracts without knowing how accurate they are or when a prompt change breaks them. What I built. A multi-provider ...