PDF Extraction Engine: 4 Minutes to 0.2 Seconds per Document

Joe Estephan


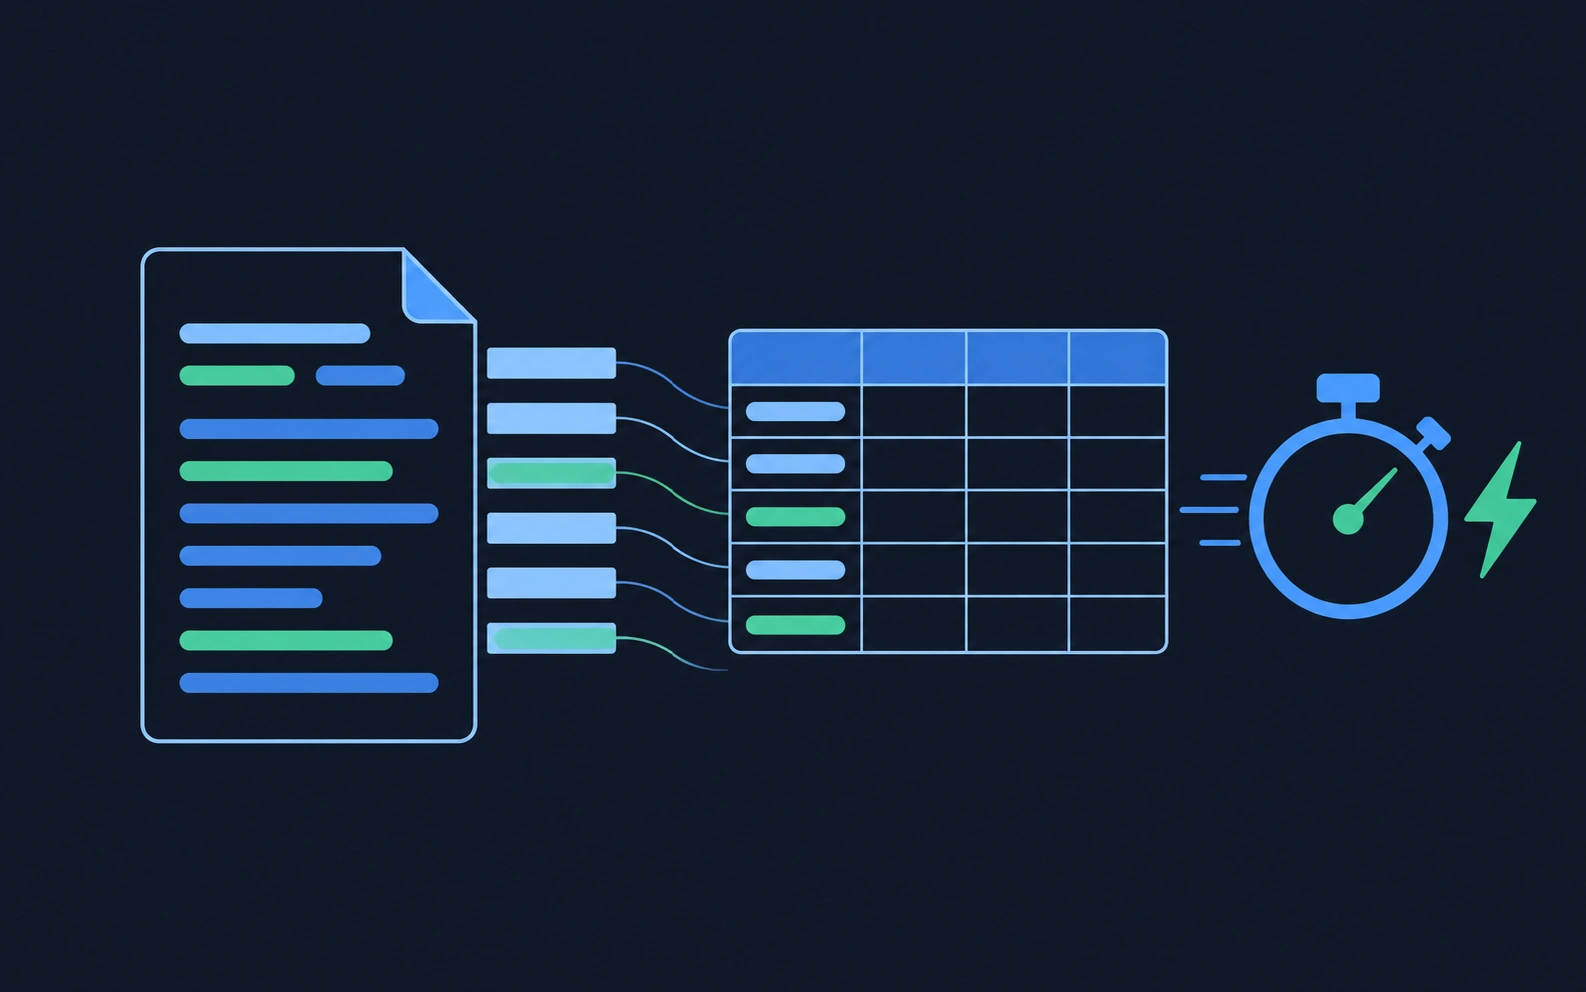
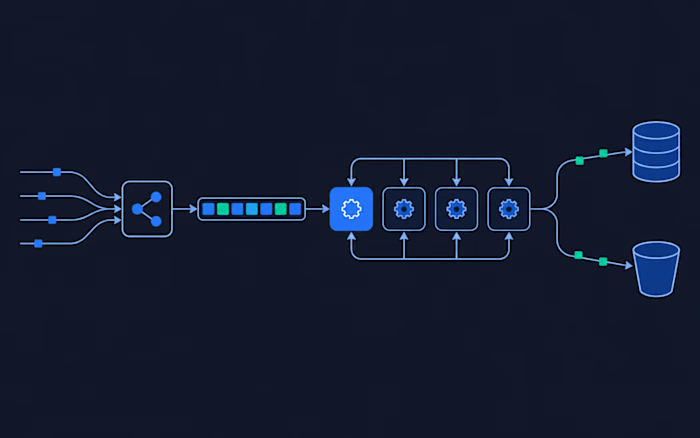
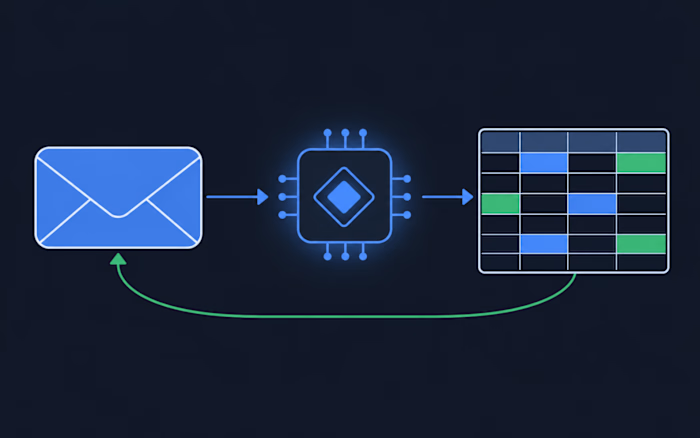
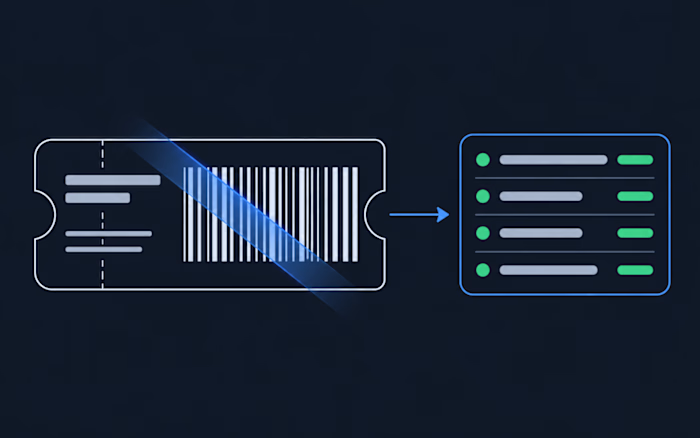
A PDF extraction engine that pulls structured data out of a document in 0.2 seconds, down from 4 minutes, with OCR for scanned files. It reads the real text instead of guessing with ML models, so accuracy is near 100%, and operating cost fell by over 90%.
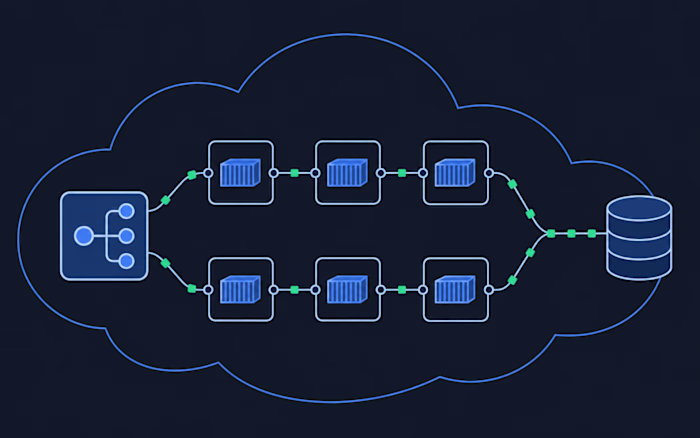
Tables are rebuilt from word bounding boxes, so the client decides how each one is structured. Every failure opens a ticket on its own. It runs on AWS Lambda, S3 and Textract.
Like this project
Posted Oct 20, 2026
A PDF extraction engine that pulls structured data out of a document in 0.2 seconds, down from 4 minutes, with OCR for scans and cost down by over 90%.
Likes
0
Views
0