PDF Text to Excel — A Checkable Sample

Héctor R. Sepúlveda A.


Self-initiated demonstration using fictional notes. This is not prior client work. Production was AI-assisted.
Compare the source PDF and download the editable Excel result:
https://hectorarriolai.github.io/practical-tools-demos/demos/pdf-extraction/
The task: Move text from a selectable-text PDF into an editable workbook while retaining the original wording, punctuation and source order.
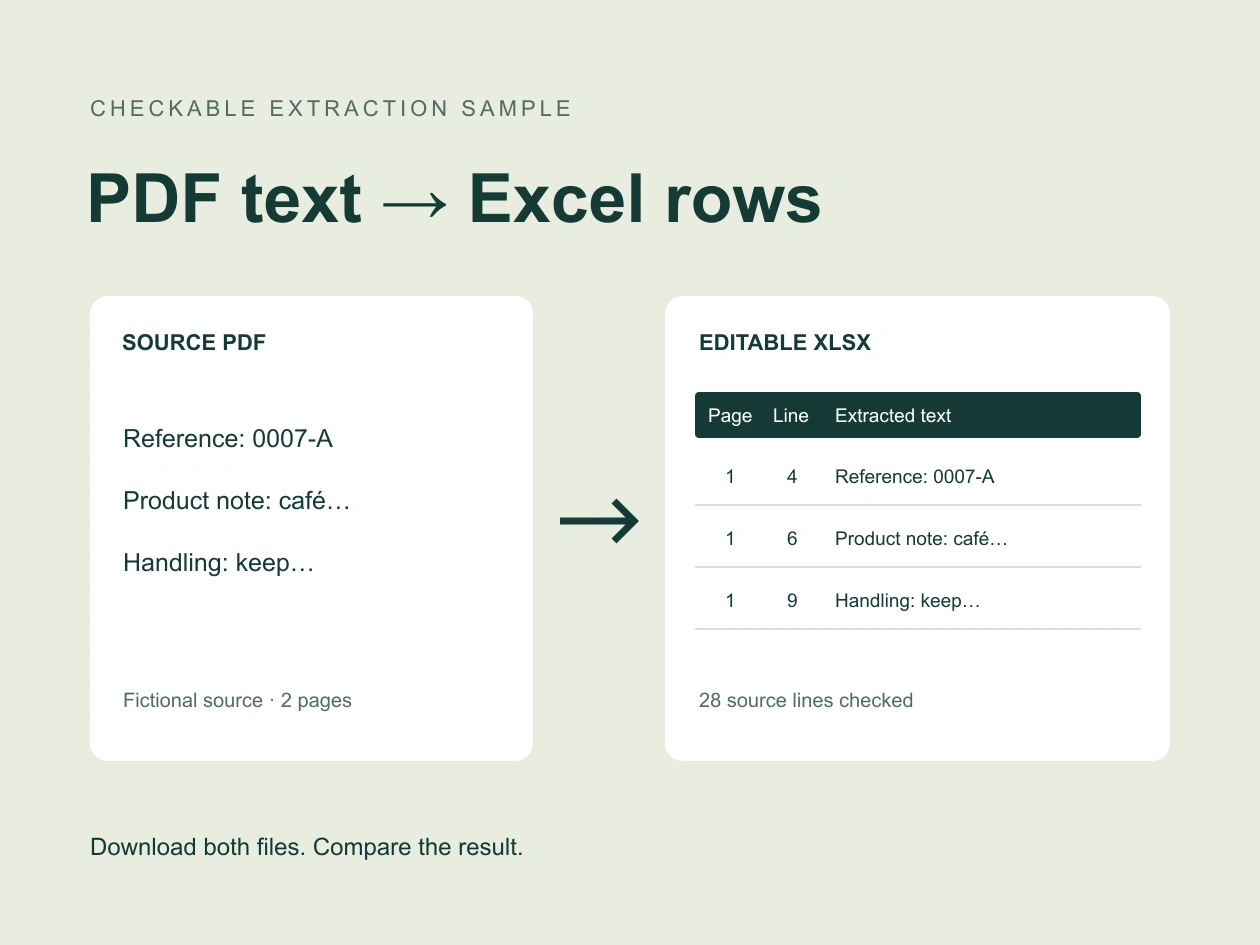
The output: A two-page PDF becomes 28 Excel rows. Each row includes a source page number, a line number and the extracted text. Accented words, quoted phrases and identifiers such as 0007-A remain as written. Dates and measurements stay text; no interpretation or calculation is applied.
The checks: PDF extraction was compared with the known authored source, then every saved Excel row was compared with the extracted text. All 28 lines matched in order. The saved workbook contained no formulas or error cells. Both PDF pages and the complete workbook were also rendered and visually reviewed. A downloadable verification record is included on the demo page.
Scope of this example: This tests one known, single-column PDF with selectable text. Each visible source line becomes one Excel row; blank areas and page styling are not reconstructed. It does not establish accuracy for scans, handwriting, tables, multiple columns or arbitrary documents. No OCR was used.
For a similar project: Share the page count, whether the text is selectable, and the output structure you need. We can review an authorized, anonymized sample on Contra before agreeing on scope, price, data handling and turnaround. English and Spanish available.
Like this project
Posted Sep 19, 2026
Fictional two-page PDF converted to editable Excel: 28 source lines checked, with both files available for comparison and download.
Likes
0
Views
1