Chomper: Document Parsing, Python and MCP

View completed workchomper-demo.vercel.app
Document parsing is only useful if the structure survives.
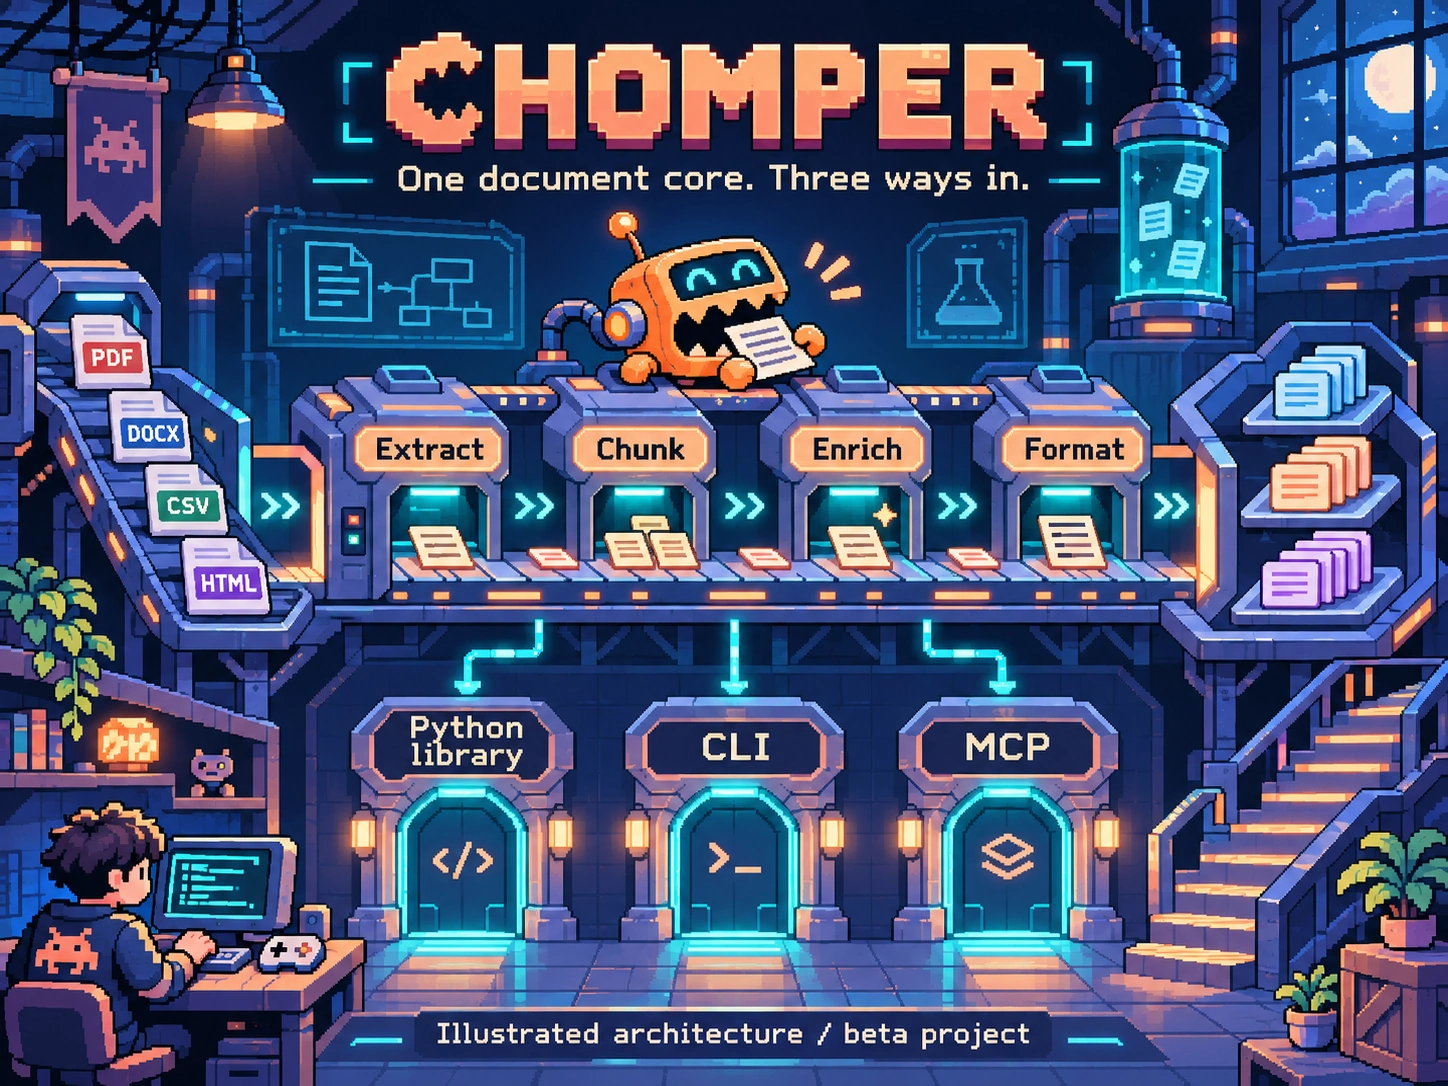
I built Chomper to give a Python application, a command-line script and an AI assistant access to the same document-processing core. It supports 36 file extensions, with optional dependencies controlling which parsers are available.
One pipeline, different ways to use it
The core extracts text and structure, splits it into chunks, adds metadata and formats the result. Each stage can be swapped without rebuilding the rest. The Python library, CLI and MCP server use that same core.
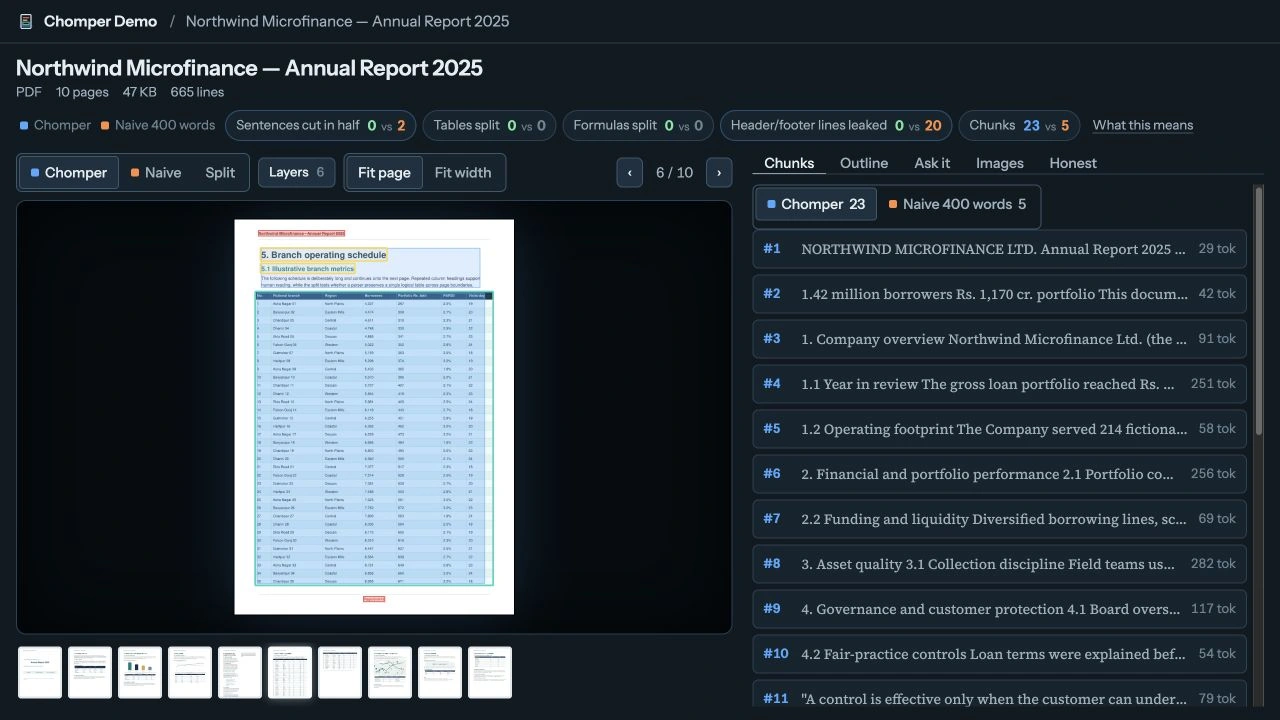
Parsing a document is one part of the problem. Keeping a table together, preserving its header and returning enough context for a useful answer takes more care. The live demo lets you inspect the source pages and the chunks side by side.
What I built
Format-specific extractors, configurable chunking strategies and a shared result model. Optional parsers are loaded only when installed, and semantic chunking loads its embedding model when requested.
The demo includes sample documents so you can see what the parser kept and where it cut the content. The inspector screenshot below uses a fictional sample report, with no client data.
Current status
Chomper is an open-source beta. Parser quality varies by format and document, and I do not treat support for a file extension as a guarantee of perfect extraction. The pixel factory cover is an architecture illustration, not a product screenshot.
0 likes · 0 views · Nov 9, 2026
One document core for 36 file extensions, with Python, CLI and MCP interfaces. A working beta with a live chunk inspector.