Private AI for a SaaS: own models, data stays in-house

Ali Sabir

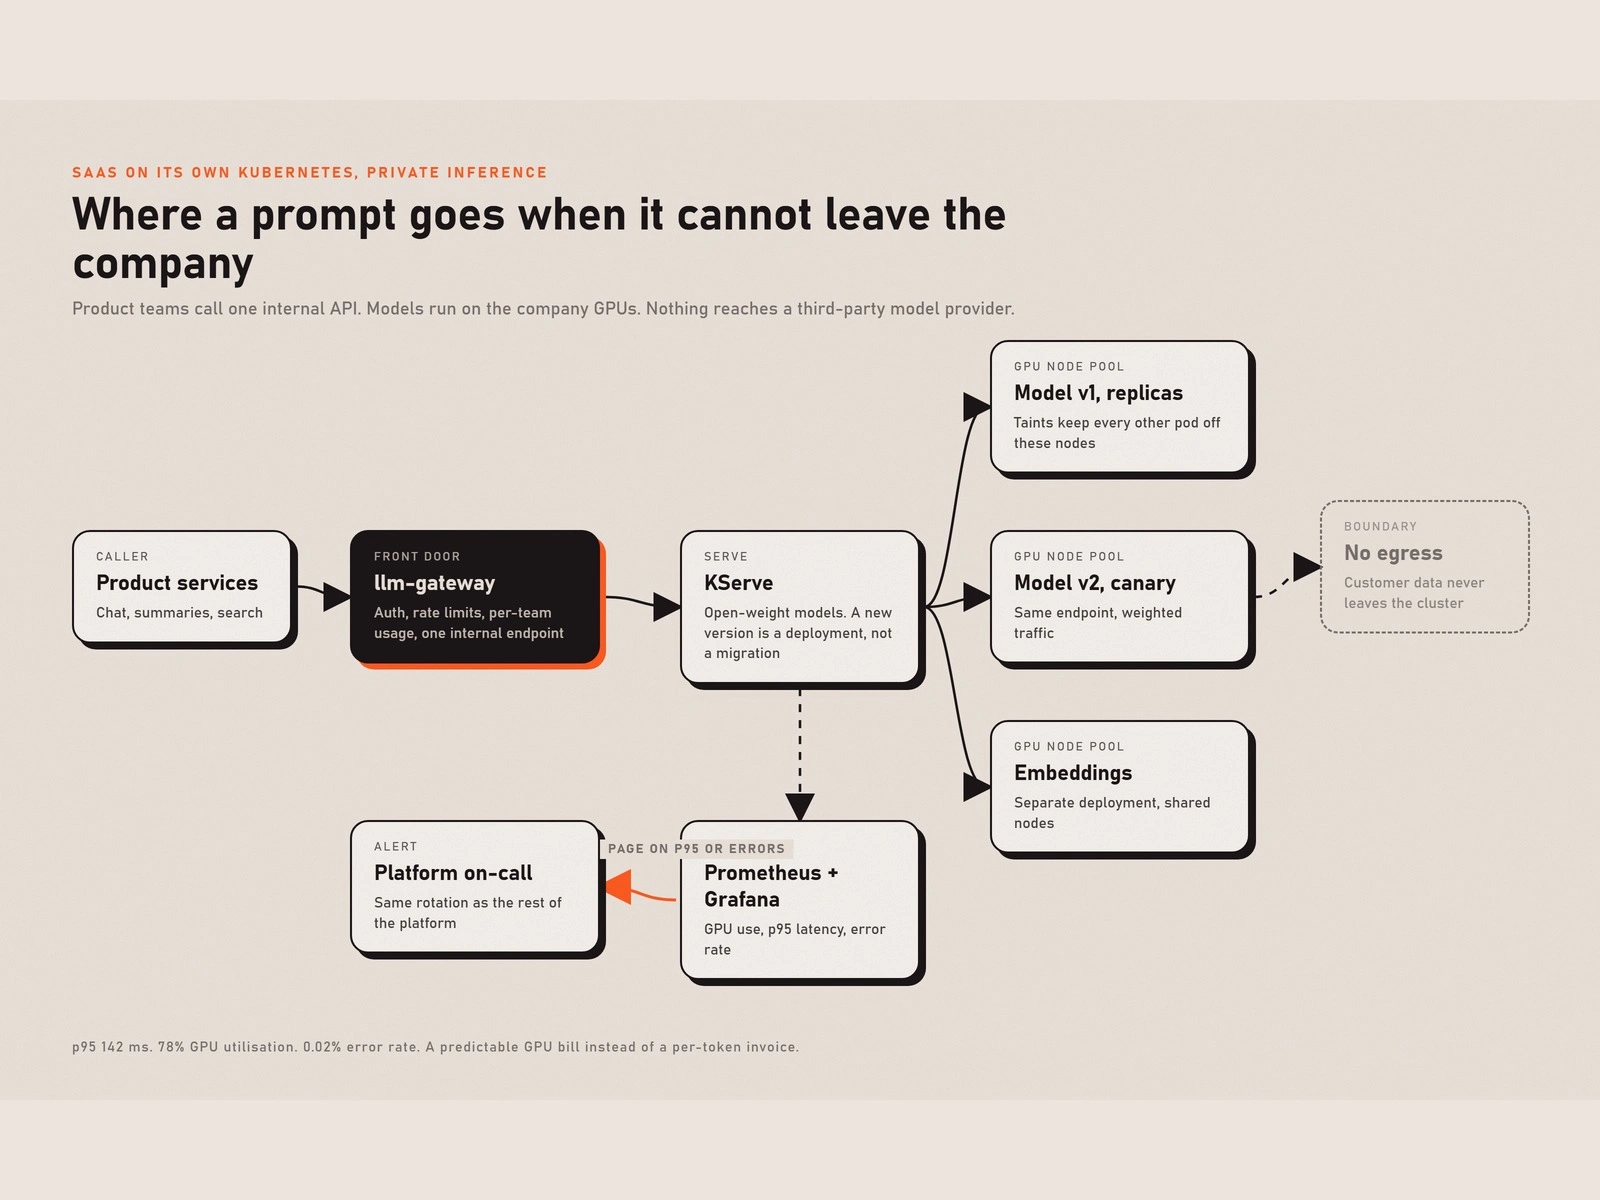
A SaaS wanted AI features in the product but could not send customer data to third-party model APIs. Legal said no, procurement said no, and per-token pricing made the unit economics impossible to forecast.
What I built
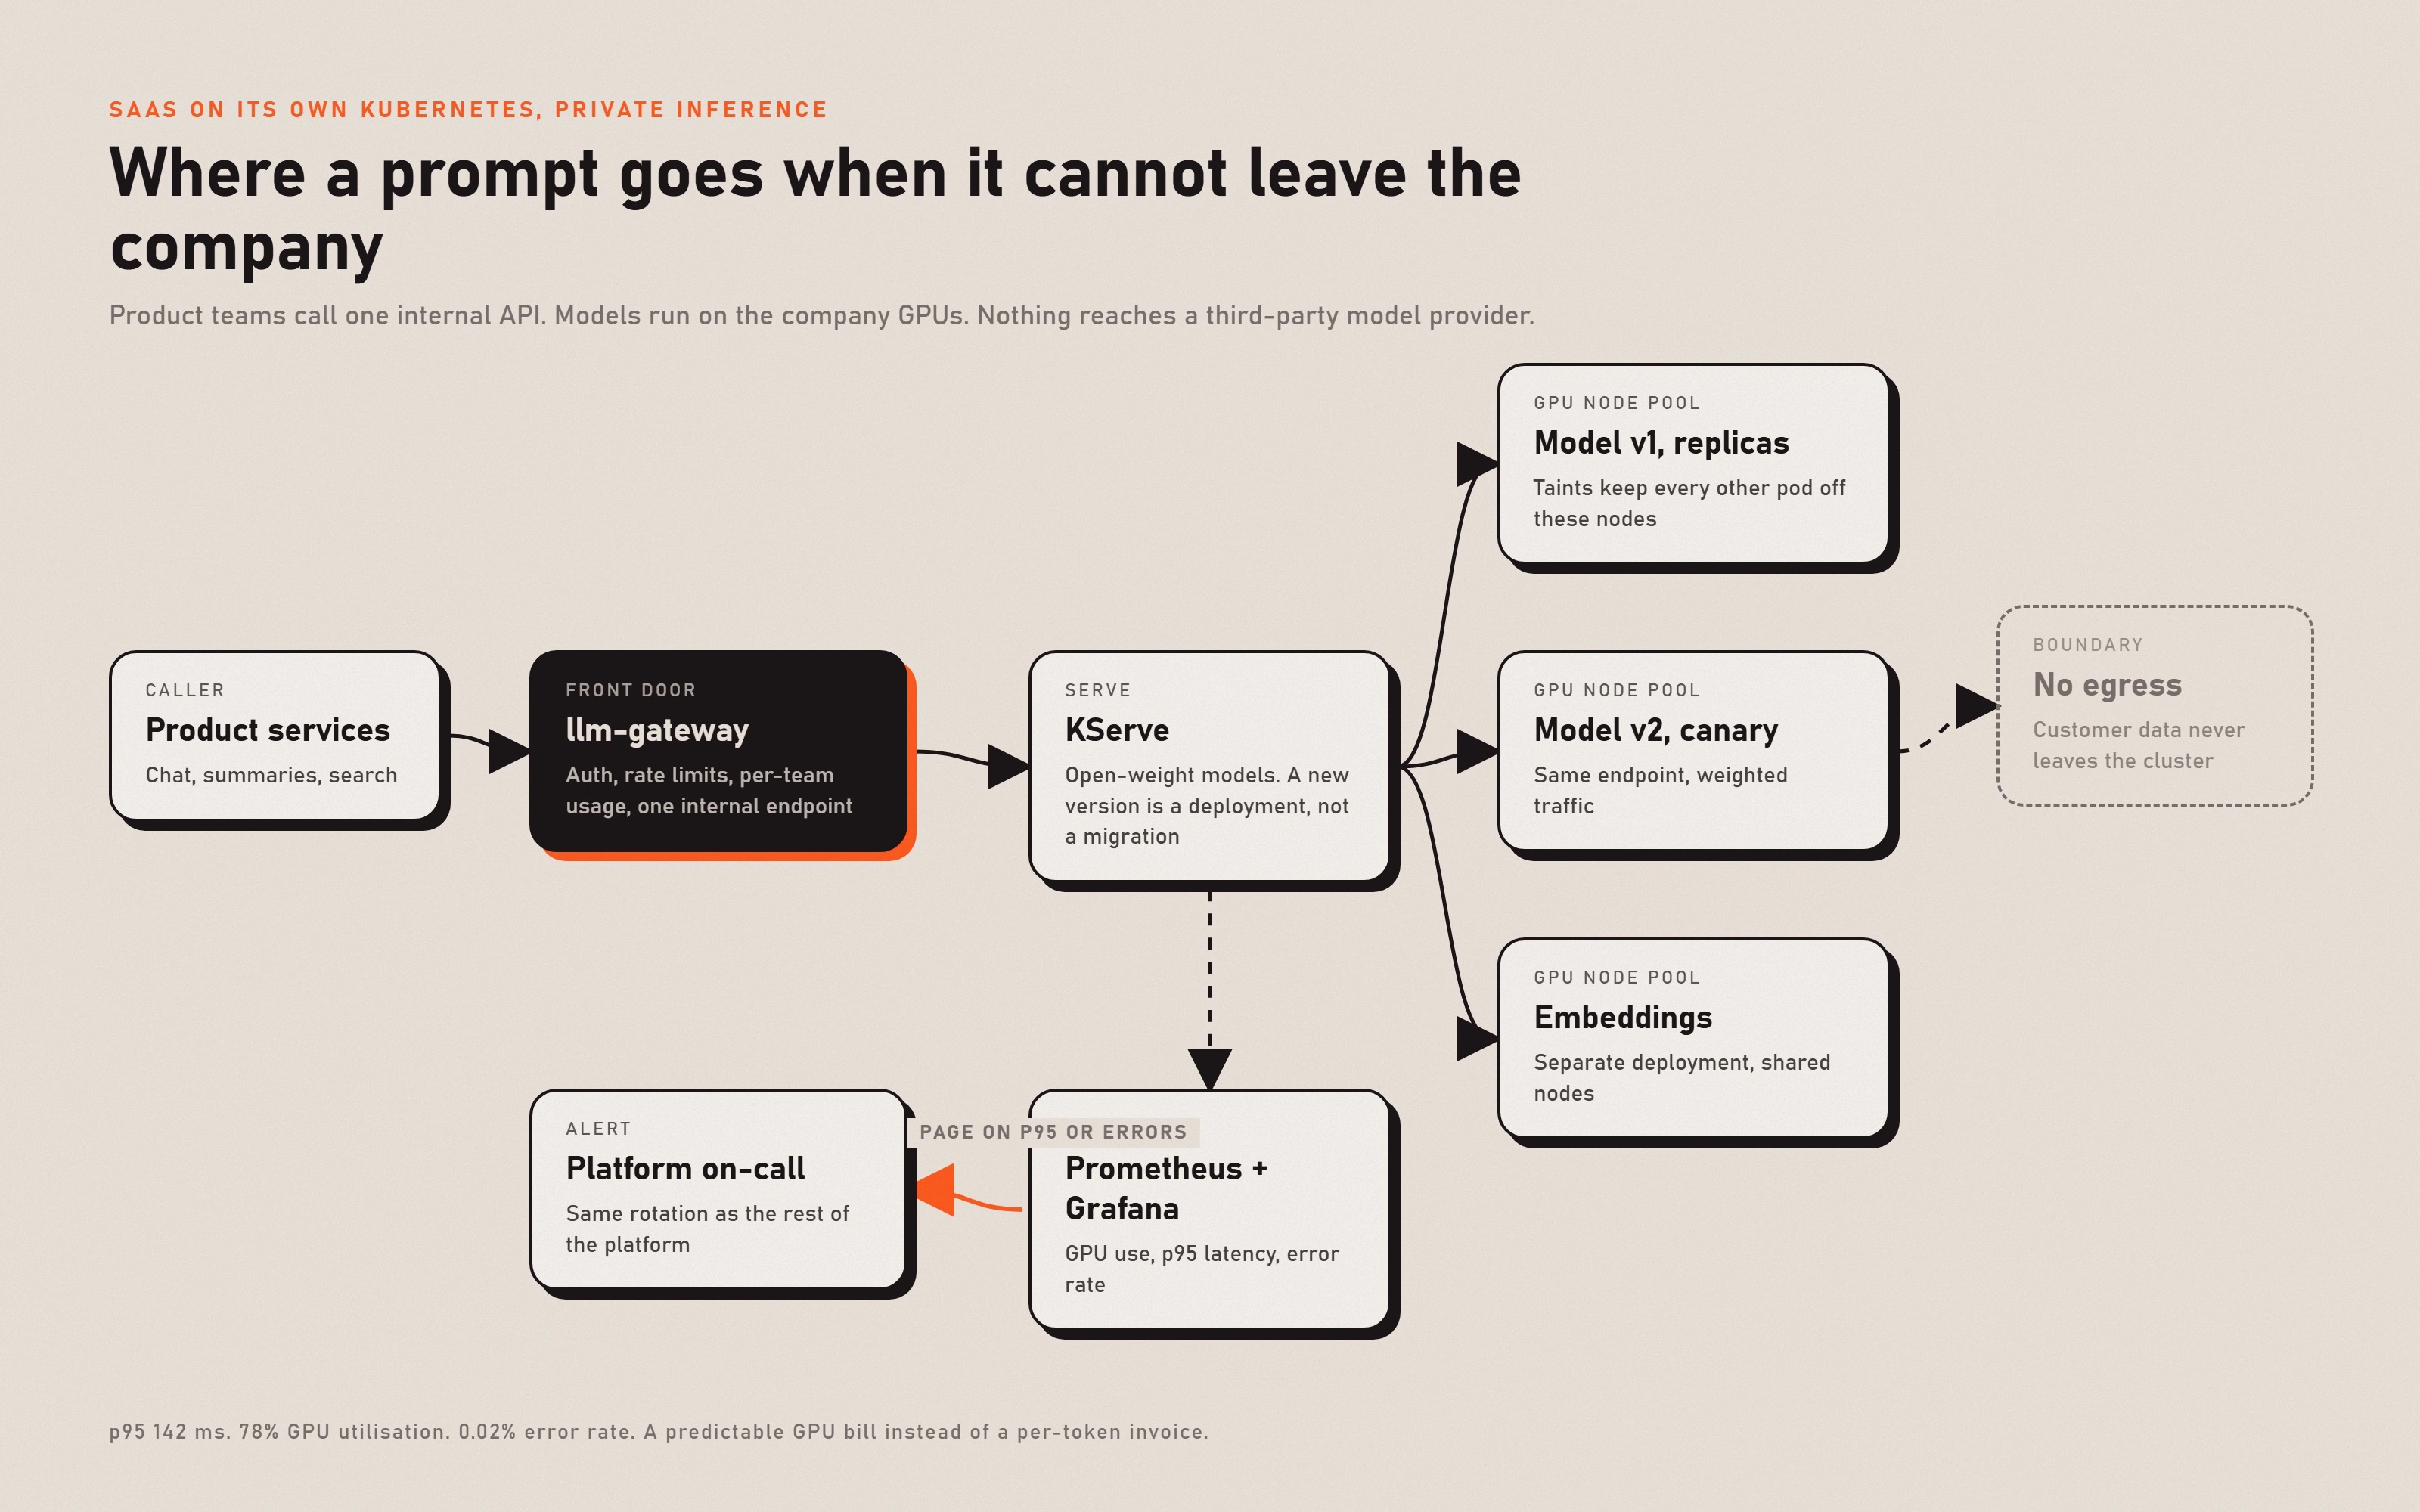
A GPU node pool on the company's own Kubernetes cluster, so inference pods only land on GPU nodes and the rest of the platform is untouched. KServe serving open-weight models behind one internal endpoint, so a new model version is a deployment, not a migration. An llm-gateway in front of it that handles auth, rate limits and per-team usage, so product engineers call one API and never touch the models directly. Dashboards for GPU utilisation, p95 latency and error rate, with alerts on the same on-call rotation as the rest of the platform.
How it fits together
Outcome
p95 latency of 142 ms, 78% GPU utilisation, 0.02% error rate, and no customer data leaving the company. The product team ships AI features against one internal API, and the cost is a predictable GPU bill instead of a per-token invoice.
Stack
Kubernetes, GPU node pool, KServe, llm-gateway, Prometheus, Grafana, Python.
Like this project
Posted Oct 9, 2026
Ran the product's AI on our own GPU cluster instead of third-party APIs: p95 142 ms, 78% GPU use, 0.02% errors, no customer data leaving the company.
Likes
0
Views
6