ai-gateway: one API over OpenAI, Anthropic, Gemini and Ollama

Chaitanya Mhetre


The problem: once a product depends on an LLM provider, every outage, rate limit and price change becomes your problem. Teams end up with provider-specific code scattered everywhere and no single place to see cost.
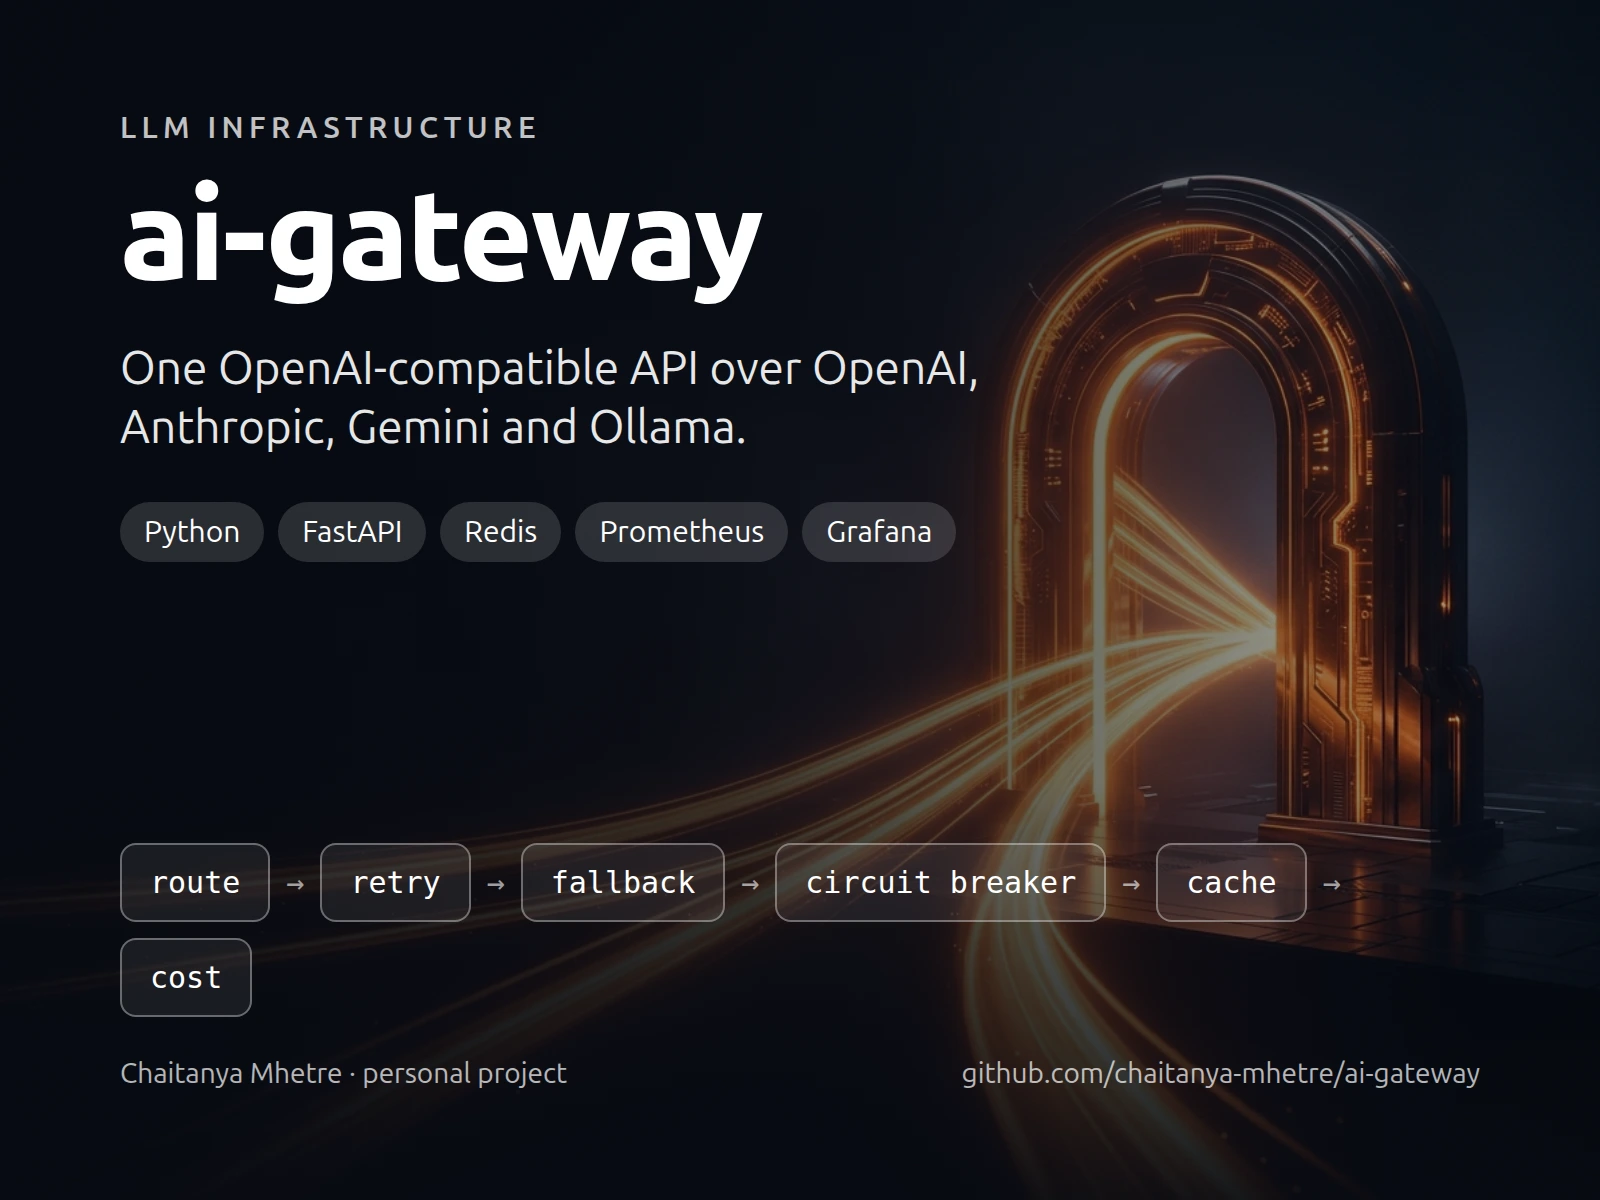
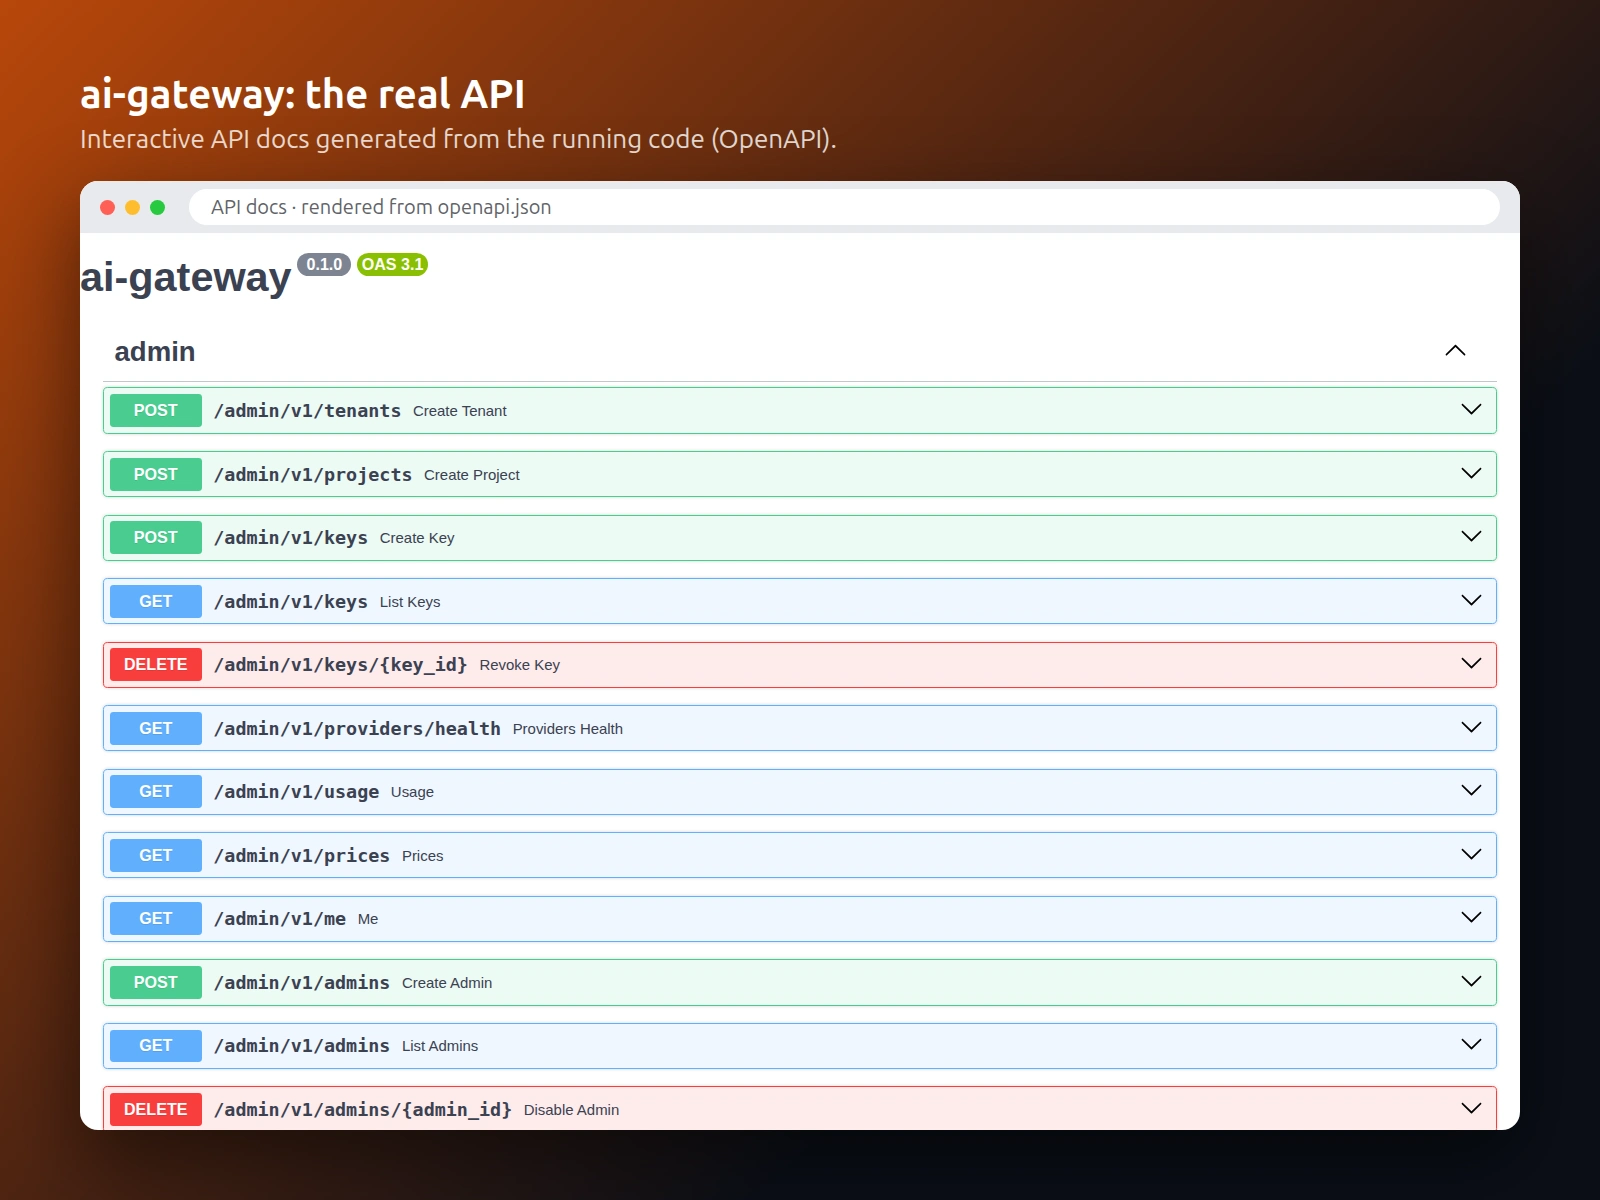
What I built: a self-hosted gateway that speaks the OpenAI API, so existing code only changes its base URL. Behind it sit OpenAI, Anthropic, Google Gemini and local Ollama models, with configurable routing, retries, fallback to another provider, circuit breakers, response caching, API keys, rate limits, per-tenant budgets and token, cost and latency metering.
The bug the benchmark found: I wrote an outage benchmark that hangs one provider on purpose. It showed that a timeout I thought was enforced was not, and every request failed while that provider was stuck. After the fix, the same test showed zero failed requests because traffic moved to the fallback. I wrote this up on my blog at chaitanyamhetre.me.
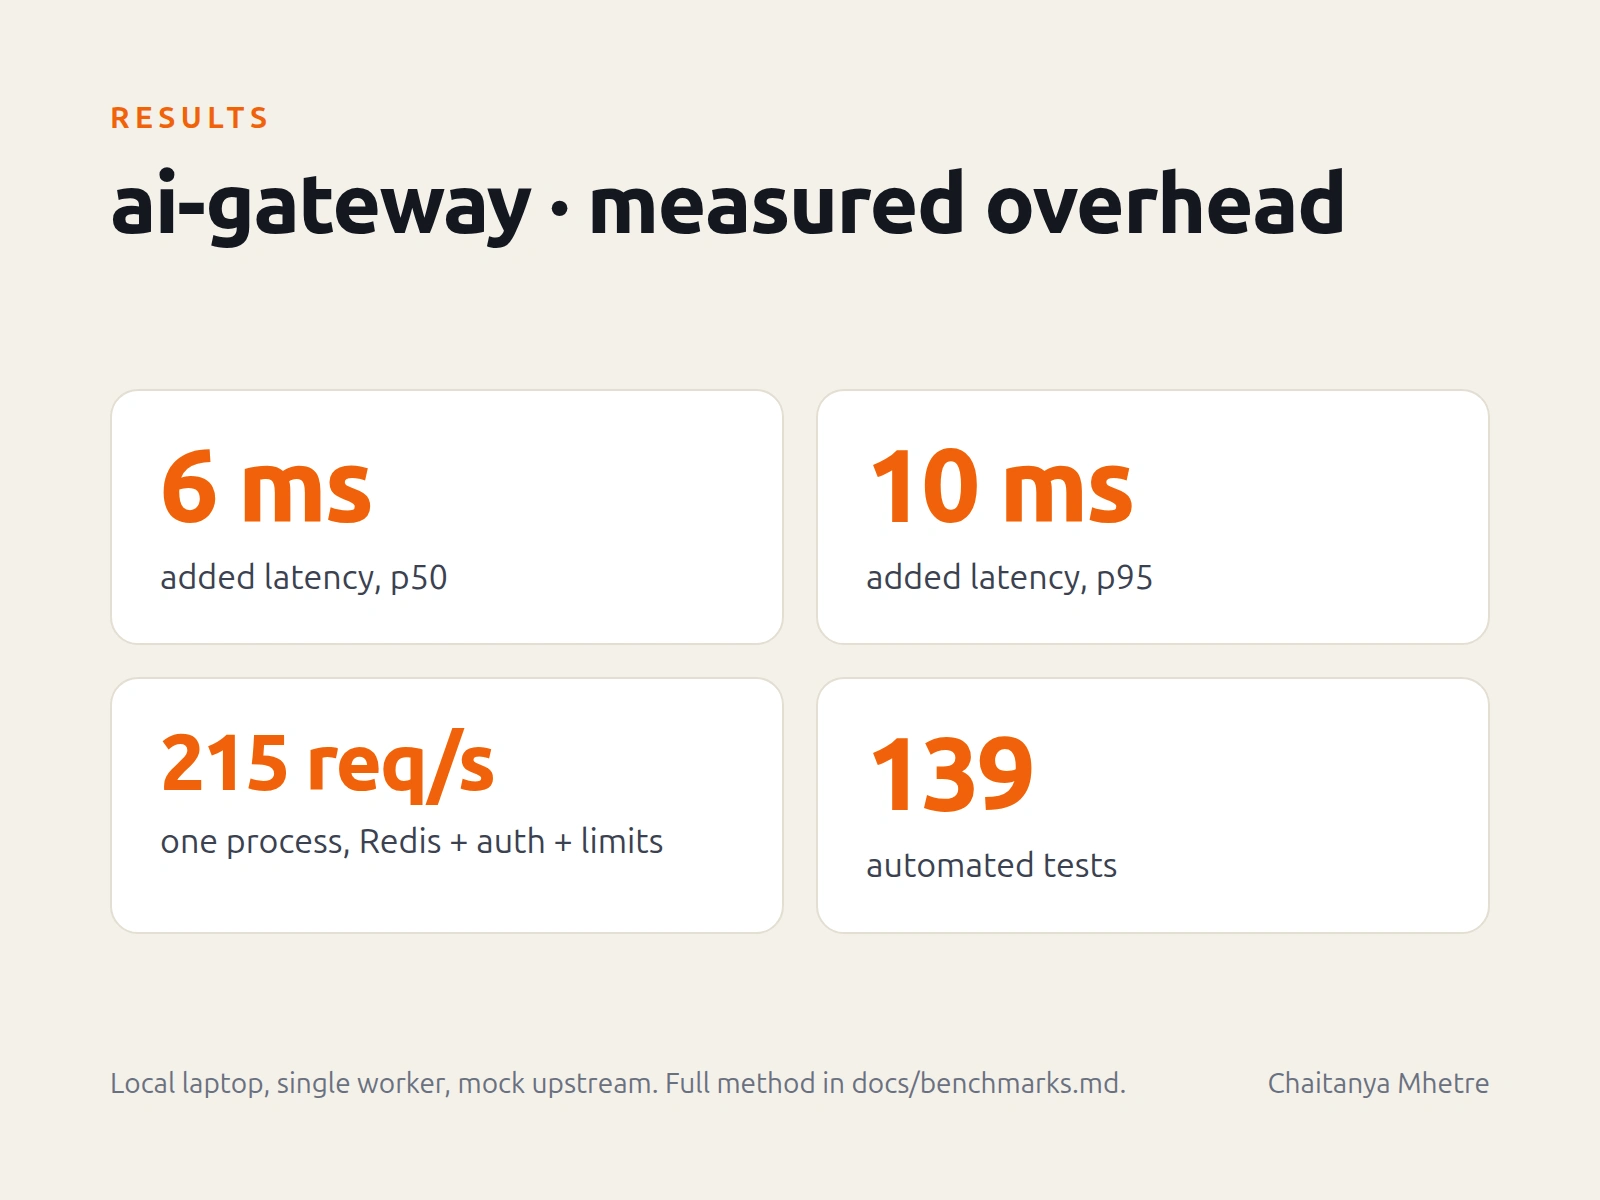
Measured overhead: on a laptop with a single worker, the gateway adds about 6 ms at p50 and 10 ms at p95, and handles about 215 requests per second with Redis, auth and limits switched on.
Details: Python, FastAPI, Redis, Prometheus with 13 metrics, a Grafana dashboard, OpenTelemetry spans without prompt content. 139 automated tests. This is a personal project. Code is on my GitHub: chaitanya-mhetre, repository ai-gateway.
Like this project
Posted Oct 13, 2026
Self-hosted LLM gateway with routing, fallback, circuit breaker, caching, budgets and cost tracking. Personal project.