RAG Engine: document Q&A with measured retrieval quality

Chaitanya Mhetre


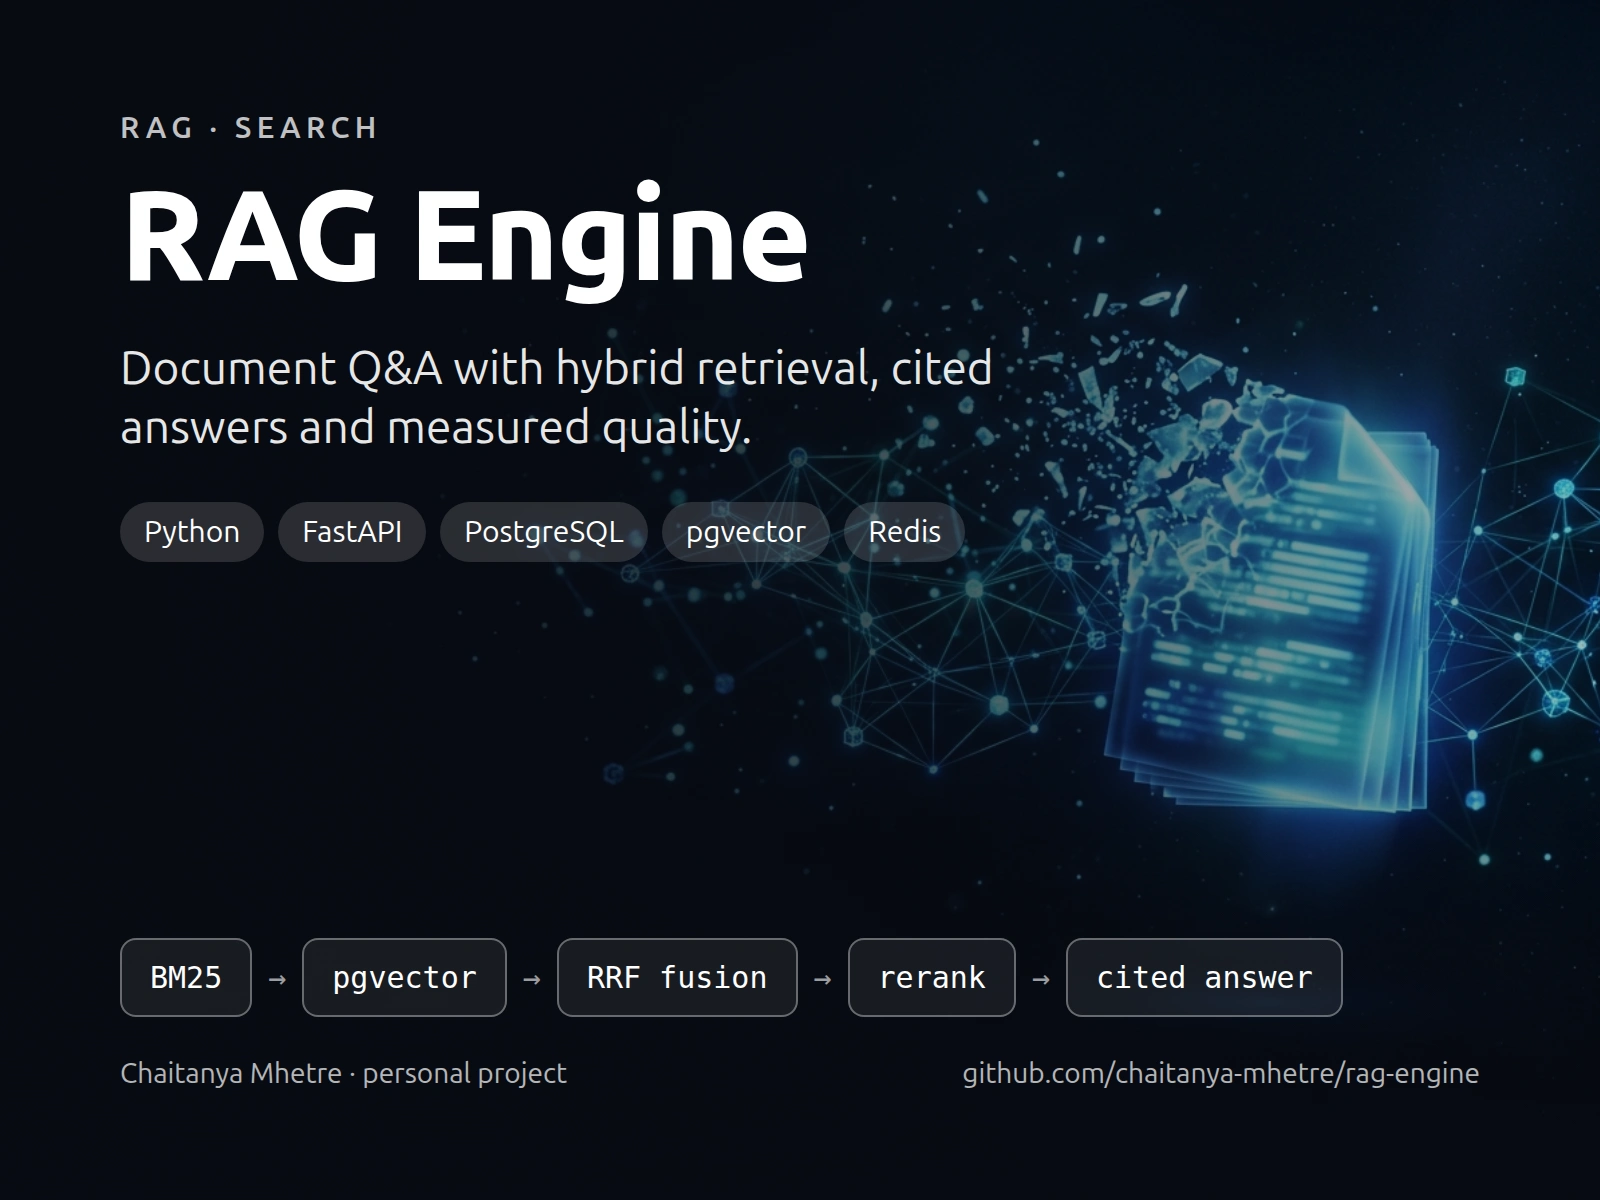
The problem: most RAG demos retrieve with vectors only and never check whether the answers are right. They miss exact terms like product codes and names, and nobody knows when quality drops.
What I built: a multi-tenant document question-answering backend. Documents are parsed and chunked, then searched two ways at once: keyword search with a BM25 implementation I wrote by hand, and vector search with pgvector. The two result lists are fused with Reciprocal Rank Fusion, reranked, and the answer is generated with citations that are validated against the retrieved text.
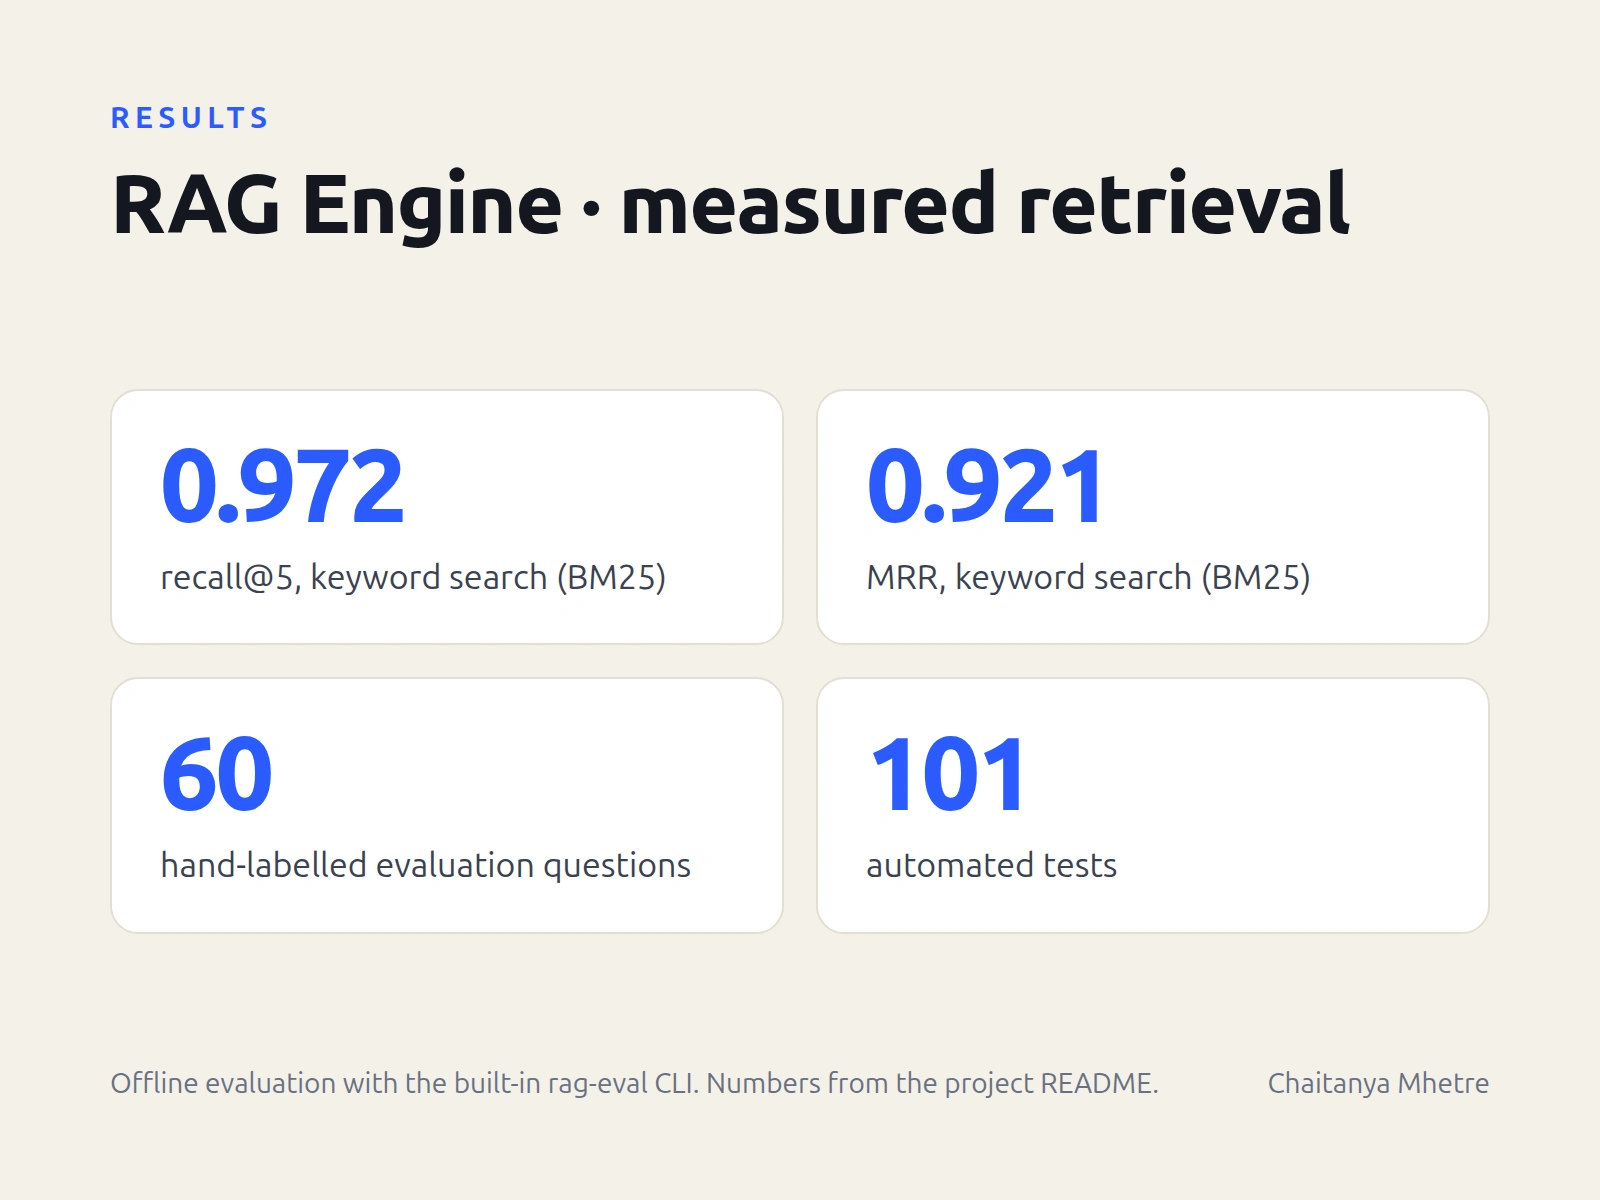
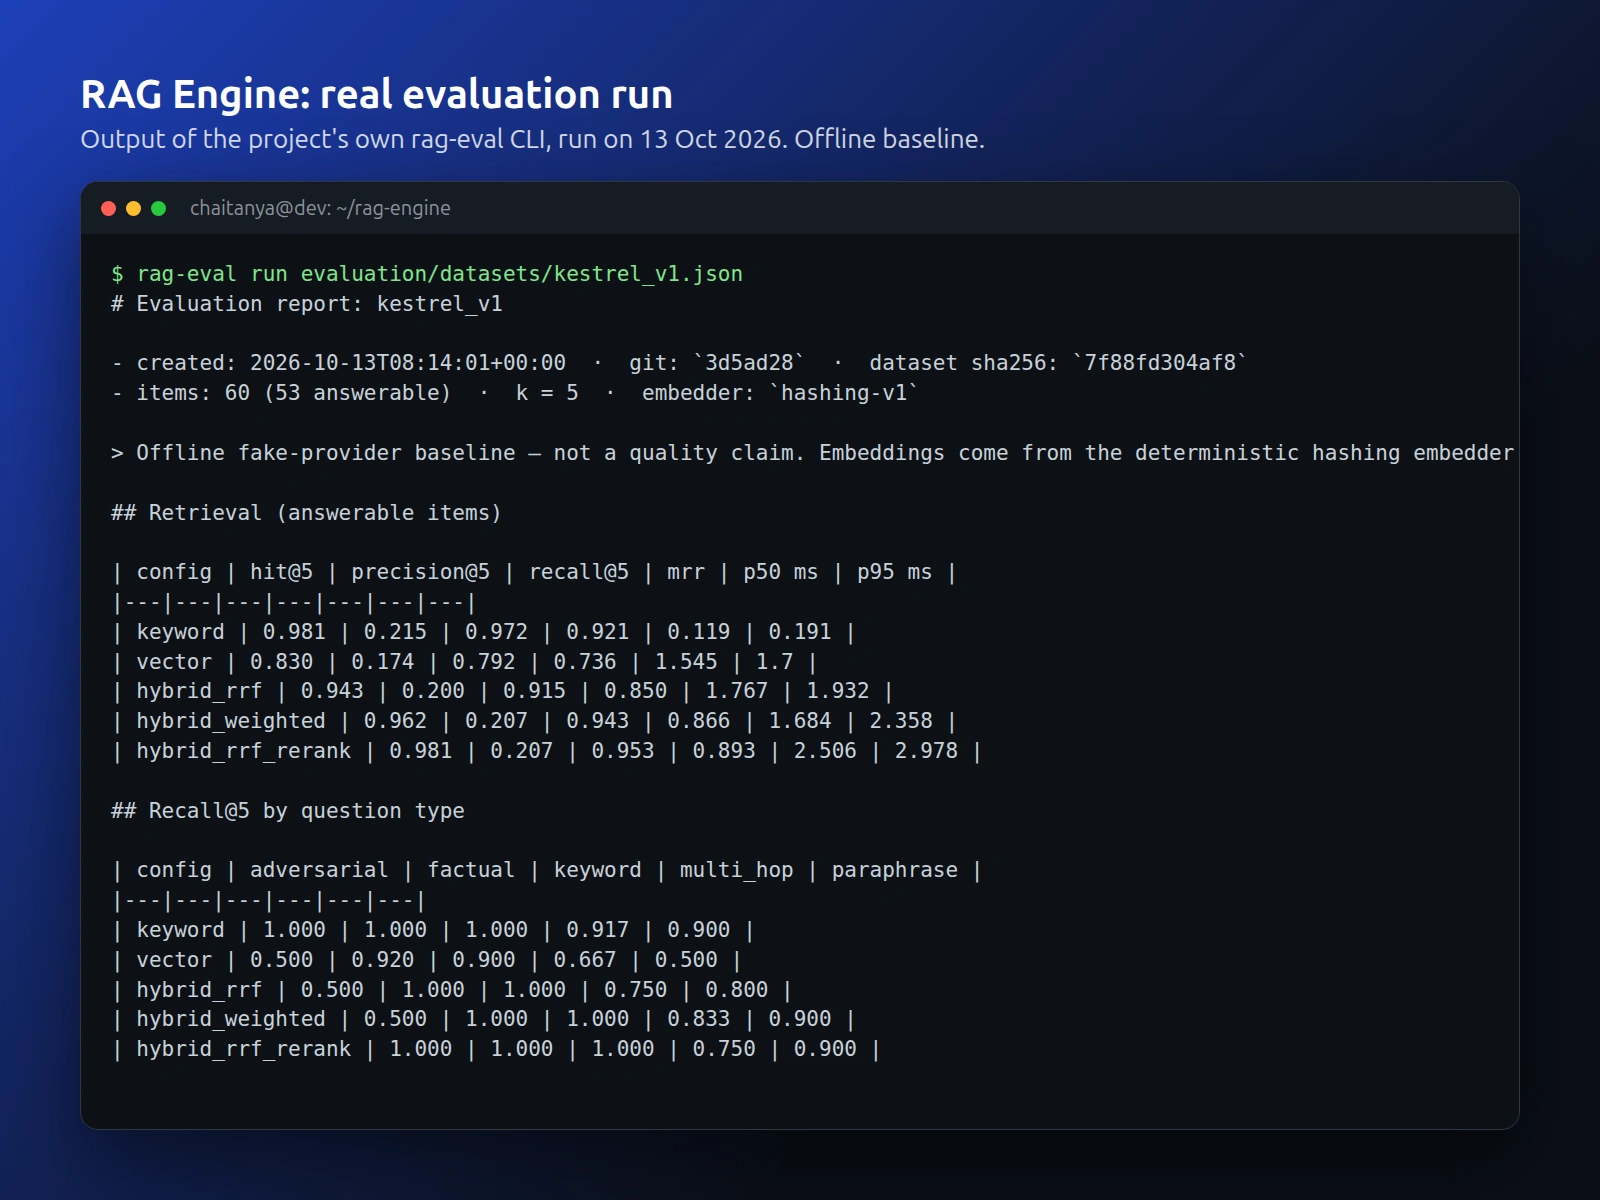
How I know it works: the project ships with rag-eval, a command-line tool that scores retrieval and answers on a 60-question hand-labelled dataset. Keyword search reaches recall at 5 of 0.972 and MRR of 0.921 on that set, and the CI pipeline fails if a change makes the scores worse.
Details: Python, FastAPI, PostgreSQL with pgvector, Redis. Tenant filtering happens before retrieval, so one customer can never see another customer's documents. It runs fully offline with deterministic fake providers for tests, and plugs into OpenAI or Gemini through the same interfaces. 101 automated tests.
This is a personal project, built to learn and to show how I work. Code and full write-up are on my GitHub: chaitanya-mhetre, repository rag-engine.
Like this project
Posted Oct 13, 2026
Hybrid search (hand-written BM25 + pgvector), cited answers, and an evaluation CLI. Personal project.