Ganesh Bandgar
Data Engineer, Data annotation, AI Engineer, AWS, SQL, .py
New to Contra
Ganesh is ready for their next project!


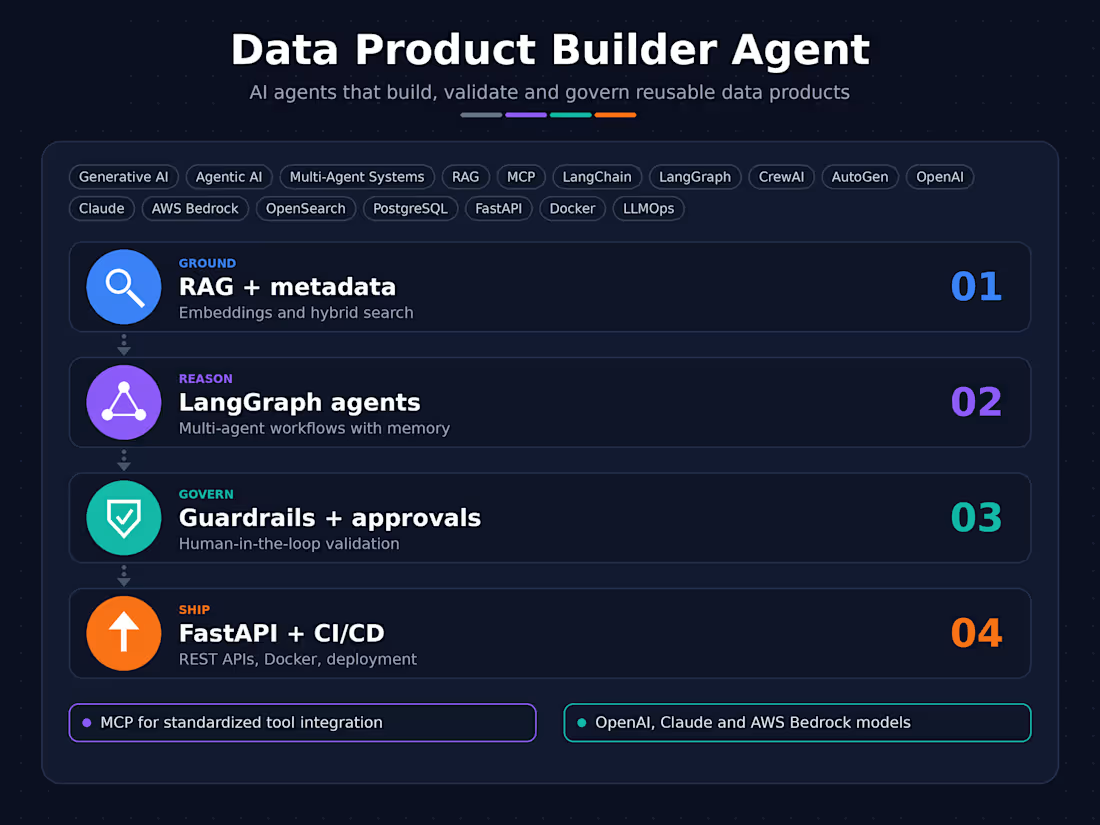
Data Product Builder Agent
Technology & Tools: Generative AI, Agentic AI, AI Agents, Multi-Agent Systems, LLM, RAG, MCP, Vector Databases, Embeddings, Semantic Search, Hybrid Search, LangChain, LangGraph, CrewAI, AutoGen, OpenAI, Claude, AWS Bedrock, Cursor, Python, FastAPI, REST APIs, Docker, Git, GitHub, AWS, S3, Lambda, OpenSearch, PostgreSQL, CI/CD, Prompt Engineering, Context Engineering, Tool Calling, Function Calling, Structured Outputs, Human-in-the-Loop, AI Guardrails, LLMOps
Role: Data Engineer / AI Engineer
• Designed an enterprise-grade AI-powered Data Product Builder Agent to accelerate creation, validation, documentation, governance, and management of reusable data products.
• Implemented Agentic AI and Multi-Agent Systems with specialized agents for metadata discovery, schema analysis, transformation, validation, documentation, orchestration, and deployment.
• Built stateful LLM workflows using LangChain and LangGraph for reasoning, tool calling, structured outputs, agent memory, error handling, and Human-in-the-Loop approvals.
• Implemented RAG using embeddings, Vector Databases, semantic search, hybrid search, and knowledge bases to ground LLM responses in enterprise data and metadata.
• Integrated MCP for standardized context and tool integration and used CrewAI and AutoGen patterns for multi-agent collaboration and task delegation.
• Integrated OpenAI, Claude, and AWS Bedrock for model flexibility, prompt/context engineering, evaluation, guardrails, and LLMOps.
• Developed Python and FastAPI REST APIs and integrated S3, Lambda, OpenSearch, and PostgreSQL for data, metadata, retrieval, and application workflows.
• Used Cursor, Git, GitHub, Docker, and CI/CD for AI-assisted development, version control, containerization, testing, and deployment
1
1
27
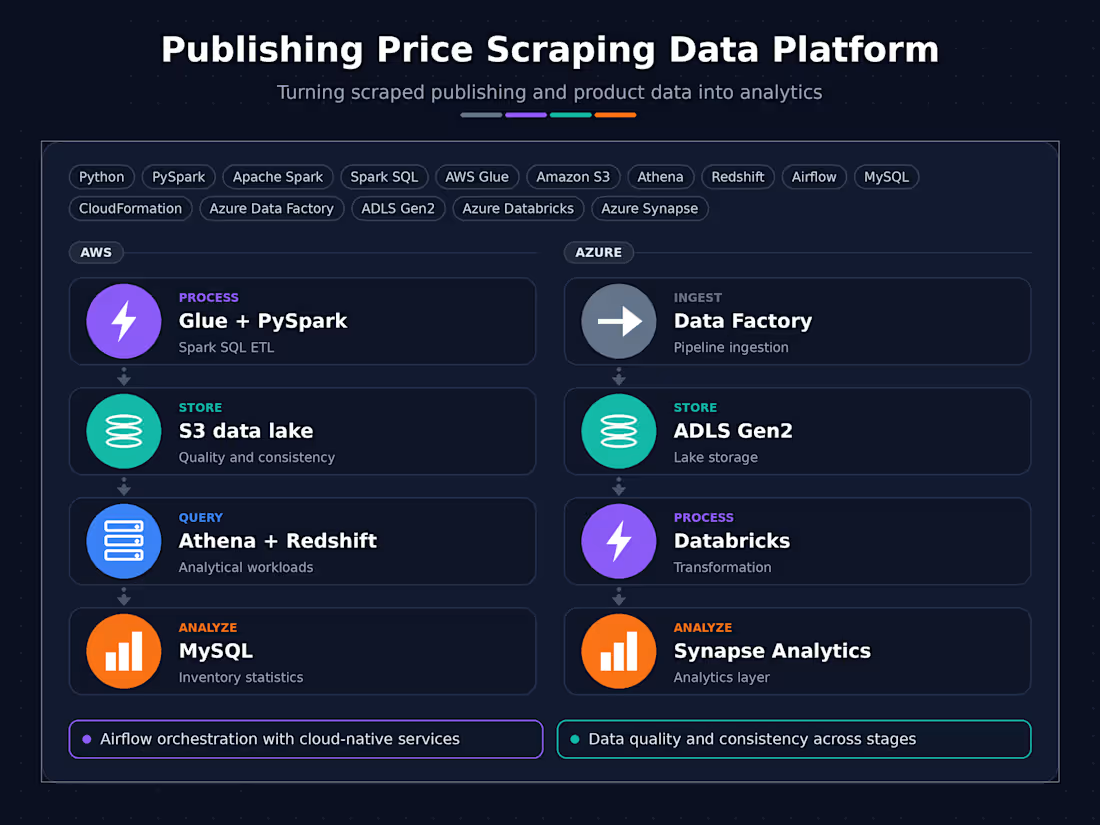
Publishing Price Scraping Data Platform
Technology & Tools: Python, AWS Glue, Amazon S3, Athena, CloudFormation, Apache Spark,
Spark SQL, Azure, Azure Data Factory, ADLS Gen2, Azure Databricks, Azure Synapse Analytics,
Airflow, Amazon Redshift, PySpark, MySQL
Role: Data Engineer
• Developed ETL processes using AWS Glue, PySpark, Apache Spark, and Spark SQL for
large-scale publishing and product data processing.
• Managed Data Lake storage in S3 and analytical workloads in Athena and Redshift,
ensuring data quality and consistency across pipeline stages.
• Implemented orchestration using Apache Airflow and cloud-native services and
optimized transformations for distributed data processing.
• Worked with MySQL and performed statistical analysis on inventory and product data.
• Used Azure Data Factory, ADLS Gen2, Azure Databricks, and Azure Synapse Analytics
for ingestion, storage, processing, transformation, and analytics.
0
19
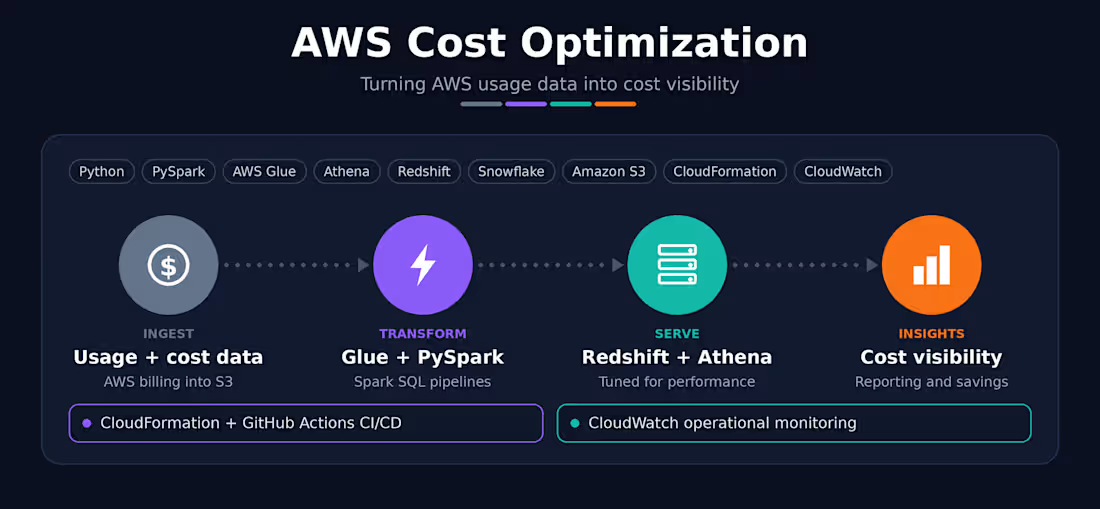
AWS Cost Optimization
Technology & Tools: Python, AWS Glue, Amazon Redshift, Snowflake, Amazon S3, Athena,
CloudFormation, PySpark, Spark SQL, CloudWatch, AWS Cost Optimization
Role: Data Engineer
• Built pipelines to process and analyze AWS usage and cost data using Glue, PySpark, S3,
Athena, Redshift, and Snowflake.
• Designed Data Lake and Data Warehouse workflows for cost visibility, reporting,
performance analysis, and cloud cost optimization.
• Applied Redshift optimization concepts including query tuning, distribution and sort
strategies, workload management, storage optimization, and Serverless vs. provisioned
workload considerations.
• Implemented scalable partitioning and query patterns and supported operational
monitoring using Amazon CloudWatch.
• Used AWS CloudFormation and GitHub Actions for repeatable infrastructure
provisioning and CI/CD-based deployments.
0
21
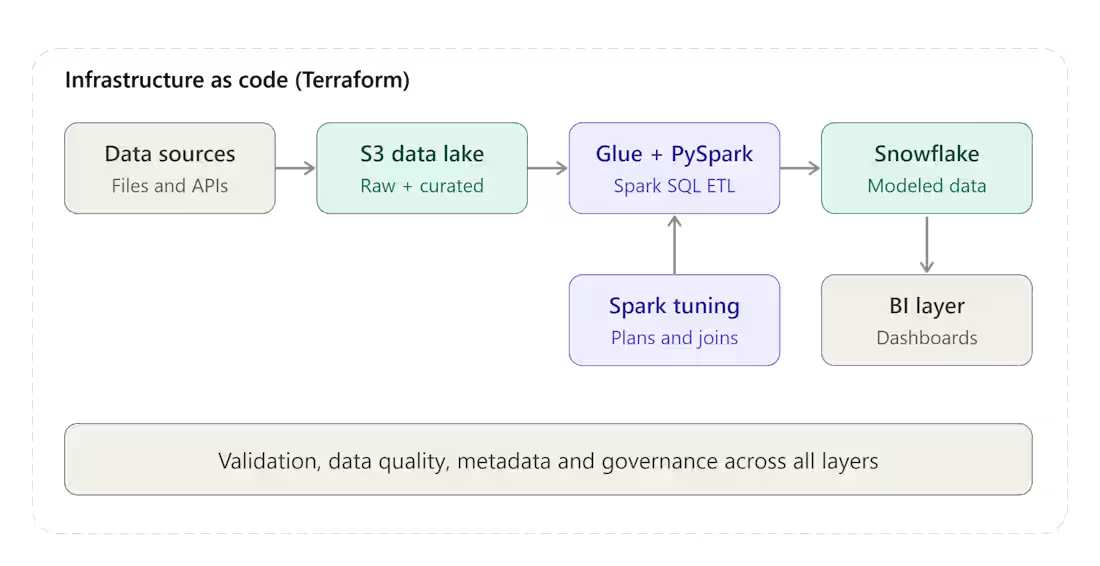
Enterprise Data Platform
Technology & Tools: Python, Java, SQL, PySpark, Apache Spark, Spark SQL, AWS, Amazon S3,
AWS Glue, PostgreSQL, Snowflake, BI, Terraform, ETL, ELT, Data Lake, Data Warehouse, Data
Lakehouse
Role: Data Engineer
• Designed scalable end-to-end ETL/ELT pipelines and batch data processing workflows
using Python, PySpark, Spark SQL, AWS, and Snowflake.
• Defined ingestion, transformation, validation, data flow, and data modeling patterns
for an enterprise Data Lake, Data Warehouse, and Data Lakehouse platform.
• Reviewed Spark execution plans and optimized transformations, joins, aggregations,
partitioning, and processing performance for distributed workloads.
• Used Terraform for Infrastructure-as-Code and collaborated across engineering,
product, and business teams to deliver scalable data solutions.
• Wrote and optimized Advanced SQL queries and supported data quality, reliability,
consistency, metadata, and governance requirements.
0
29