The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

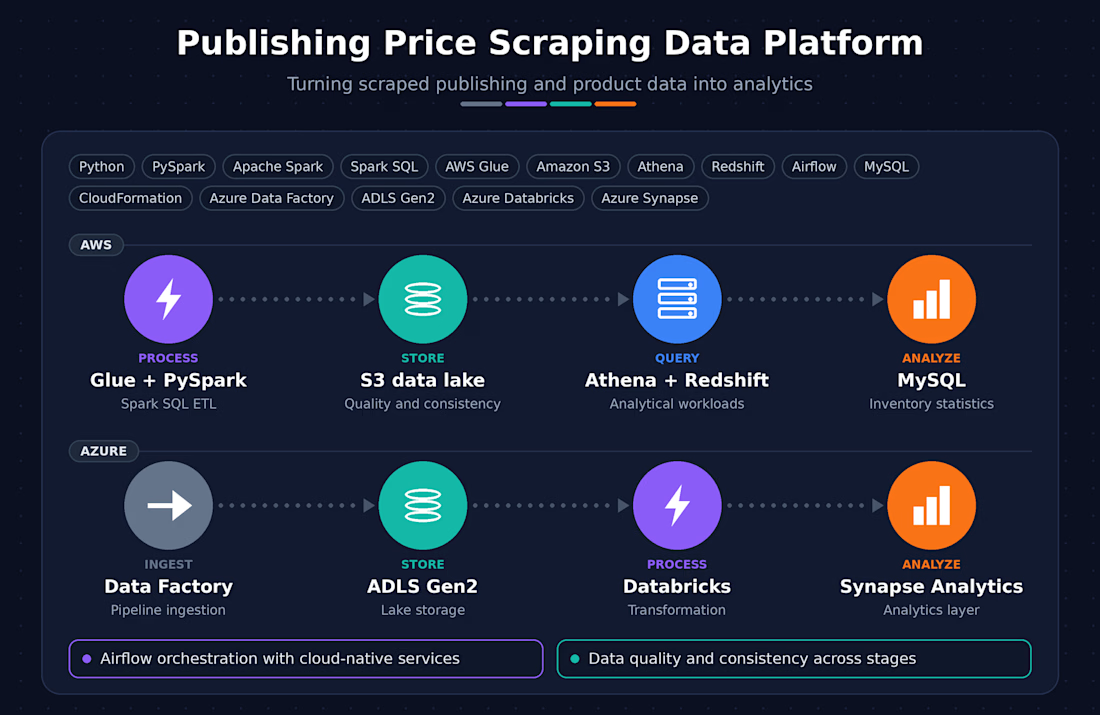
Publishing Price Scraping Data Platform
Technology & Tools: Python, AWS Glue, Amazon S3, Athena, CloudFormation, Apache Spark,
Spark SQL, Azure, Azure Data Factory, ADLS Gen2, Azure Databricks, Azure Synapse Analytics,
Airflow, Amazon Redshift, PySpark, MySQL
Role: Data Engineer
• Developed ETL processes using AWS Glue, PySpark, Apache Spark, and Spark SQL for
large-scale publishing and product data processing.
• Managed Data Lake storage in S3 and analytical workloads in Athena and Redshift,
ensuring data quality and consistency across pipeline stages.
• Implemented orchestration using Apache Airflow and cloud-native services and
optimized transformations for distributed data processing.
• Worked with MySQL and performed statistical analysis on inventory and product data.
• Used Azure Data Factory, ADLS Gen2, Azure Databricks, and Azure Synapse Analytics
for ingestion, storage, processing, transformation, and analytics.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts


Messy Data In. Clearer Decisions Out. 📊
Over the past year, I've noticed most businesses don't struggle because they lack data — they struggle because that data never turns into a decision.
That's the gap I work in:
→ Cleaning and analyze data with Python & R
→ Turning findings into investor-ready pitch decks
→ Polishing the final write-up so nothing gets lost in translation
If your team has data sitting in spreadsheets with no story attached, or a pitch deck that needs to actually land — that's exactly where I can help.
Open to projects. Let's talk 👇




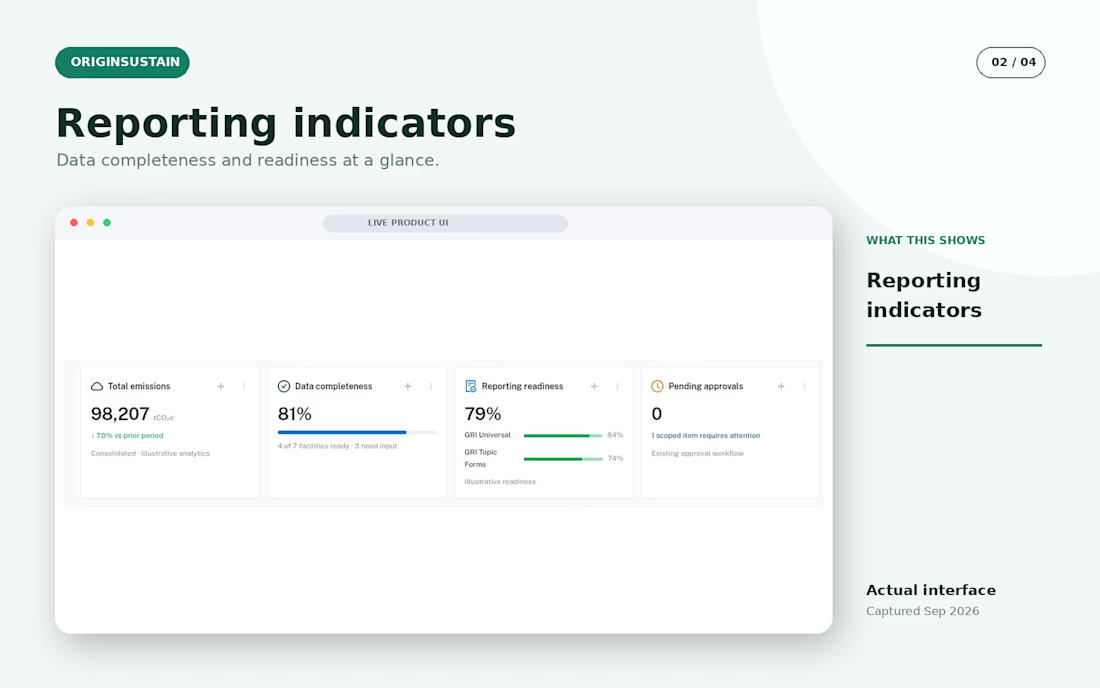
ESG reporting is a workflow problem as much as a data problem: teams need applicability rules, evidence, consolidation, review, and approvals before a report is ready.
For OriginSustain, I built NestJS/TypeScript backend services, PostgreSQL and Redis/BullMQ processing, and AWS/Docker delivery with CI/CD. OpenAI API and RAG support part of the reporting flow. The screens here are from the product’s illustrative command center; the numbers are demo values, not client outcomes.
The full backend case study: https://contra.com/p/WvNXbmQR-origin-sustain-or-multi-tenant-esg-reporting-backend



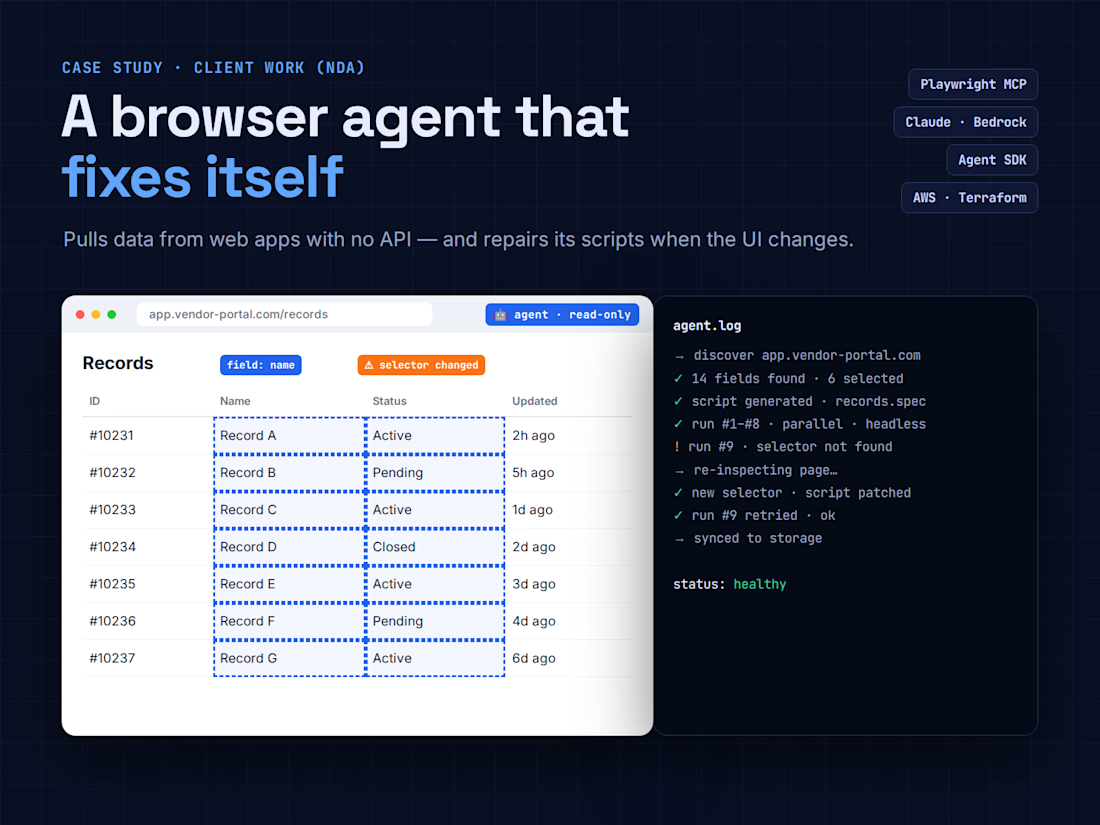
Hand-written scrapers break every time a vendor changes its UI. So I'm building an AI browser agent that learns a new web app, writes its own Playwright scripts, runs them in parallel, and repairs them itself when a selector breaks. Read-only by design, API-first, human review for critical changes. Claude on Bedrock + Playwright MCP + AWS.