
Data Scientist
Hi Contra , a big part of my work is building ML projects end to end, from exploration to deployment.
I work across the full lifecycle:
• 🔍 EDA & data validation on large, messy datasets
• 🧩 Feature engineering with PySpark driven by business logic
• 🧠 Model training & evaluation (time-series & ML)
• 🚀 Production pipelines & deployment
On the engineering side, I focus on making ML reliable and scalable:
• PySpark pipelines for feature engineering, batch training & inference
• MLflow for experiment tracking, model versioning & reproducibility
I enjoy working with teams that care about clean ML systems, not just experiments , especially when models need to be trusted and reused.
👉 If you’re looking for someone to build ML pipelines end to end , from data exploration to production
I’m open to contract or freelance work.
0
318
👋 Hi Contra — I’m Lilya, a Data Scientist working at the intersection of retail, demand forecasting, and promotion analytics.
My recent work focuses on SKU-level forecasting, where small modeling choices have a big business impact:
• 📦 Improving SKU-level demand forecasts for planning & inventory
• 📊 Approximating the pull-forward effect of promotions
On the technical side, I work end-to-end:
• Time-series & ML forecasting
• Promo, price & calendar feature engineering
• PySpark batch pipelines & MLflow tracking
💡 Open to freelance or contract projects around demand planning, retail analytics.
Happy to connect 🚀
0
347
🧠 Hi Contra, alongside retail forecasting, I’ve worked on applied NLP and computer vision projects that go beyond experiments and turn into real solutions.
I’ve built:
• Review rating prediction with BERT
• Text summarization using FLAN-T5
• Sign language classification
• Fruit disease detection with Fast R-CNN
• A neural-network chess move predictor
What I enjoy most is shaping messy data, choosing the right models, and evaluating solutions realistically.
👉 If you’re building NLP or computer vision products and need someone hands-on, I’d love to connect.
2
1
335
🤖 Hi another side of my work is building LLM-powered systems that actually ship.
I’ve worked on chatbots and AI assistants from research to production, focusing on usefulness and reliability:
• Designing LLM-based recommenders using LangChain & FAISS
• Fine-tuning transformer models (BERT, T5 / FLAN-T5) for real NLP tasks
• Testing, debugging, and improving chatbot behavior based on user feedback
⚙️ Tech I often use: PyTorch, Hugging Face, LangChain, vector search, MLflow
💡 Open to freelance or contract work where teams need:
• LLM integration or fine-tuning
• Chatbots or AI assistants that deliver real value
• Practical NLP solutions, not demos
Happy to connect with teams building AI-driven products 🚀
0
270


AI • Data engineering • Backend


Full stack developer, AWS, GCP, Real time analytics.
Full stack developer, AWS, GCP, Real time analytics.


View more →

Optimising businesses with data and business intelligence.
- 18
- Followers
Optimising businesses with data and business intelligence.


AI Engineer | Agentic Systems & Automation | MLOps

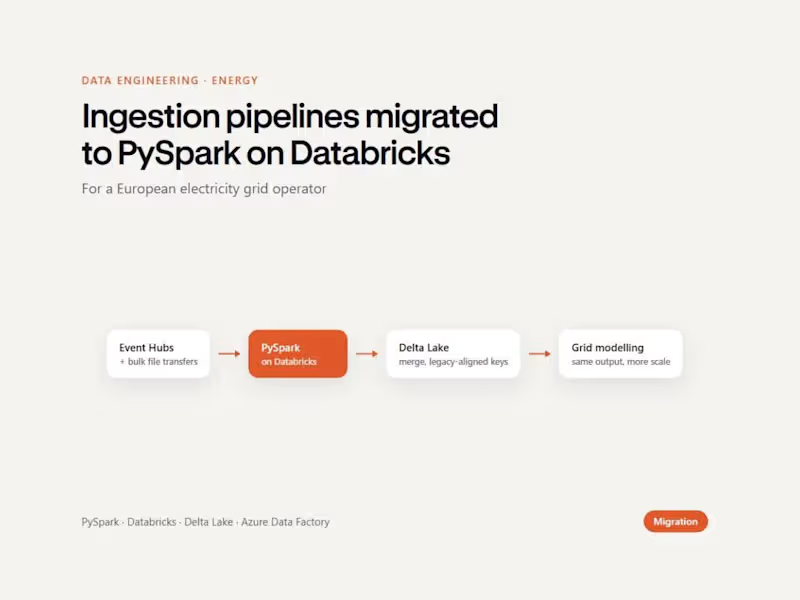
I engineered a large-scale package-network intelligence pipeline using Azure Databricks and PySpark. The system joined approximately 4.5 billion historical records and transformed them into reusable fingerprint signals covering package movement and network behavior.
I developed time-windowed feature logic using native Spark expressions rather than Python UDFs, preserving distributed performance at scale. The pipeline produced an approximately 200-million-row fingerprint dataset and a 22-million-row operational output that classified package activity along a cold-to-hot temperature scale.
The resulting signals supported downstream monitoring, prioritization, and operational analysis. The architecture shown here is a sanitized representation; client identifiers, proprietary schemas, infrastructure paths, and business rules have been removed.
1
304
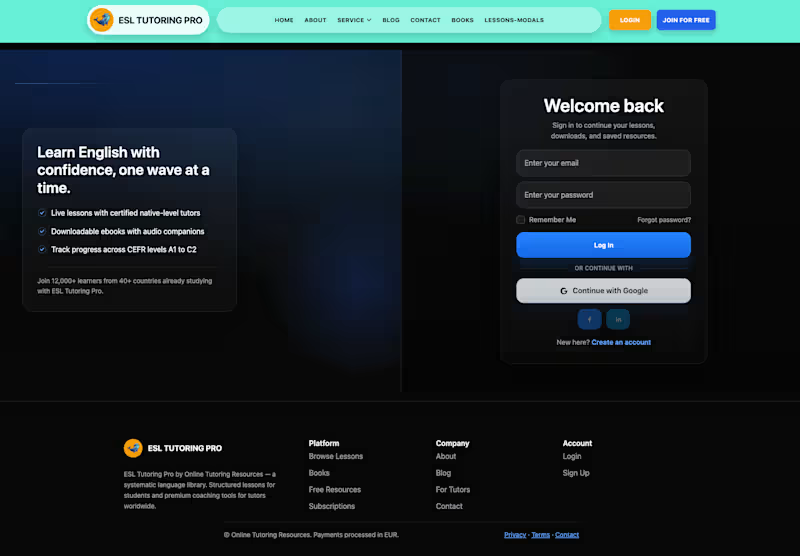
Last week I shipped a full learning platform: two audience journeys (students + tutors), subscriptions and digital-product sales, lead capture, blog — built solo, end to end.
1
184

I designed and engineered a hierarchical multi-agent orchestration framework for coordinating complex AI-assisted engineering and analytical work.
A central orchestrator assigns bounded tasks to specialized builder, analyst, reviewer, and verification agents. Execution follows an explicit dependency graph, while shared evidence, acceptance gates, negative-path testing, and checkpointed state prevent agents from declaring work complete without proof.
The framework supports targeted retries, rollback, and recovery from the first incomplete node instead of restarting an entire workflow. It also separates implementation from independent review, reducing the risk of an agent validating its own unsupported conclusions.
This independent engineering project demonstrates how agentic systems can be made more controlled, observable, and recoverable. The architecture and control interface are representative views of the framework rather than screenshots containing private execution data.
0
128

I developed an AI-assisted document-intelligence workflow for transportation-agency teams working with large collections of reports, standards, studies, scanned documents, and project records.
The system combined document extraction, OCR, structured metadata, semantic retrieval, knowledge relationships, and grounded LLM responses. Analysts could ask questions in natural language, review the supporting evidence, inspect source citations, and approve, revise, or reject generated findings.
The workflow was designed around human review, access controls, traceability, and safe failure rather than treating an LLM response as an unquestionable answer. Related work reduced decision time by approximately 60% and improved data accuracy by approximately 35%.
The displayed architecture and interface are sanitized representations and contain no client documents, production data, proprietary prompts, or confidential system details.
0
171

Senior AI Engineer building AI agents, RAG & AI apps

Expert in building an efficient and scalable data pipeline
Expert in building an efficient and scalable data pipeline


Results-driven Data Engineer & Full-Stack Developer building
Results-driven Data Engineer & Full-Stack Developer building


