The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Built an LLM-powered question-answering application that lets users ask natural-language questions over large document corpora and get accurate, grounded answers, instead of manually searching through documents for the right section.
Designed and built the full RAG pipeline independently, from document ingestion through to answer generation, as a technical demonstration of production-grade retrieval-augmented generation using AWS-native tooling.
Key Challenges:
Documents exceeding token limits: Large source documents couldn't be fed directly into the LLM's context window, so they had to be broken down without losing meaning or context across chunks.
Finding the right context: With a large corpus, the system needed to reliably surface the specific chunks relevant to a given question, not just the most textually similar ones.
Grounded, accurate answers: Answers had to be based on the actual retrieved content, not the model's general knowledge, to avoid confidently wrong responses.
Working within a managed AWS ecosystem: Embeddings, storage, and generation all needed to work together cleanly using Bedrock-native models rather than a patchwork of external services.
Approach:
Document loading and chunking
Processed large documents into manageable chunks sized to stay within model token limits while preserving enough context for coherent retrieval.
Vector embeddings with Amazon Titan
Generated vector embeddings for each document chunk using Amazon Titan, capturing semantic meaning rather than just keyword overlap.
Vector storage and retrieval
Stored the embeddings in a vector database, enabling fast similarity search to pull the most relevant chunks for any given question.
RAG-based answer generation with Claude on Bedrock
When a question comes in, the system retrieves the relevant chunks and passes them as context to Anthropic Claude via Amazon Bedrock, which generates an answer grounded in the retrieved content rather than relying on parametric memory alone.
Results & Impact:
Accurate, source-grounded answers over document corpora too large to fit in a single context window.
A scalable retrieval architecture that separates document processing, embedding, and generation, so any of the three can be swapped or scaled independently.
A fully AWS-native RAG pipeline, demonstrating fluency with Bedrock's embedding and generation models working together in production patterns.
Tech Stack
Python · LangChain · AWS Bedrock · Amazon Titan · Anthropic Claude · FAISS DB


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started

Challenges
View all


Related posts

An experiment exploring how to visually communicate design impact through a draggable before/after slider. Built to test the interaction and motion feel of scrubbing between two states of a design, it uses a small format to show transformation at a glance 😊


The compact format is doing a lot of work—the draggable reveal makes the improvement immediately legible, while the consistent card rhythm keeps the comparison easy to scan.

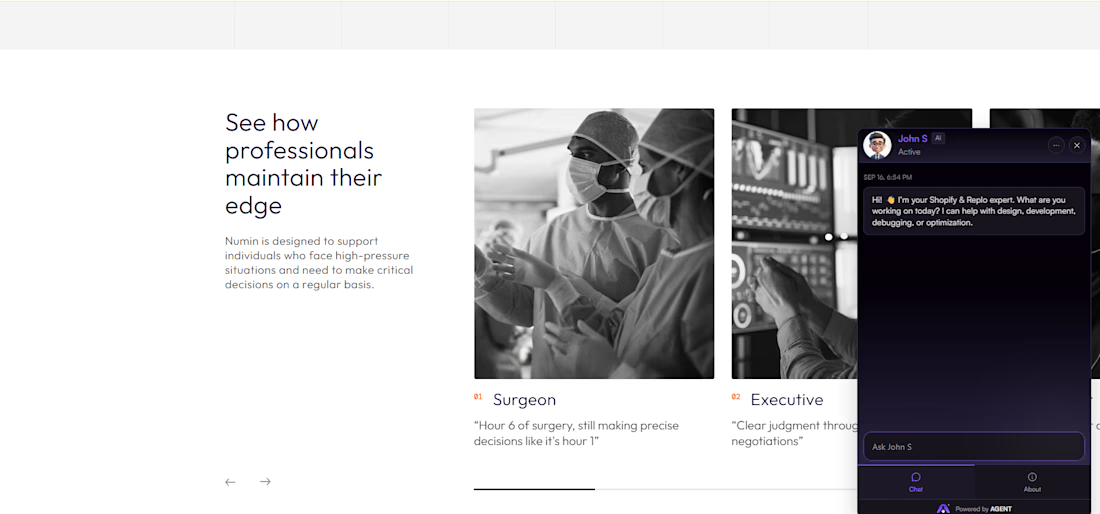
AI Agent Integration & Custom Website Chat Widget


Built a SaaS platform with Laravel & PHP
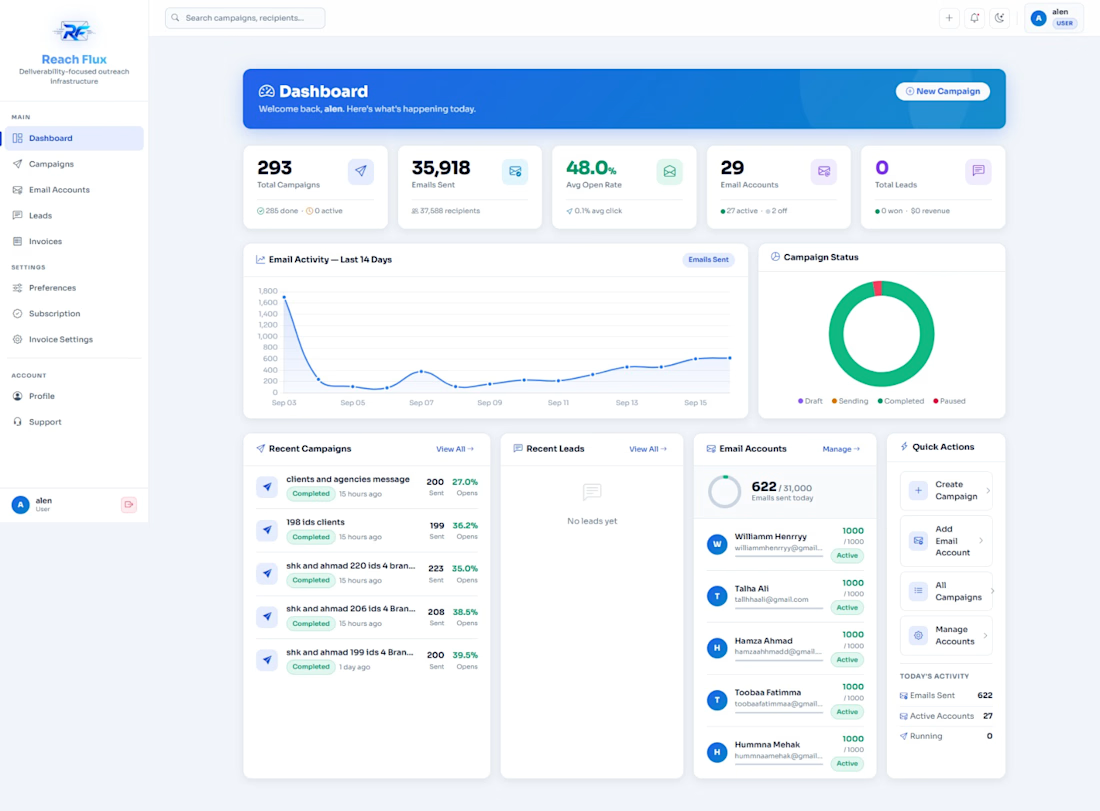
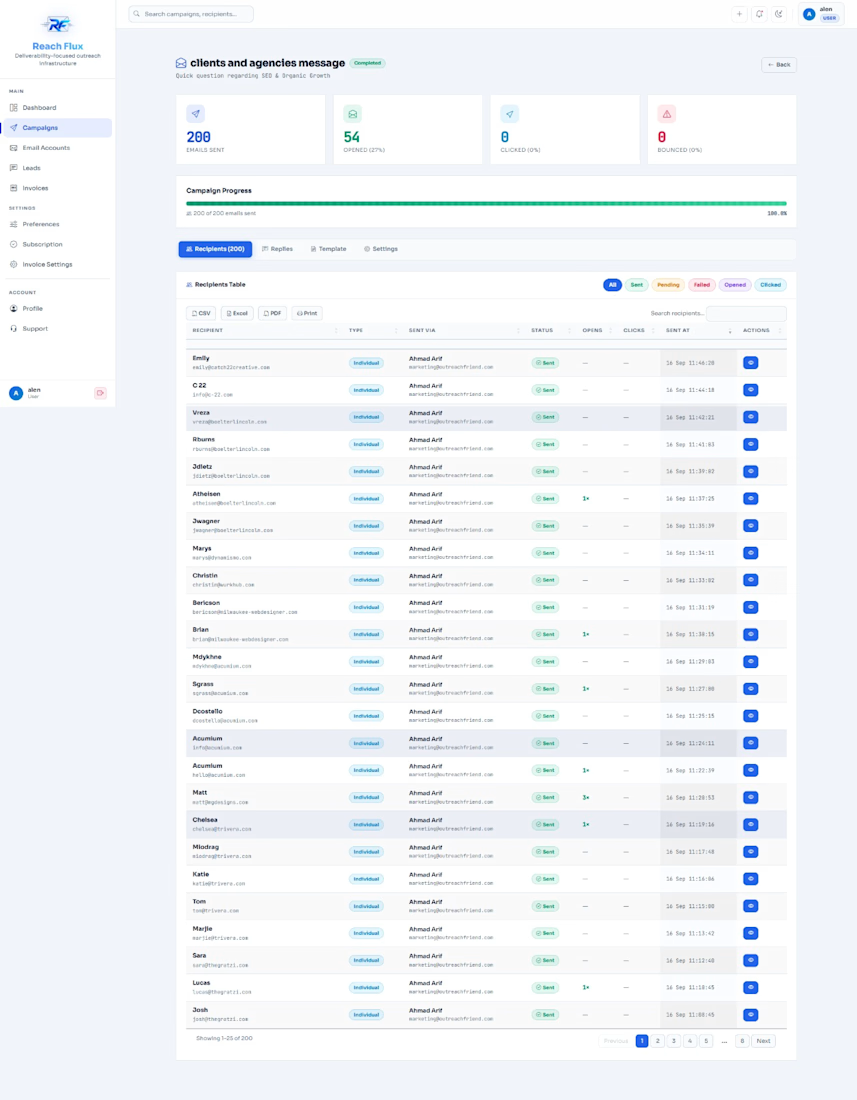
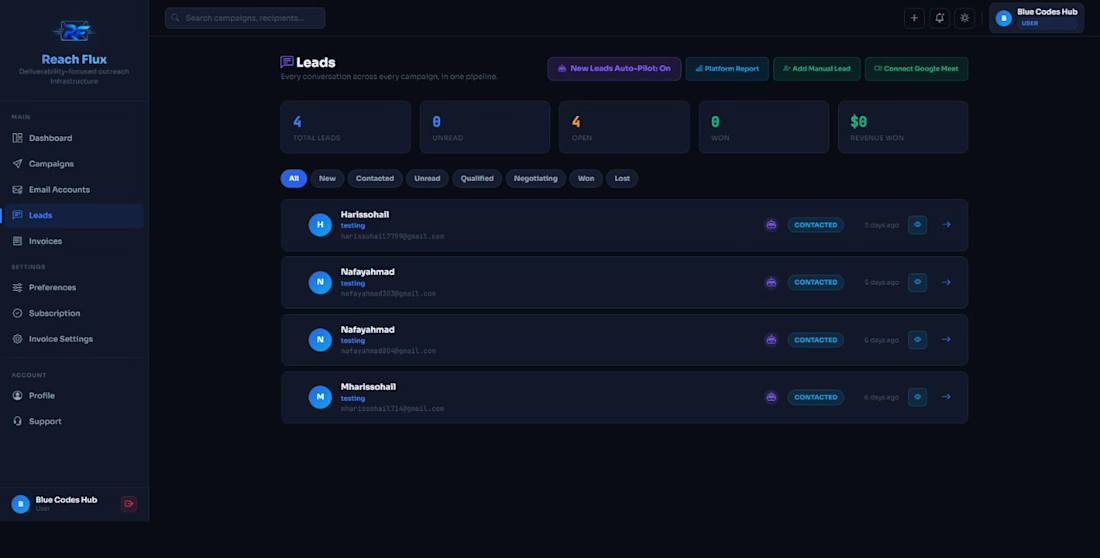
One of my recent projects is ReachFlux, a SaaS marketing platform built with PHP, Laravel and MySQL.
I worked on the application structure, authentication, user roles, dashboards, database management, APIs, campaign management, and responsive frontend.
Tech stack:
PHP · Laravel · MySQL · JavaScript · AJAX · Bootstrap · REST API
The project involved building a complete web application with different workflows, dashboards, automation features, and data-driven functionality.
Always enjoy turning an idea into a functional web application.