The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Non-metric MultiDimensional Scaling (NMDS) on a publicly-available legume dataset


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts

Saw this - been testing Seedance 2.5 too. Output is good but still needs human clean-up, esp label warp. I disclose it as AI-assisted. Human eye still matters.

Is AI finally good enough to shoot a product demo on its own, or human touch is still needed?
I generated a 20s product demo with Seedance 2.5 in a single take providing it with one product image reference and an example video transcript (posted in the comments).
Do you disclose...

so impressive

Superstore Sales Forecasting | Python & Machine Learning
Developed a sales forecasting project using the Superstore dataset and machine learning. The project includes data preparation, exploratory analysis, feature engineering, model development, and performance evaluation. A Random Forest regression model was used to forecast sales and evaluate predictive performance.



Back to Basics: The Anatomy of a RAG Pipeline 🧱
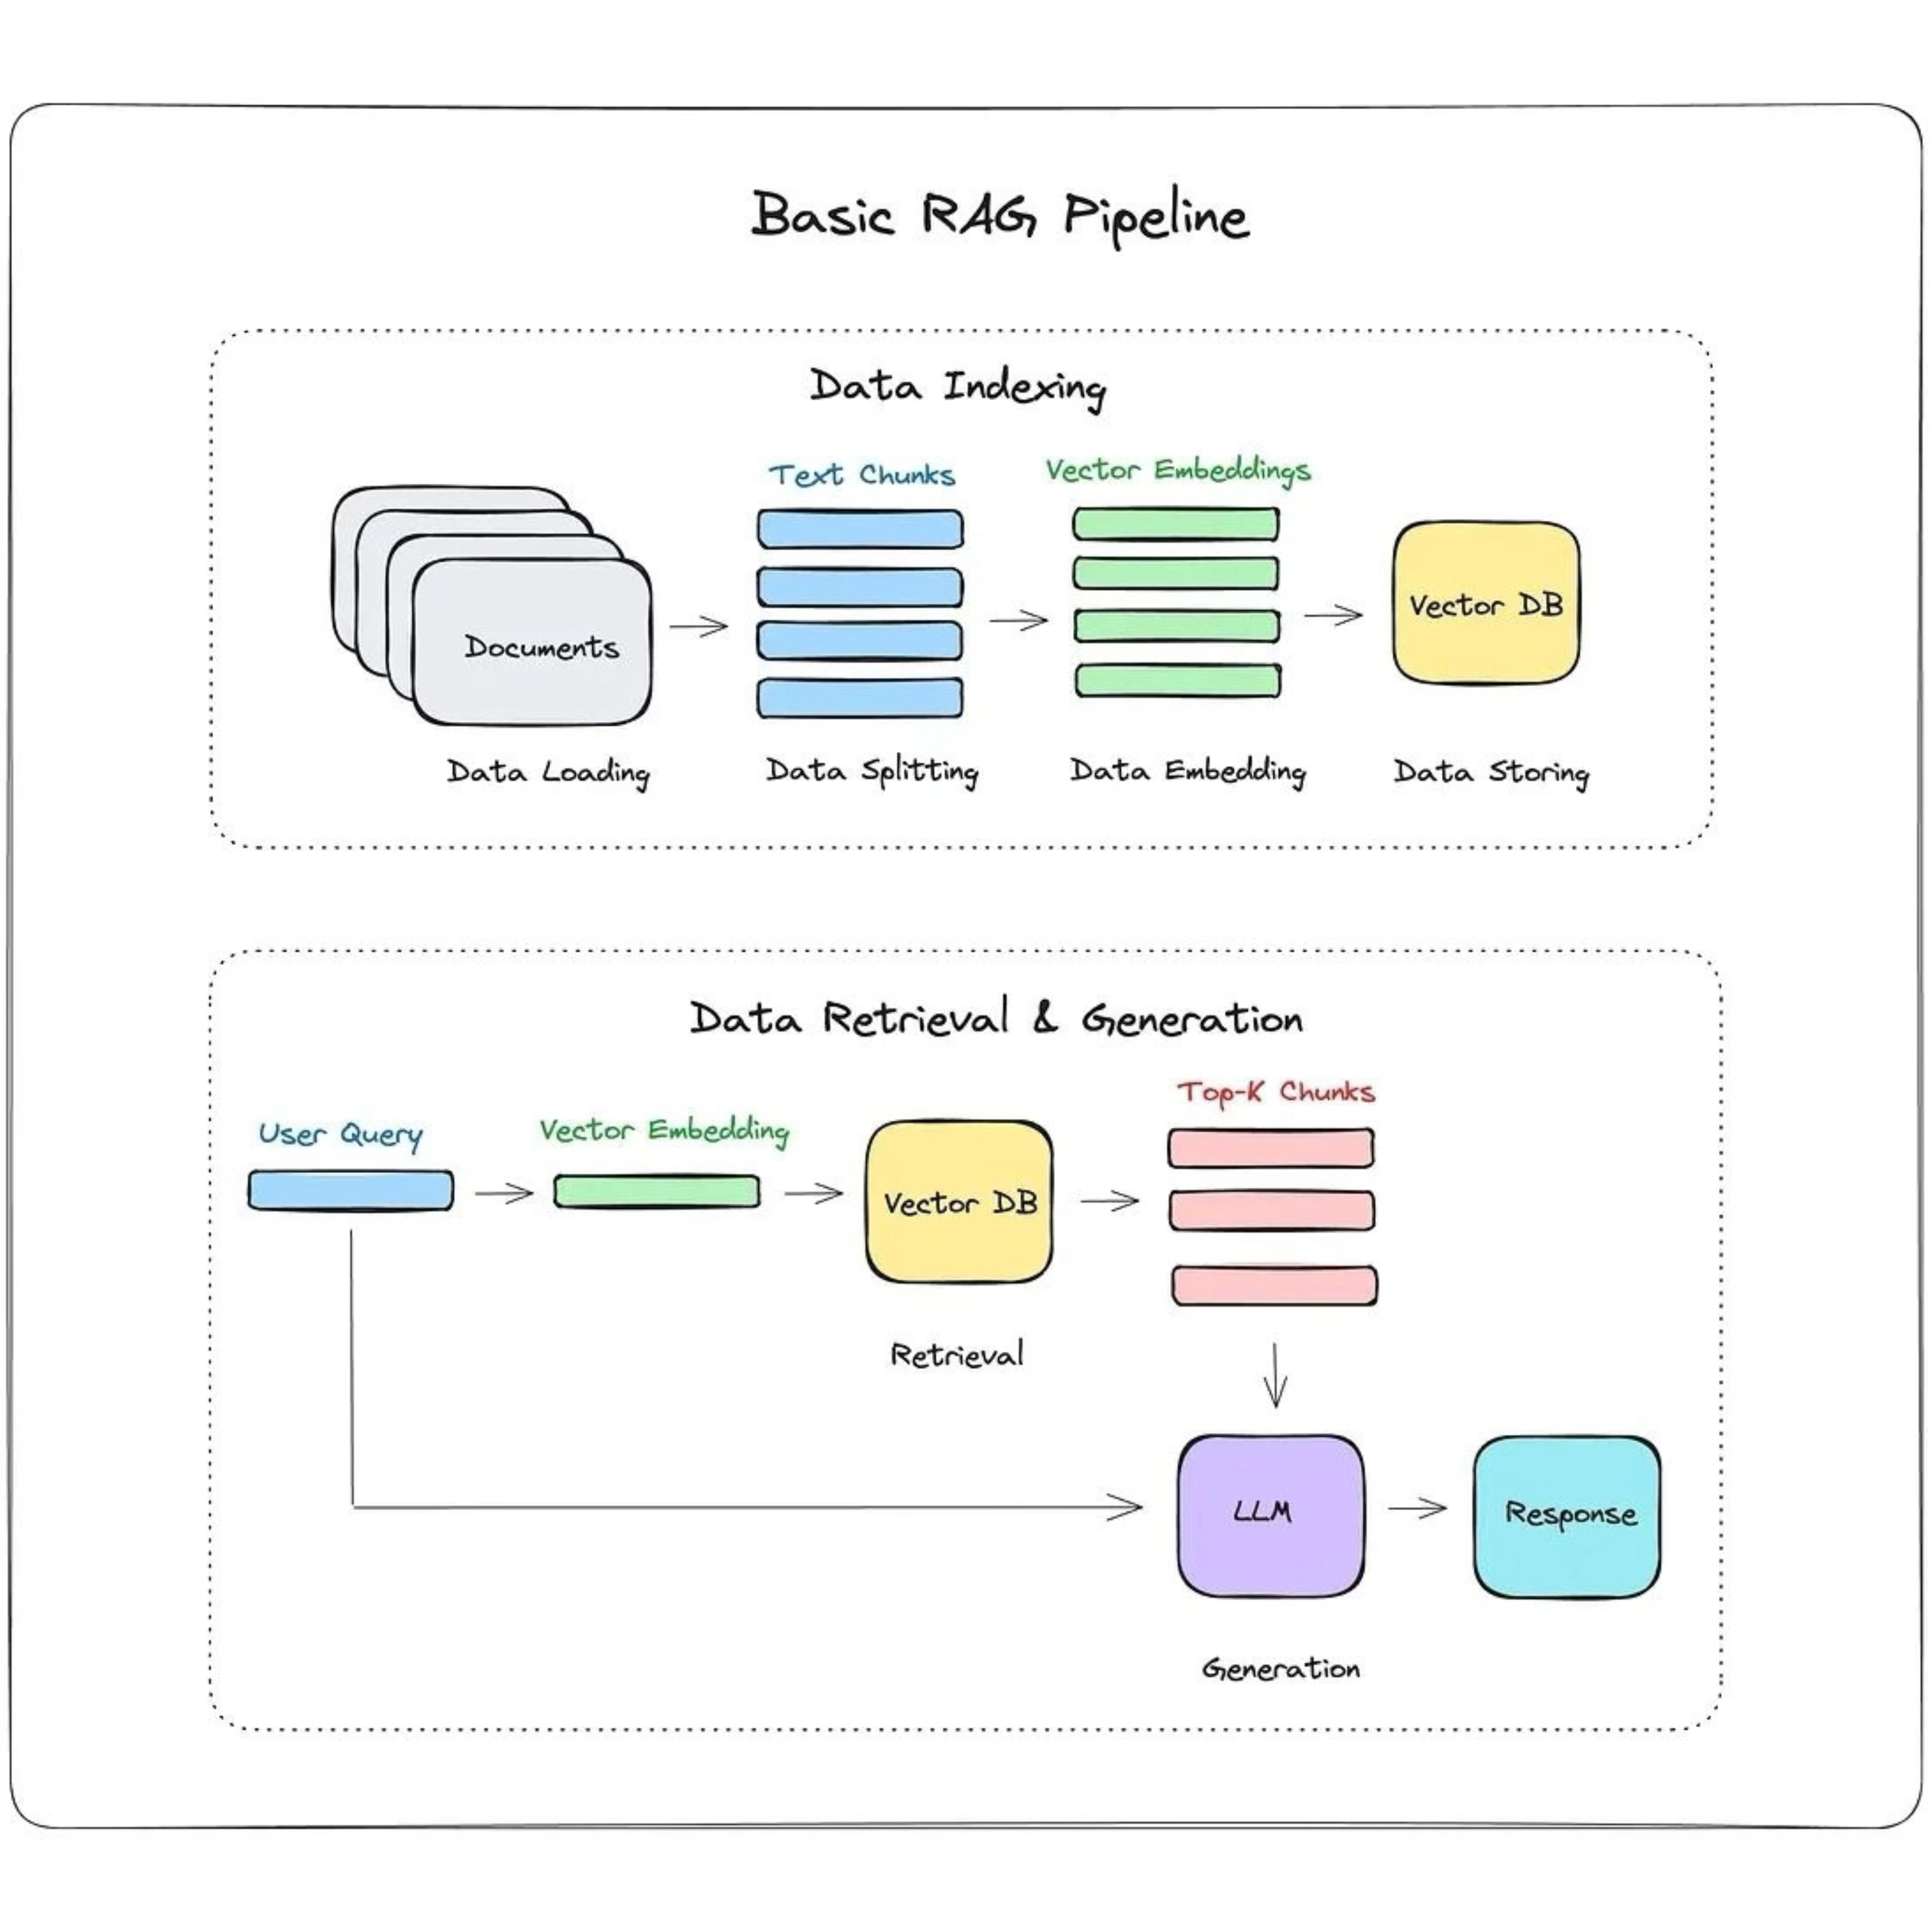
Before diving into advanced techniques like hybrid search or agentic workflows, you have to master the foundation. This clean visualization perfectly breaks down the fundamental architecture of a Basic Retrieval-Augmented Generation (RAG) system.
Every solid RAG application is built on two distinct phases:
📦 Phase 1:
Data Indexing (The Prep Work)
This is where you build your knowledge base. It involves taking raw documents (PDFs, Notion pages, databases), loading them, and splitting them into manageable Text Chunks. Those chunks are then passed through an embedding model to create Vector Embeddings, which are finally stored in a Vector DB (like Pinecone, Milvus, or pgvector). Pro-tip: Your chunking strategy here will make or break your entire system.
⚡ Phase 2:
Data Retrieval & Generation (The Runtime)
When a user asks a question, the system converts that specific query into a vector embedding using the same model from Phase 1. It then performs a similarity search against the Vector DB to retrieve the Top-K Chunks of relevant context. Finally, both the original query and the retrieved context are fed into the LLM to generate a highly accurate, context-aware response.
While simple, getting this baseline architecture right is the hardest part for most teams. If your embedding model is weak or your chunk size is wrong, no amount of advanced reranking will save the output.
What is your current go-to embedding model for setting up this foundational pipeline? Are you team OpenAI, Cohere, or using open-source models via HuggingFace? Let me know below! 👇