
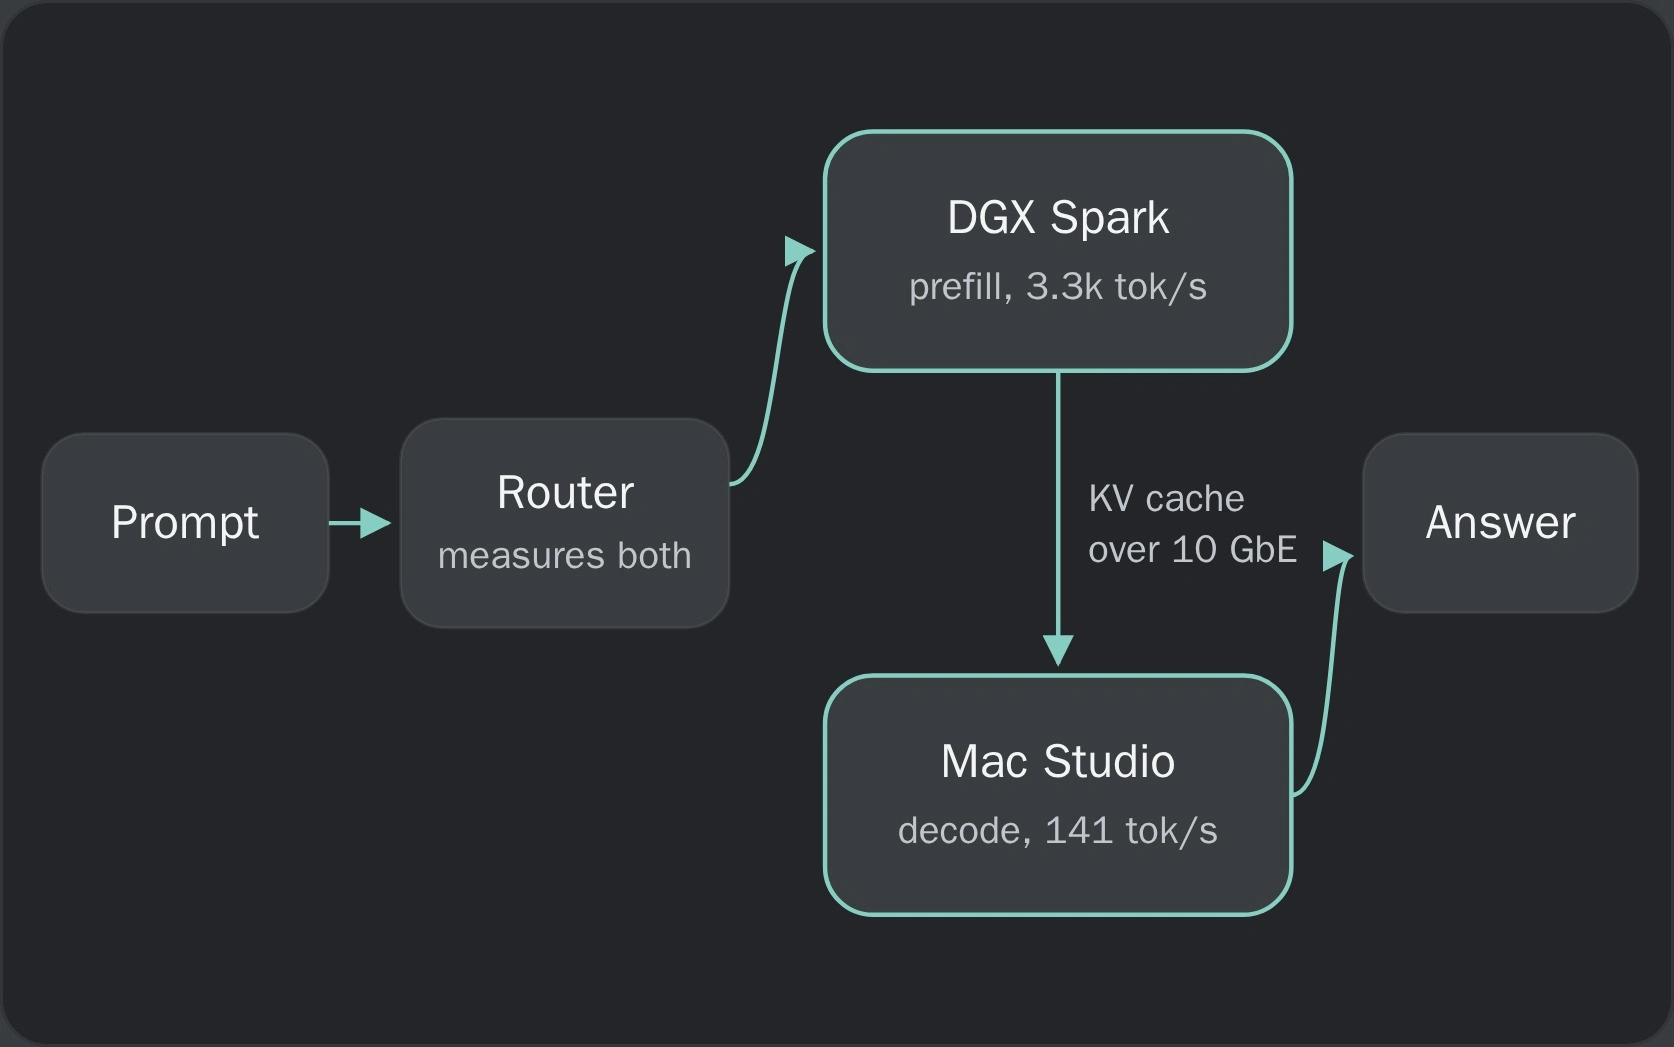
A private LLM cluster that splits one request across two machines: an NVIDIA DGX Spark reads the prompt and a Mac Studio writes the answer. Nothing leaves the building.
A router measures both paths and picks the faster one per request, so a client application talks to a single endpoint and does not need to know which machine did what.
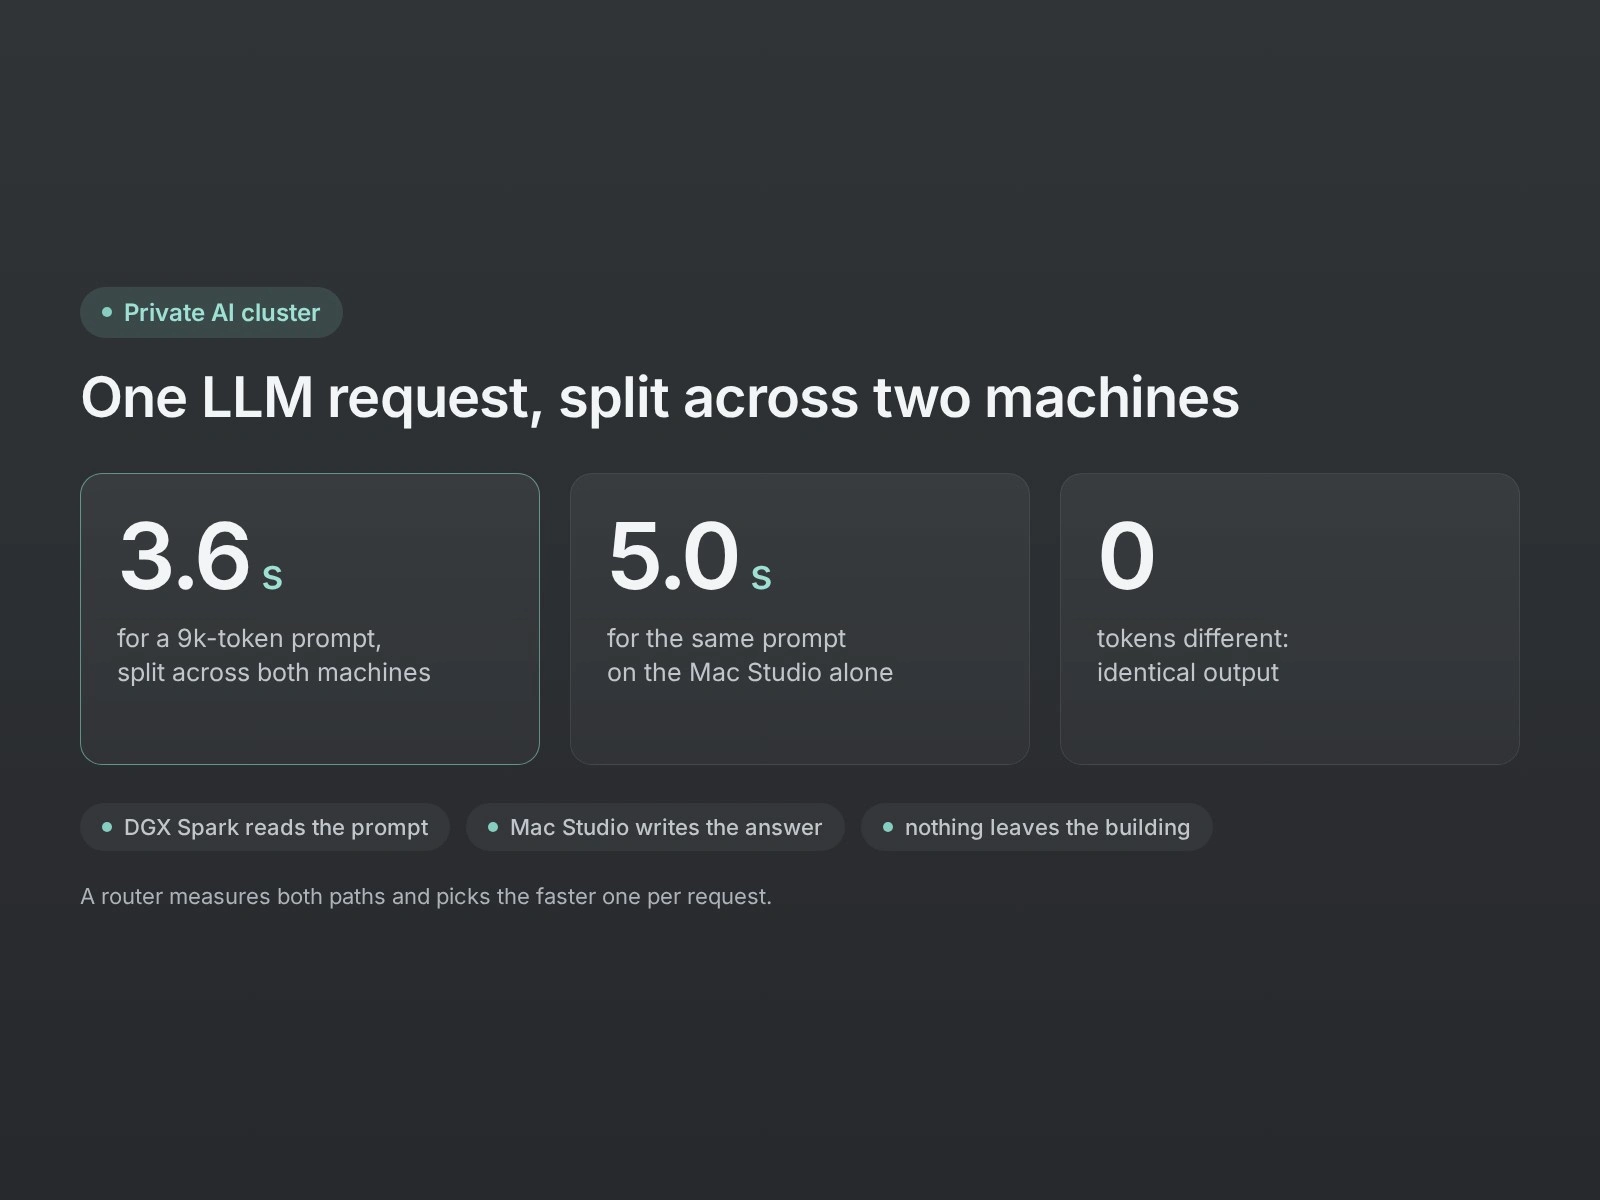
On a 9k-token prompt the split path took 3.6 s, against 5.0 s on the Mac Studio alone, and the answer was identical, token for token.
Stated plainly: this is one benchmark on my own two machines. A client setup starts by measuring their own models and prompts on their own hardware.
0 likes · 0 views · Nov 19, 2026
One LLM request split across a DGX Spark (prefill) and a Mac Studio (decode): a 9k-token prompt in 3.6 s instead of 5.0 s, identical output.
