
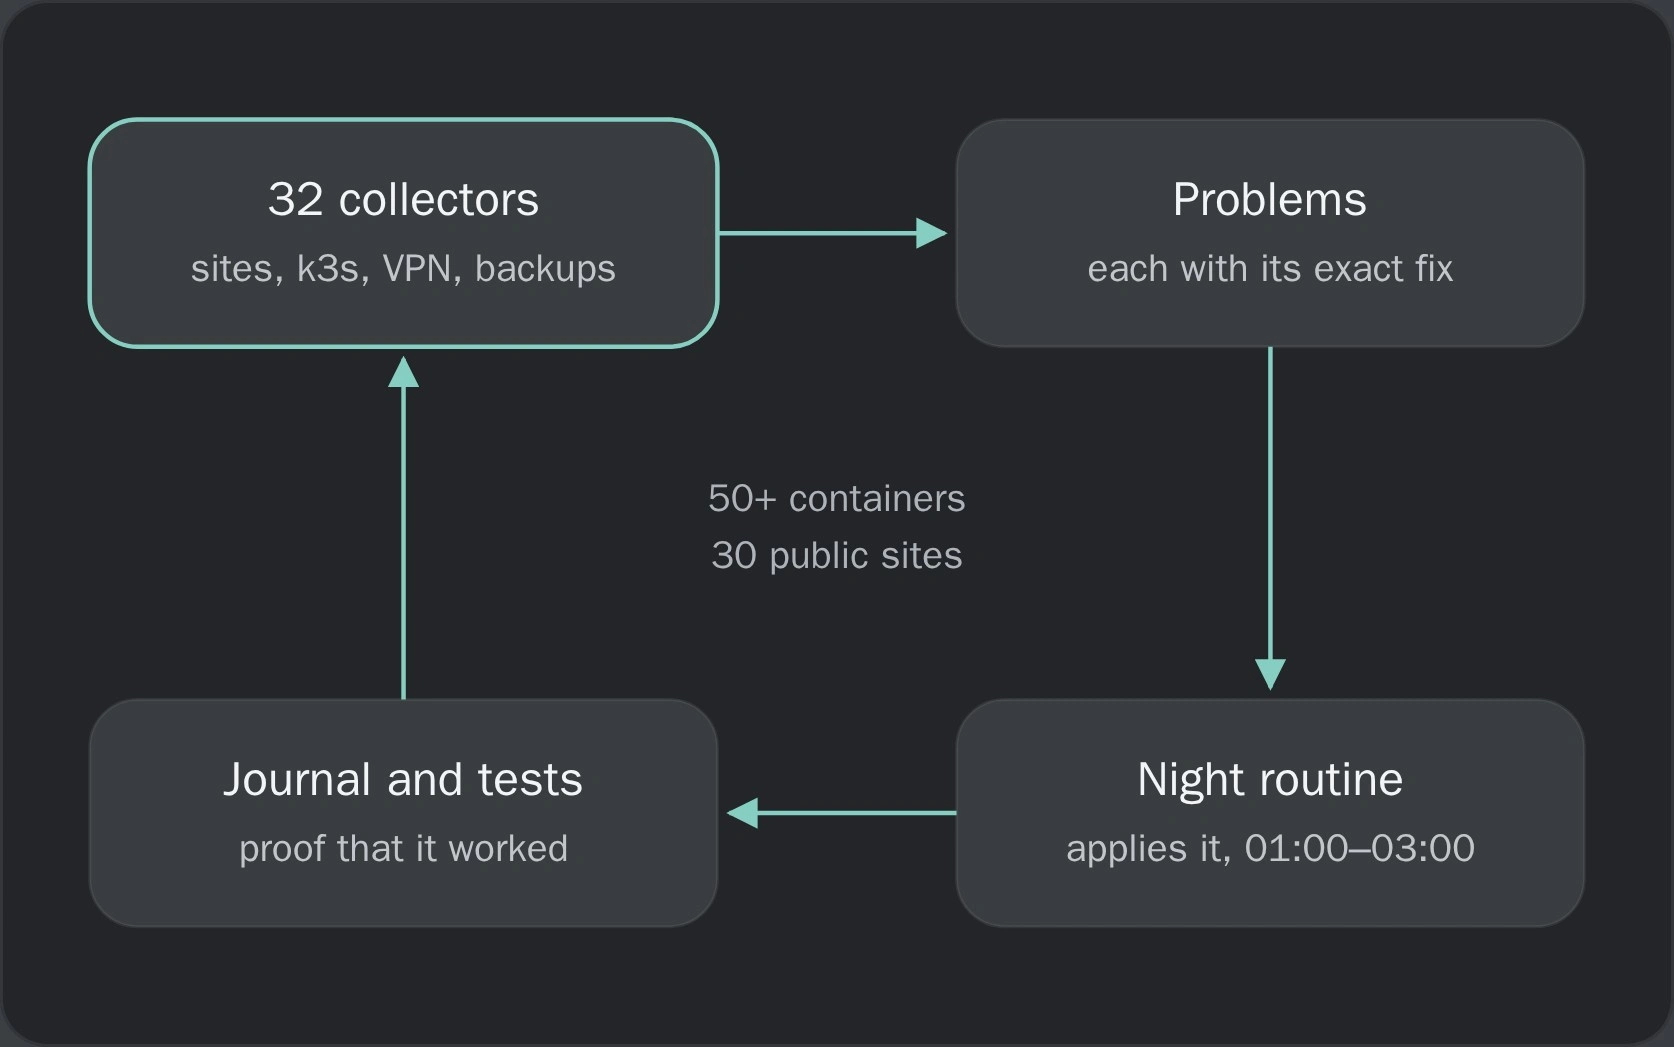
One control point for a home server, a Kubernetes cluster and 30 public sites. It knows what should be running, measures what is running, and is the single door every automated agent goes through, with one audit log and one kill switch.
32 collectors check containers against their desired state, every site at the edge and the origin, the cluster, backups, VPN chains, tunnels and DNS. Each problem they raise carries a severity and the exact commands that fix it.
An unattended routine follows those commands in a night window and writes what it did to a journal. Outages are fixed at once, degraded services wait for the night, and anything that changes an application becomes a pull request for a person to review.
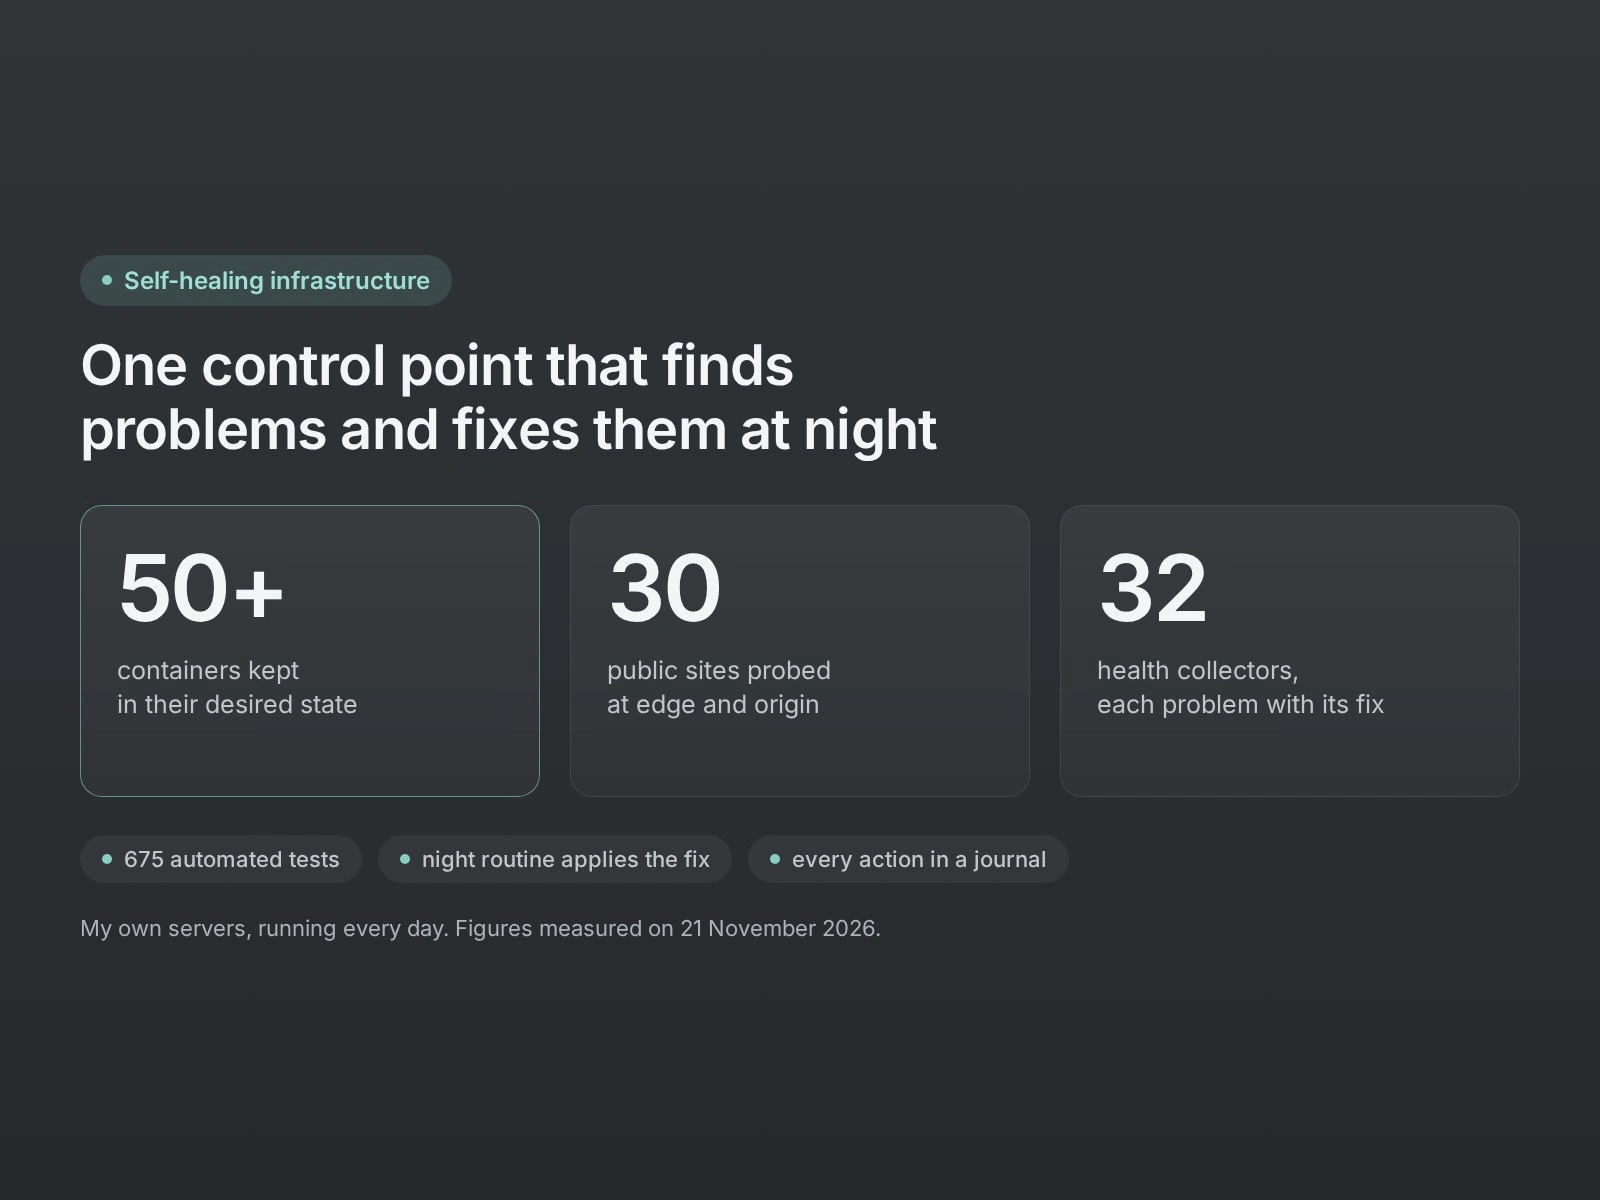
Measured on 21 November 2026: 50+ containers, 30 sites probed, 32 collectors and 675 automated tests. This is my own infrastructure, so it shows how I build and run systems rather than a client result.
0 likes · 0 views · Nov 19, 2026
Self-healing control point for my servers and 30 sites: collectors find problems, a night routine applies the fix. 675 tests.


