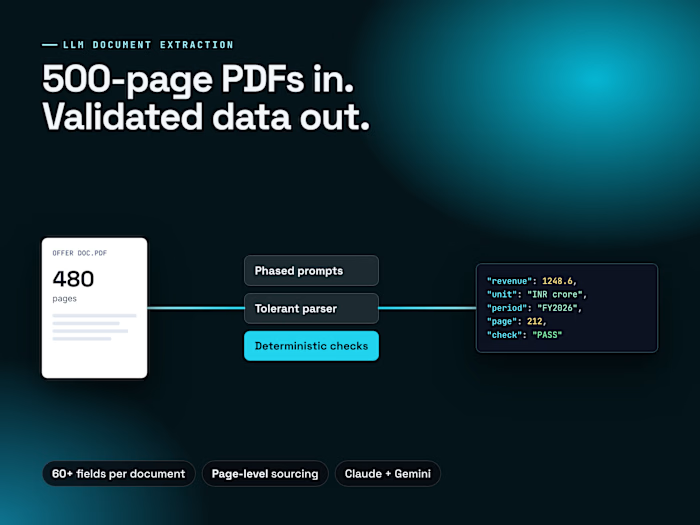
Transforming Comprehensive PDFs into Verified Data

Gaureesh Vats Shukla


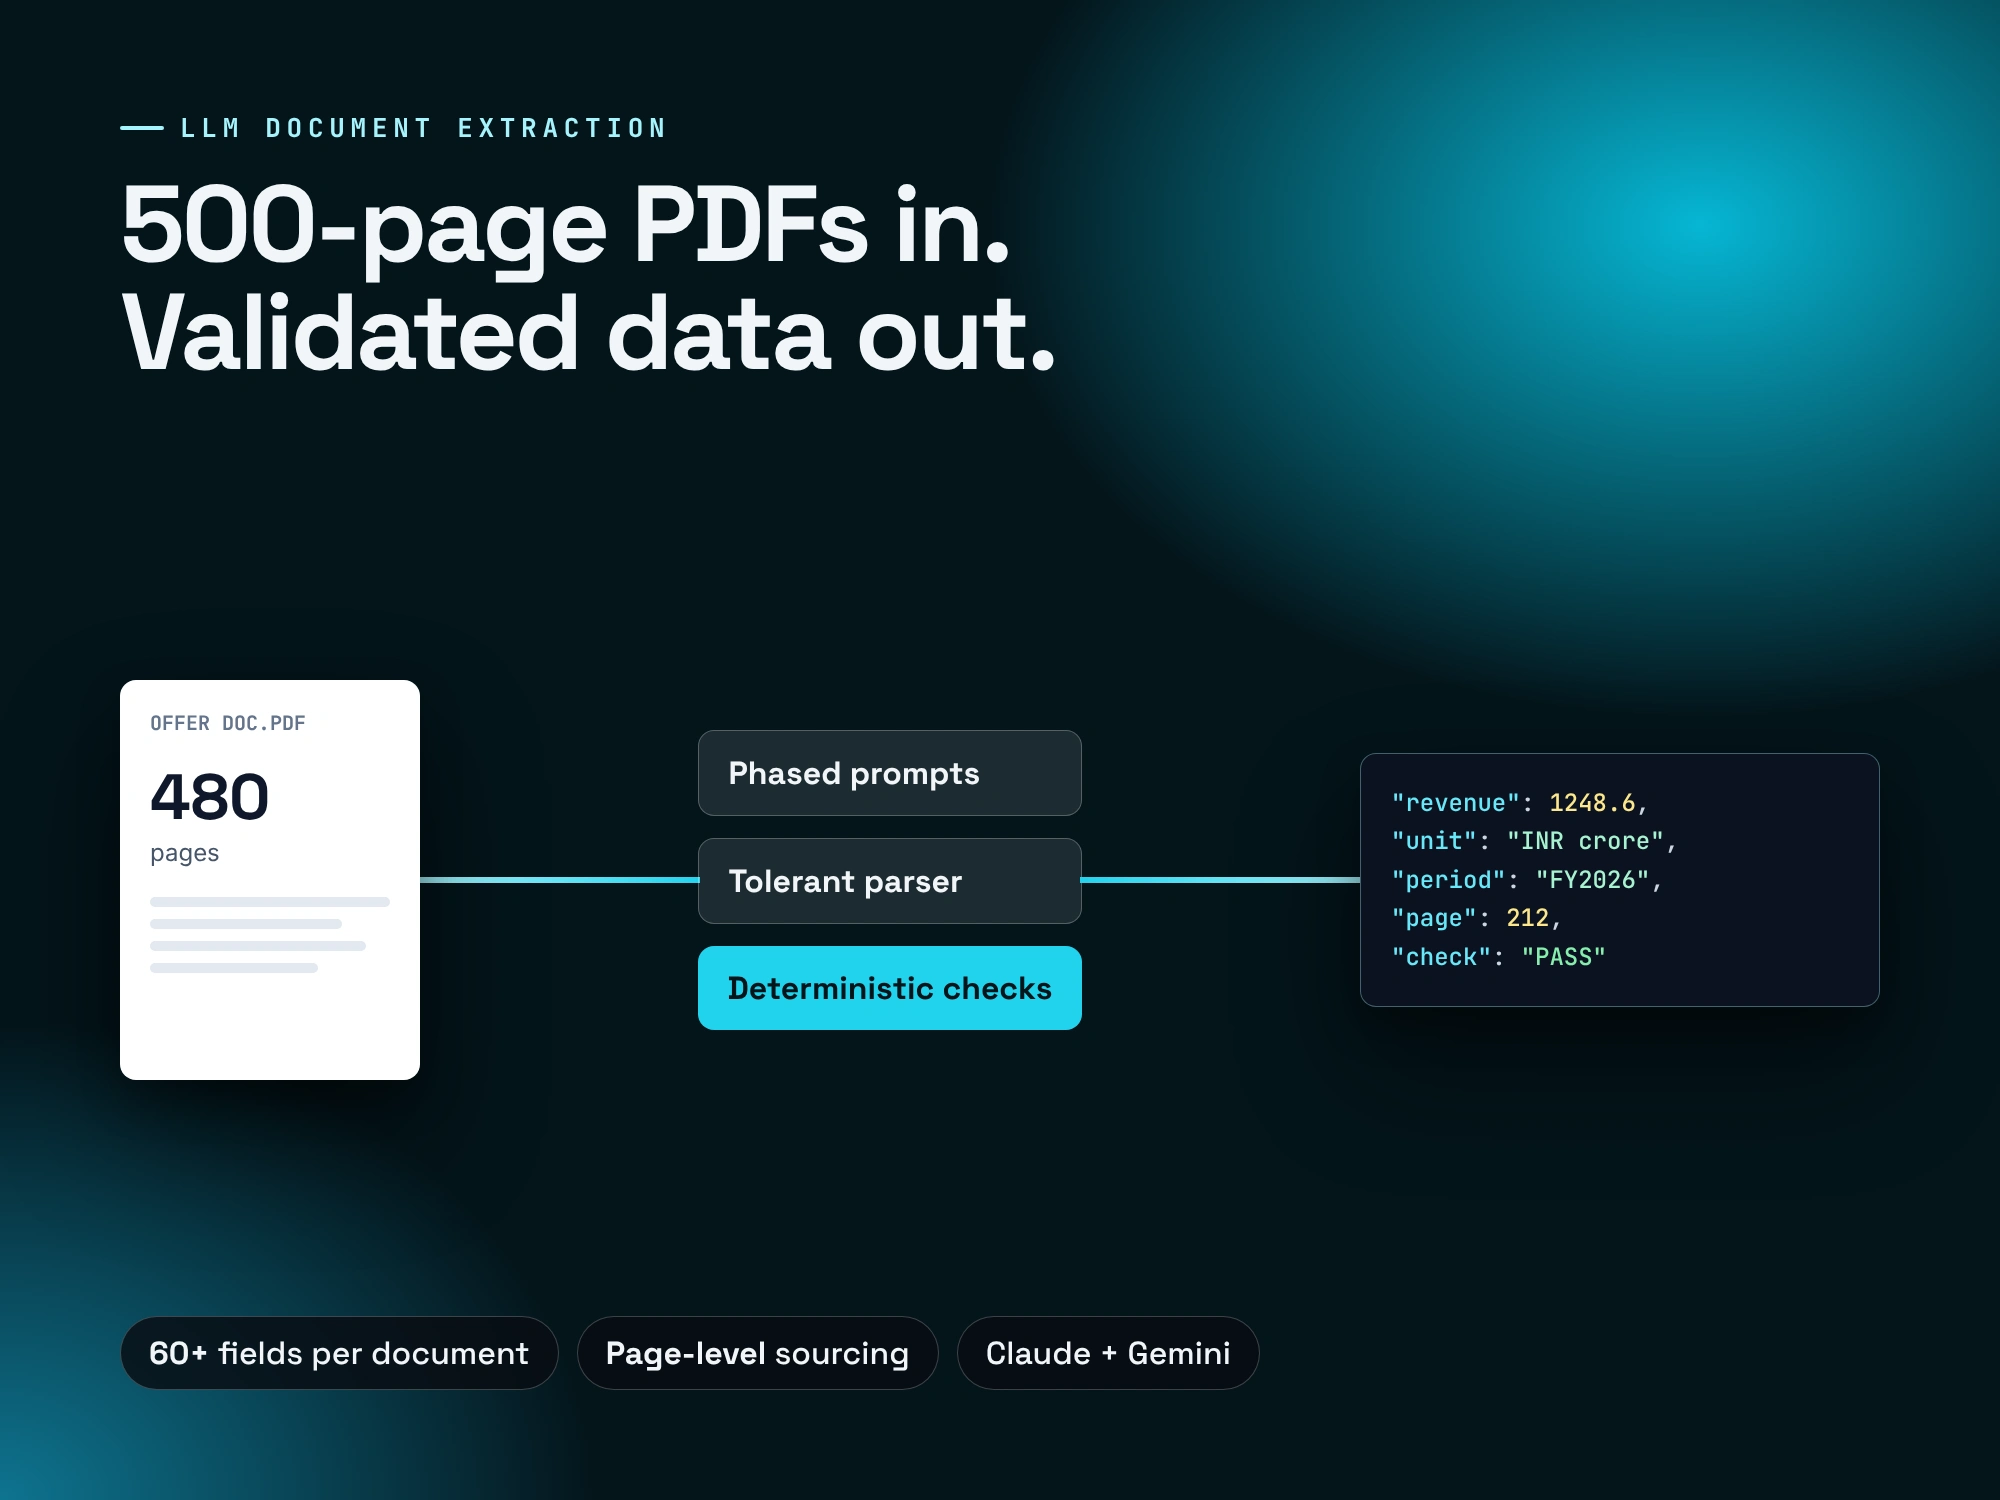
Turning 500+ page PDFs into validated, page-sourced data
The problem Offer documents run 300 to 500 pages. A single prompt cannot read them, and a model that guesses a unit (lakh vs crore) is worse than no model at all.
How it works
Phased prompts that read the document section by section, past the context window
A tolerant parser that recovers from broken or partial model output instead of failing
Deterministic checks around the model: units, totals, periods and page references are verified in code
60+ fields per document, each with the page it came from
The result Structured data a reviewer can check in seconds, because every value points back to its page. Model-agnostic: Claude and Gemini both run in production.
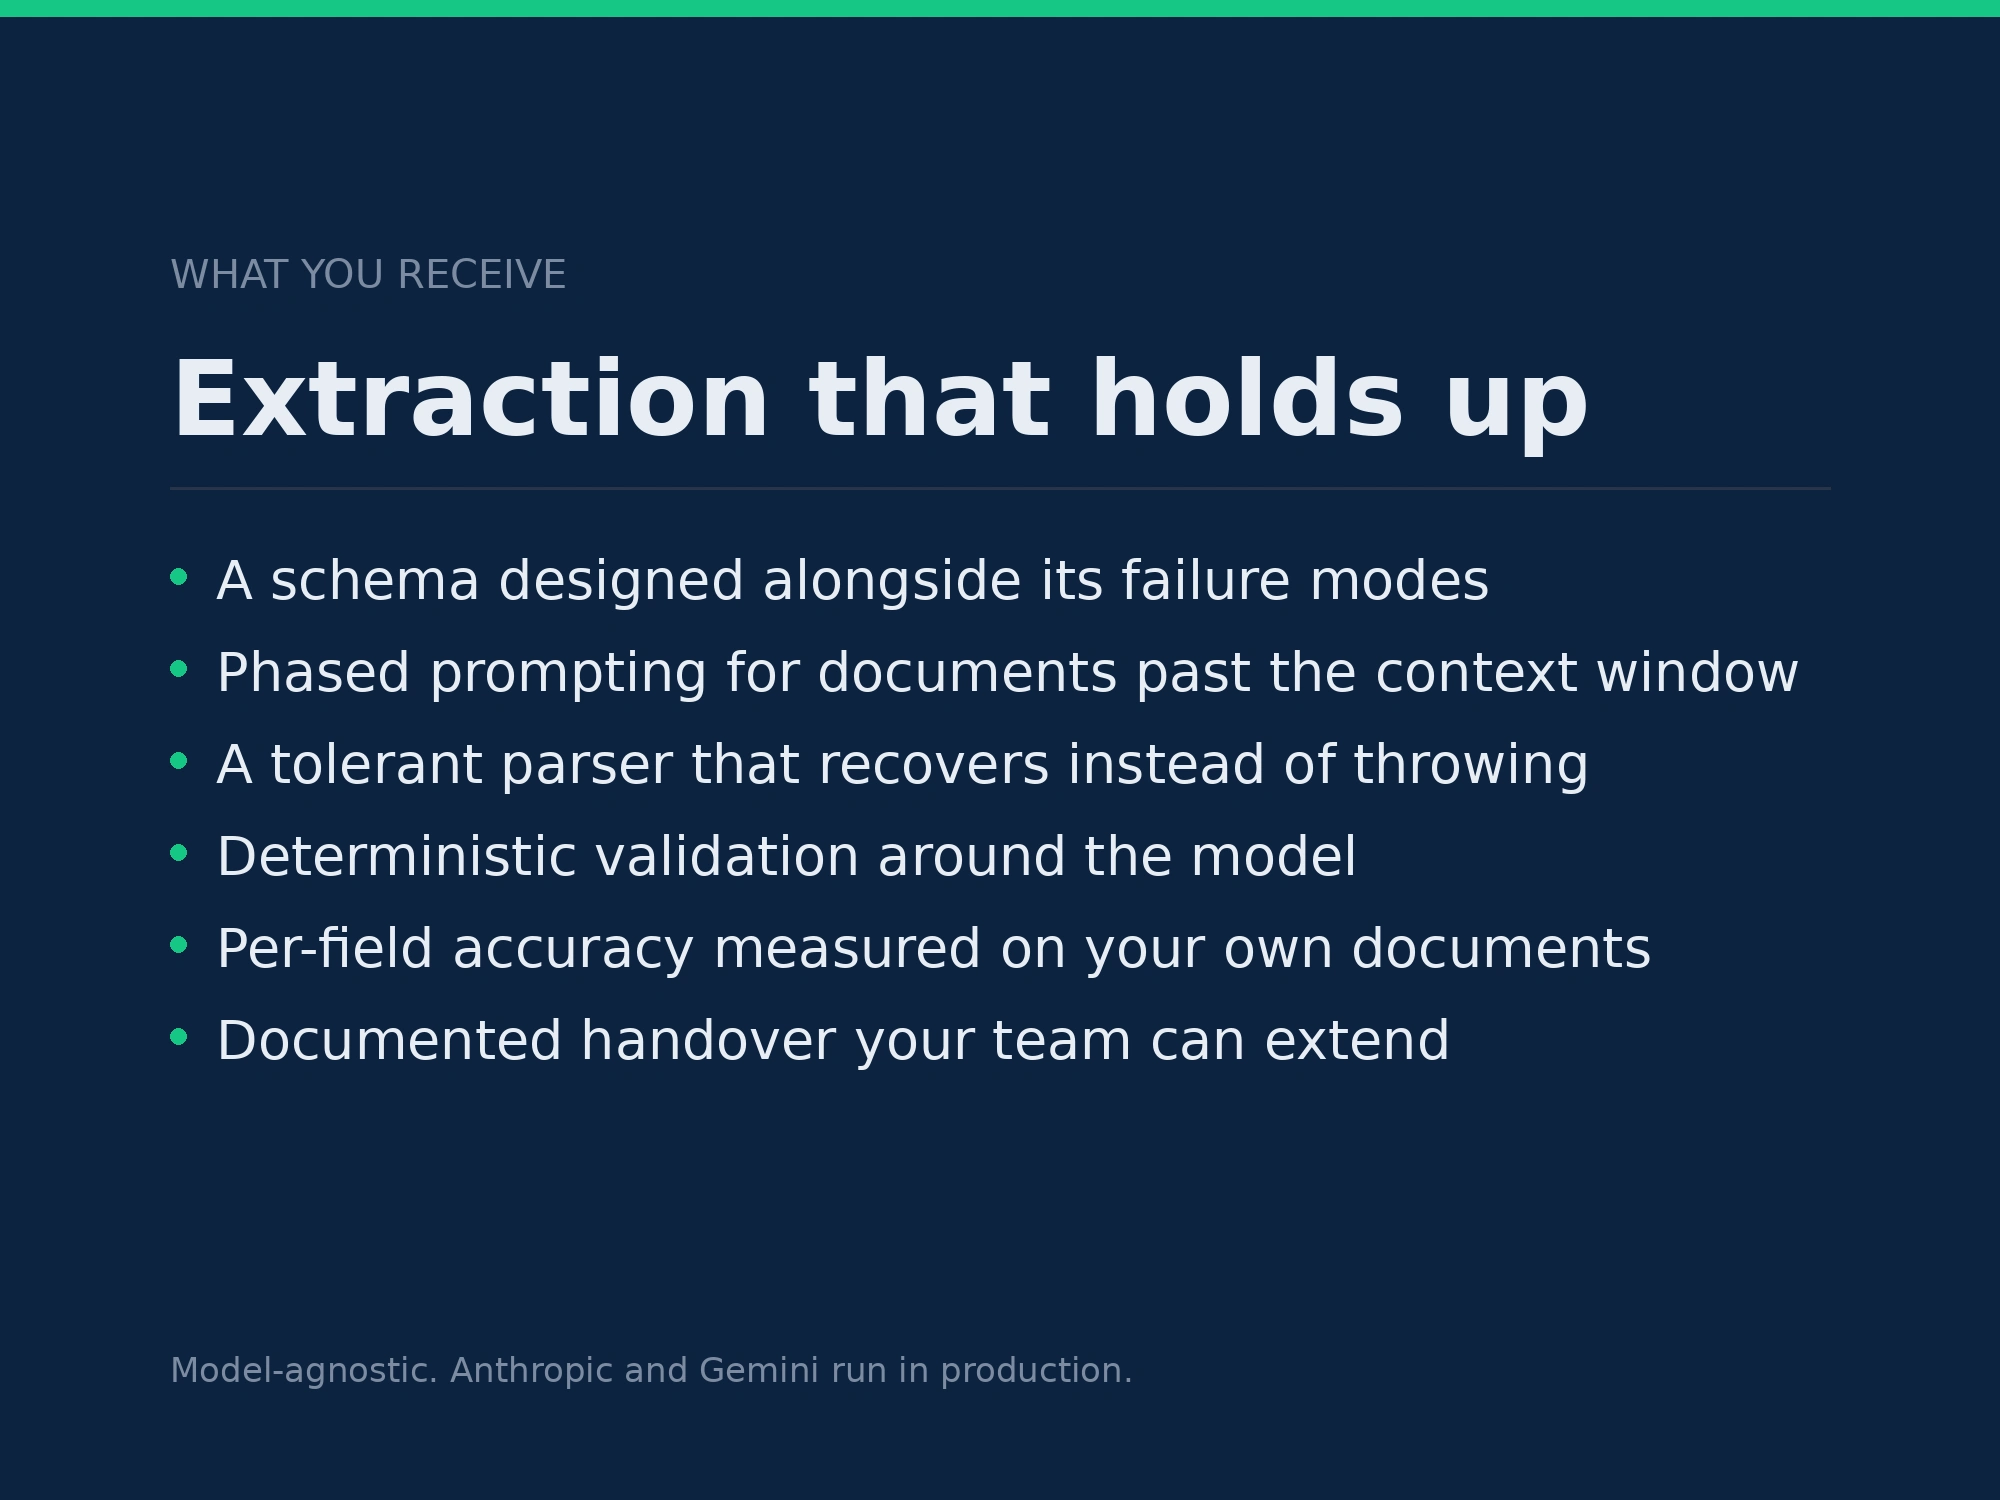
What the pipeline delivers
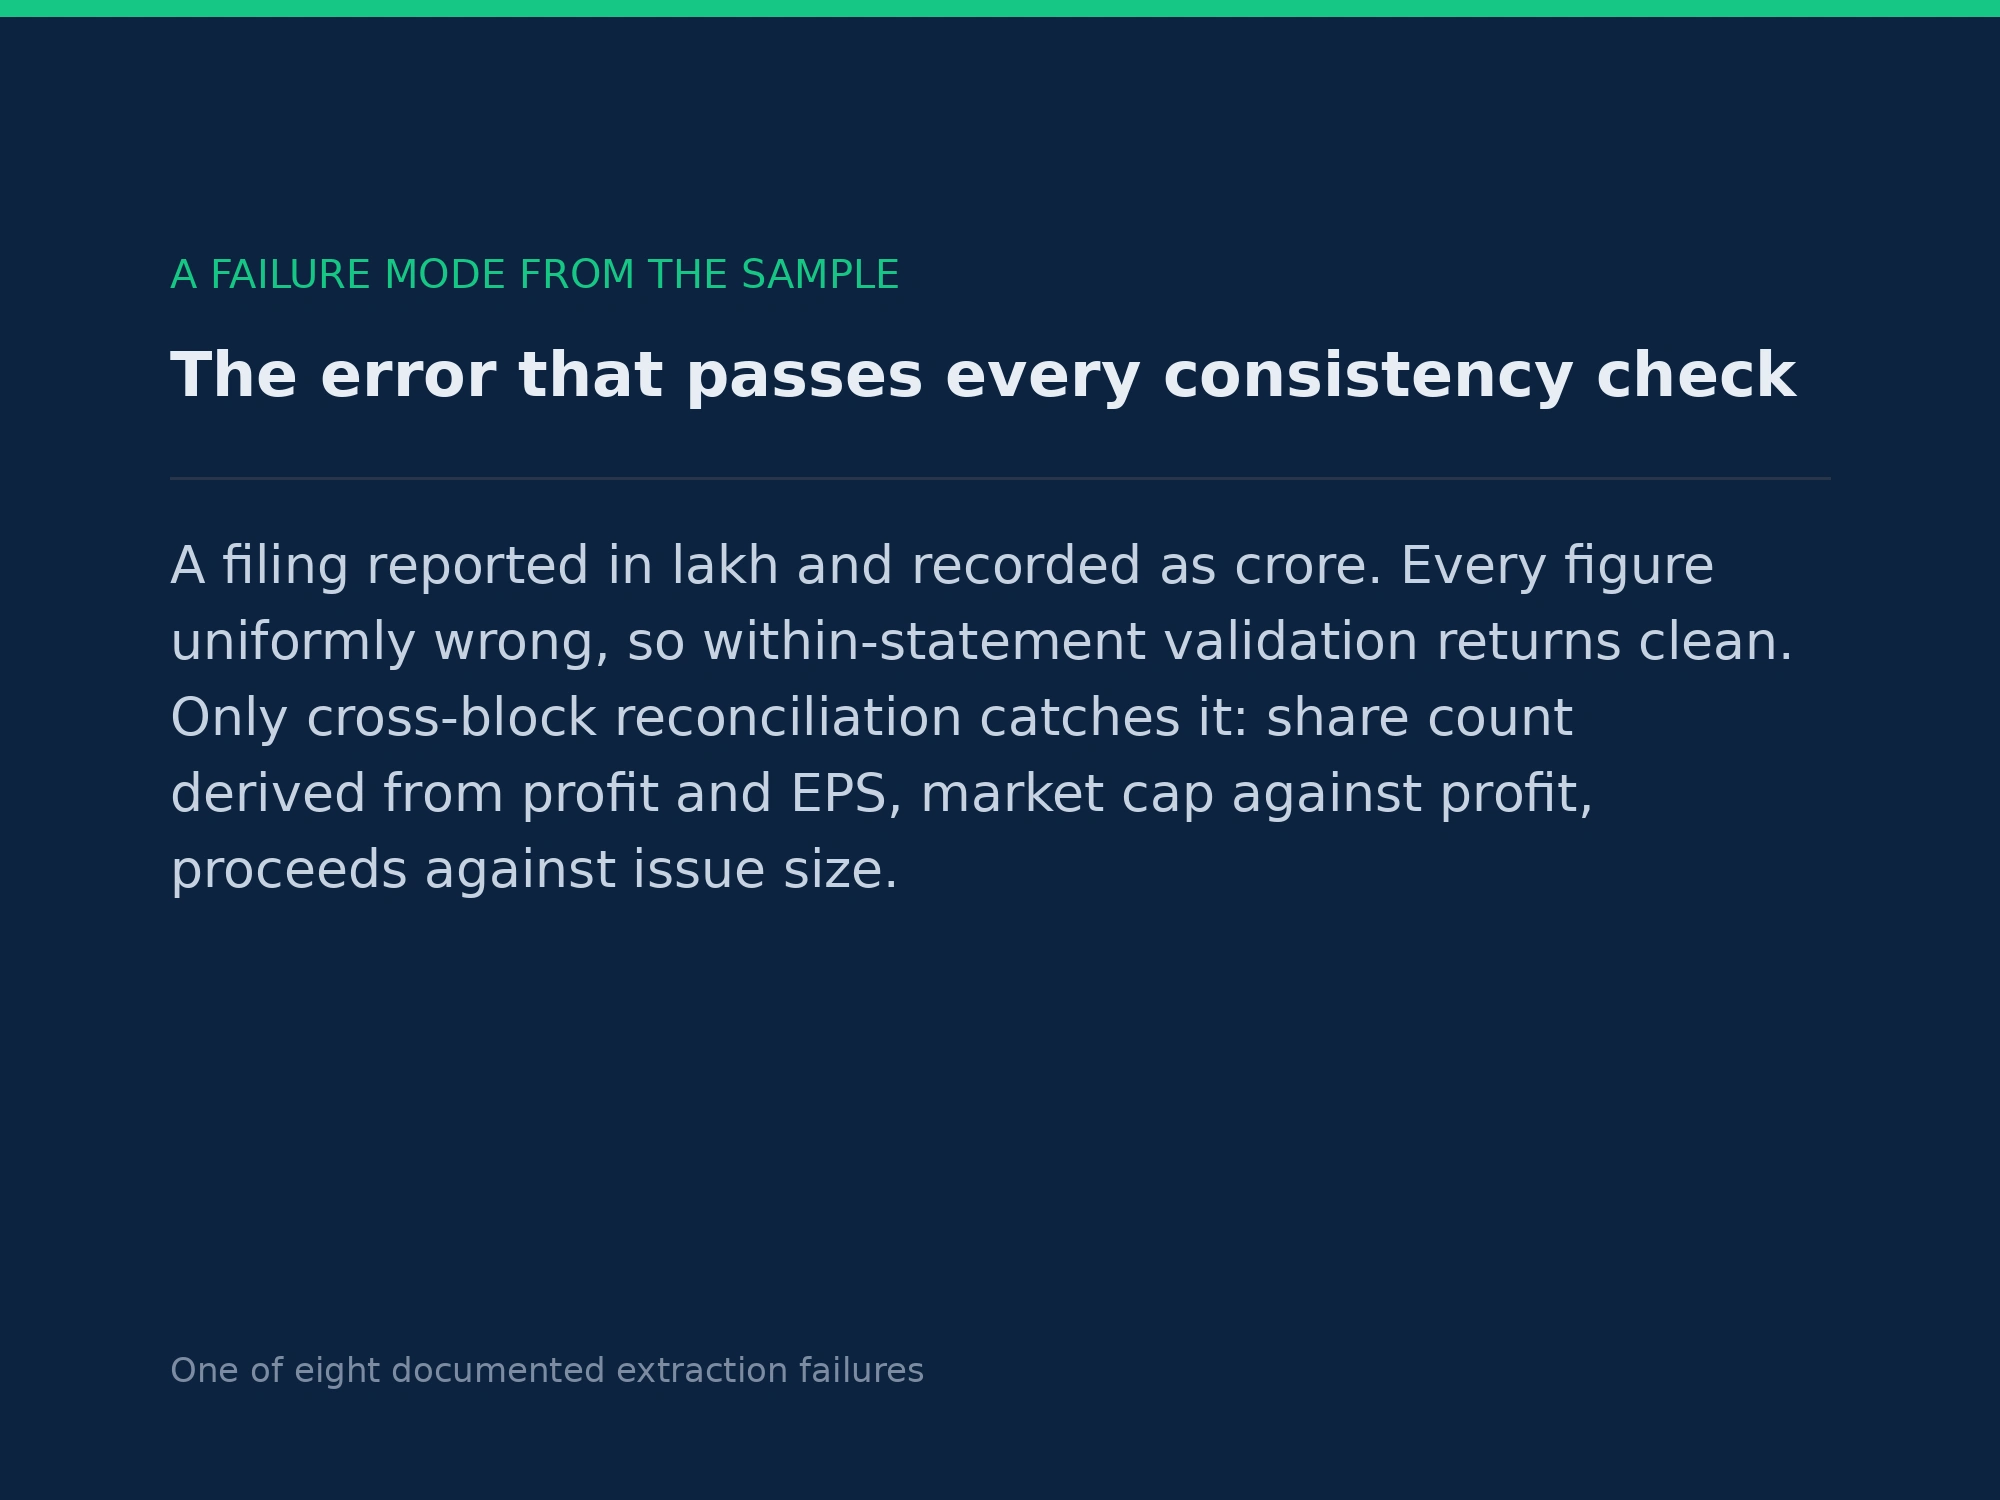
The failure mode it was built to catch
Like this project
Posted Oct 10, 2026
LLM pipeline that reads 300 to 500 page filings in phases and returns 60+ validated fields, each tied to its source page. Claude and Gemini.