
Private Multimodal RAG — Evidence Across Documents and Images
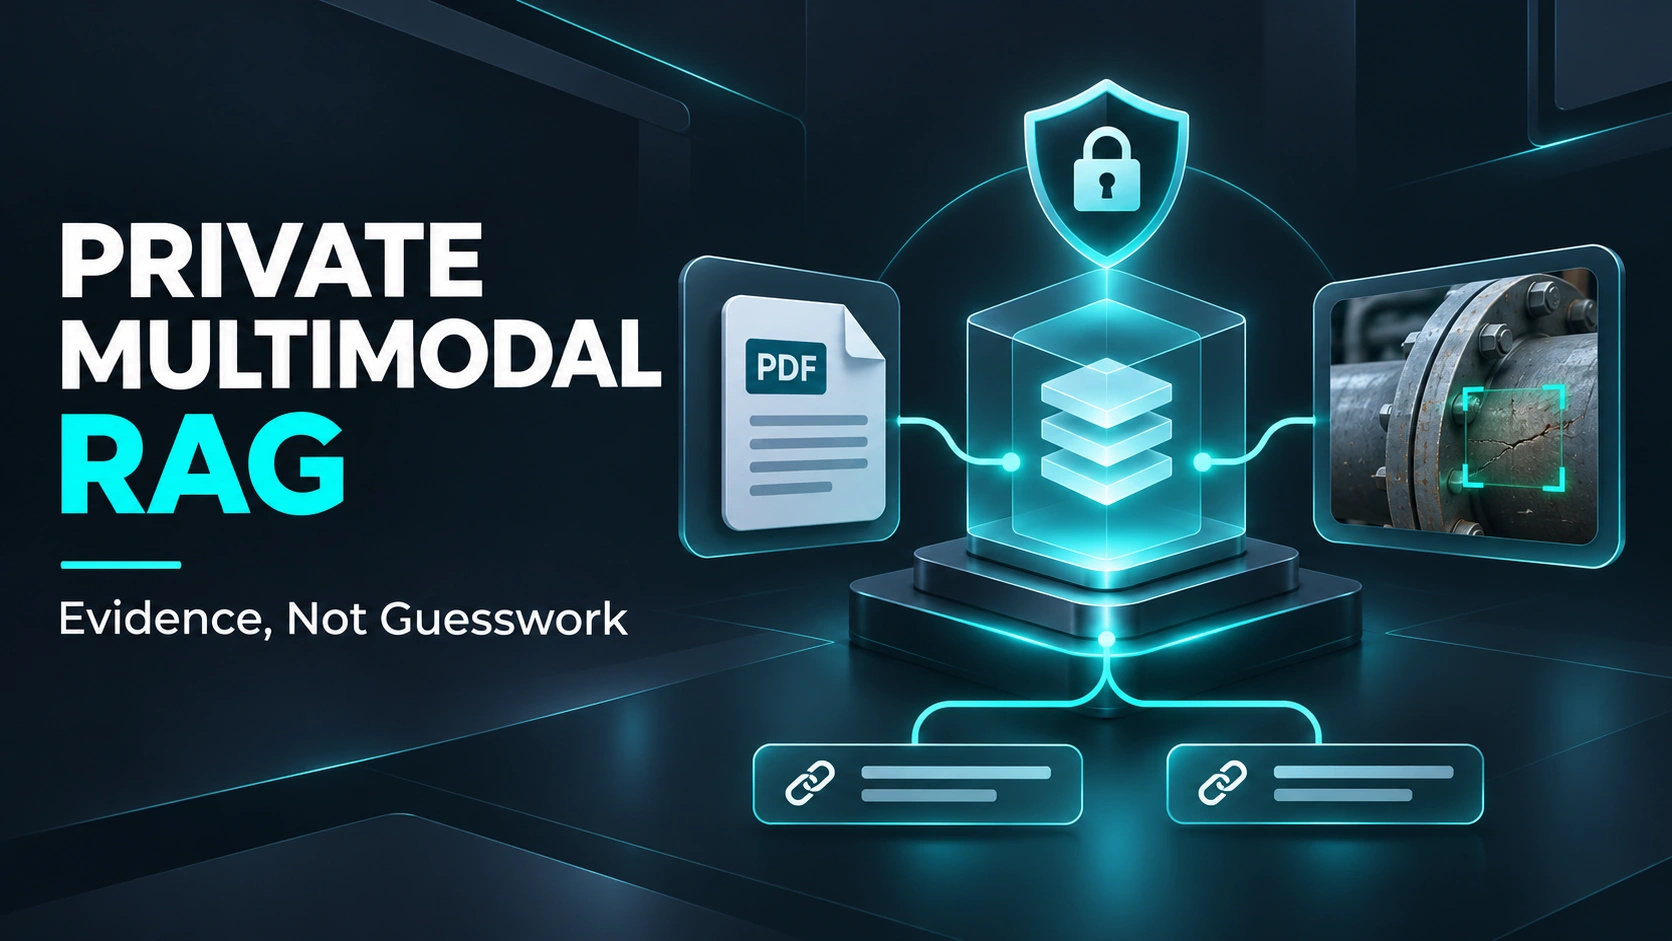
A local-first knowledge assistant that retrieves evidence from both written documents and inspection images.
The problem
Important operational knowledge is often divided between PDFs, reports, manuals and photographs. A normal chatbot may answer fluently without showing whether its answer is supported by the available evidence.
What I built
I designed a multimodal retrieval workflow that:
• Ingests documents and inspection images
• Creates searchable representations
• Retrieves the most relevant evidence
• Uses a vision-language model when image interpretation is required
• Produces answers grounded in the retrieved context
• Preserves source references for review
Why it matters
The objective is not simply to generate an answer. It is to help a user inspect the evidence behind that answer while keeping sensitive information under greater control.
Technology
Python, LangChain, FAISS, Ollama and Qwen3-VL.
This architecture is suitable for internal documentation, technical inspections, equipment knowledge and other private knowledge bases.
0 likes · 0 views · Nov 20, 2026
A local-first knowledge assistant that retrieves evidence from both written documents and inspection images.


