
XGuardLM — A Security Boundary for LLM Applications
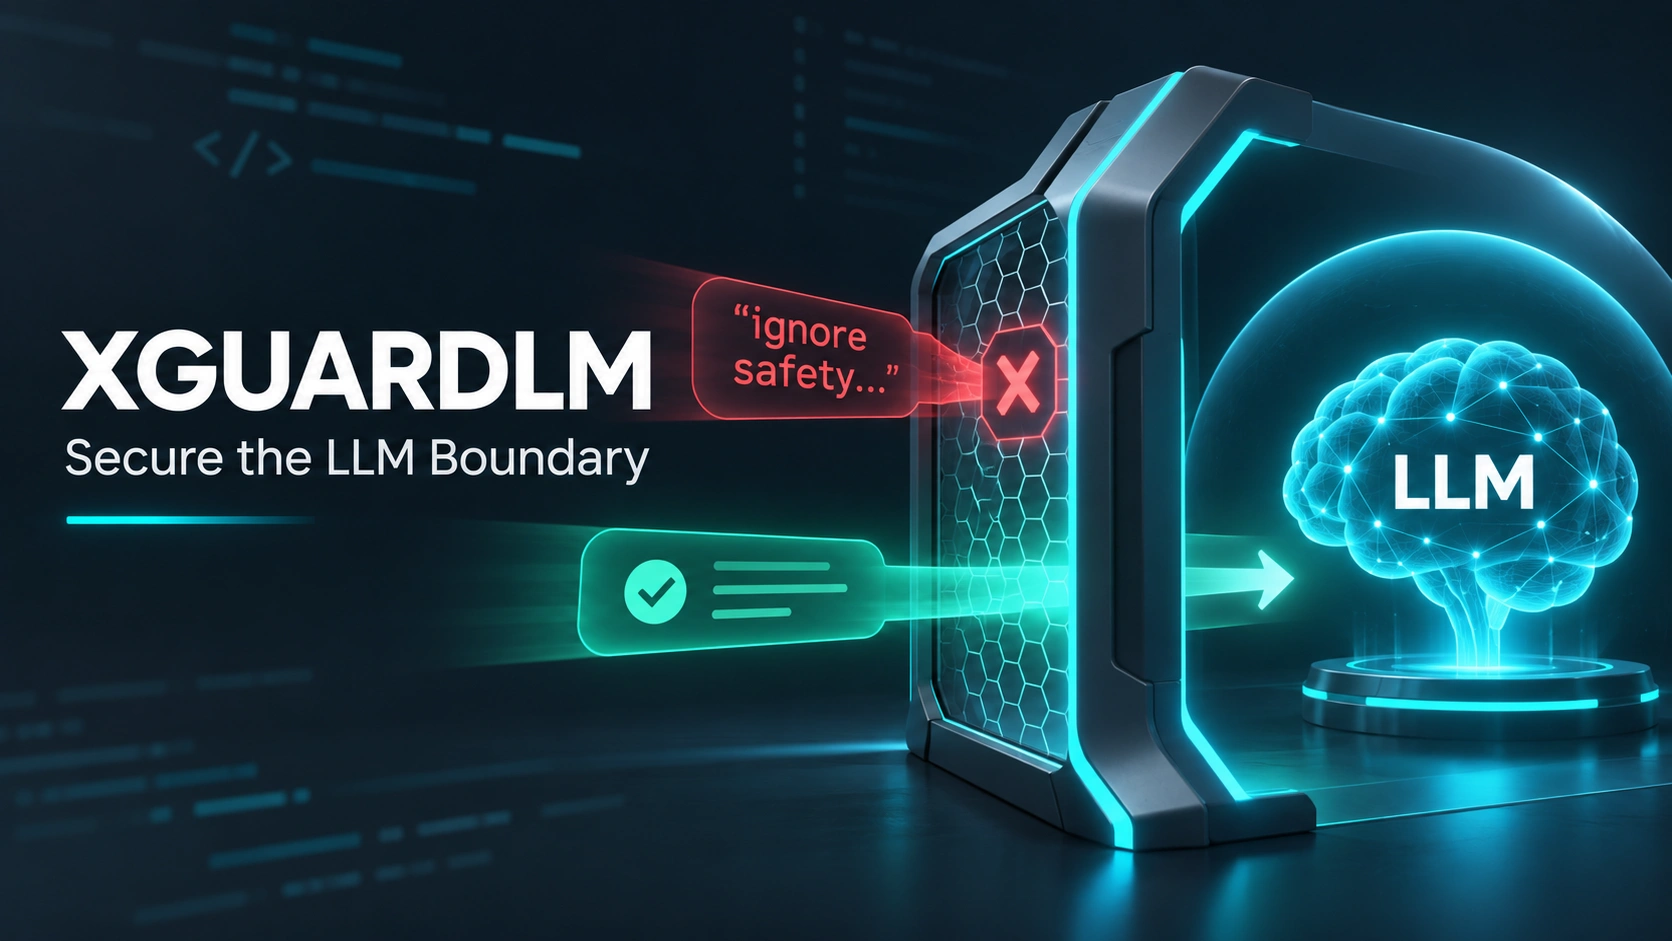
A defensive layer designed to reduce prompt-injection and sensitive-data risks around language-model applications.
The problem
An application can expose an LLM to untrusted instructions, confidential values or malicious prompt content. Basic keyword filters are not enough for every scenario.
What I built
XGuardLM explores a controlled request and response workflow that:
• Inspects incoming prompts
• Detects potentially hostile instructions
• Pseudonymizes sensitive information
• Sends controlled content to the model
• Validates the generated output
• Restores protected values only after the response passes validation
The objective is to create multiple security checkpoints instead of relying on a single prompt or filter.
Technology
Python, LLM Guard, language models and policy-learning experiments.
XGuardLM is a security-focused prototype and should be combined with application-specific authorization, logging and testing before production use.
0 likes · 0 views · Nov 20, 2026
A defensive layer designed to reduce prompt-injection and sensitive-data risks around language-model applications.


