maddie-bench: A Reproducible Structured-Drawing AI Benchmark

Maddie D. Reese

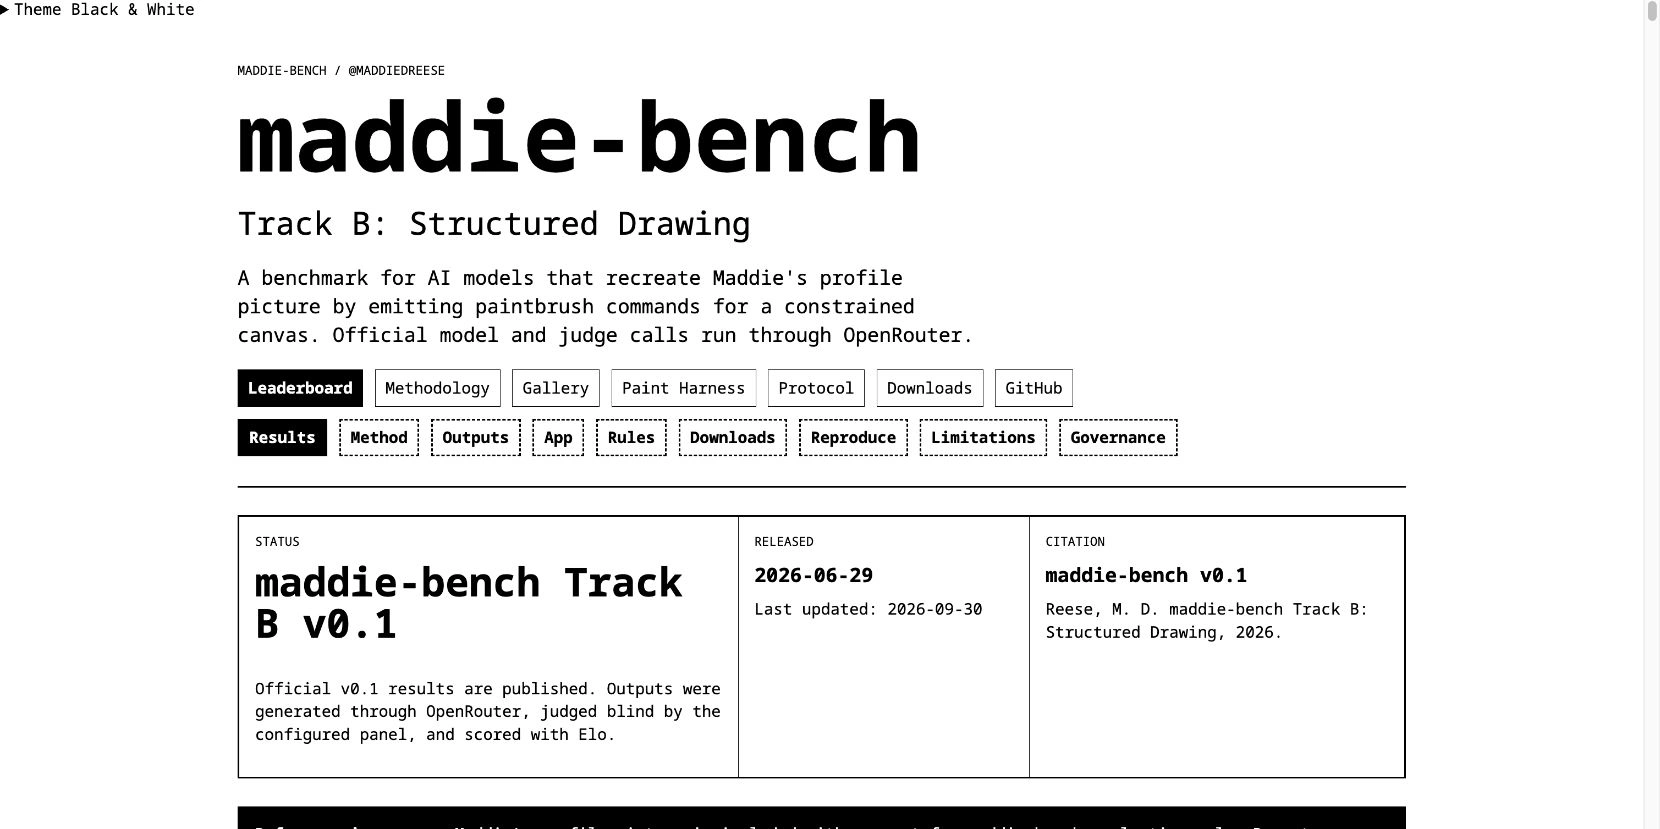
I built maddie-bench to make a specific AI capability visible and inspectable: recreating a reference image through structured drawing commands. Track B asks models to return JSON paintbrush commands for a constrained 1205 × 1448 canvas, with a recommended maximum of 30 commands.
The evaluation pipeline runs model and judge calls through OpenRouter, renders the structured output, and compares blind image pairs using a GPT, Claude, and Gemini judge panel. Elo scoring turns the comparisons into a public leaderboard.
The web experience includes an output gallery, a paint harness with command replay, methodology, downloadable configurations, results, and reproduction steps. Failed attempts remain visible, and audit artifacts help readers inspect the process.
Like this project
Posted Oct 12, 2026
An open-source benchmark with structured drawing outputs, blind panel judging, Elo scores, a public leaderboard, and reproducible evaluation artifacts.
Likes
0
Views
0