
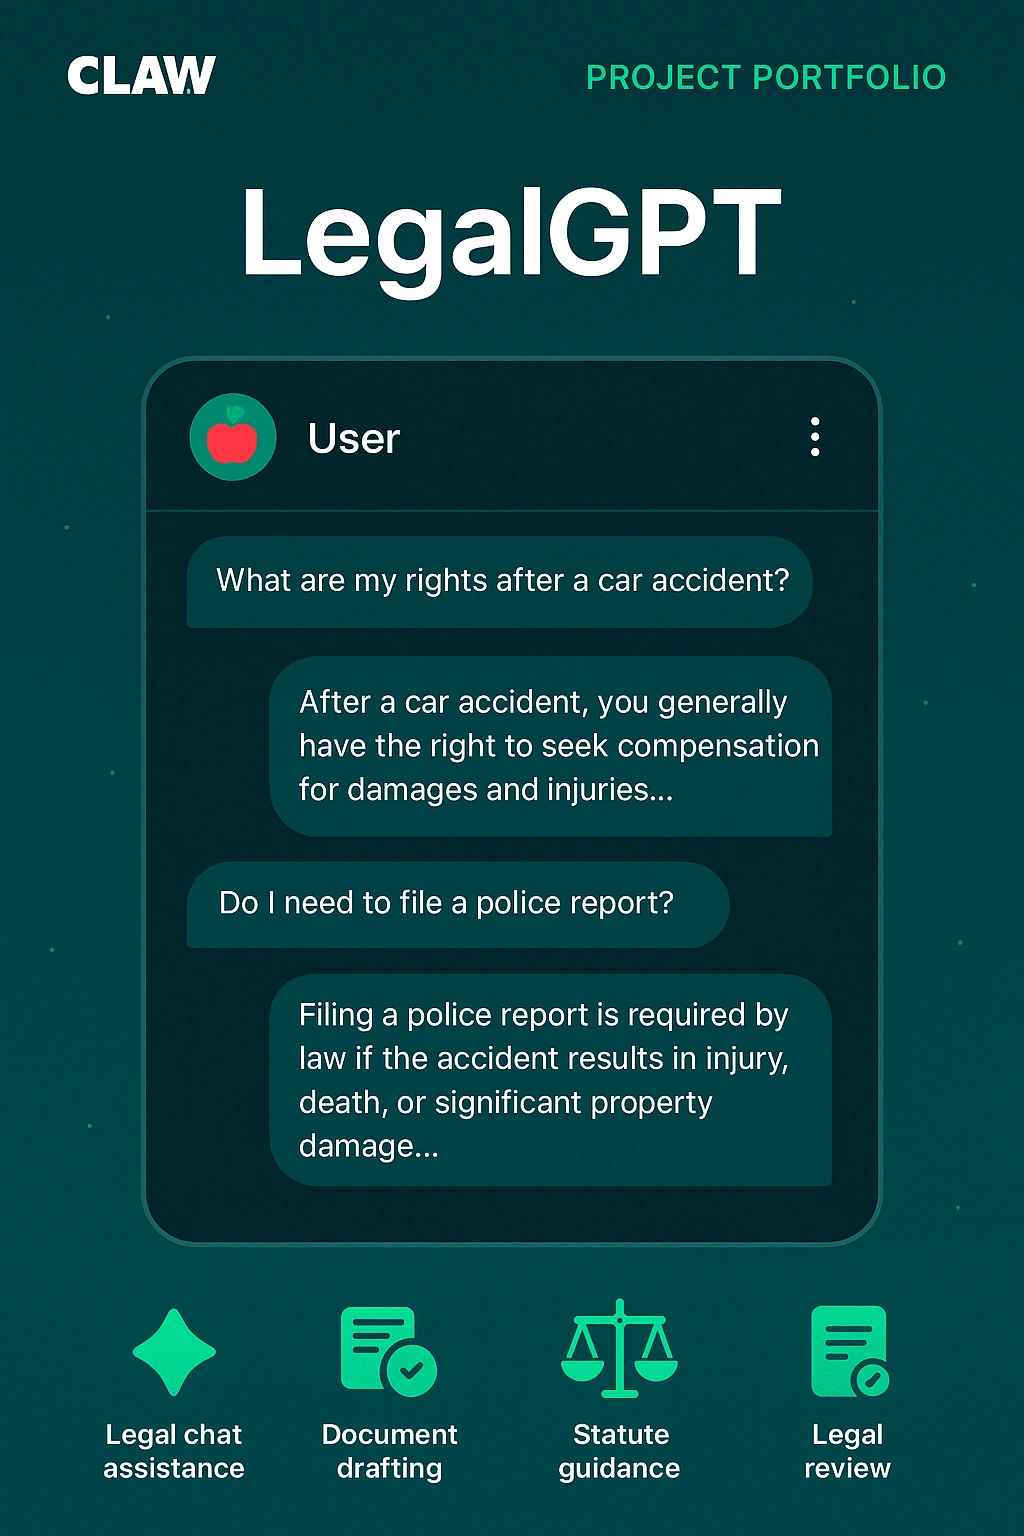
LegalGPT by Claw
Overview:
LegalGPT is Claw LegalTech’s proprietary Generative AI assistant tailored for Indian legal professionals. The tool allows users to perform contextual legal research, draft contracts, and understand court judgments by interacting with a chat-based interface powered by a custom-trained LLM.
At its core, LegalGPT is a hybrid RAG (Retrieval-Augmented Generation) system layered with multiple legal-specific capabilities, including citation insertion, clause extraction, judgment summarization, and precedent suggestion.
Objective:
To build a domain-specific LLM system optimized for legal texts with reliable, up-to-date Indian case law and legislation. The system needed a scalable and maintainable ETL pipeline to handle continuously evolving legal corpora.
ETL Pipeline: Design and Implementation
1. Data Sources
Case Laws: Extracted from Indian judiciary portals (e.g., Indiankanoon, eCourts, Judis)
Statutes and Bare Acts: Scraped from government websites in structured and unstructured formats
Legal Contracts: Anonymized document bank from law firms (PDFs, DOCX, HTML)
Law Firm Blogs and Treatises: Extracted with semantic weighting for relevance
2. Extraction Layer
Built using Scrapy + Playwright for dynamic scraping
Used asyncio-based job runners to schedule crawls for over 200k+ case law documents per month
Integrated
pdfminer and docx parsers for contract ingestion3. Transformation Layer
Data Cleaning: Removal of procedural text, pagination errors, footnotes
Clause and Entity Tagging: Custom spaCy NER pipeline to tag:
Parties, Judges, Court Names, Dates, Citations, Sections
Semantic Chunking: Each case split into:
Facts
Issues
Arguments
Judgments
Stored as structured JSON blobs with metadata
4. Embedding & Vectorization
Used HuggingFace Sentence-BERT (trained on legal domain data) for vector generation
Indexed embeddings into:
Faiss (for local dev/test)
Pinecone (for scalable production RAG search)
Embedding refresh jobs scheduled via Airflow
5. Loading Layer
Metadata stored in PostgreSQL
Vector data in Pinecone
Raw + transformed data backed up in AWS S3 with versioning
Model Layer (LLM & RAG)
Base Model: Mistral 7B / Falcon 7B fine-tuned with QLoRA on legal-specific instruction-tuning tasks
Integrated with LangChain to support:
Prompt templating
Tool invocation (search, summarization, clause generator)
Implemented context window trimming with token-weighting heuristics
Key Features Enabled by ETL
Real-time legal precedent suggestions based on chat queries
Clause-level case law lookup and citation injection
Auto-tagging and classification of uploaded judgments
Legal document QA on contracts with “hallucination prevention” via RAG fallback
Challenges & Solutions
Data volume: Over 2M+ case docs — resolved with asynchronous batching and delta-updates using checksum logic
Document variability: Built rule-based + ML hybrid pipeline for structure detection
Vector index sync: Automated invalidation and refresh pipelines with Faiss ID hash matching
Outcome
LegalGPT reduced legal research time by 80%
Supported drafting of legal arguments with jurisdiction-aware citations
The system is currently used by over 300 lawyers across India in alpha and pilot testing
0 likes · 18 views · Apr 19, 2025
Developed LegalGPT, a Generative AI for Indian legal professionals, reducing research time by 80%.
Timeline
Jan 19, 2021 - Feb 28, 2023

