A lead-discovery engine that runs itself

Lukas Janda


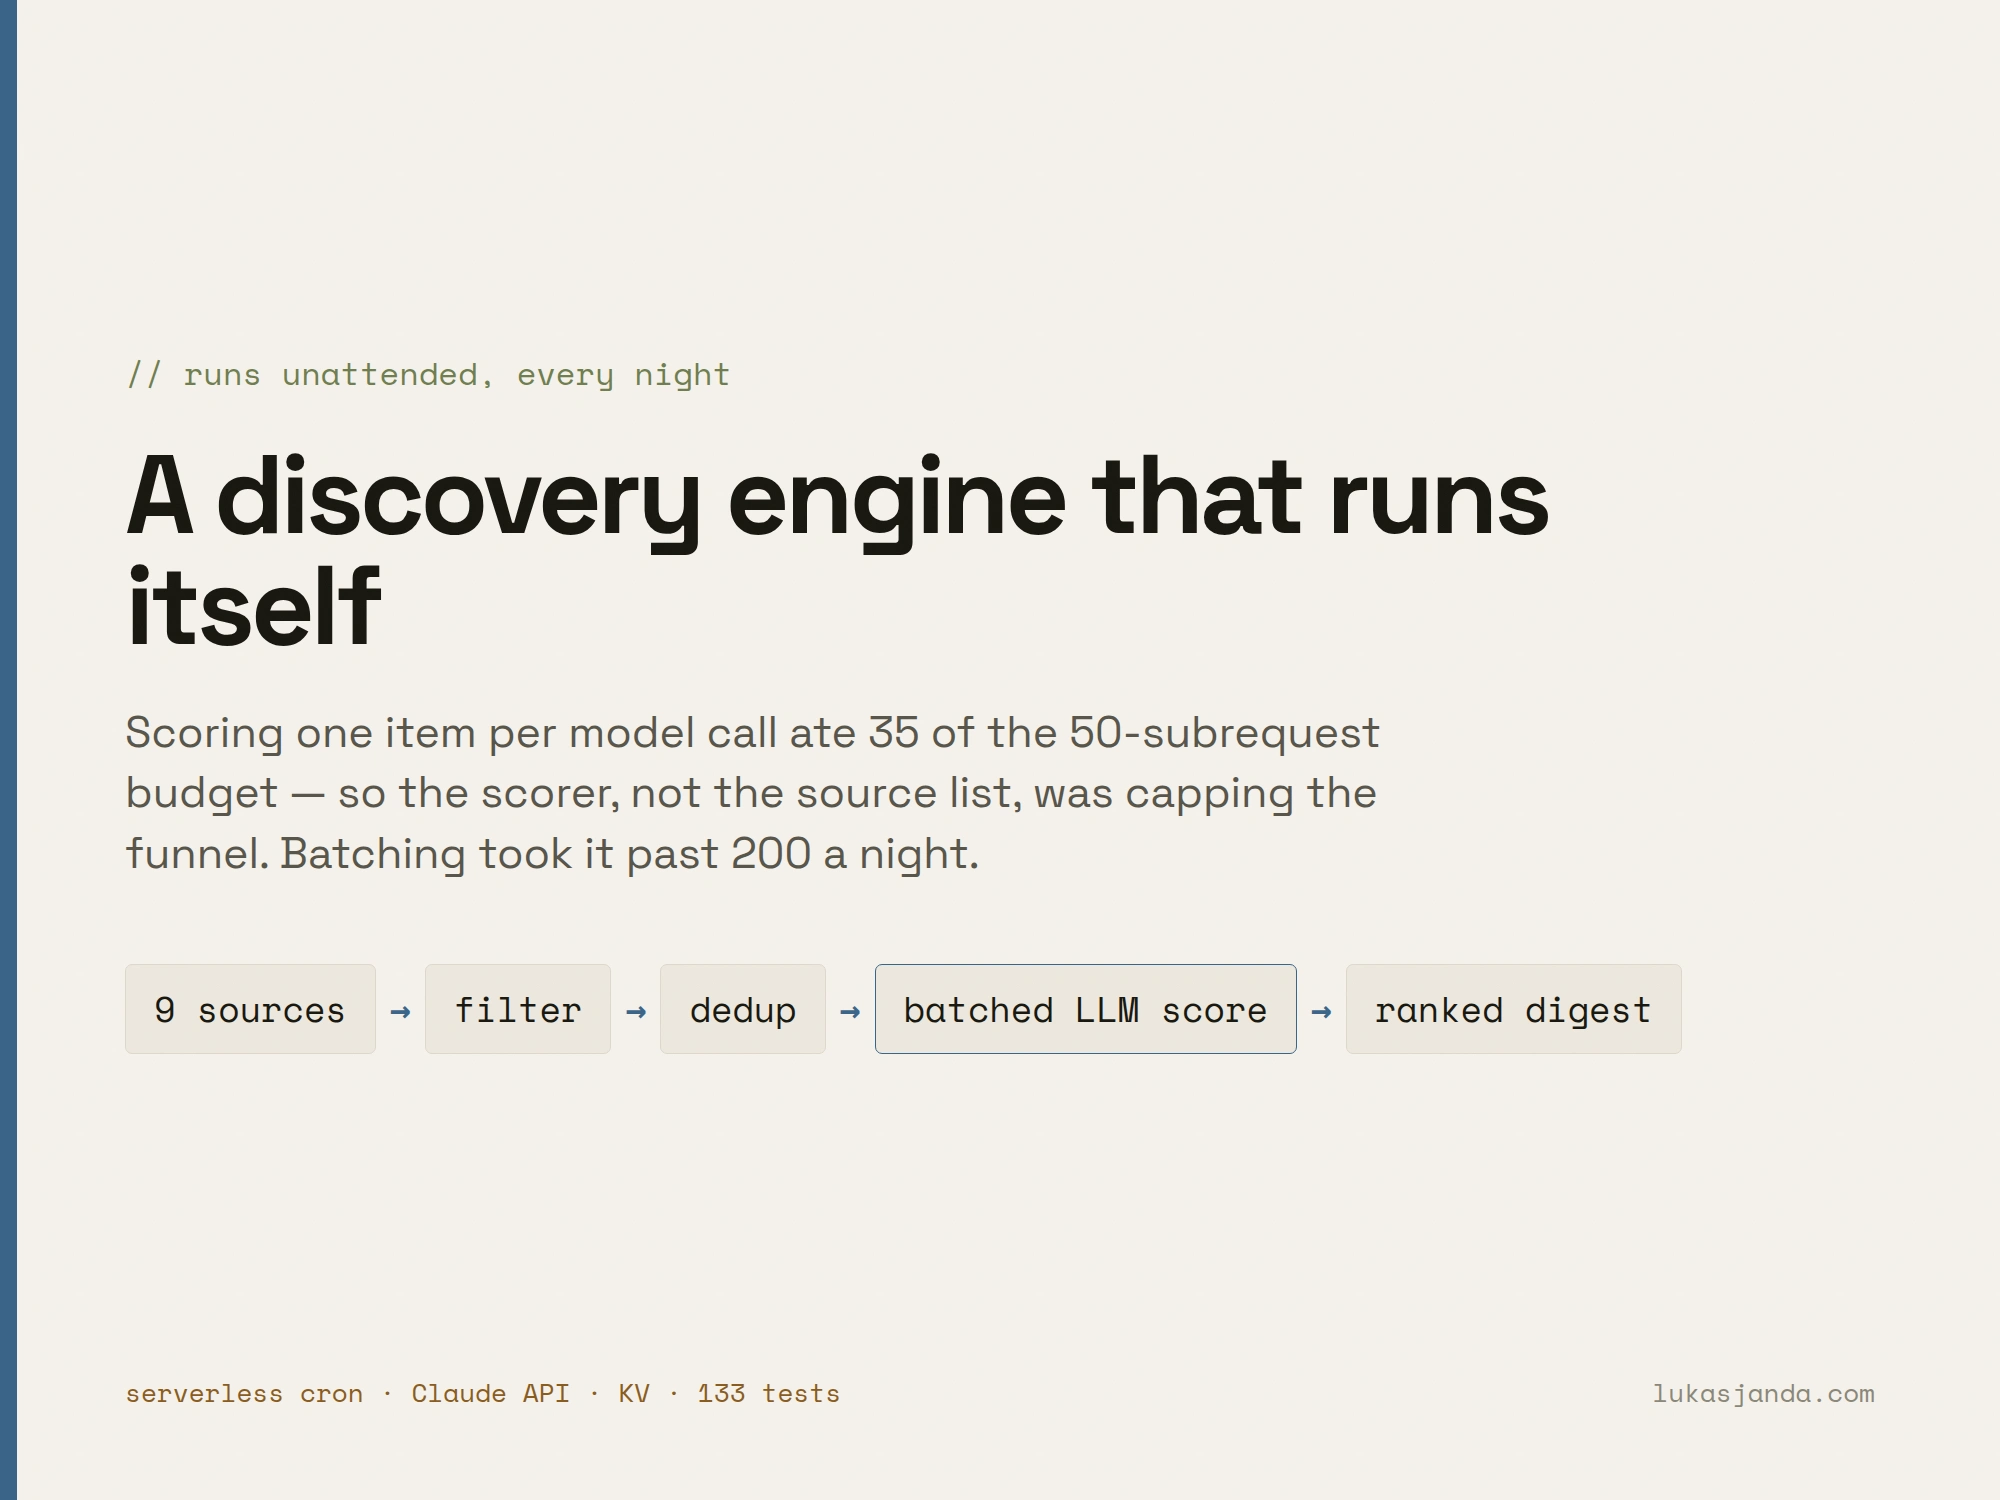
A system I built and run daily, unattended. Nine ingestion sources, a keyword pre-filter, KV deduplication, batched LLM scoring in two independent lanes, and one ranked digest a night. Cloudflare Workers, zero dependencies, 133 tests.
The build was the easy half. What it taught me was operational, and that is the part worth reading.
The scorer was the bottleneck, not the sources
Scoring one posting per model call ate 35 of the platform's 50-subrequest budget. So the scorer — not the source list — was what capped the funnel: adding feeds would only have grown a backlog that aged out before anything looked at it.
Batching ten postings into one call inverted the arithmetic. Throughput went from 35 scored a night to over 200, without adding a single source. A malformed response marks that batch unscored and the items still reach the digest flagged, so a bad reply costs ranking, never data.
"Zero results" was not a broken filter
The system started reporting nothing. The obvious read was that the filter had broken. Measuring instead showed the filter was passing 51% of its inputs correctly — the real fault was a source adapter that had never read the API's page count and had been silently returning exactly half its data on every run since it was written.
That is the case for instrumentation over intuition. The digest now prints a per-source breakdown with the empty sources in bold, because an aggregate count cannot tell a quiet day from a dead adapter.
Where the model was wrong, and what I did about it
The scorer rated a posting 8/10 with the reason "Latin America CET-overlap". The posting said "based in Latin America" twice. It had read a hard geographic exclusion as a note about timezones — and did it four times across different postings.
I had added a prompt rule after the first one. It did not hold. Eligibility is binary, so it stopped being a judgement call: it moved into deterministic code with the real postings as test fixtures, and every mention of region was removed from the prompt — because leaving it in alongside the check made the model swing the other way and invent a restriction on a posting that was fine.
The model scores the work. Code decides who is allowed to do it.
Like this project
Posted Oct 6, 2026
A serverless system that sweeps nine sources nightly, scores what it finds with an LLM in two independent lanes, and mails one ranked digest. Built and operated by me.
Likes
0
Views
0