Mortgage Application Extractor: RAG for 200-Page Loan Files

Joe Estephan


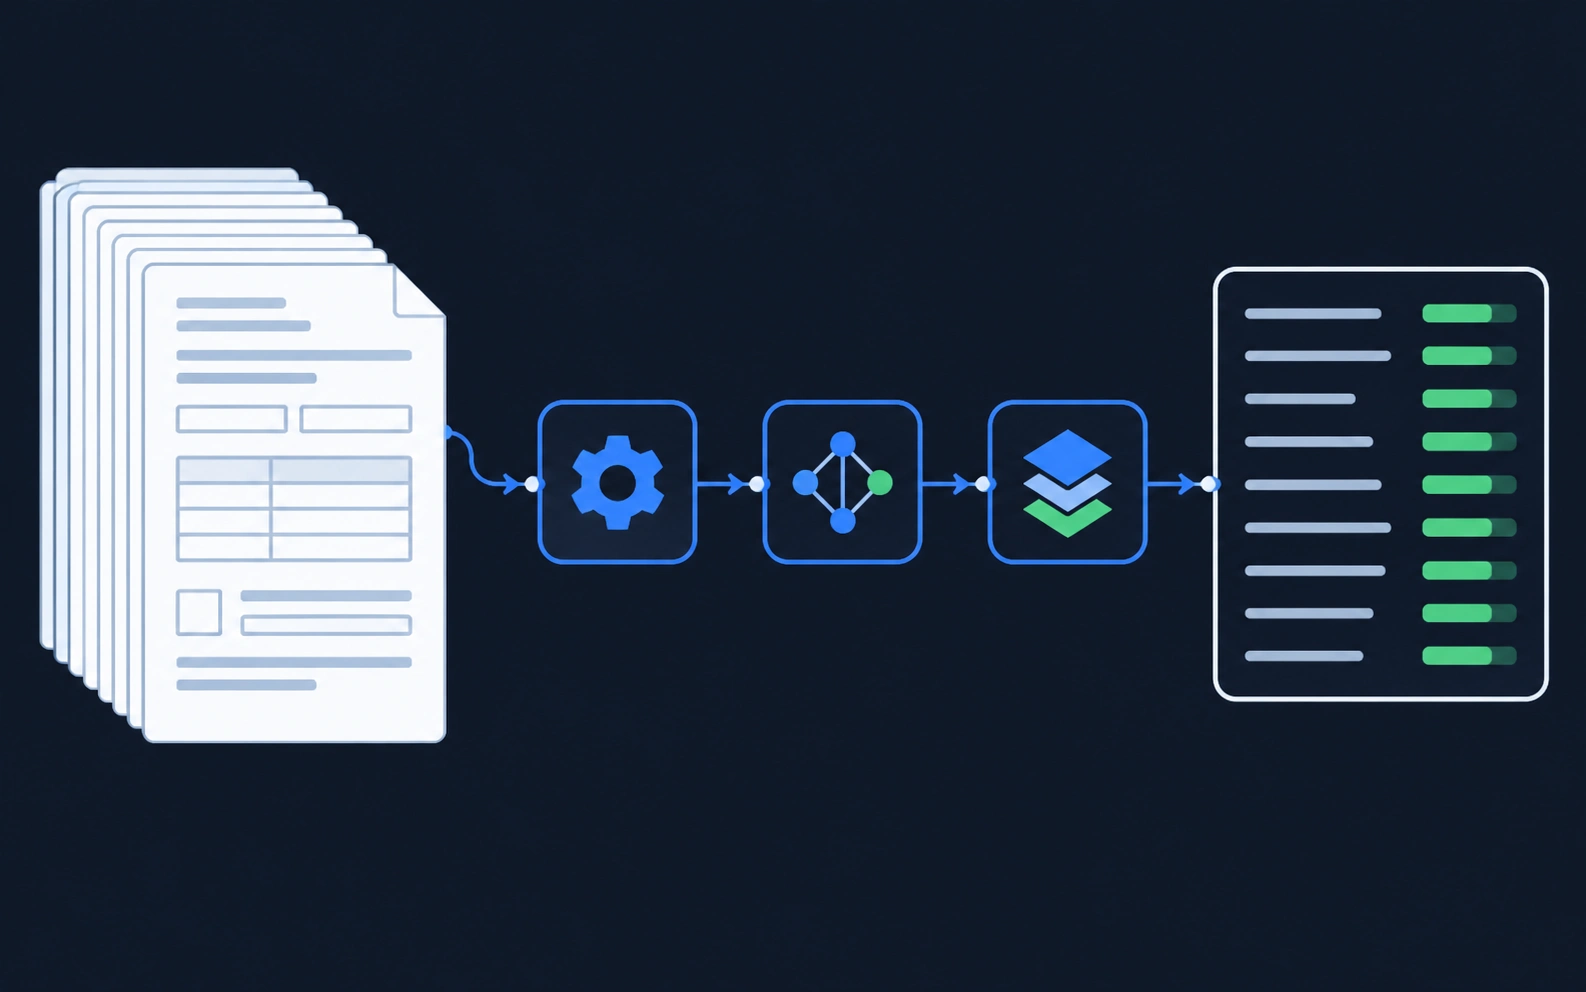
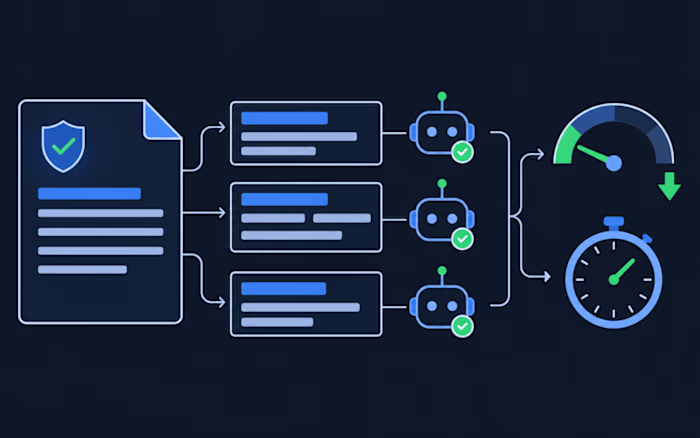
Turns scanned mortgage applications, often 200 pages or more, into one structured data model, with a confidence score on every field.
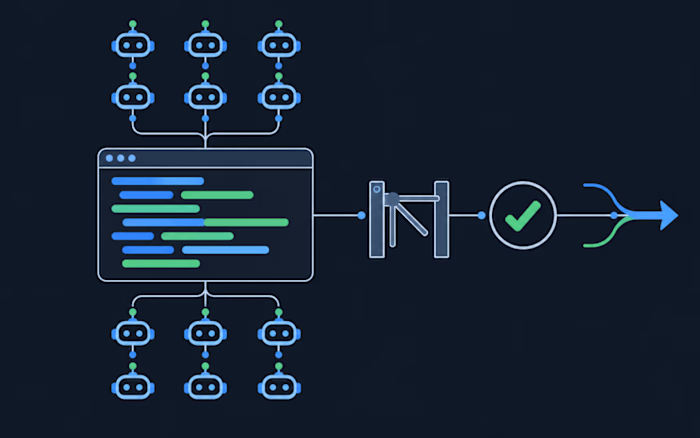
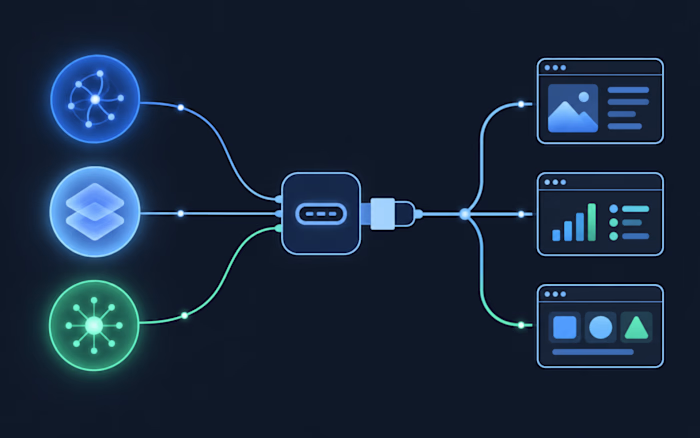
Textract reads the scans with the layout kept and the boilerplate dropped. A small file goes straight to the LLM. A large one is chunked, embedded and stored in Pinecone, so each field's query pulls back only the pages that matter before extraction. Partial results are merged by confidence. Prefect runs the 15 steps with retries and caching, Terraform builds the AWS side, and each step has its own tests.
Like this project
Posted Oct 20, 2026
Scanned mortgage applications of 200+ pages turned into one structured data model, with a confidence score on every field, through OCR, chunking and retrieval.