Deepfake Video Detection System

Fares Sultan


Deepfake-detector-using-BiLSTM-ResNeXt50
Try the Live Demo
Experience the deepfake detector without installation:
Simply upload a video and get instant deepfake detection results!
Overview
Deepfake technology has become increasingly realistic, making it difficult to distinguish manipulated media from authentic content using traditional visual inspection.
This project presents an AI-based deepfake detection system designed to classify video content as either Real or Fake. The system combines face detection and preprocessing, data augmentation, and advanced deep learning techniques to achieve reliable deepfake detection.
The project also includes a Streamlit-based application that provides an interface for testing videos and obtaining a deepfake prediction.
Installation
Prerequisites
Ensure you have the following installed on your system:
Python: 3.8 or higher
pip: Python package manager
Git: For cloning the repository
Step 1: Clone the Repository
Step 2: Create a Virtual Environment
It's recommended to create a virtual environment to avoid dependency conflicts:
On Windows:
On macOS/Linux:
Step 3: Install Required Dependencies
Install all required packages from
requirements.txt:Step 4: Install PyTorch (Optional - if not in requirements.txt)
If you need GPU support or want to specify a specific PyTorch version:
For CPU only:
For GPU (CUDA 11.8):
For GPU (CUDA 12.1):
For other CUDA versions, visit PyTorch.org.
Step 5: Download Pre-trained Models
The project requires two pre-trained models:
YOLOv8 Face Detection Model - Will be automatically downloaded on first use
Deepfake Detector Model - Download from the models directory
Ensure the
models/ directory exists:Download the trained models and place them in the
models/ directory:deepfake_detector.pthYOLOv8.pt (auto-downloads)Project Pipeline
The complete detection pipeline follows these stages:
Main Features
Video-based deepfake detection
Face detection and extraction using YOLOv8
Face preprocessing and augmentation
Fixed-length video frame sequences
Deep visual feature extraction using ResNeXt50
Temporal modeling using Bidirectional LSTM
Binary Real/Fake classification
Video-level prediction
Streamlit web interface for inference
Model confidence calibration using temperature scaling
Configurable prediction threshold
Dataset
The project was developed using multiple publicly available deepfake datasets:
FaceForensics++
Celeb-DF
DeepFake Detection Challenge (DFDC)
The datasets contain both authentic and manipulated videos and were used to build a diverse training and evaluation pipeline.
The original datasets are not included in this repository because of their size and dataset licensing/distribution restrictions.
Data Preprocessing
Before training, videos are processed through a dedicated preprocessing pipeline.
The preprocessing stage includes:
Loading input videos.
Detecting faces using YOLOv8.
Extracting the detected face regions.
Selecting a fixed number of frames from each video.
Applying preprocessing operations.
Applying data augmentation where appropriate.
Preparing the resulting frame sequences for feature extraction.
A fixed sequence of 60 frames per video is used by the classification pipeline.
Face Detection
YOLOv8 is used to locate faces within video frames.
The detected face regions are extracted and prepared for the following stages of the pipeline.
Using a dedicated face detection stage allows the system to focus on facial regions that contain important information for detecting manipulated content.
Feature Extraction
After preprocessing, the extracted frames are passed through ResNeXt50 to obtain high-level visual representations.
For each frame, the feature extractor produces a feature vector of:
The extracted features are stored offline and later used as input to the temporal classification model.
This offline feature extraction approach separates the computationally expensive CNN feature extraction stage from the recurrent training stage.
Temporal Classification Model
The extracted frame-level features are treated as a temporal sequence.
The classification architecture consists of:
The BiLSTM allows the model to learn temporal relationships between consecutive frames rather than treating each frame independently.
The final classifier predicts whether the input video is:
or
Training
The model is trained using video-level data splitting to reduce data leakage between training and evaluation sets.
Key training components include:
BiLSTM-based temporal modeling
AdamW optimizer
Learning rate:
1e-4Label smoothing:
0.05Dropout regularization
Video-level train/validation/test separation
The training pipeline is implemented in the
training directory.Model Configuration
The final temporal model uses:
Component Configuration Input Features 2048 Sequence Length 60 frames Recurrent Layer Bidirectional LSTM LSTM Layers 1 Hidden Size 96 Optimizer AdamW Learning Rate 1e-4 Label Smoothing 0.05 Classification Binary
Usage
Running the Streamlit Application Locally
After installation, you can run the Streamlit web interface:
The application will open in your default web browser at
http://localhost:8501.Online Demo
Try the live hosted demo without installation: Streamlit Cloud Demo
Using the Detection Pipeline Programmatically
Evaluation
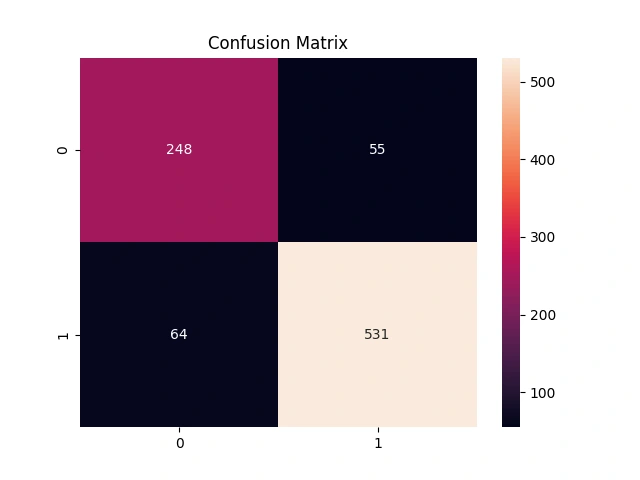
The model was evaluated using multiple classification metrics.
Final Results
Metric Score Accuracy 86.8% Weighted F1-Score 86.7% ROC-AUC 0.93
Confusion Matrix
ROC Curve
LOSS Curve
These results demonstrate the model's ability to distinguish between real and manipulated video content within the evaluated datasets.
Confidence Calibration
The system also applies temperature scaling to improve prediction calibration.
The calibrated temperature value obtained during evaluation was approximately:
A prediction threshold of:
is used by the Streamlit application for the final decision.
Streamlit Application
The project includes a Streamlit application that provides an interactive interface for deepfake detection.
The application allows users to:
Upload a video.
Process the video.
Detect and extract faces.
Generate the required frame sequence.
Extract visual features.
Run the trained temporal model.
Display the prediction and confidence.
Real Video Detection
Fake Video Detection
The application also provides visual feedback during the detection process.
Repository Structure
Directory Description
feature_extraction/
feature_extraction/Contains the offline ResNeXt50 feature extraction pipeline.
models/
models/Contains the trained model weights and YOLOv8 weights when included in the repository.
preprocessing/
preprocessing/Contains the face extraction, preprocessing, and augmentation pipeline.
results/
results/This folder contains the evaluation results and sample outputs of the Deepfake Detection System, including model performance curves, confusion matrix, and Streamlit prediction examples.
streamlit/
streamlit/Contains the Streamlit inference application.
test_videos/
test_videos/This folder contains sample videos for testing the Deepfake Detection System, including real and fake videos.
training/
training/Contains the model training implementation.
Technologies Used
Python
PyTorch
YOLOv8
ResNeXt50
BiLSTM
OpenCV
NumPy
Pandas
Scikit-learn
Streamlit
Limitations
Although the system achieves strong results on the evaluated datasets, deepfake detection remains a challenging problem.
Potential limitations include:
Performance may vary on unseen manipulation techniques.
Dataset distribution can affect generalization.
Highly realistic or newly generated deepfakes may be difficult to detect.
Face-based processing can reduce the amount of contextual information available to the model.
Offline feature extraction separates CNN training from temporal model training.
Future Improvements
Potential improvements to the system include:
End-to-end CNN and temporal model training
Full-frame video analysis
Improved generalization to unseen deepfake generation methods
Transformer-based temporal modeling
More diverse and recent deepfake datasets
Joint spatial and temporal feature learning
Improved robustness against compression and video quality changes
Real-time deepfake detection
Support for image-based deepfake detection
Project Information
This project was developed as a Graduation Project in the Artificial Intelligence department at Sadat Academy for Management Sciences.
The system demonstrates an end-to-end deepfake detection workflow covering:
Disclaimer
This project is intended for research and educational purposes.
Deepfake detection models can produce false positives and false negatives. The system should therefore be considered an AI-assisted detection tool rather than definitive proof that a video is authentic or fake.
Users bear full responsibility for the use of this project and any consequences resulting from its use.
Results at a Glance
Task: Deepfake Video Detection
Classes: Real / Fake
Frames: 60 per video
Features: 2048-D ResNeXt50
Temporal: Bidirectional LSTM
Accuracy: 86.8%
F1-Score: 86.7%
AUC: 0.93
Calibration: Temperature Scaling
Like this project
Posted Sep 28, 2026
Developed an AI system using BiLSTM and ResNeXt50 for deepfake video detection.
Likes
0
Views
0
Clients
Sadat Academy for Management Sciences