
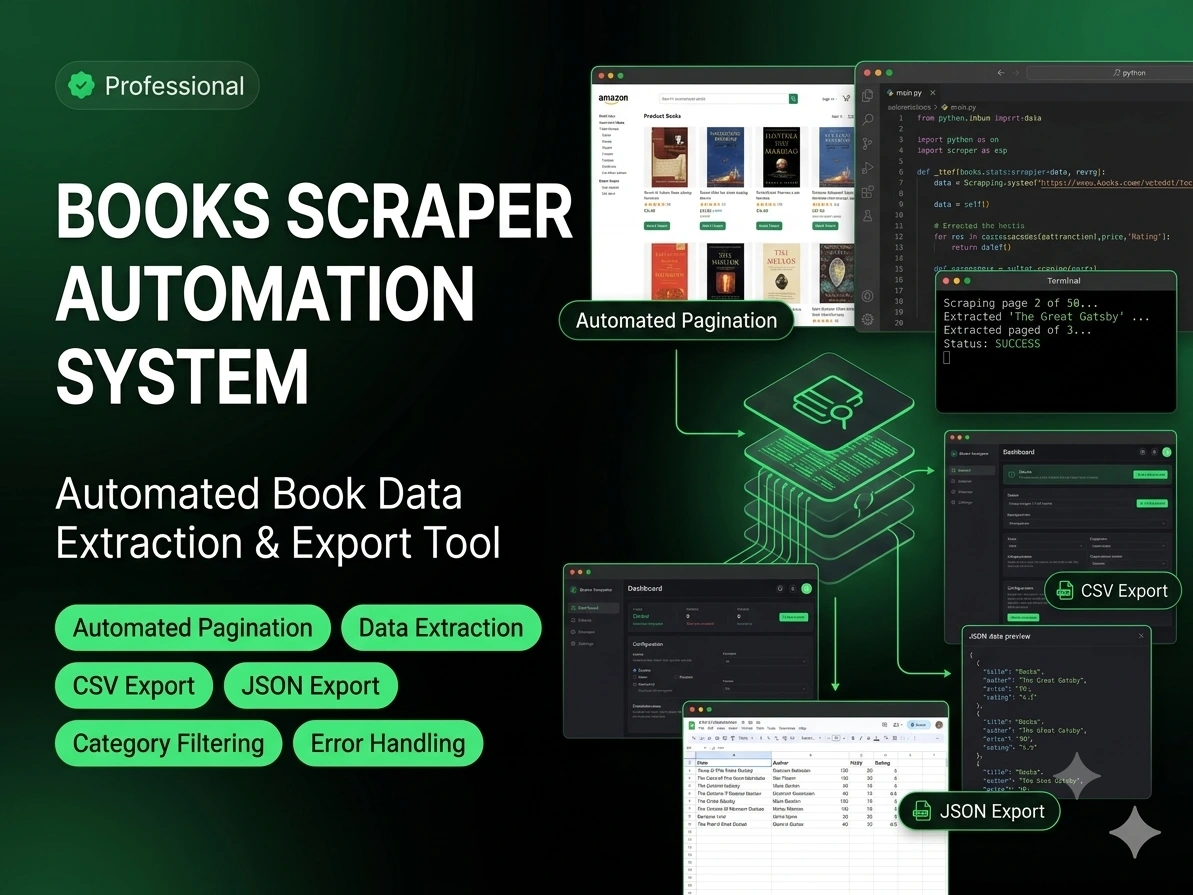
Built a Python-based web scraping system that automates the extraction of book data from a multi-page online catalog.
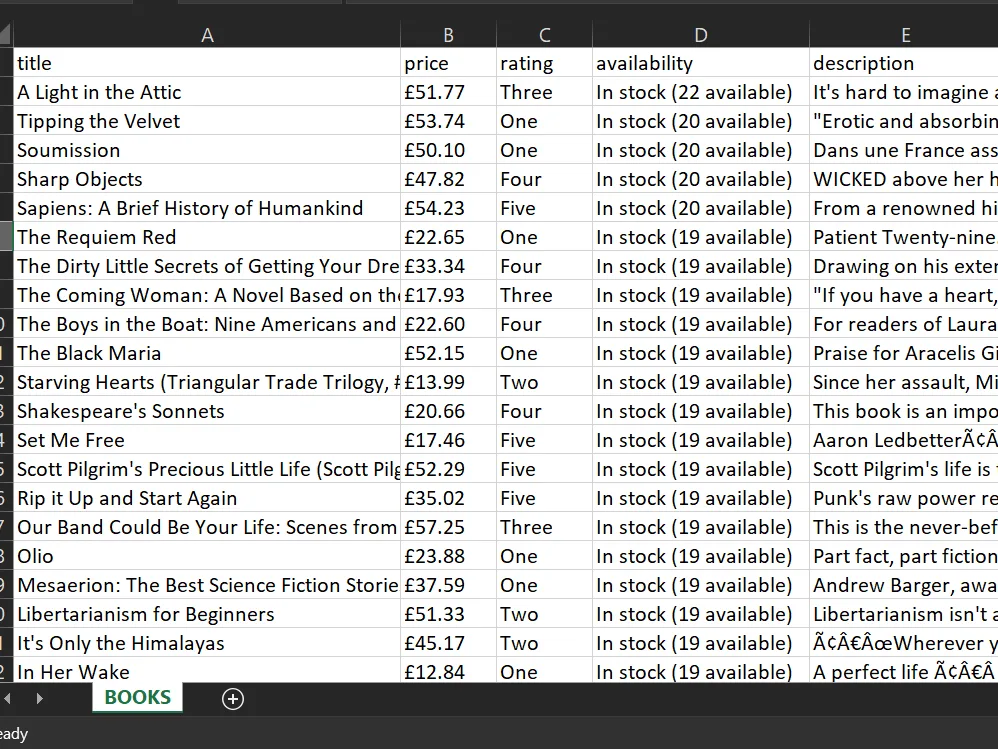
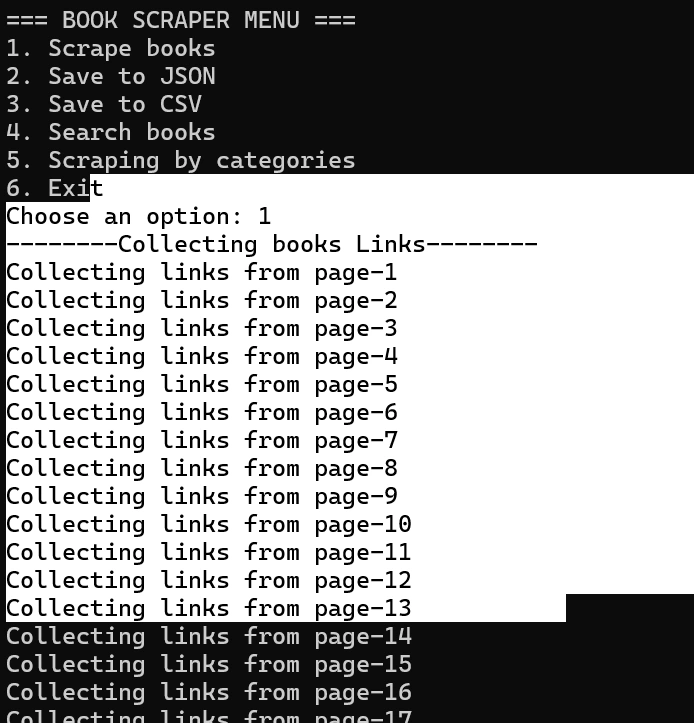
The scraper efficiently navigates paginated pages, collects product links, extracts structured information, and exports clean datasets in both CSV and JSON formats.
Key Features:
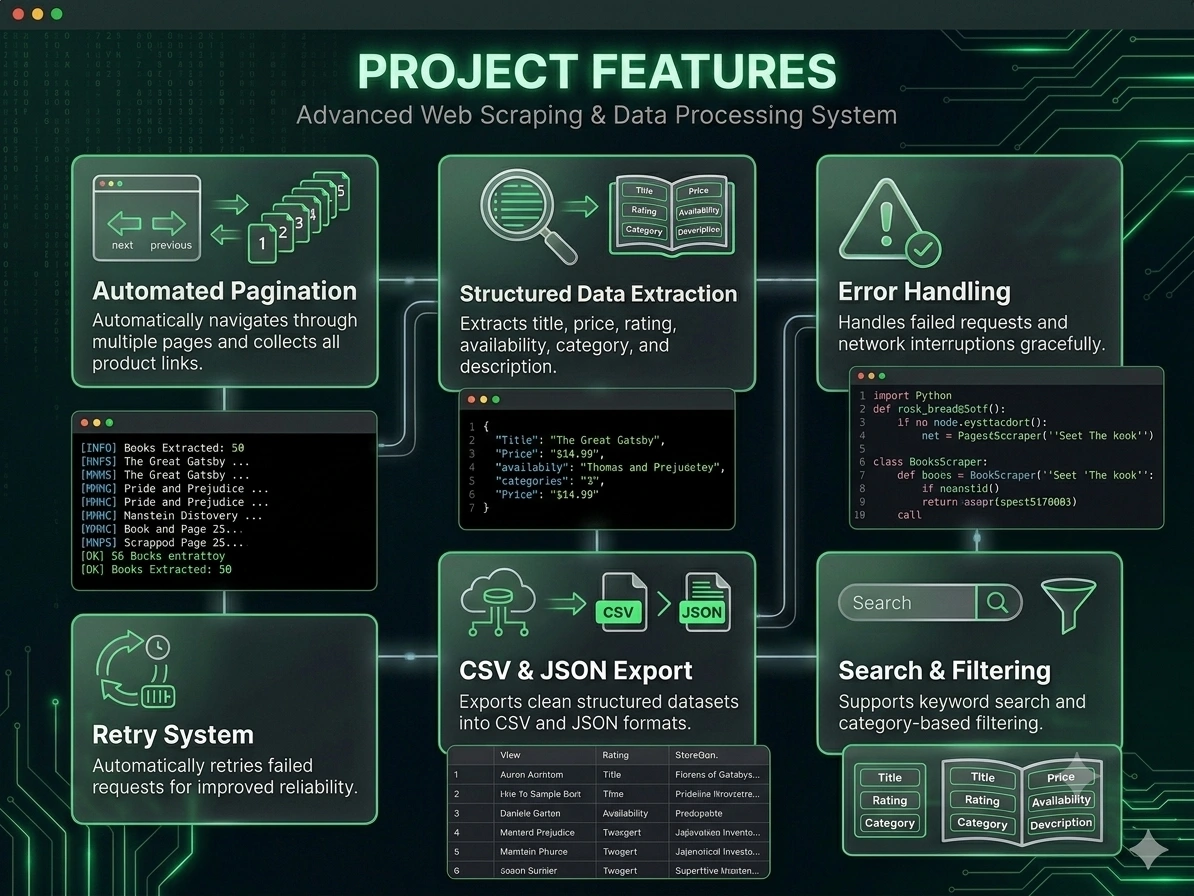
• Automatic pagination handling • Category-based filtering • Keyword search functionality • Retry mechanisms for failed requests • Robust error handling • Structured data export for analysis and integration
Extracted Data:
• Book title • Price • Rating • Availability status • Product description • Category • Product URL
Tech Stack:
Python | Requests | BeautifulSoup | CSV | JSON
This project strengthened my understanding of web scraping architecture, data extraction pipelines, HTML parsing, and building resilient automation systems.
#Python #WebScraping #DataExtraction #Automation #BeautifulSoup #Requests #DataEngineering #SoftwareDevelopment #OpenToWork #FreelanceDeveloper
0 likes · 0 views · Jun 24, 2026
Built a Python-based web scraping system that automates the extraction of book data from a multi-page online catalog. The scraper efficiently navigates pagin...
Timeline
Mar 15, 2026 - Apr 13, 2026
