Trace the Ace: Predicting Tutoring Outcomes

Arqam Ali


Trace the Ace: Predicting Tutoring Outcomes
Developed a predictive NLP pipeline to determine if students would answer tutoring questions correctly based on transcript data. The model achieved a 0.6138 log loss, placing in the top 20% (Rank 228 of 1,150) of a global DrivenData competition.
Key Architectural Decisions:
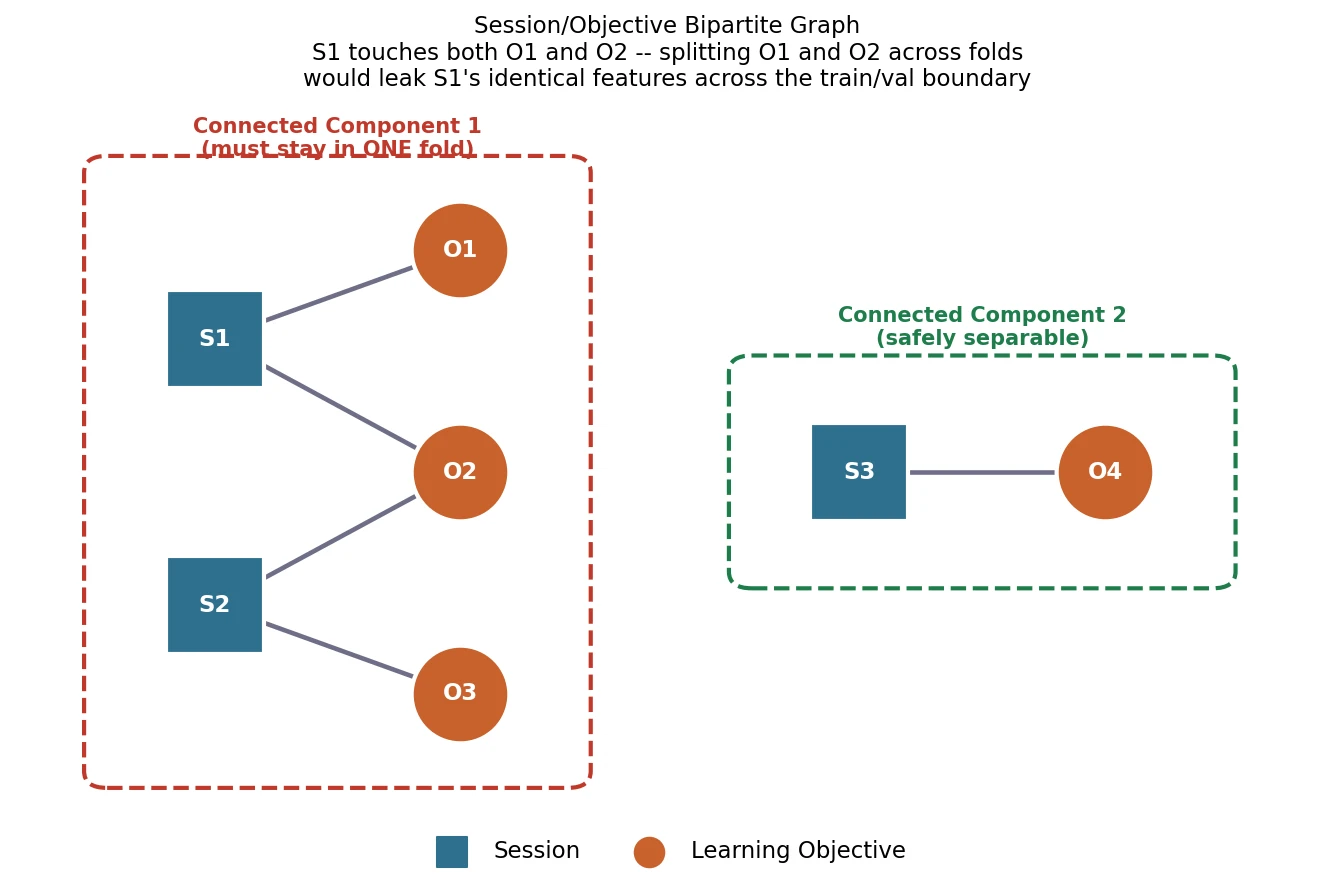
Graph-Based Leakage Prevention: Discovered that 59% of the dataset contained overlapping session data. I modeled the sessions as a bipartite graph to isolate connected components, ensuring strict, leak-free cross-validation.
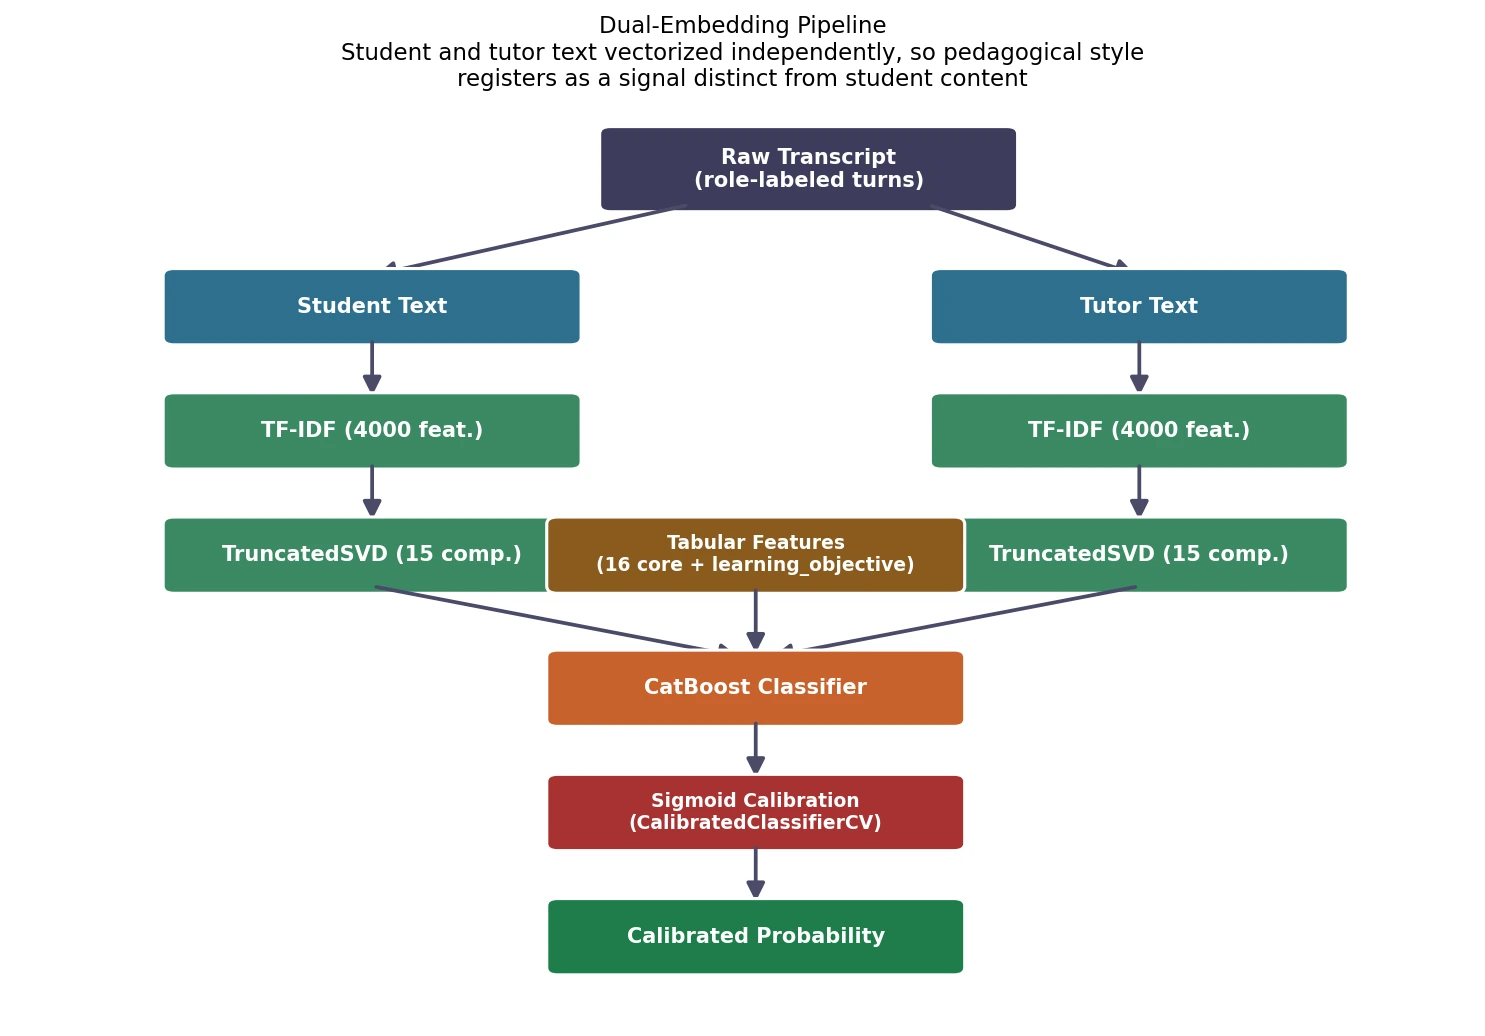
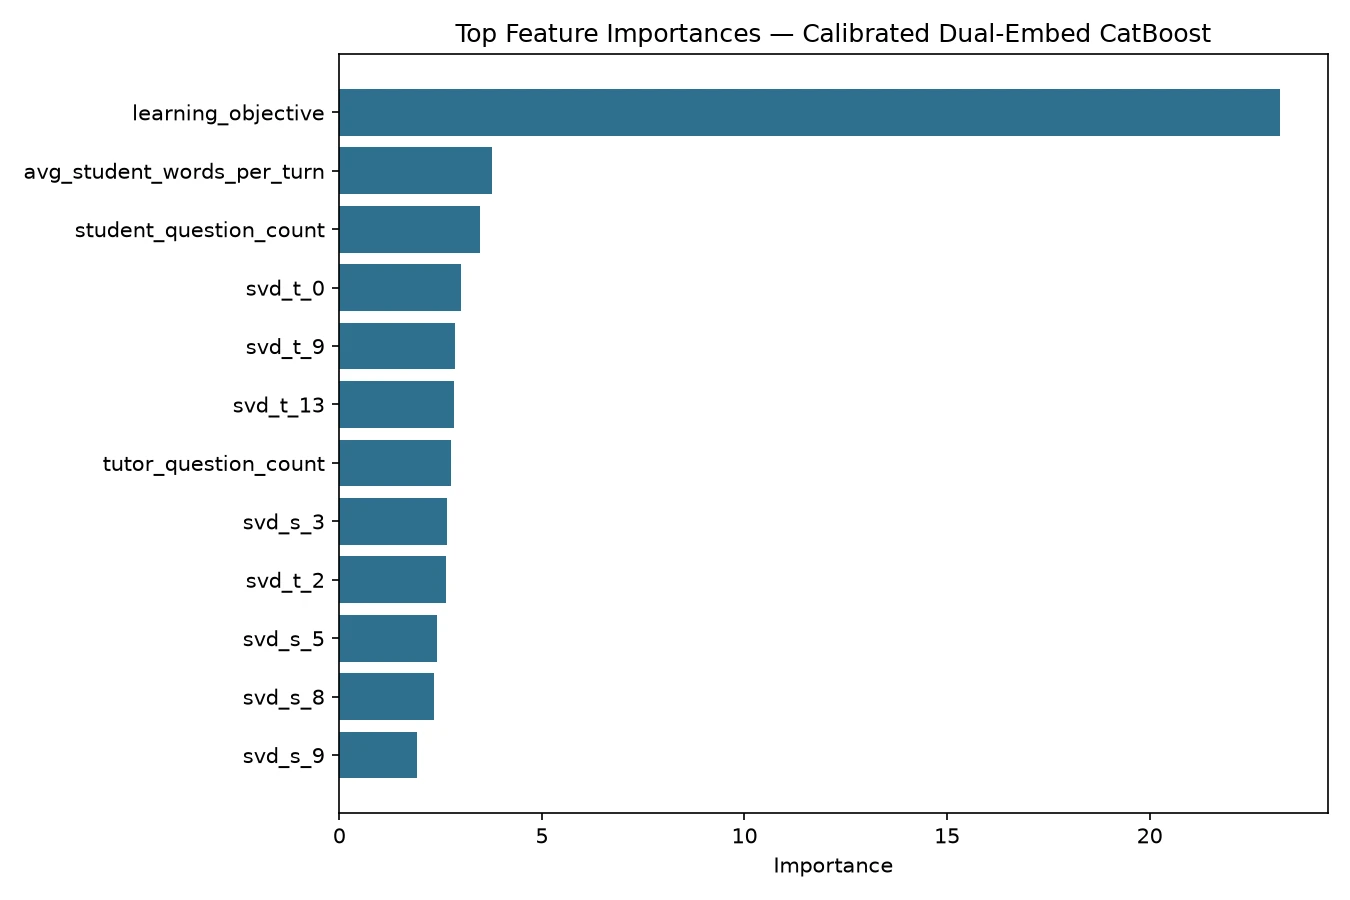
Dual-Stream NLP: Rather than mixing transcript text, I built a split architecture that vectorized student and tutor speech independently. This isolated pedagogical intent from student content.
Calibrated Probabilities: Applied sigmoid calibration to a CatBoost classifier to heavily penalize confidently wrong predictions, optimizing for the strict evaluation metric.
Tech Stack: Python, CatBoost, Scikit-learn, NLP (TF-IDF/TruncatedSVD).
Full methodology and reproducible codebase available on my GitHub.
Like this project
Posted Sep 24, 2026
Built a top 20% predictive NLP architecture to forecast student success. Utilized dual-stream text vectorization and graph-based data leak prevention.