Case Study 2: Zero Trust Gateway
Cybersecurity
Zero Trust Architecture
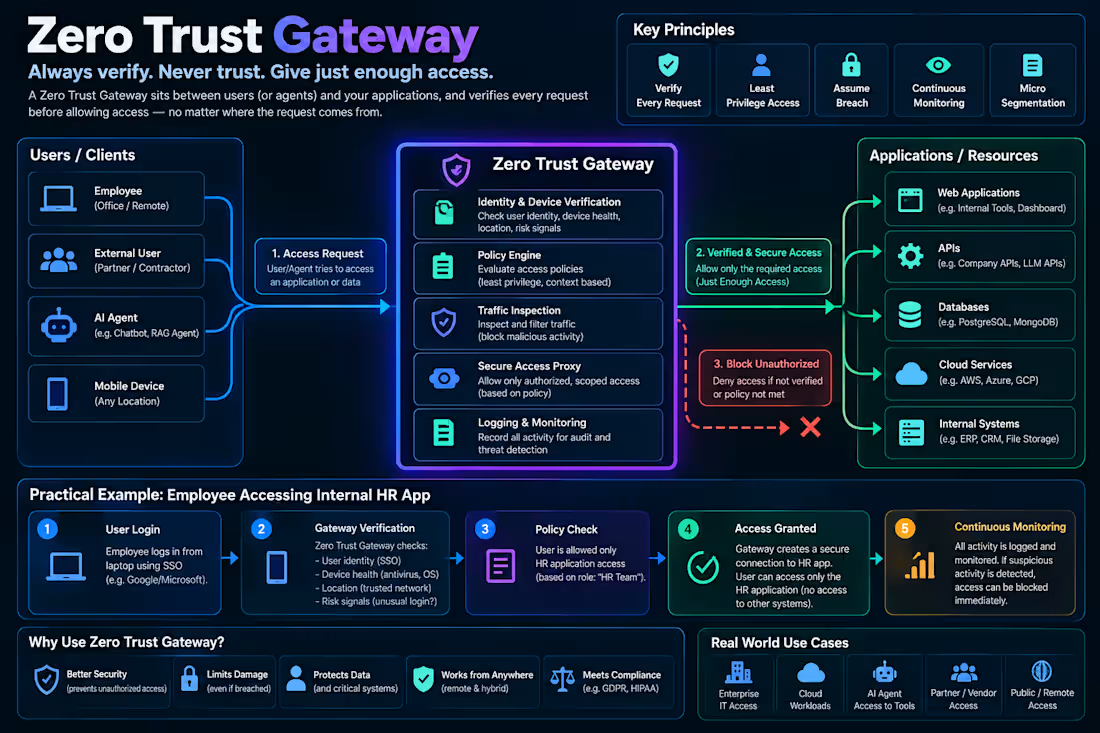
Project: Zero Trust Gateway — Identity-Aware Access Control and Continuous Verification
Problem
Traditional network security often relies on trusted internal networks. However, remote access, compromised credentials and vulnerable devices can expose sensitive applications and data.
Proposed Solution
A Zero Trust Gateway that verifies every access request using identity, device health, contextual information and access policies before granting access to protected resources.
System Architecture
Access request: An employee, external user or AI agent requests access.
Identity verification: Authenticate the user's identity through an identity provider.
Device verification: Check device security status and compliance.
Policy engine: Evaluate access permissions, location and risk signals.
Access control: Grant limited access or deny the request.
Continuous monitoring: Log activity and detect suspicious behavior.
Technology Stack
Python and FastAPI
OAuth 2.0 / OpenID Connect
PostgreSQL
Redis
Docker
Policy-based access control
Key Features
Identity-based authentication
Least-privilege access
Device posture verification
Context-aware access policies
Centralized audit logs
Session monitoring and revocation
Practical Example
An employee attempts to access an internal HR application from a remote laptop.
The gateway verifies the employee's identity.
It checks whether the device meets security requirements.
The policy engine confirms the employee belongs to the HR team.
If all requirements are satisfied, access is granted only to the HR application.
Suspicious activity can trigger additional verification or access revocation.
Expected Outcome
A security gateway that reduces unauthorized access and limits the potential impact of compromised accounts or devices.
Real-world applications
Enterprise networks
Cloud infrastructure
Remote employee access
API security
AI agent access control
Project Impact
The gateway demonstrates how identity, device trust and access policies can work together to protect modern applications.
Conceptual case study; security effectiveness requires implementation, penetration testing and validation.
0
24
Case Study 1: AgentTape
AI Engineering
Agent Observability
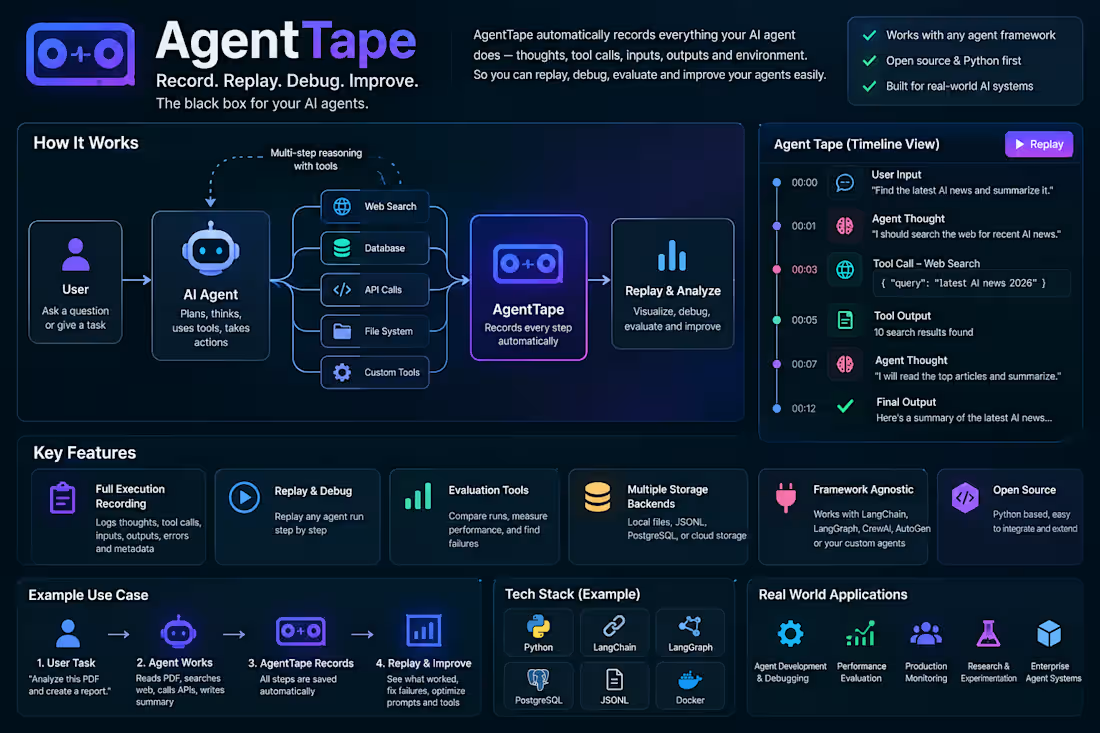
Project: AgentTape — AI Agent Execution Recording, Replay & Debugging System
Problem
AI agents perform multiple tasks using LLMs, APIs, databases and external tools. When an agent produces an incorrect result or fails, identifying the exact cause can be difficult.
Proposed Solution
AgentTape is a Python-based observability system that records AI agent executions and allows developers to replay and debug them.
System Architecture
Input: Receive a task from the user.
Agent execution: The AI agent reasons, calls tools and processes data.
Recording: AgentTape captures tool calls, inputs, outputs, errors and execution events.
Replay: Developers review previous executions step by step.
Evaluation: Compare different runs to identify failures and improve performance.
Technology Stack
Python
LangChain and LangGraph
PostgreSQL and JSON
Docker
LLM APIs
Key Features
Complete execution tracing
Step-by-step replay
Error detection and debugging
Agent performance evaluation
Execution history and analytics
Expected Outcome
A reusable observability layer that helps developers understand agent behavior, troubleshoot failures and improve the reliability of AI applications.
Real-world applications
AI customer support agents
Autonomous research agents
AI workflow automation
Enterprise AI systems
Project Impact
AgentTape aims to make complex AI agent workflows more transparent, traceable and easier to maintain.
Conceptual case study; performance improvements require implementation and testing.
0
19
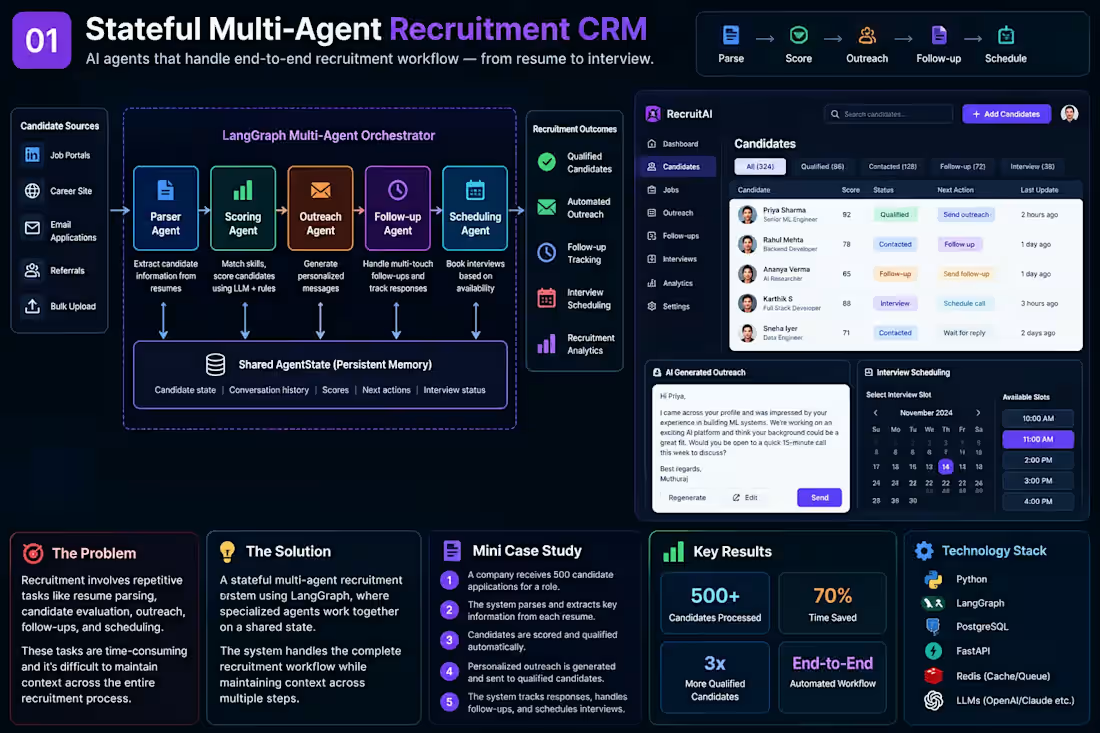
Stateful Multi-Agent Recruitment CRM — Case Study
The Challenge
Recruitment loses quality through context loss. Resume parsing, scoring, outreach, follow-ups, and scheduling are separate workflows. Agents don't share candidate state → conflicting messages, duplicate follow-ups, missed scheduling windows.
The Solution
LangGraph multi-agent orchestrator with 5 specialized agents + shared persistent memory.
Agent breakdown:
Parser Agent → Extract skills, experience, fit signals from resumes
Scoring Agent → LLM-based ranking (not rule-based scores)
Outreach Agent → Generate personalized LinkedIn/email messages
Follow-up Agent → Handle multi-touch cadence, track responses
Scheduling Agent → Book interviews, avoid conflicts
Critical architecture: Shared AgentState
All agents read/write to the same state → no context switching.
The Positioning
Headline: "AI agents that handle end-to-end recruitment workflow — from resume to interview."
Value props:
"Stateful" → Agents don't repeat work; they know what happened to each candidate
"Multi-Agent" → Specialized agents → better performance than monolithic LLM
"End-to-End" → Parse → Score → Outreach → Follow-up → Schedule (no manual handoffs)
Metrics They Lead With
Metric Result Candidates Processed 500+ Time Saved 70% Qualified Candidates 3x more Workflow Fully Automated
Mini case study in the image:
Input: 500 candidate applications
Parse: Extract info automatically
Score: Rank candidates (50% filtered out)
Outreach: AI-generated, personalized messages
Follow-up: Automated multi-touch
Result: 3x more qualified candidates reach interview
Dashboard UX
Right panel shows:
Candidates list with: Score (92, 78, 65), Status (Qualified, Contacted, Follow-up), Next Action, Last Update
AI-Generated Outreach sample → Shows quality of personalization (candidate name, specific role match)
Interview Scheduling → Visual calendar, slot selection
UX insight: Dashboard surfaces actions (Send outreach, Schedule call), not just metrics.
Tech Stack (Why It Matters)
LangGraph → Agent orchestration + state management (core to stateful workflows)
PostgreSQL → Persistent candidate state (not ephemeral)
FastAPI → Scalable API layer
Redis → Cache for scoring/matching
LLMs (OpenAI/Claude) → Parsing, scoring, outreach generation
Why this stack wins:
Agents can be tested independently (Scoring Agent accuracy measured separately)
State persists across failures (retry-safe)
Scalable to 1000+ parallel workflows
What You Should Copy
1. Architecture
Don't build a monolithic "recruitment AI." Build 5 focused agents, each optimized for one task. Let LangGraph manage the handoffs.
2. State Management
The shared AgentState is the moat. Without it:
Outreach Agent doesn't know candidate was already contacted
Scheduling Agent double-books
Follow-up Agent sends duplicate messages
Action: If building recruitment or SDR automation, design shared state first. Agents second.
3. Positioning Shift
RudraStack: "Automate follow-ups" (feature-first)
This system: "End-to-end workflow" (outcome-first) + "Stateful agents" (technical credibility)
Result: Attracts technical buyers (CTOs, engineering orgs) + recruiters who care about quality.
4. Metrics Hierarchy
Output quality (3x more qualified candidates)
Time saved (70%)
Volume (500+ processed)
Most tools lead with volume. This leads with quality first.
Competitive Edge for Your Stack
vs. RudraStack:
RudraStack: Dashboard-first, lead quantity focus
This system: Agent-first, candidate quality focus
vs. Traditional ATS:
Stateful agents = no lost context
LLM-driven scoring = learns from outcomes
Multi-agent = modular and debuggable
Technical Differentiation You Could Build
Agent fine-tuning → Specialized models for Parser/Scoring agents (better accuracy than GPT-4 for resume parsing)
Feedback loop → Track which outreach messages → interviews → placements. Retrain Outreach Agent.
Multi-source orchestration → LinkedIn sources + Career portal sources + Referrals, all in shared state
Real-time scoring updates → As follow-up responses come in, re-score candidates (dynamic ranking)
Quick Tactical Win for Your AI-SDR
Apply this to your staffing agency outreach:
Replace your SDR follow-up system with a Follow-up Agent that reads shared candidate state
Add a Conversation Analysis Agent that scores email replies (Intent: Interested? Unsubscribe? Dead-end?)
Route high-intent replies to Scheduling Agent automatically
Result: 3x faster sales cycle because context isn't lost between touch points.
0
25
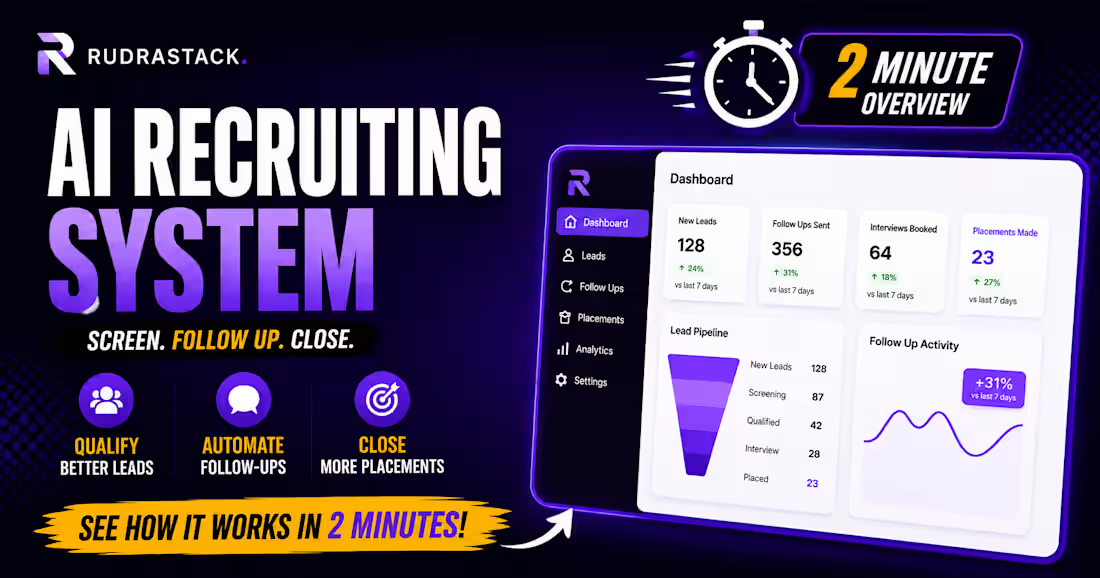
RudraStack AI Recruiting System — Case Study
The Challenge
Staffing agencies lose placements through manual follow-up bottlenecks. Sales teams qualify 128 leads/week but convert only 18% to interviews and 8% to placements. Each follow-up is friction.
The Solution
RudraStack automated the qualification → follow-up → placement workflow with a funnel-focused dashboard that surfaces three metrics:
Lead quality score (Screen phase)
Follow-up cadence (Automate phase)
Close velocity (Close phase)
The Positioning
Tagline: "Screen. Follow Up. Close."
Value prop stack:
"Qualify Better Leads" (lead scoring, not volume)
"Automate Follow-Ups" (remove manual scheduling friction)
"Close More Placements" (optimize handoff to sales)
Metrics They Led With
Week-over-week growth (vs. absolute numbers):
New Leads: +24%
Follow-Ups Sent: +31%
Interviews Booked: +18%
Placements Made: +27%
Dashboard KPIs: 128 → 87 → 42 → 28 → 23 (transparent funnel decay)
Why This Works
Funnel transparency — Agencies see where they leak (87→42 is biggest drop = qualification problem)
ROI-first messaging — "Placements Made" as headline metric, not efficiency scores
Growth narrative — Week-over-week % (not flat counts) creates urgency
Speed as trust signal — "2-Minute Overview" reduces time-to-value perception
What You Should Copy
Lead with the result metric (placements/closes), not the process (leads screened)
Show funnel stages visually so clients can diagnose their own bottleneck
Use week-over-week %, not absolute numbers, for acquisition copy
Dashboard-first positioning (not API/integration first)
Competitive Angle for Your Stack
If you're building against RudraStack:
Differentiate on: LinkedIn-native workflows (vs. dashboard upload), higher qualification accuracy (vs. volume automation), or lower cost
Own what they gloss over: What's the actual qualification logic? Why does 87→42 leak? Better LLM-based scoring?
0
33