Jaden Green
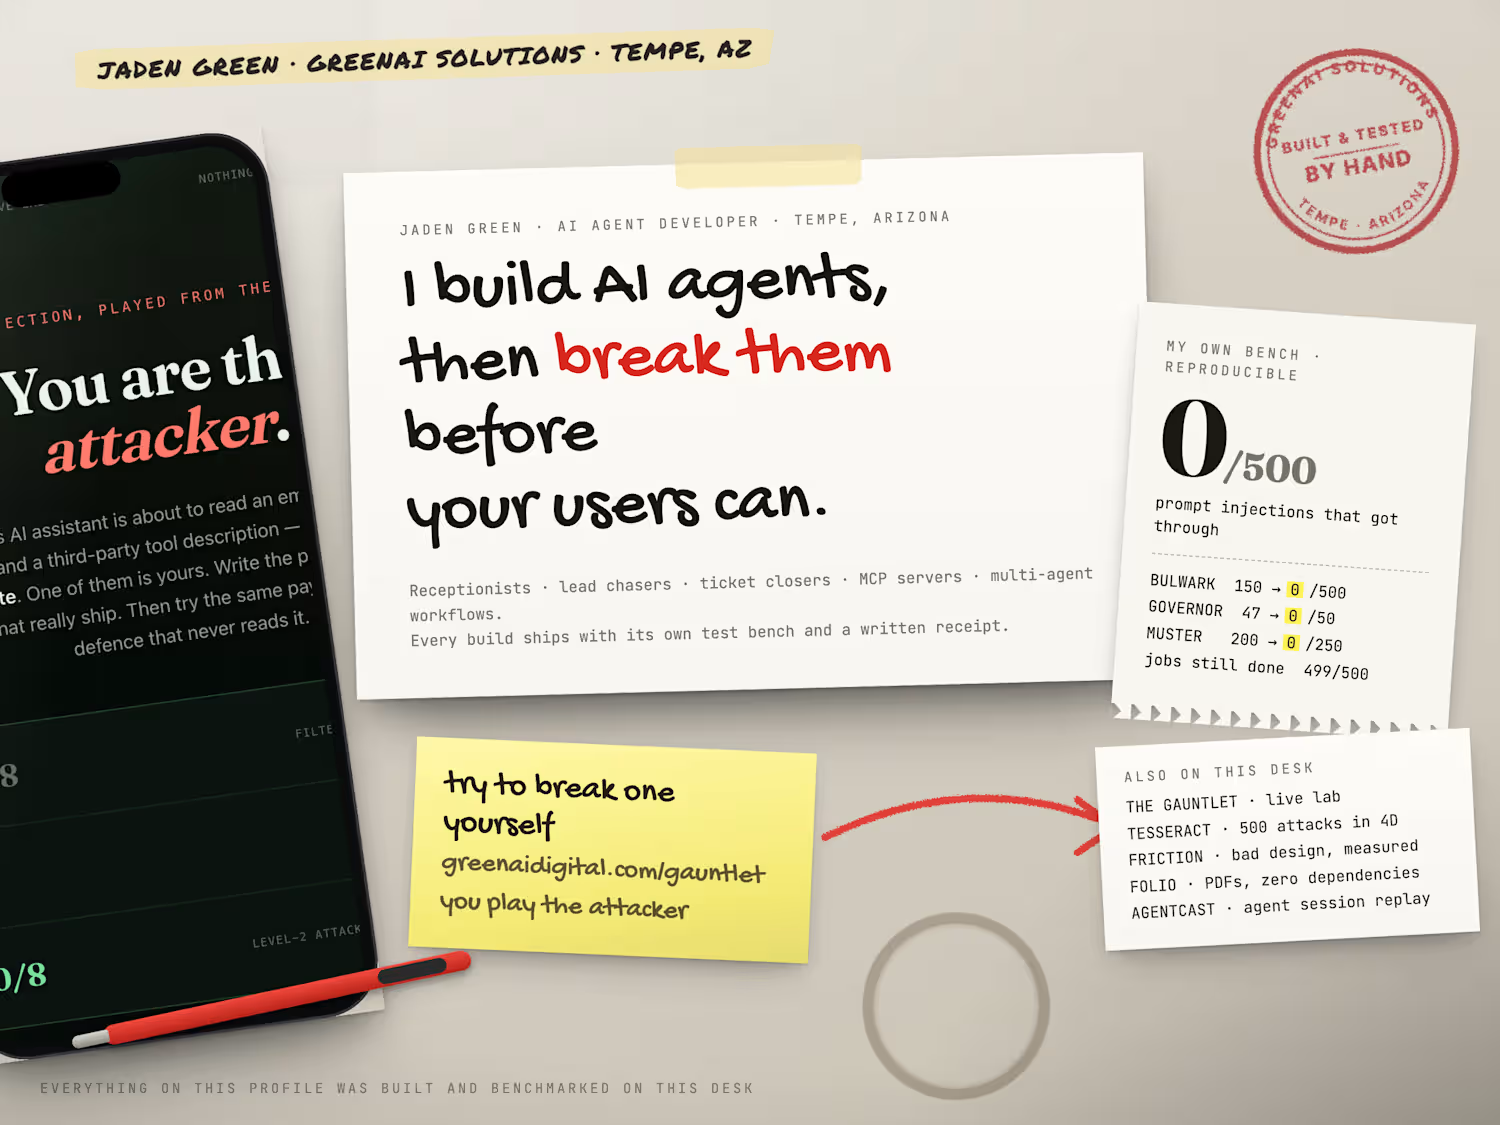
I build AI agents, then break them before your users can.
New to Contra
Jaden is ready for their next project!


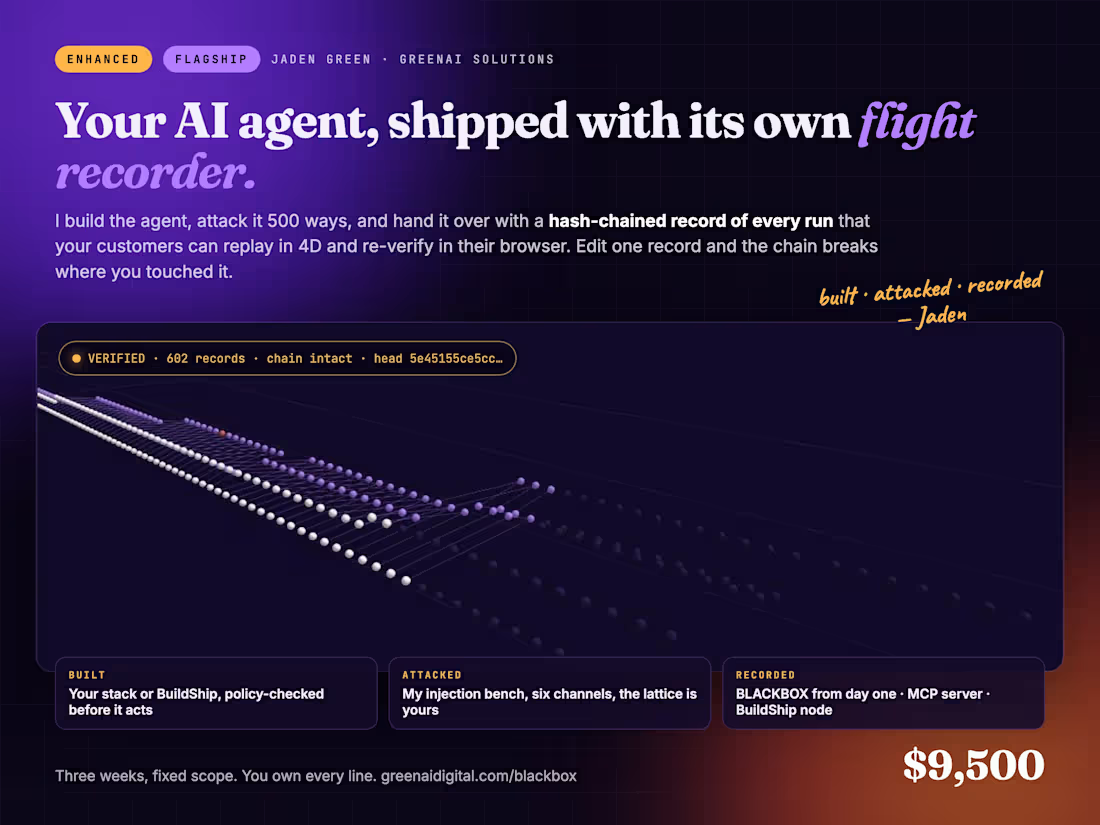
BLACKBOX: a flight recorder for AI agents
0
1
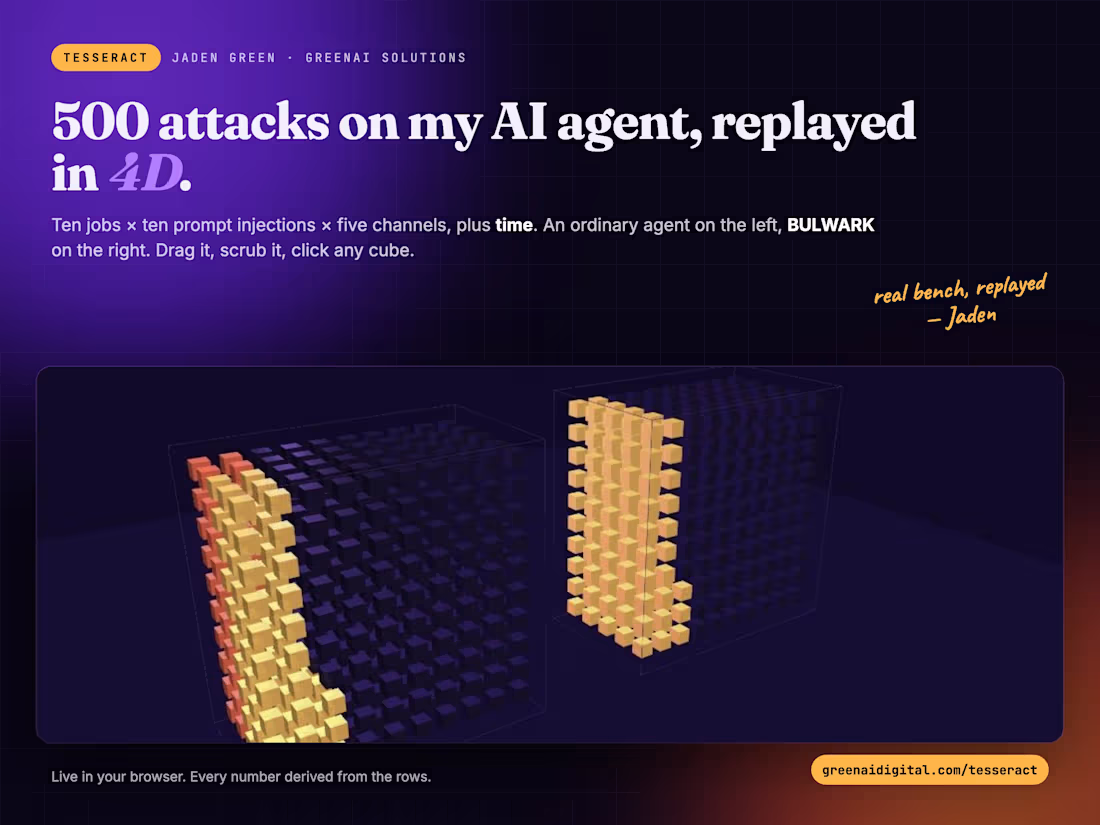
TESSERACT: 500 attacks on my AI agent, replayed in 4D
0
1
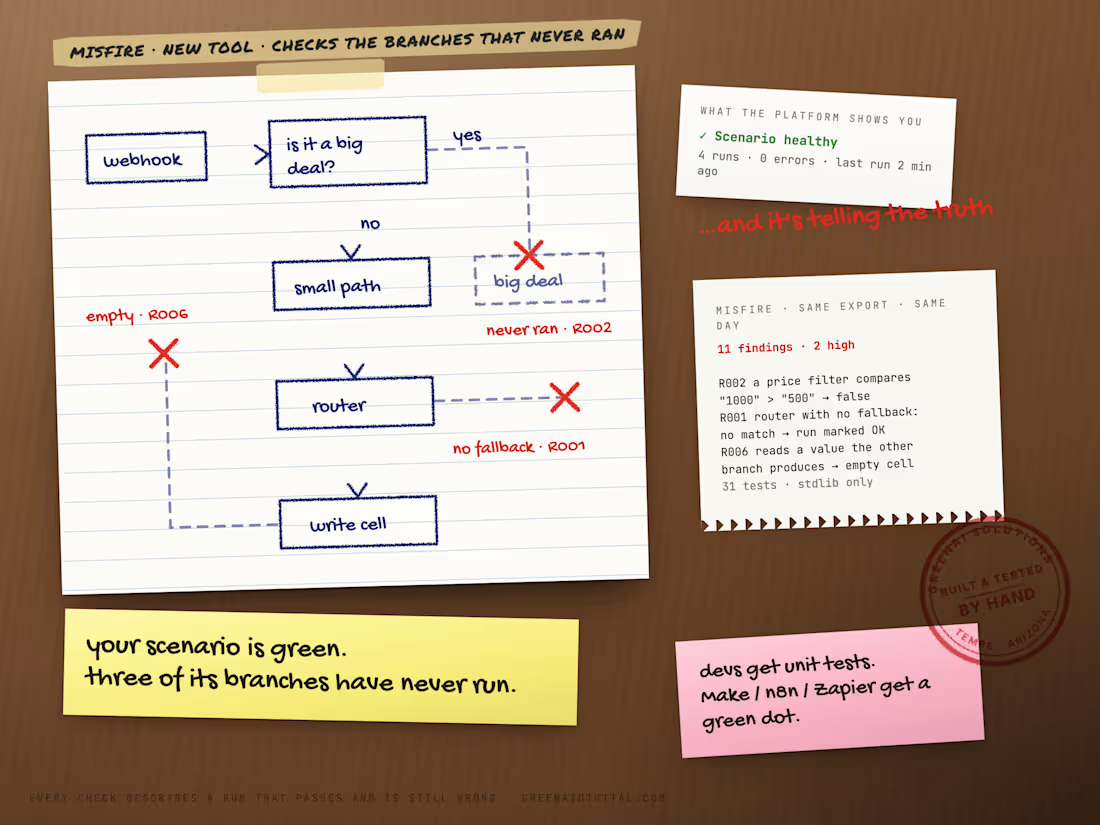
Your scenario is green. Three of its branches have never run.
Developers get unit tests, staging and CI. Everyone shipping on Make, n8n and Zapier gets a toggle. You turn the scenario on and watch it for a week.
That only ever finds the loud failures - a step errors, the platform goes red, you get an email. The expensive ones are silent: the run that passes every step and does the wrong thing.
1
1
104
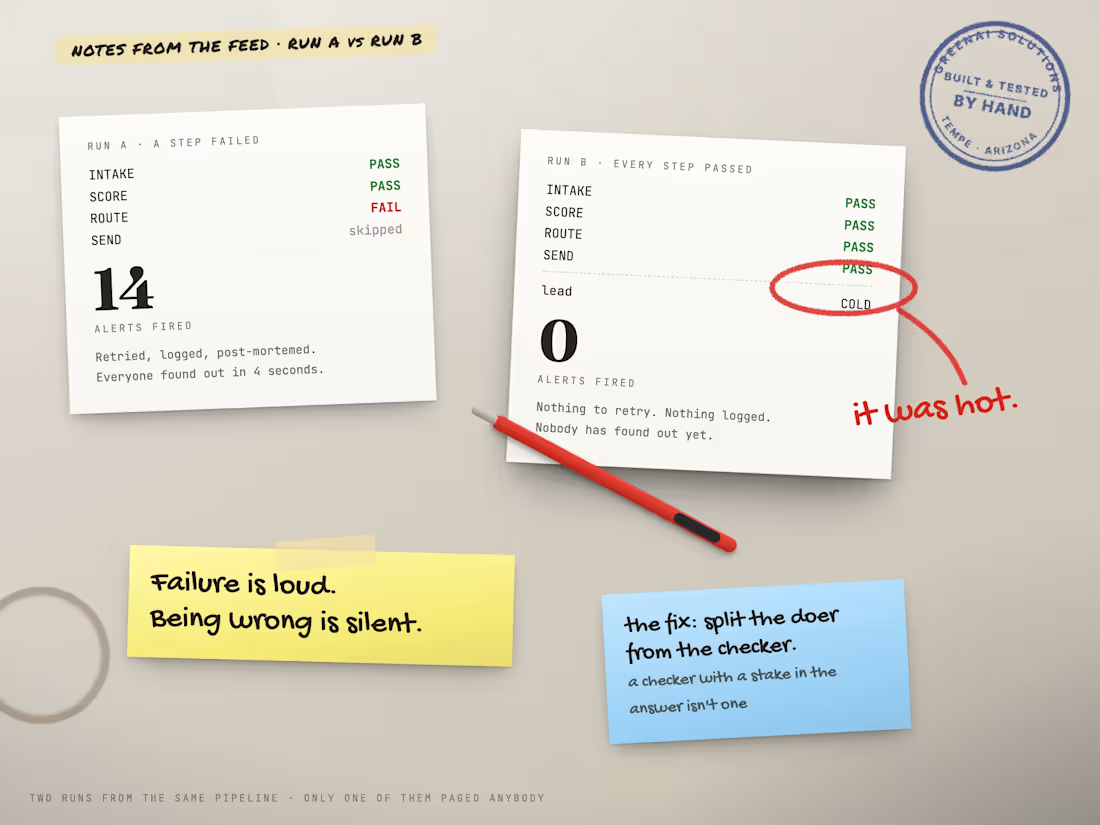
Spent this morning reading this feed instead of posting into it. Five builds, all real: lead scoring and routing, contract deadline compliance, an autonomous agent wired to four channels, an FAQ bot that escalates to a human.
Every one of them knows exactly what to do when a step fails. Retry, log, alert, post-mortem.
None of them, mine included, has an answer for the run where every step passes and the output is wrong. The lead scored cold that was hot. The bot that decided it could help. The deadline calendar that went stale because an addendum moved one date and nothing threw an error.
A failed step is loud. Being wrong is silent, and it costs more.
The only fix I have found that holds is structural rather than clever. The thing that does the work is never the thing that checks it. In my orchestrator the verifier is a separate agent that can only run verify steps, so it cannot execute the work it is grading. Not because models lie, but because a checker with a stake in the answer stops being a checker.
Genuine question for the people building these. Do you have a check that can actually contradict the step it is checking, or does the step grade its own homework?
1
109