Innerhouse Data
Data labeling team for AI companies
New to Contra
Innerhouse is ready for their next project!
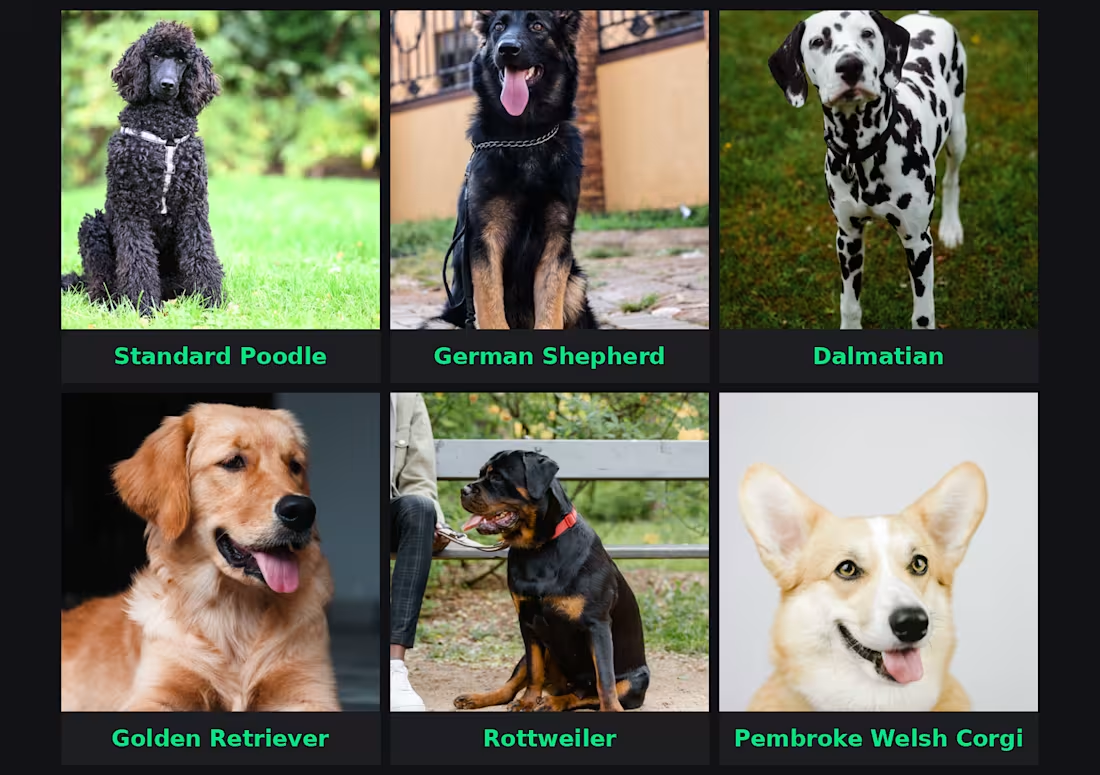
Single-label image classification across multiple dog breeds, demonstrating category assignment for computer vision training data. Each image labeled with its correct breed class, ready to feed directly into a classification model pipeline. We handle both broad categories and fine-grained distinctions depending on your dataset's needs, with every batch reviewed by our QA lead before delivery
0
21
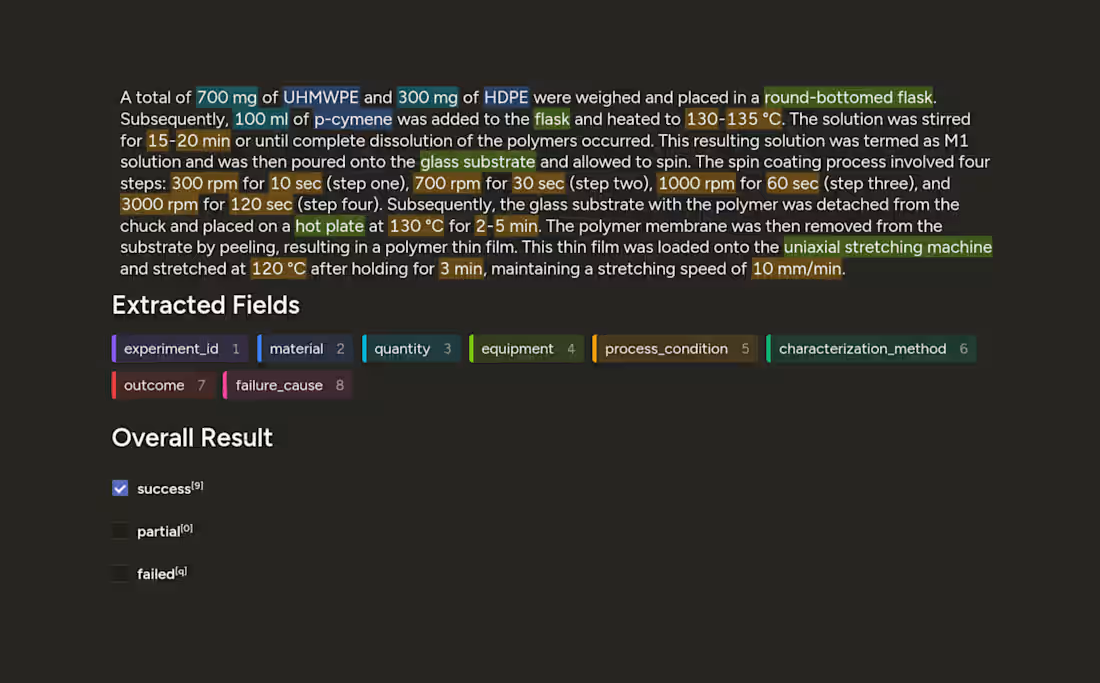
Structured entity extraction and outcome classification on materials science experiment descriptions. Extracted fields include experiment ID, materials, quantities, equipment, process conditions, characterization methods, and outcomes, tagged directly on the source text. Overall experiment outcome (success/partial/failed) classified from the full passage context. This demonstrates our approach to domain specific text annotation where accurate labeling requires understanding technical terminology and process sequences. Every batch reviewed by our QA lead before delivery
0
28
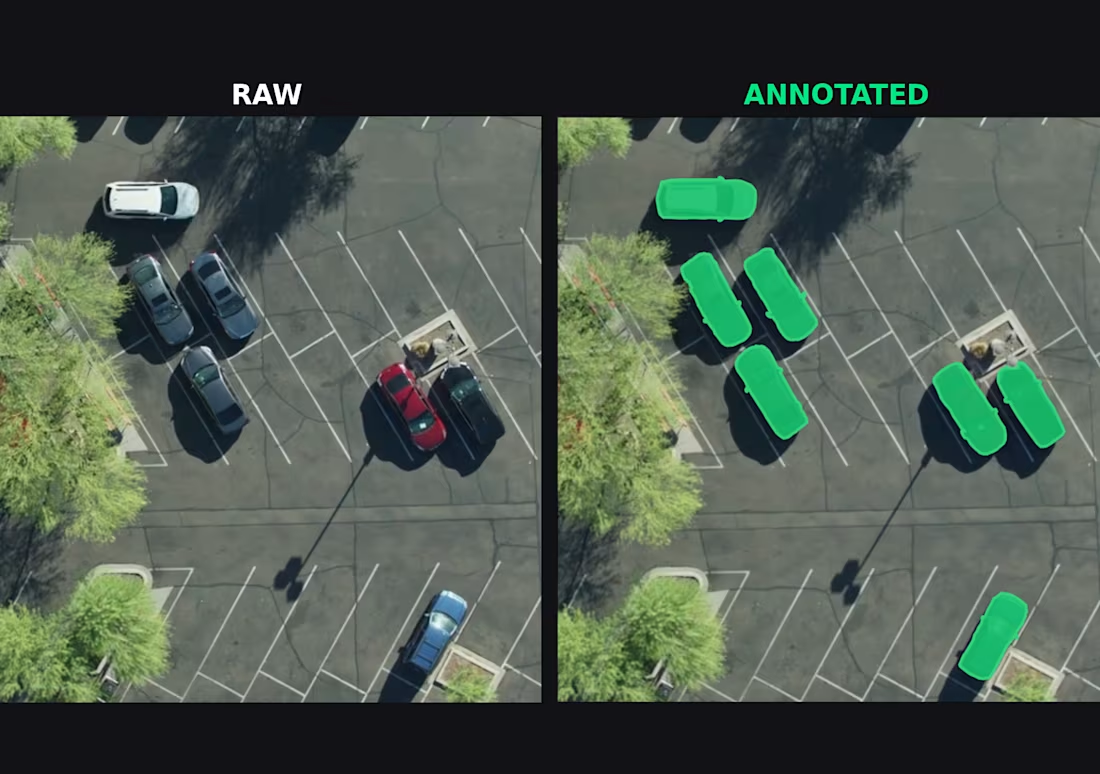
Pixel-level instance segmentation on aerial parking lot imagery, masking each vehicle by its actual outline. Demonstrates our approach to segmentation tasks where shape accuracy matters more than a loose bounding region, useful for applications like autonomous vehicle perception, aerial surveying, and occupancy detection. Delivered in COCO segmentation format. Every batch reviewed by our QA lead before delivery
0
32
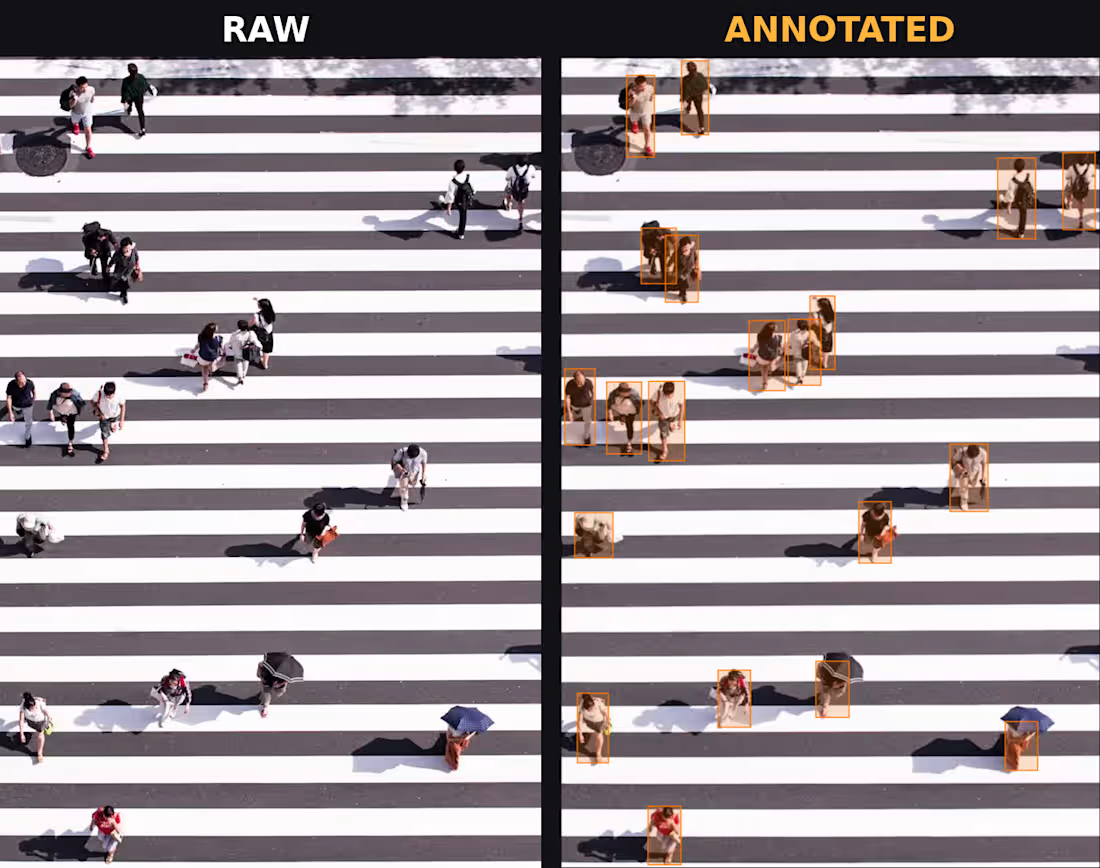
Bounding box annotation on a busy street scene for pedestrian detection. All visible pedestrians identified and boxed individually, including partially occluded and distant figures. This sample demonstrates our approach to dense, high object count scenes where consistency matters more. Every box tight to the subject, no ambiguity. Delivered in COCO JSON format, compatible with standard object detection training pipelines. Every batch is reviewed by our QA lead before delivery
0
43