👋 Hi Contra — I’m Lilya, a Data Scientist working at the intersection of retail, demand forecasting, and promotion analytics.
My recent work focuses on SKU-level forecasting, where small modeling choices have a big business impact:
• 📦 Improving SKU-level demand forecasts for planning & inventory
• 📊 Approximating the pull-forward effect of promotions
On the technical side, I work end-to-end:
• Time-series & ML forecasting
• Promo, price & calendar feature engineering
• PySpark batch pipelines & MLflow tracking
💡 Open to freelance or contract projects around demand planning, retail analytics.
Happy to connect 🚀
0
347



I engineered a large-scale package-network intelligence pipeline using Azure Databricks and PySpark. The system joined approximately 4.5 billion historical records and transformed them into reusable fingerprint signals covering package movement and network behavior.
I developed time-windowed feature logic using native Spark expressions rather than Python UDFs, preserving distributed performance at scale. The pipeline produced an approximately 200-million-row fingerprint dataset and a 22-million-row operational output that classified package activity along a cold-to-hot temperature scale.
The resulting signals supported downstream monitoring, prioritization, and operational analysis. The architecture shown here is a sanitized representation; client identifiers, proprietary schemas, infrastructure paths, and business rules have been removed.
1
304


Problem:
Users needed a faster way to find the most relevant counselor based on specialization and available data.
Solution:
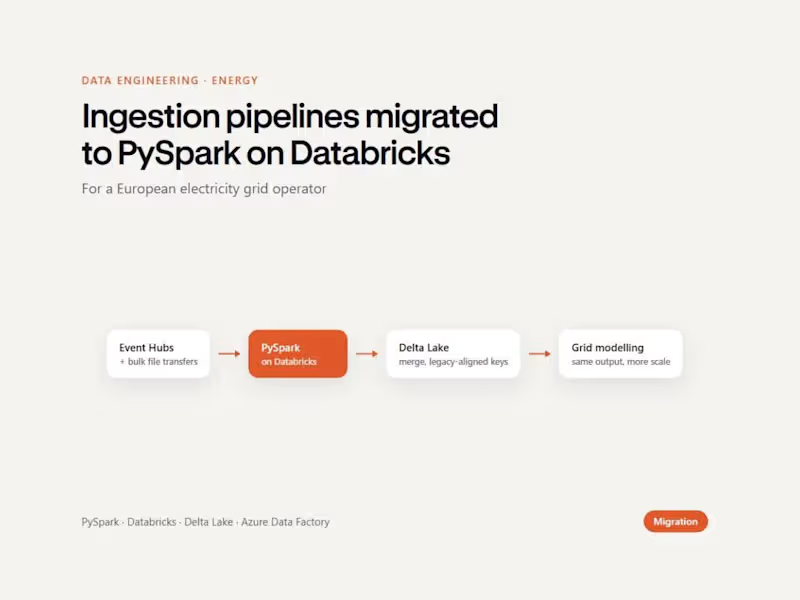
Built a recommendation workflow using PySpark for data processing and Redis for fast lookup and recommendation serving.
Tools:
Python, PySpark, Redis, Docker, Docker Compose
Result:
Created a containerized recommendation system that processes counselor data and returns relevant matches efficiently.
0
96