
PO & APM optimizing product performance and system reliable.
PO & APM optimizing product performance and system reliable.
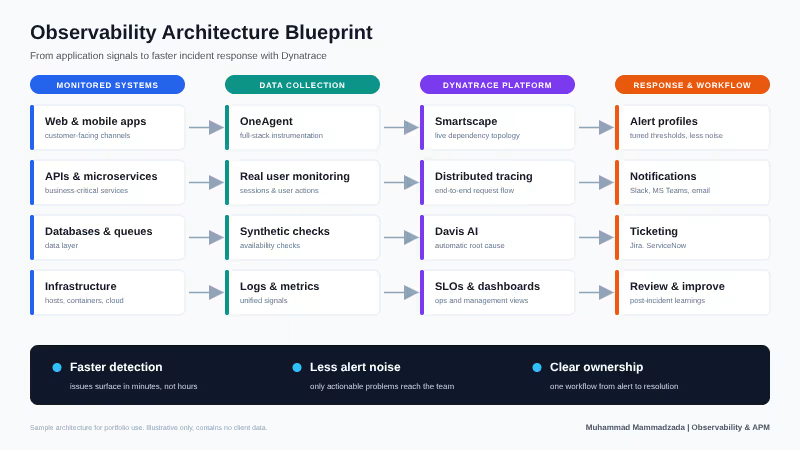
A sample observability architecture I designed to show how a team can go from raw application signals to faster incident response using Dynatrace.
The challenge: Growing teams often have logs, metrics and traces scattered across tools, so finding the root cause of a production issue takes too long and alerts become noise.
What I did:
Mapped the full flow: monitored systems → data collection → Dynatrace platform → alerting and workflow
Covered APM, real user monitoring, synthetic checks, distributed tracing and logs in one view
Defined how alerts reach the right people through Slack/Teams and Jira/ServiceNow
Planned SLO dashboards for both operations and management
Tools: Dynatrace, Smartscape, Davis AI, Jira, ServiceNow
This is a generic blueprint with no client data. I can adapt it to your stack and run a short audit of your current monitoring setup.
0
97
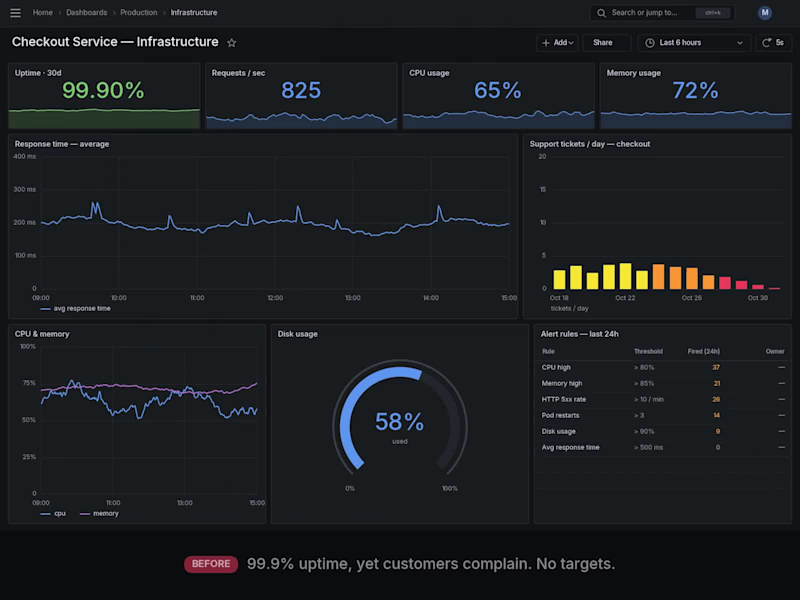
Many teams track CPU, memory and uptime, but nobody knows what “good” means. There are no targets, no error budget, and alerts fire without an owner. Customers feel the pain before the dashboard does.
What I do
In one week I define how reliable your service should be, and set up the targets and alerts to prove it.
What you get
3–5 SLIs and SLOs based on your real user journeys (availability, latency, error-free requests)
An error-budget policy: what happens when the budget runs low
Burn-rate alert rules, with clear “page” vs “ticket” thresholds
A dashboard design with SLO status, budget burn-down and a summary table
A short handover document and a 30-minute walkthrough call
How it works
Day 1: a short call about your service and users
Days 2–3: I draft the SLIs and SLOs
Days 4–5: alert rules, dashboard design and handover
Good fit if you
Run a production web or API service
Get alerts but still feel blind
Want SRE practices without hiring a full-time SRE
0
33
The problem
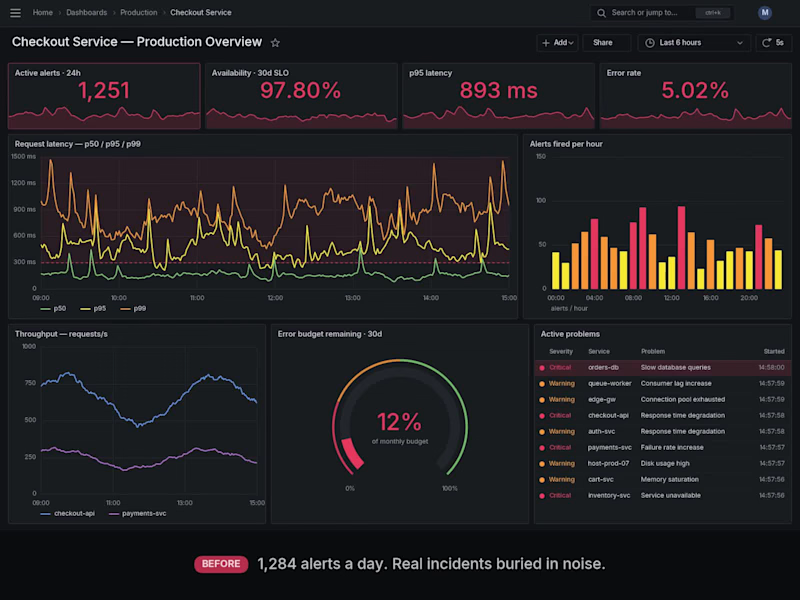
Teams often get over a thousand alerts a day. Real incidents get buried, on-call engineers burn out, and nobody trusts the dashboards.
What I do
Audit existing alerts and find the noisy, duplicate and non-actionable ones
Rebuild alerting around SLOs (availability, latency, error rate)
Design one clear dashboard: key metrics, latency percentiles, error budget, and active problems with root cause
Sample result shown in the video (demo data)
Alerts per day: 1,284 → 12 actionable
Availability: 97.8% → 99.95%
p95 latency: 842 ms → 187 ms
Error rate: 4.8% → 0.21%
Good fit if you
Run a production service and feel alert fatigue
Use Dynatrace or a similar APM tool and want better dashboards
Need a clear fix plan, not just a report
Message me with your stack and your biggest alerting pain, and I’ll reply with a quick plan.
0
40


Full-Stack Engineer & AI Automation Specialist

Pultizer-winning journalist in tech, culture and biz.
Pultizer-winning journalist in tech, culture and biz.


Content Writer and SEO Copywriter

Detail-Oriented QA Engineer & Web Designer
Detail-Oriented QA Engineer & Web Designer


Innovative Cloud Architect & DevOps Engineer
Innovative Cloud Architect & DevOps Engineer


View more →

Scalable Backend & Cloud Solutions Architect
Scalable Backend & Cloud Solutions Architect


Ex-Head of AI building SaaS MVPs & AI agents, Tel Aviv
New to Contra
Ex-Head of AI building SaaS MVPs & AI agents, Tel Aviv
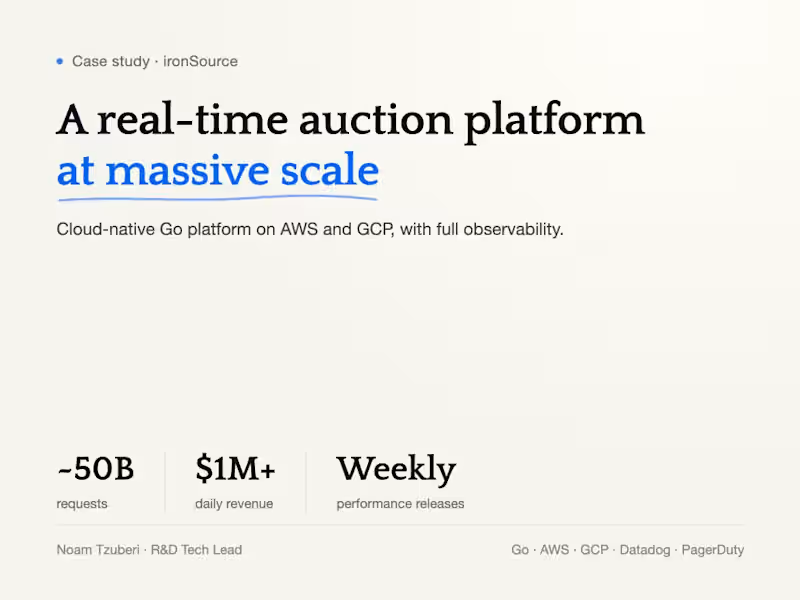
A highly scalable, cloud-based real-time auction platform written in Go, which I established and led as R&D Tech Lead at ironSource. Architected for massive scale on AWS and GCP, handling ~50 billion requests and generating $1M+ in daily revenue, with end-to-end observability in Datadog and PagerDuty and performance improvements shipped every week. The same engineering standards go into every backend I build for clients.
0
55
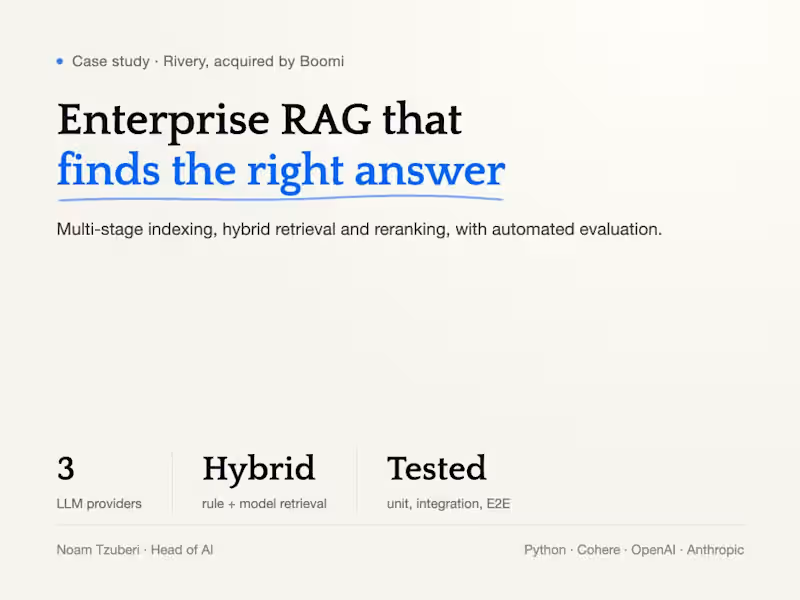
Enterprise RAG and document-intelligence pipelines I built as Head of AI at Rivery (acquired by Boomi). Multi-stage indexing with AI-native search engines (Perplexity, Tavily) and smart chunking, hybrid retrieval with Cohere reranking and OpenAI embeddings, multi-LLM features across OpenAI, Anthropic Claude and Cohere, and Python evaluation pipelines covered by unit, integration and E2E tests. I can build the same for you: a RAG chatbot or AI search over your own documents, with measured accuracy.
0
49
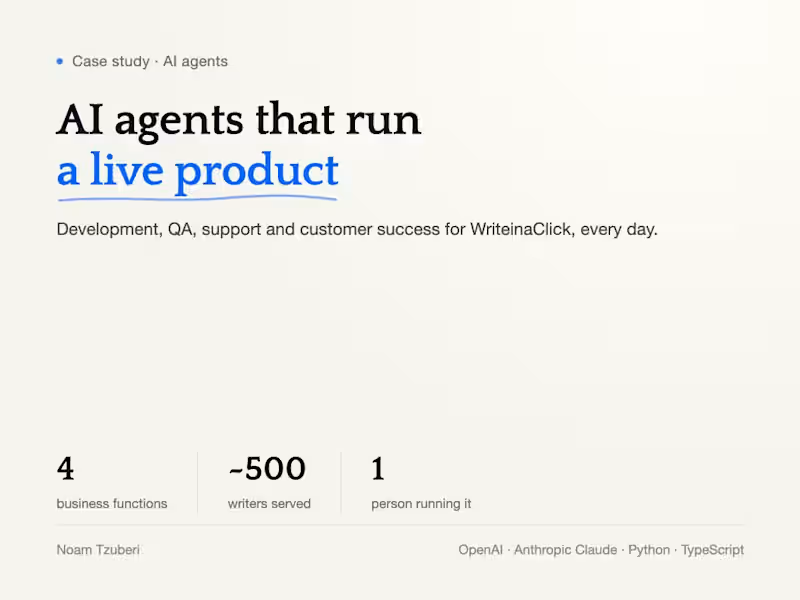
A multi-agent AI system I built to run the day-to-day operations of my own SaaS product. Specialized agents handle development, QA, customer support and customer success, so a live product with ~500 users runs with a team of one. Built on OpenAI and Anthropic Claude models with TypeScript, Python and Supabase/Postgres. I build the same kind of agents for clients: support bots, internal assistants, automated QA and workflow automation.
0
50
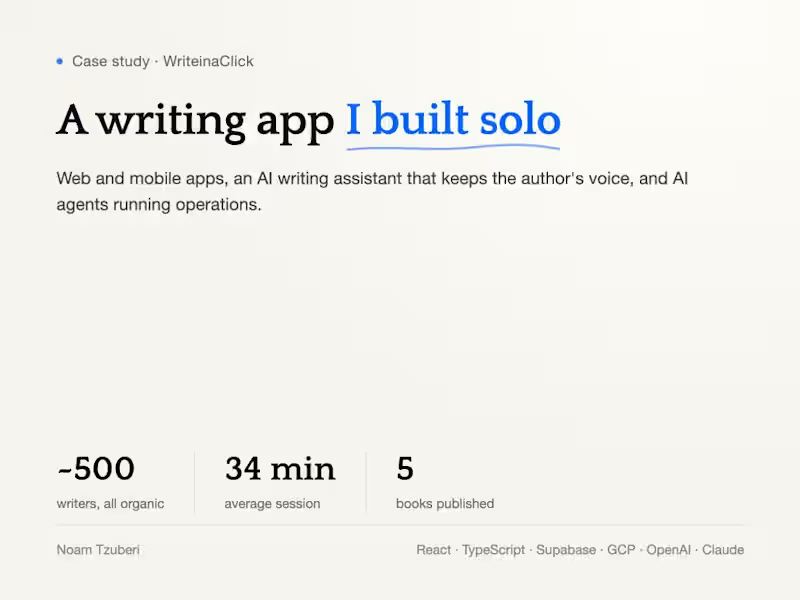
WriteinaClick, an AI book-writing platform I designed and built solo, end-to-end. Web and mobile apps, an AI writing assistant (Robin) that suggests edits in the author's own voice, and a multi-agent layer that runs daily operations. ~500 writers in under 6 months, fully organic, with a 34-minute average session and 5 books already published. Stack is React, TypeScript, Supabase/Postgres, GCP, OpenAI and Anthropic Claude.
0
50